
Inside Flipkart Altair’s MySQL Failover: Detection, Fencing, and Discovery
Flipkart’s Altair account shows why MySQL failover depends on false-positive checks, replica lag, fencing, and client rediscovery.
On this page
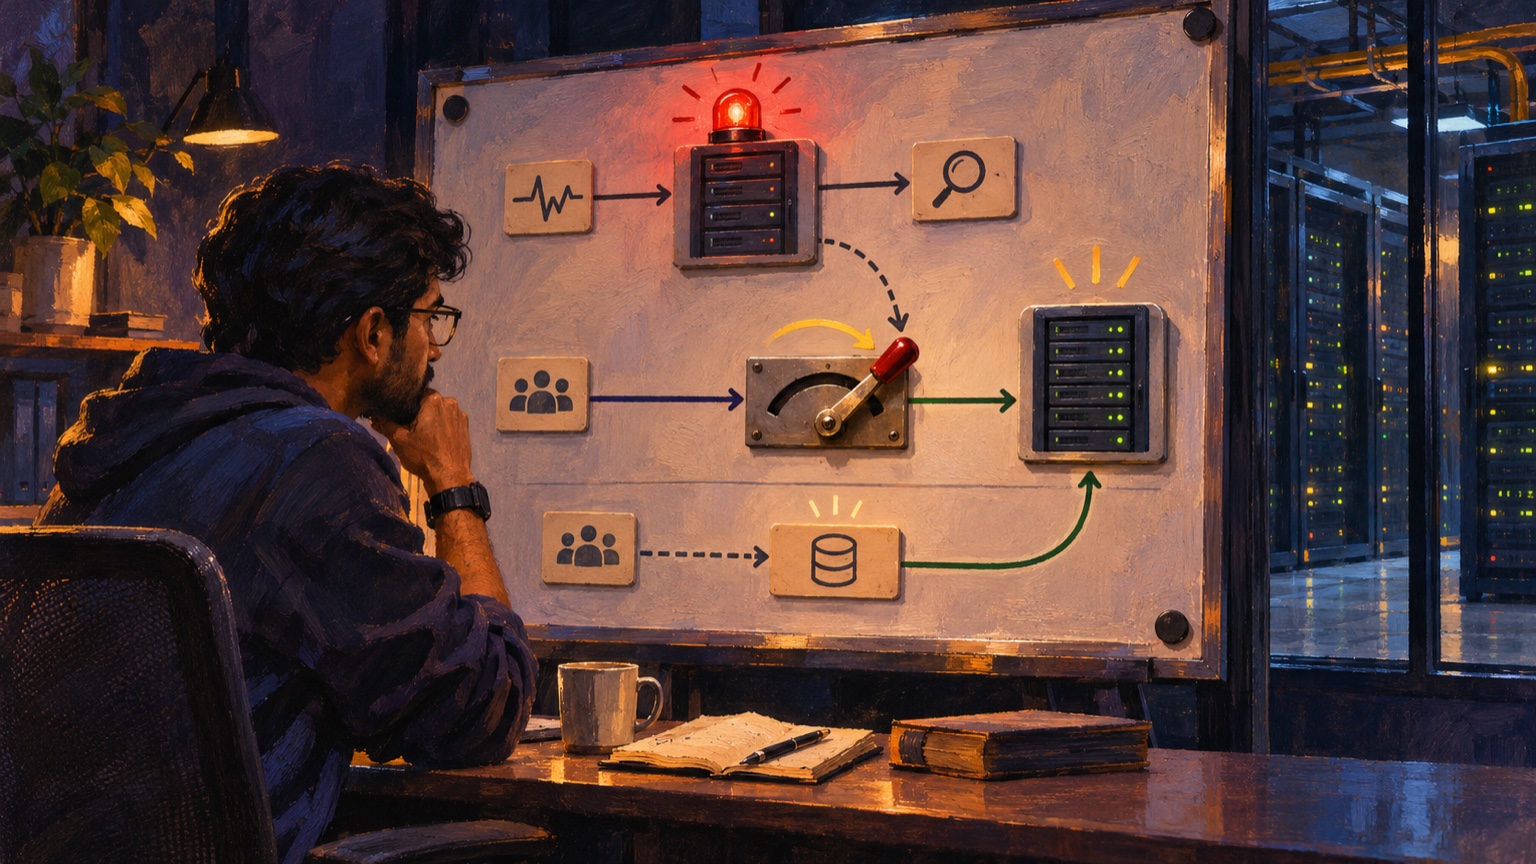
A database failover has two jobs that are easy to conflate: choose a replica that can take writes, then make sure the old primary cannot keep accepting writes. Flipkart’s 2023 description of its Altair managed MySQL service makes both visible—and adds a third step that application teams often miss: clients must discover the new primary. [1]
What Altair is responsible for
Flipkart says teams previously operated their own MySQL clusters, with uneven operational effort and practices. Altair is its managed MySQL service. The described clusters are mostly primary-replica: the primary handles writes and may serve reads; replicas asynchronously copy changes and can serve read traffic. That asynchronous detail matters because a promoted replica may not have received every transaction the former primary acknowledged before it failed. [1]
The article describes three control-plane roles. An agent runs alongside MySQL and sends health information, including process state, disk use and replication status. A monitor stores and compares updates, then notifies an orchestrator. The orchestrator checks whether the apparent failure is real before initiating recovery. Flipkart’s article says the agent and monitor report on a ten-second interval and describes a node being marked unhealthy after three missed updates; those are implementation details reported in the 2023 post, not a current service guarantee. [1]
The documented recovery sequence
The recovery job is composed of executable steps rather than one atomic promotion. In Flipkart’s description it pauses monitoring, waits for the replica’s SQL thread to apply available log entries, attempts to set the old primary read-only for planned failovers, stops the primary, promotes the replica, and updates the primary DNS record. If the primary is unreachable, the read-only step can be skipped. [1]
suspected primary failure
        ↓
check VM, MySQL reachability and replica connectivity
        ↓
wait for available replica log entries to apply
        ↓
attempt to stop or fence the former primary
        ↓
promote replica and update primary DNS
        ↓
clients reconnect to the discovered writer
DNS is part of the service contract: Altair updates the name clients use for the primary, but applications still need to reconnect. The post says clients generally need not restart after a successful DNS update; the partition case is different. If the orchestrator cannot determine whether the old primary is still alive, the failover job pauses, asks clients to stop their applications, then resumes promotion and DNS updates. That pause trades some write availability for a clearer split-brain boundary. [1]
The hard limit: asynchronous replication
Replica catch-up can reduce the gap before promotion, but it cannot restore log entries the replica never received. The exact data-loss exposure depends on the replication state and workload at failure time. MySQL’s replication documentation describes source-to-replica binary-log transfer; it does not make asynchronous replication equivalent to a synchronous commit protocol. [2]
This is why an HA design has to begin with a service’s recovery objectives. Teams should decide how much acknowledged-write loss they can tolerate, how long writes may pause, and whether an operator can safely fence an uncertain primary. A monitor quorum can reduce false positives, but it cannot turn an ambiguous network partition into proof that a host is powered off.
What to take into your own runbook
- Treat health detection, promotion, client discovery and fencing as separate steps with observable outcomes.
- Test what happens when the database is healthy but a monitor cannot reach it, and when monitoring works but the primary is isolated from the orchestrator.
- Measure replica lag under production-shaped load; do not infer a zero-loss guarantee from successful failover drills.
- Make clients resilient to DNS updates and broken pooled connections, and document when applications must stop during an ambiguous partition.
- Track the age of the vendor or engineering write-up. Flipkart’s article reports 500+ failovers at publication and notes that application coordination was still required for fencing; it does not establish the platform’s current implementation. [1]
Failure cases that change the decision
| Situation | What the source says Altair does | Design question for your team |
|---|---|---|
| MySQL process or host fails | Monitoring reports the health change; the orchestrator validates it and starts recovery. | Which independent signals distinguish a dead host from a temporary path failure? |
| Primary-replica network partition | Flipkart says this is not itself a candidate for failover. | Could promoting a replica create two writers? What evidence is required first? |
| Primary isolated from control plane | The orchestrator attempts to verify the primary and to fence it before promotion. | Can the old writer be stopped through an independent path? |
| Primary state is indeterminate | The job can pause while applications are told to stop, then resume promotion and DNS update. | Can clients safely quiesce and reconnect without replaying writes twice? |
Operational Lessons for Mission-Critical Databases
Do
- Define a measurable lag and data-loss policy for each primary-replica workload.
- Make the fencing and service-discovery steps explicit in the recovery runbook.
- Exercise the ambiguous-partition path, including what clients do while writes are paused.
Don't
- Do not describe asynchronous replica promotion as zero-loss unless your commit and recovery guarantees establish that.
- Do not treat a missed heartbeat as proof that the primary has stopped accepting writes.
- Do not forget connection pools and application behavior after DNS changes.
Altair’s case study shows the operational surface area behind managed MySQL availability: detection, catch-up, fencing, naming and application coordination. The design’s own partition procedure is a reminder that safe recovery is a policy decision, not a promise that every failover is instantaneous or lossless. Our guides to availability tradeoffs and retry behavior during partial failures explore adjacent decisions.
Frequently asked questions
What does Flipkart’s Altair manage?
Flipkart describes Altair as a managed MySQL service. Its 2023 engineering post focuses on availability for clusters that are mostly configured with a primary and asynchronously replicating read replicas.
Why does failover need false-positive checks?
A missed network probe can mean a real outage, but it can also be a transient partition or restart. Altair’s described orchestrator checks VM state, whether a replica can connect to the primary, and whether the primary itself is reachable before deciding to recover.
How does Altair handle replica lag during promotion?
The documented recovery job waits for the replica SQL thread to apply available log entries before promotion. Because replication is asynchronous, this does not guarantee zero data loss if the old primary has acknowledged transactions that never reached the replica.
How does Altair reduce split-brain risk?
The workflow attempts to stop the old primary before promoting a replica. When the primary’s state is indeterminate during a network partition, Flipkart says the job pauses and coordinates with applications before resuming promotion and DNS updates.
Sources & further reading
Keep reading

Traffic Engineering at the Boundary: Load Balancers, Gateways and Reverse Proxies
How Layer 4 and Layer 7 balancers, edge API gateways, and reverse proxies coordinate to shape, authenticate, and distribute web-scale traffic.

Content Delivery Networks Demystified: Edge Caching, Origin Offload and Traffic Shaping
How CDNs route requests to distributed edge locations, cache reusable responses, reduce origin load, and manage freshness without overclaiming latency gains.

Database Sharding Guide: Horizontal Partitioning, Shard Keys, and Cross-Shard Joins
Why databases resist horizontal scaling: deep dive into database sharding, range vs hash vs directory strategies, cross-shard joins, and resharding.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.