
Cloudflare vs AWS and Azure: Compare Execution Boundaries, Not Labels
A grounded comparison of edge Workers, regional cloud functions and CDN paths—focused on runtime, networking, state, operations and workload fit.
On this page
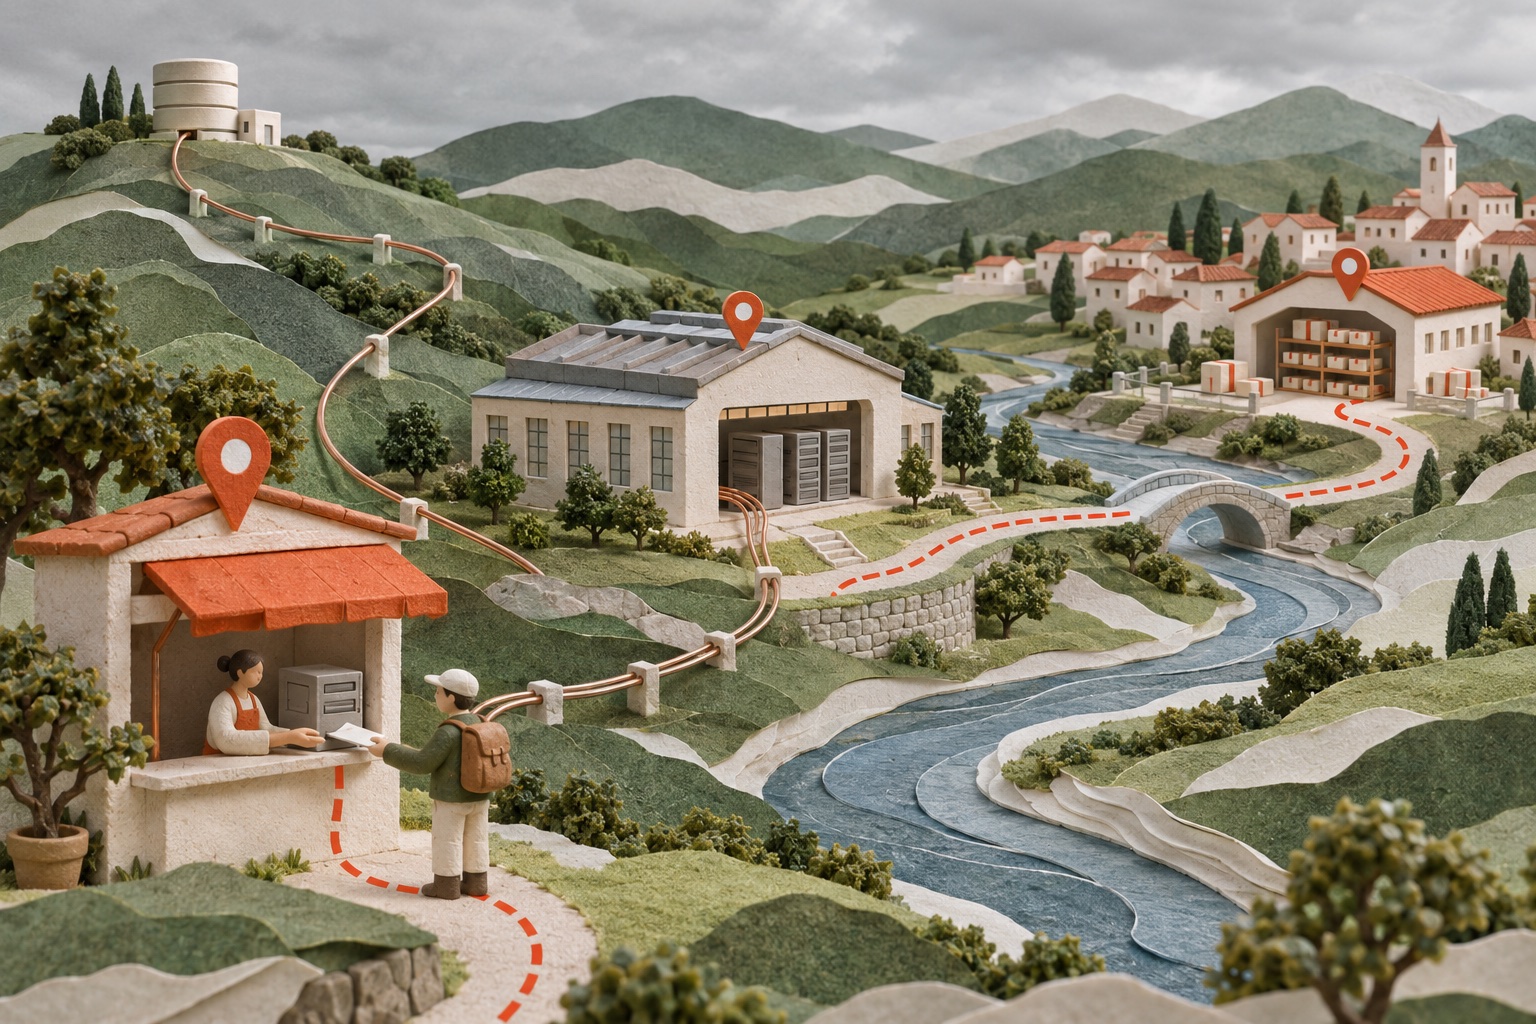
A common comparison puts “edge” on one side and “cloud” on the other, as if a provider name predicted runtime, distance and cost. It does not. Cloudflare documents isolate-based Workers execution and placement controls; AWS documents Lambda execution-environment lifecycle; Azure offers multiple Functions hosting plans; and CloudFront is a content-distribution service that routes through edge locations. These are related tools with different contracts, not identical products in a benchmark table. [1] [4] [5] [6]
Separate execution from delivery
Start by deciding whether your workload needs compute, content delivery, or both. A CDN caches or retrieves content from an origin and serves it from a network location selected for the request. A worker/function runs application code. Some platforms combine these capabilities, but one does not imply the other.
CloudFront documents delivery from edge locations, retrieving a configured origin when content is not already available there. That is different from moving the application’s database or full service to every edge location. [6]
Compare the runtime boundary
Cloudflare describes Workers as V8 isolates hosted in a distributed runtime. Isolates are lightweight execution contexts, but they are preemptible: requests are not guaranteed to reach the same instance, and mutable global state should not be treated as durable storage. Security and resource behavior are part of the service model; the public security document also explains that isolate-based isolation differs from VM isolation. [1] [3]
AWS Lambda documents an execution environment lifecycle: initialization, reuse for later requests when available, and shutdown. A cold start can add initialization latency, while execution environments may be reused but should not be treated as permanent state. [4]
Azure Functions is not one fixed runtime plan. Its documentation describes hosting choices with different scaling, always-ready, timeout, container and networking characteristics. A plan decision is part of the architecture, not a footnote. [5]
| Question | Edge Worker | Managed regional function | CDN / edge delivery |
|---|---|---|---|
| Main role | Run request-handling code in a distributed runtime | Execute code in a selected hosting plan/environment | Cache or retrieve content and deliver it through edge locations |
| State assumption | Request/instance locality is not durable by default | Environment reuse is an optimization, not a persistence contract | Cache state follows caching rules, not application database semantics |
| Network question | Where does code run relative to origin and data? | Which plan, region and VPC/network integration apply? | Which origin is fetched on a cache miss? |
| Compatibility check | Supported APIs, package and resource limits | Runtime, deployment package, plan limits and integrations | Cacheability, origin behavior, headers and invalidation |
This table is an architectural guide, not a current feature matrix. Consult the selected product’s region, plan and service-limit documentation before a decision; those details can change.
Placement is a latency trade-off
Running a small request handler near the user can reduce the distance for that part of a request. But if the handler immediately calls a database in another region, the request still pays for that network path. It may now include both client-to-edge and edge-to-origin hops, plus any proxy or TLS work. For origin-bound workloads, compute placement closer to the origin can be better than executing at the nearest user-facing location.
Cloudflare’s Smart Placement documentation describes a placement decision that considers Worker performance and latency added by forwarding the request, and permits placement near a configured cloud region. That is a reminder that “edge” is not synonymous with “closest is always best.” [2]
Before selecting a location, draw the dependency chain and mark where data lives. Measure from representative client regions, include cache-hit and cache-miss cases, and track tail latency for the entire user action. A benchmark that measures only an empty function startup does not represent a database-backed request.
A practical selection sequence
- List the actual code requirements. Does the handler need native binaries, filesystem access, long-running work, large memory, custom sockets or a particular language runtime?
- Place the durable data first. Identify the database, object store and private services; then compare network path and access controls.
- Choose the smallest execution boundary that fits. A lightweight edge rewrite or token check may suit a Worker. A broader runtime or VPC-integrated dependency may fit a regional function or container.
- Add delivery separately. Decide which assets and responses are cacheable, what varies by user, and how stale content is invalidated.
- Price a representative workload. Include request count, CPU time, memory, egress, origin calls, always-ready capacity and observability—not just a headline per-request price.
- Test failure and rollback. Verify dependency failure, cold-start behavior, deployment rollback and region or provider outage responses.
For teams new to the model mechanics behind these request handlers, our streaming inference explainer separates public API behavior from hidden implementation. The same discipline applies here: compare documented contracts, not provider folklore.
Do
- Compare exact products, plans, regions and runtime limits against the workload you will deploy.
- Measure the full request path, including origin and database calls, rather than only edge execution.
- Treat global placement and low startup overhead as product properties to verify under your configuration.
Don't
- Do not equate a CDN with globally replicated application compute or data.
- Do not treat warm or reused runtime state as durable storage.
- Do not claim one provider is faster or cheaper without a matched workload and published method.
There is no provider-wide winner. The useful decision is where each step should execute, which contract the runtime offers, and what failure mode the team is prepared to own.
Frequently asked questions
Is Cloudflare Workers the same product category as AWS Lambda or Azure Functions?
They all let teams run code without managing each underlying server, but their runtime models, networking, service integrations, scaling and limits differ. Compare the exact workload and plan rather than treating the products as interchangeable.
Should application code always run at the edge?
No. Edge placement can help when the work is small and benefits from being near the request, but a function that waits on a distant database can add another network hop. Cloudflare Smart Placement can move execution closer to an origin for some workloads.
Can edge Workers replace a regional cloud backend?
Sometimes for suitable request handlers, but not as a general rule. Operating-system requirements, dependency compatibility, memory or execution limits, private-network access, state, and data locality can require a regional service or container.
Are vendor performance and cost numbers directly comparable?
Only when workload, region, traffic shape, memory, network calls, plan and measurement method match. Product documentation describes each provider's own system; it does not establish an apples-to-apples benchmark.
Sources & further reading
Keep reading

Traffic Engineering at the Boundary: Load Balancers, Gateways and Reverse Proxies
How Layer 4 and Layer 7 balancers, edge API gateways, and reverse proxies coordinate to shape, authenticate, and distribute web-scale traffic.

Content Delivery Networks Demystified: Edge Caching, Origin Offload and Traffic Shaping
How CDNs route requests to distributed edge locations, cache reusable responses, reduce origin load, and manage freshness without overclaiming latency gains.
Cookies vs Sessions vs JWTs: Where Login State Lives and How It Fails
A comprehensive breakdown of client-side cookies, server-side sessions, and signed JWT tokens, including CSRF defenses and token revocation.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.