
Consistent Hashing: What Moves When a Node Joins or Fails?
Understand hash rings, virtual nodes, data movement and operational caveats through Dynamo, Cassandra and Redis Cluster's contrasting slot design.
On this page
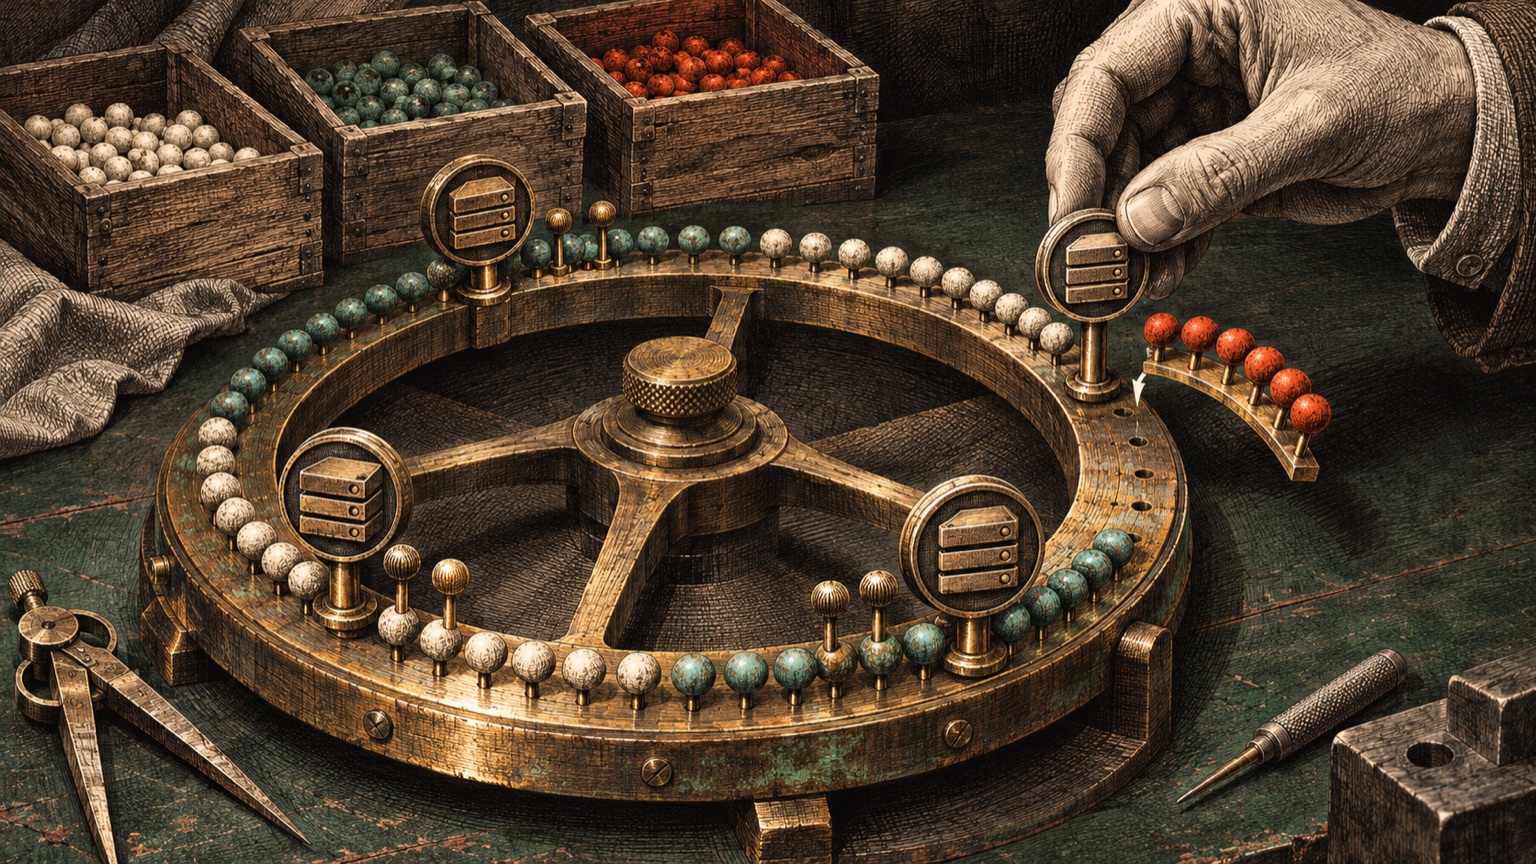
The promise of consistent hashing is often compressed to “only a few keys move when a server changes.” That is a useful intuition, but it hides the real design: which hash space is used, how nodes are represented, how ownership is replicated, how data is transferred, and how clients learn the new map? Amazon’s Dynamo paper describes a ring with virtual nodes; Apache Cassandra documents a token-ring approach; Redis Cluster uses fixed hash slots instead of a consistent-hash ring. These systems illustrate why the mapping algorithm is only one part of partitioning. [1] [2] [3]
The ring model
Imagine a fixed circular range of hash values. Hash each key into a point on that range. Assign one or more points, or tokens, to each storage node. Starting from a key’s point, walk according to the ring’s ownership rule to find the node responsible for that key. The wraparound at the end of the numeric range makes the space circular.
hash space (wraps around)
        [Node A token]
      /                \
 key x                  [Node B token]
      \                /
        [Node C token]

owner(key x) = first token encountered in the defined direction
A simple modulo scheme maps a key with hash(key) % node_count. When the number of nodes changes, the divisor changes and many keys can receive a different result. In a ring design, adding a token typically changes ownership for the interval between that token and its predecessor, subject to the chosen direction and implementation. Removing a token shifts its interval to another owner. The fraction of data moved is not a universal fixed percentage: token placement, number of nodes, replication, and the actual key distribution affect it.
Why use virtual nodes?
If each physical node owns one randomly positioned point, the interval sizes can be uneven. Dynamo’s design assigns multiple virtual positions to each physical host. With multiple positions, a physical node owns several smaller ranges instead of one potentially large range. The paper describes benefits such as sharing the transfer burden when a node joins or fails and assigning different numbers of virtual nodes to hosts with different capacity. [1]
Apache Cassandra’s documentation likewise describes partitioning by a token ring. A token maps ranges in the partitioner space; a replica strategy determines which nodes receive copies. The token allocation and the replication policy are separate concerns. [2]
Virtual nodes have costs. More ranges mean more ownership metadata and potentially more small streaming operations during movement. A balanced token space does not guarantee balanced request load: one popular key can dominate its range, and uneven object sizes can make equal hash intervals unequal in storage. Capacity-aware token allocation helps with heterogeneous machines, but it cannot predict every workload skew.
A mapping is not a migration protocol
When a node is added, a system must do more than calculate which keys should move. Existing data needs to be copied or streamed, writes must remain coherent during movement, replicas must be updated, and clients or coordinators need a route to the current owner. A failure also raises questions about replicas, quorum or consistency policy, repair and membership consensus.
Dynamo’s paper discusses these supporting mechanisms, including replication, preference lists, versioning and handling failures. The ring is a placement mechanism inside a broader distributed storage design, not a stand-alone availability guarantee. [1]
This distinction is practical. If a cache uses consistent hashing to select a server, moving a key may simply cause a cache miss and refill. If the same mapping is used for durable database partitions, the system needs a careful data-movement and consistency procedure. The mapping may be identical; the operational consequence is not.
Redis Cluster is a useful contrast
Redis Cluster’s specification says it divides keyspace into 16,384 hash slots, calculates a slot from CRC16 and assigns slot ranges to nodes. Its documentation explicitly says the design is not consistent hashing. Resharding moves slots—and the keys contained in those slots—from one node to another, while clients refresh routing information when they receive redirects. [3] [4]
That contrast prevents a common category error: a system can distribute keys across nodes without using a ring. Fixed partitions or slots can make assignment and migration more explicit, while placing responsibility on rebalancing tools and clients to handle ownership changes. The right model depends on the system’s consistency, routing and administrative needs.
Questions to answer before adopting a ring
- What is the ownership unit? A cache key, data partition, range or virtual token?
- How is membership changed? Is there a coordinator, gossip, control plane or operator?
- When is the new owner ready? Does routing change before, during or after data transfer?
- What happens to writes while copying? Is there dual-write, replay, fencing or a version comparison?
- How are hot keys handled? More tokens do not split one dominant key unless the data model changes.
- How is client routing refreshed? Clients may cache a topology and need redirects or invalidation.
- What does failure mean for replicas? Ownership and data safety require an explicit replication policy.
For an adjacent failure-domain example, our Airbnb database-on-Kubernetes analysis shows why replacement sequencing and data catch-up matter in addition to placement.
Do
- Describe the ownership algorithm, direction, virtual-token policy and replication separately.
- Measure both storage distribution and request load; the two can diverge sharply.
- Test data movement, routing updates and writes during rebalancing before production scale-out.
Don't
- Do not promise that consistent hashing eliminates rebalancing or guarantees an even workload.
- Do not assume Redis Cluster uses a consistent-hash ring.
- Do not mistake a changed owner map for a completed, durable data migration.
Consistent hashing narrows the scope of remapping under membership changes. The storage system still has to move bytes, preserve its correctness rules and teach clients where to send the next request.
Frequently asked questions
What problem does consistent hashing solve?
It provides a way to map keys to changing sets of nodes so that membership changes can affect a subset of assignments instead of requiring a full modulo-based remap. The exact movement depends on the chosen algorithm and topology.
Do virtual nodes guarantee even data or request load?
No. Virtual nodes can improve distribution and divide reassignment among more owners, but key popularity and object sizes can remain skewed. Capacity-aware assignment and observed workload data are still important.
Does Redis Cluster use a consistent-hash ring?
Redis Cluster uses 16,384 hash slots and assigns ranges of slots to nodes; its documentation explicitly distinguishes this from consistent hashing.
Does consistent hashing move the data automatically?
The hash mapping identifies ownership, but a storage system still needs membership changes, replication, data transfer, client routing and recovery procedures. Those are separate protocols and operational tasks.
Sources & further reading
Keep reading

Traffic Engineering at the Boundary: Load Balancers, Gateways and Reverse Proxies
How Layer 4 and Layer 7 balancers, edge API gateways, and reverse proxies coordinate to shape, authenticate, and distribute web-scale traffic.

Content Delivery Networks Demystified: Edge Caching, Origin Offload and Traffic Shaping
How CDNs route requests to distributed edge locations, cache reusable responses, reduce origin load, and manage freshness without overclaiming latency gains.

Database Sharding Guide: Horizontal Partitioning, Shard Keys, and Cross-Shard Joins
Why databases resist horizontal scaling: deep dive into database sharding, range vs hash vs directory strategies, cross-shard joins, and resharding.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.