
GitHub’s October Outages Show Why Regional Failover Needs Isolation
GitHub’s October reliability report describes runner queues and a saturated database pool. Teams can turn those incidents into practical dependency tests.
On this page
A service can look healthy at the machine level while users wait for work to start. GitHub’s October availability report offers two examples: hosted Actions jobs that could not get assigned to runners, and requests that could not obtain database connections before timing out. Both incidents show why reliability depends on the boundaries between components, not just the components themselves.
GitHub said it experienced eight incidents that degraded services in October. In an October 5 incident, many hosted Actions jobs remained queued or failed to start; at the worst point, most hosted-runner jobs did not start within five minutes. Self-hosted runners were not affected. In an October 30 incident, a shared database connection pool reached capacity after some update requests held connections longer than expected. GitHub reported that pull-request merges and Git operations over SSH and Git LFS were among the most affected paths. [[1] ]
These are GitHub’s descriptions of its own incidents. They give useful operational detail, but readers do not have an independent reconstruction of the underlying systems. The company also described continuing a migration and capacity expansion across its infrastructure; that context should not obscure the specific user-visible failures and their causes.
A queue can be the failure users see
In the October 5 event, the immediate symptom was not that every runner machine stopped. Jobs could not reliably get assigned to available hosted runners. That distinction matters for any system with a dispatcher between requests and workers: build queues, background jobs, data pipelines and support-ticket processing can all accumulate work even when the workers themselves are healthy.
A queue needs explicit behavior when demand spikes or the dispatch path slows down. Set limits on queue size and wait time. Alert on age of the oldest job, not only the number of running workers. Decide whether to reject, defer or prioritize new work when the queue is full. If a secondary region is a recovery path, rehearse whether it has enough capacity and whether the system can safely route jobs there without overwhelming downstream services.
Shared connection pools create hidden coupling
The October 30 report describes a different kind of limit. Some requests held database connections longer than expected while the pool was already near capacity. Once the pool filled, new requests waited and timed out. If several services depend on a shared pool, a slow operation in one area can consume a resource needed elsewhere.
Teams can reduce this risk by giving operations explicit timeouts, monitoring pool saturation and wait time, and testing what happens when a downstream dependency slows down. Retries need budgets and backoff; otherwise, timed-out requests may return as a larger wave of new work. Where feasible, isolate pools or workloads that have different latency and failure characteristics. Isolation costs resources, so it should target dependencies whose coupling can create broad impact.
Failover needs a containment test
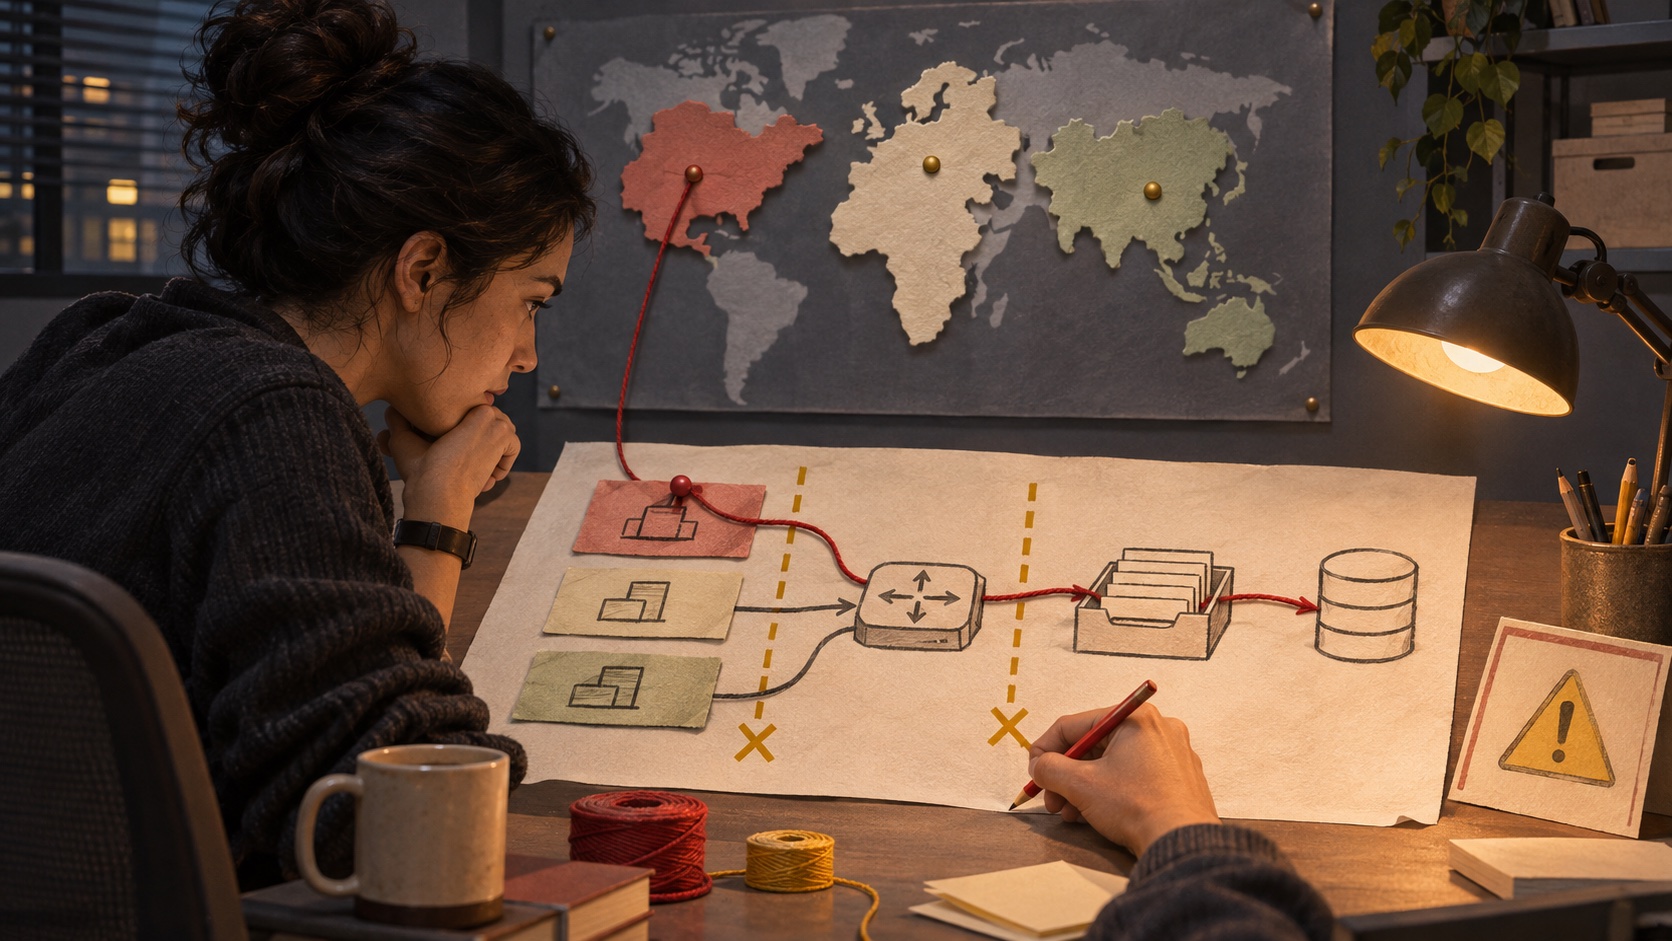
Failing over to a healthy region can restore service, but it also changes load patterns. If clients, queues or data services all move at once, the destination may be stressed beyond its tested capacity. A regional recovery plan should specify which workloads move, what capacity is reserved, how dependencies follow, and what happens if only part of the stack is available.
Google’s incident-management guidance emphasizes clear roles, communication and a documented response process during an incident. Its current SRE materials also discuss reliability as an engineering practice that includes testing operational assumptions and learning from failures. The useful action is to turn a report into a rehearsal: simulate the dispatch service slowing down, saturate a test connection pool within safe limits, or remove a non-production region and observe which user flows fail. [[3] , [4] ]
Build a smaller blast radius before adding capacity
Capacity expansion can reduce overload, but it does not replace isolation. Teams should begin with a dependency map for their most important user journeys. Mark shared queues, databases, authentication services, networks and third-party APIs. For each, write down what the user sees when it is slow, what the system retries, and where failure should stop spreading.
Then choose one bounded exercise. Measure time to detect, time to contain, time to restore and the amount of queued or failed work. Verify that alerts distinguish a growing backlog from a healthy queue and that operators know which controls are safe to use. Capture what happened and assign follow-up work while the details are fresh.
The practical reading of GitHub’s report is not that any one architecture is immune to incidents. It is that reliability work needs evidence at the boundaries: can work still be dispatched, do shared resources have safe limits, and does failover contain the damage? Those questions apply whether a team runs a global platform or a small production service. For another view of the storage layer’s reliability tradeoffs, see our analysis of GitHub’s Git storage architecture.
Frequently asked questions
What did GitHub report about October 2026 availability?
GitHub reported eight incidents that degraded services in October. Its November 12 write-up describes, among other events, a prolonged hosted Actions queue disruption and an October 30 database connection-pool saturation incident.
Why can a database connection pool cause a wider outage?
When requests hold connections longer than expected and the pool reaches its limit, new requests may wait until they time out. If many services share the pool, the failure can affect more than the code path that caused the long-held connections.
How can teams test failure isolation?
Map shared dependencies, inject a bounded failure in a non-production environment, and verify that queues, timeouts, retries and regional failover remain contained. Track user-visible impact and recovery time, not only component health.
Sources & further reading
Keep reading

Traffic Engineering at the Boundary: Load Balancers, Gateways and Reverse Proxies
How Layer 4 and Layer 7 balancers, edge API gateways, and reverse proxies coordinate to shape, authenticate, and distribute web-scale traffic.

Content Delivery Networks Demystified: Edge Caching, Origin Offload and Traffic Shaping
How CDNs route requests to distributed edge locations, cache reusable responses, reduce origin load, and manage freshness without overclaiming latency gains.

Database Sharding Guide: Horizontal Partitioning, Shard Keys, and Cross-Shard Joins
Why databases resist horizontal scaling: deep dive into database sharding, range vs hash vs directory strategies, cross-shard joins, and resharding.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.