
Kubernetes Pod Termination: Signals, Endpoint Draining, and Object Cleanup
Follow a Pod from API creation through scheduling and readiness to graceful shutdown, and distinguish lifecycle phases from kubectl status labels.
On this page
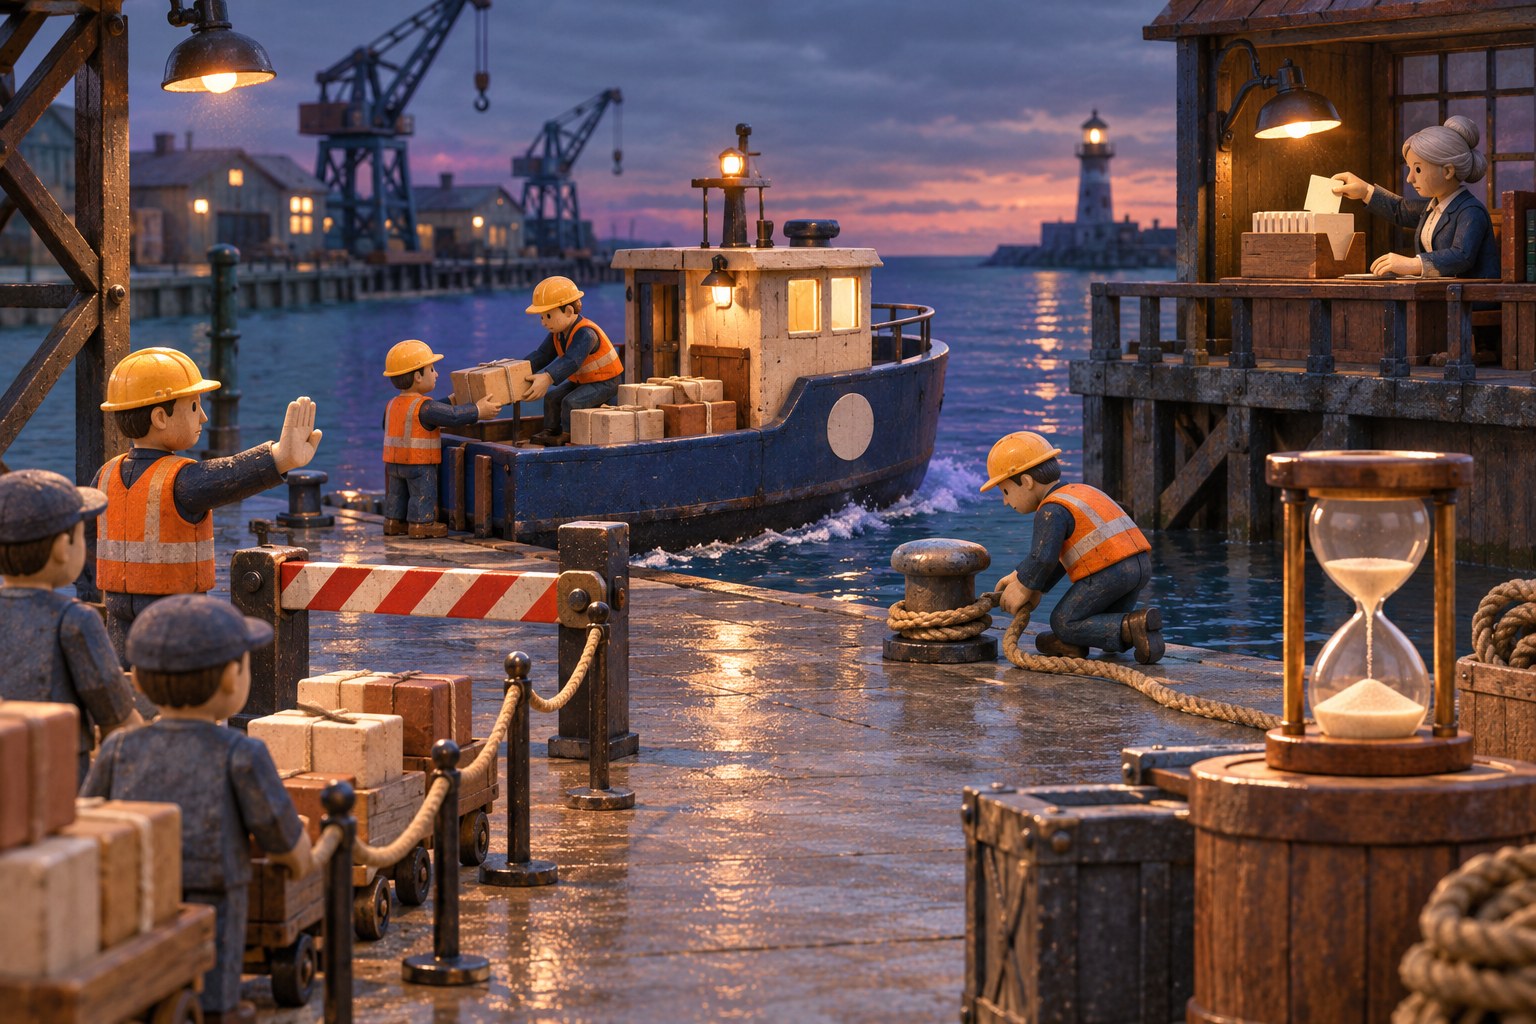
The quickest way to debug a Pod is to stop treating its STATUS column as a state machine. Kubernetes exposes several related but distinct signals: Pod phase, container state, conditions, events, and command-line display reasons. They answer different questions.
A Pod is created, assigned, and started
A request to create a Pod is submitted to the Kubernetes API. Once accepted, the Pod may remain in Pending while the scheduler searches for a suitable node, images download, storage mounts, or the kubelet prepares the runtime sandbox. The scheduler binds the Pod to a node; that does not itself start the process. The node-local kubelet works with a container runtime to realize the Pod specification. [1]
After placement, inspect the Pod’s spec.nodeName, conditions, container states, and events. Pending is a phase that includes multiple kinds of work, so it does not mean only “the scheduler has not chosen a node.” A scheduling event may explain insufficient resources or a constraint mismatch, while a node event may point to an image pull or volume setup problem.
The Pod’s phase is intentionally a high-level summary, not a complete rollup or state machine. Kubernetes defines Pending, Running, Succeeded, Failed, and Unknown. Running means the Pod is bound and all containers have been created, with at least one still running or starting; it does not guarantee the application is ready to receive traffic. [1]
Container state and Pod conditions answer different questions
Each container has its own state: Waiting, Running, or Terminated. A waiting container can be pulling an image or applying Secret data. A terminated container has an exit code, reason, and timestamps. kubectl describe pod helps reveal those container-level details.
Conditions describe checks such as whether a Pod has been scheduled, initialized, or is ready. Readiness is not the same as liveness. A readiness probe controls whether the Pod is eligible to receive normal Service traffic; a liveness probe can trigger a container restart after repeated failures; a startup probe can delay the other two while an application initializes. Poorly chosen liveness checks can restart a process that is merely waiting on a slow dependency. [2] [3]
CrashLoopBackOff is a status reason shown by tools such as kubectl, not a Pod phase. It means repeated container failures have activated restart backoff. Check the last termination reason, exit code, previous logs, probe configuration, memory limits, and recent changes. The label tells you that retries are backing off; it does not explain why the process exits. [1]
A controller replaces a failed Pod
Pods are disposable instances. If a node fails or a Pod must be replaced, a controller may create a new Pod that resembles the old one but has a different UID. A Pod is not moved to another node while keeping its identity. Higher-level resources such as Deployments or StatefulSets provide the desired replacement behavior and may recreate an object with the same human-readable name. [1]
This distinction matters for storage and debugging. Volumes tied to the lifetime of a specific Pod can be destroyed and recreated with its replacement. Logs or local files on an ephemeral container filesystem do not automatically become durable application state. Persist data through the storage resource appropriate to the workload, and use the Pod UID or owner reference when tracing an instance across replacement.
Deletion begins a shutdown sequence
When a Pod is deleted, the API records a deletion timestamp and grace period. kubectl often displays Terminating while that process is underway, but Kubernetes does not define Terminating as a Pod phase. The Pod’s containers continue to have their own state, and controllers may already be creating a replacement.
On the node, the kubelet observes the deletion and begins graceful shutdown. If a preStop hook is configured and the grace period is nonzero, it runs before the container stop request. The runtime typically sends SIGTERM to the main process. The default termination grace period is 30 seconds, though the Pod specification can set another value. If the grace period expires, the runtime sends SIGKILL to processes still running. [1]
At roughly the same time, the control plane updates EndpointSlice state for the Service. Terminating endpoints are marked not ready for ordinary traffic, but they are not necessarily removed in one instantaneous step. A load balancer and existing connections can have their own propagation and drain behavior. Applications that must finish in-flight work need a shutdown handler and enough grace time to stop accepting new work, complete requests, and close resources. [4]
Since Kubernetes 1.27, the kubelet transitions most deleted Pods to a terminal Succeeded or Failed phase before the API object is deleted. Static Pods and force-deleted Pods without a finalizer are exceptions. Version and feature-gate details can change, so check the documentation for the cluster version you operate. [1]
Debug from the symptom to the owning component
- No Pod object: inspect the API request, namespace, admission policy, and owning controller.
- Pending without node assignment: read scheduler events, resource requests, affinity, taints, and storage claims.
- Assigned but containers waiting: inspect kubelet events, image access, Secrets, and volumes.
- Running but not ready: inspect readiness conditions, startup behavior, and application dependencies.
- Repeated restarts: inspect the prior container logs, exit code, OOM state, restart backoff, and probe results.
- Slow or failed shutdown: check the grace period, pre-stop hook, signal handling, EndpointSlice state, and connection-drain behavior.
The control-plane and node responsibilities behind these steps are covered in our Kubernetes architecture guide. If a queue or upstream request burst keeps workloads overloaded while they restart, see how to bound work in an API.
Kubernetes can recreate a desired workload, but it cannot make an application’s shutdown logic correct by itself. Knowing whether you are looking at API state, scheduling, container state, readiness, or deletion is the difference between responding to a label and finding the failing step.
Frequently asked questions
Is Terminating a Kubernetes Pod phase?
No. Kubernetes defines Pending, Running, Succeeded, Failed, and Unknown as Pod phases. Terminating is commonly shown by kubectl while deletion is in progress; it is not a sixth phase.
Does Kubernetes immediately stop sending traffic when a Pod is deleted?
Deletion, kubelet shutdown, and EndpointSlice updates proceed as coordinated events. Terminating endpoints are marked not ready for regular traffic, but propagation and application connection draining are not instantaneous.
What does CrashLoopBackOff mean?
CrashLoopBackOff is a kubectl status reason indicating restart backoff after repeated container failures. It is not a Pod phase. Inspect the container exit reason, logs, events, probes, and restart policy to find the cause.
Sources & further reading
Keep reading
Cookies vs Sessions vs JWTs: Where Login State Lives and How It Fails
A comprehensive breakdown of client-side cookies, server-side sessions, and signed JWT tokens, including CSRF defenses and token revocation.
GraphQL Architecture Demystified: Client-Driven Queries, Resolvers and Federation
How GraphQL replaces fixed REST endpoints with flexible typed schemas, solves the N+1 problem with DataLoader, and scales via Apollo Federation.
Faster Go Services Start with Profiles: Allocation Hotspots, Benchmarks, and PGO
A measurement-first Go guide: benchmark representative work, inspect profiles, reduce costly allocations, and verify profile-guided builds.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.