
Throughput Is a Rate; Tail Latency Is a Distribution: How to Read Both
A practical guide to request rate, response time, queueing, Little’s Law, percentiles, and fan-out—without confusing bandwidth for application speed.
On this page
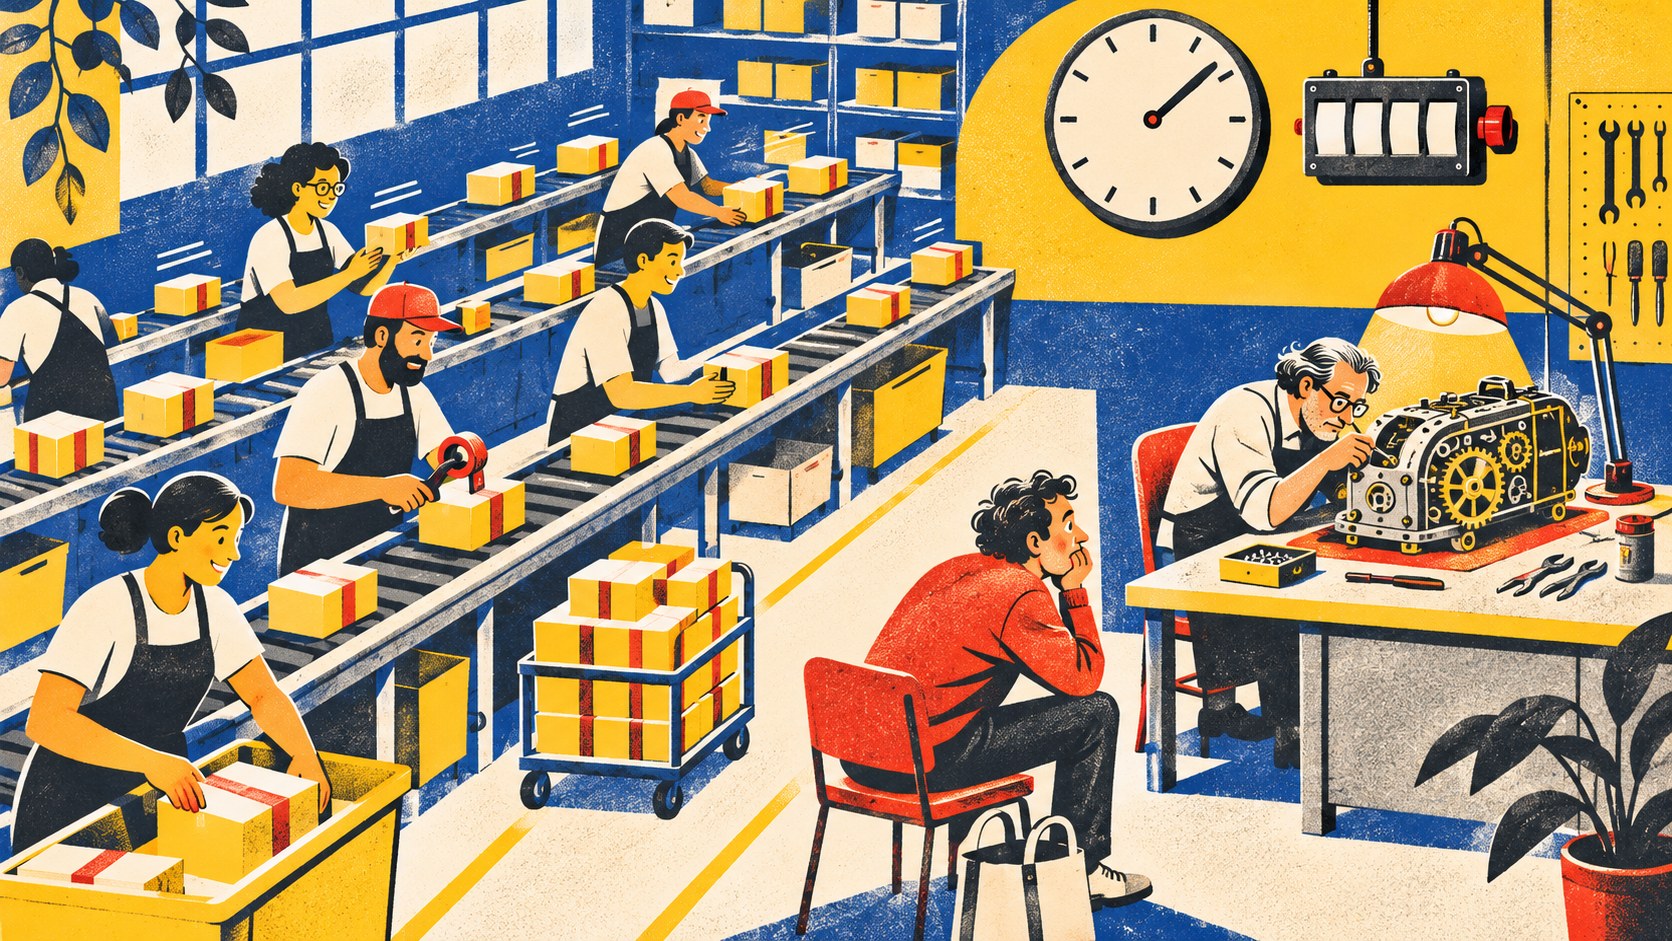
A service can complete thousands of requests per second and still make one customer wait several seconds. The mean rate describes how much work finishes; it does not tell you how long an individual request waited or whether the slowest requests are getting worse.
Three measurements that are easy to conflate
Latency is elapsed time for a defined operation. State where the clock starts and stops: client-to-client, ingress-to-response, or one database call. Each boundary includes different work.
Throughput is completed work per unit time, such as successful requests per second. Measure successful completions separately from attempts. A system that receives 10,000 requests per second but completes 6,000 and rejects or times out the rest does not have 10,000 successful requests per second.
Bandwidth is the amount of data a network path can carry over time. A higher-bandwidth link can transfer a large payload faster once data is flowing, but a request also pays for propagation, connection setup, server processing, queueing, serialization, and dependencies. Upgrading the link does not remove time spent waiting for a database lock or a busy worker.
A useful decomposition is:
observed request time = network + queueing + service work + dependency waitsThis is a model for investigation, not an exact additive formula for every trace: stages can overlap, and instrumentation boundaries can include different work.
Why the average hides the tail
Request times are a distribution. The median (p50) tells you about a typical request; p95 and p99 show the values below which 95% or 99% of the measured requests completed. A p99 value is not the slowest request and it does not identify why that request was slow.
Google’s SRE guidance notes that an average can conceal a long tail, and recommends looking at percentiles and the shape of the latency distribution. Histograms are useful because they retain counts across ranges; a single mean cannot tell whether latency rose for everyone or only for a small group of requests. [1] [2]
Percentiles need context. A p99 computed over one minute with few requests is noisy; a monthly percentile can hide a short outage. Segment by endpoint, region, tenant class, request size, and dependency where privacy and cardinality permit. Keep the aggregation window and success criteria stable so comparisons remain meaningful.
Queueing turns load into delay
When arrivals approach the capacity of a constrained worker or dependency, requests spend more time waiting for service. This can happen before CPU reaches 100%: one database pool, lock, disk, or remote quota may saturate while the host has spare cores. Retries can add load precisely when the service has less capacity.
Little’s Law gives a useful average relationship for a stable system: L = λW, where L is average work in the system, λ is the effective arrival rate, and W is average time spent in that system. Little’s original proof states assumptions about finite means and stationary processes; in operations, the equation is most useful when the system boundary and measurement window are defined. It does not say that doubling latency always doubles concurrency in every workload, nor does it forecast a p99 value. [3]
For example, if an API boundary averages 200 completed requests per second and each request spends 0.25 seconds inside that same boundary, the average number in flight is about 50. If average time rises to 0.5 seconds while the same effective rate is maintained, the average in flight becomes about 100. That extra concurrency consumes sockets, memory, worker slots, and downstream connections. This example uses the relationship; it is not a capacity benchmark.
Fan-out makes slow components visible
A user request may call several services in parallel. If the overall response waits for all of them, one slow branch can determine the total latency. Dean and Barroso’s “The Tail at Scale” describes how rare slow responses become more consequential as systems aggregate work across many machines. [4]
A simple illustration: if 50 independent subrequests each have a 1% chance of exceeding a chosen threshold, the chance that at least one exceeds it is 1 - 0.99^50, about 39.5%. This is a probability calculation under the independence assumption, not a prediction for a real system. Dependencies often share hardware, network paths, or load, so failures may be correlated. Measure the actual end-to-end distribution and dependency traces.
Possible mitigations include reducing unnecessary fan-out, setting a deadline for the whole request, returning partial results when the product allows it, caching stable reads, or limiting speculative parallel calls. A timeout can bound waiting but may not cancel downstream work unless cancellation is propagated and honored.
Measure both demand and useful work
A practical dashboard should show:
- request attempts and successful completions per second;
- error, timeout, and rejection rates;
- p50, p95, and p99 latency for the same operation boundary;
- in-flight work, queue length and age, and the saturated resource;
- per-dependency time and the fraction of requests that call each dependency.
Collect traces or spans to explain the slow path, while retaining a low-cardinality histogram for trends. Do not average percentiles from separate workers to estimate a service-wide percentile; aggregate histogram buckets or raw observations using a method appropriate to the telemetry system.
If the service is overloaded, increasing worker count can help only when the bottleneck can scale and downstream capacity exists. Bound queues, shed optional work, control retries, and protect critical operations. The goal is not the largest requests-per-second number; it is useful throughput at the latency and error levels users need.
For a broader look at request overload controls, see our API scaling guide. For safe behavior when remote calls time out, see the distributed-systems explainer.
Latency and throughput complement one another. Define the boundary, report the distribution, and follow slow requests to the queue or dependency that owns the wait. That turns a vague “the app feels slow” report into a measurable engineering question.
Frequently asked questions
What is the difference between latency and throughput?
Latency is the elapsed time for a defined operation to complete. Throughput is the number of completed operations per unit of time. Bandwidth is a link’s data-carrying capacity; it is only one factor in end-to-end request performance.
Why can average latency look healthy while users report slowness?
Averages can hide a slow tail. If a small fraction of requests wait on a queue, a lock, or a slow dependency, users in that fraction may see a much worse experience even while the mean changes little.
How should I apply Little’s Law to a service?
Define one system boundary, then relate long-run average in-flight work L, effective arrival or completion rate λ, and average time in the system W as L = λW, under the theorem’s assumptions. It describes averages and does not predict a percentile by itself.
Sources & further reading
Keep reading
Cookies vs Sessions vs JWTs: Where Login State Lives and How It Fails
A comprehensive breakdown of client-side cookies, server-side sessions, and signed JWT tokens, including CSRF defenses and token revocation.
GraphQL Architecture Demystified: Client-Driven Queries, Resolvers and Federation
How GraphQL replaces fixed REST endpoints with flexible typed schemas, solves the N+1 problem with DataLoader, and scales via Apollo Federation.
Faster Go Services Start with Profiles: Allocation Hotspots, Benchmarks, and PGO
A measurement-first Go guide: benchmark representative work, inspect profiles, reduce costly allocations, and verify profile-guided builds.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.