
LinkedIn’s Cognitive Memory Agent: Durable Context for Hiring Assistants
LinkedIn’s memory platform separates conversational, episodic, semantic and procedural context, with explicit ingestion and retrieval controls.
On this page
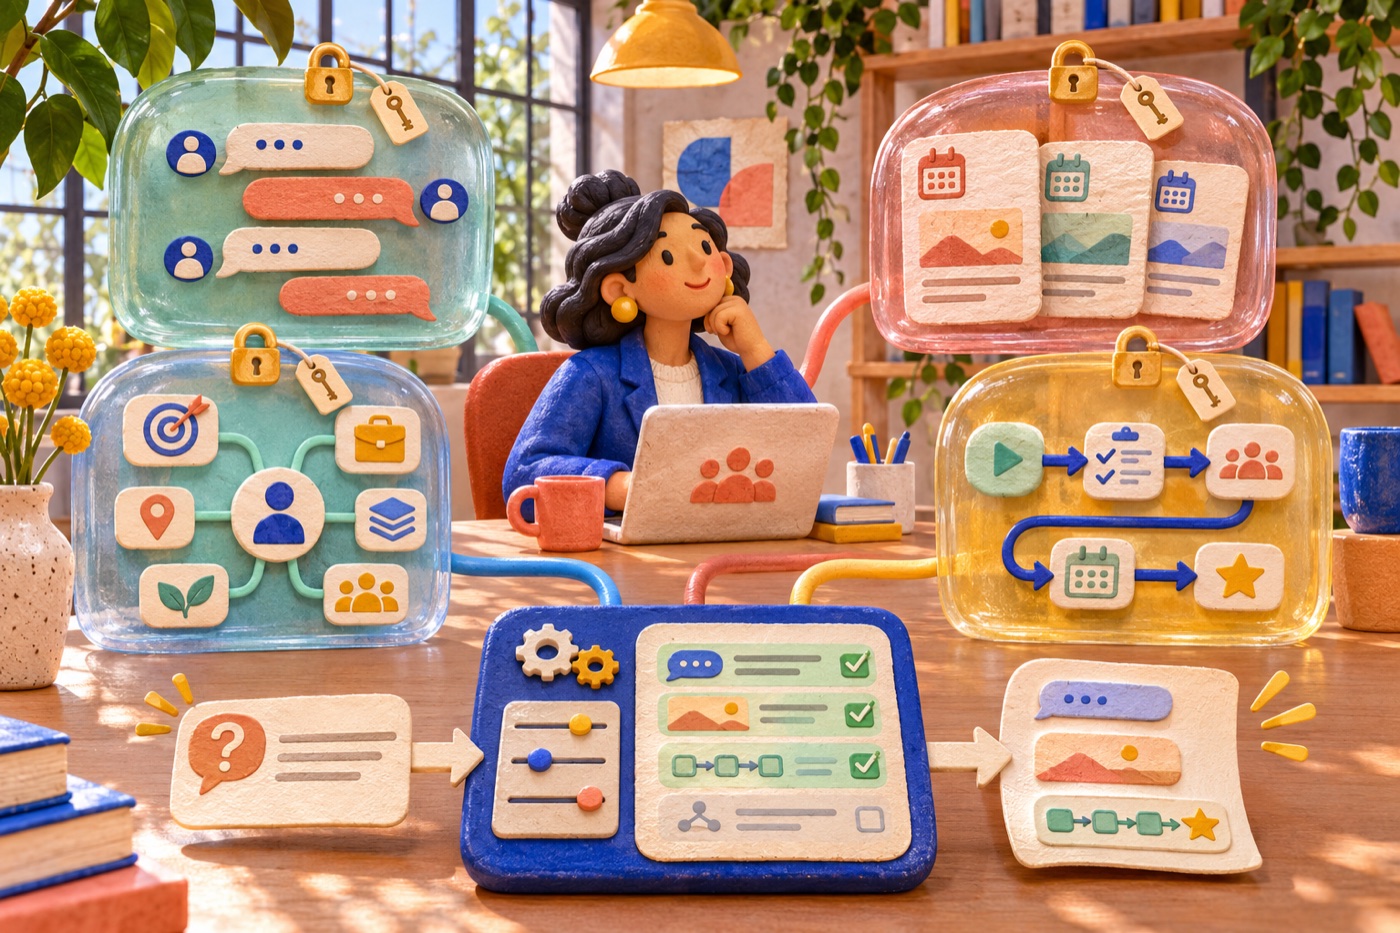
A long conversation can exceed a model’s context limit, but simply retrieving similar text from a vector store does not capture every kind of useful history. Some facts are temporary; some summarize repeated preferences; others describe a workflow a person consistently follows. A memory system has to decide what to preserve, how long it remains useful and which application or user may retrieve it.
LinkedIn’s March 2026 engineering post describes the Cognitive Memory Agent (CMA), a platform used with application agents such as Hiring Assistant. [1] The post frames memory as infrastructure with explicit ingestion and retrieval layers, not as an unbounded transcript pasted into each prompt. LinkedIn’s account is about its own recruiter-assistant system and should not be read as a general description of every LinkedIn product or all production agents.
Four kinds of context
CMA separates conversational memory from three long-term categories. Conversational memory represents a compressed in-session state, supported by a chronological conversation log and semantic representations. Episodic memory records contextual past events; semantic memory aggregates recurring facts and preferences; procedural memory captures a user’s repeated way of carrying out a task.
These categories serve different retrieval questions. “What did we just discuss?” is different from “What preference appears repeatedly?” or “What sequence of steps does this recruiter tend to follow?” A single similarity search over raw conversation text may not preserve those distinctions.
LinkedIn says each memory layer is exposed through tool abstractions. [1] That provides an interface for an application agent, while letting the memory system evolve its storage and retrieval behavior independently of the application.
Ingestion is an asynchronous data pipeline
The article describes memory prompts that tell the system what a given application should extract and where the resulting information belongs. Raw interactions can be summarized, episodic activity extracted, and longer-term semantic information aggregated. LinkedIn says those operations use both streaming and batch pathways so that heavier processing does not block the live conversation.
The split is a latency and freshness choice. Recent conversational state may need faster updates, while broader preferences can be computed over a longer window. A system needs to carry timestamps and context with each memory so retrieval can distinguish a fresh event from an old pattern and resolve conflicts when behavior changes.
Retrieval becomes a planned operation
CMA’s retrieval layer interprets a user’s question, chooses among memory tools and combines results. LinkedIn gives an example where an agent consults aggregated preferences, checks recent episodes and incorporates the active conversation before composing an answer. This is a multi-step retrieval process rather than a single nearest-neighbor lookup.
The platform article says its orchestrator uses an open-source language model on LinkedIn’s internal infrastructure for planning, tool calls and response generation. That statement applies to the system described in the post; it does not establish that every LinkedIn agent uses the same model or deployment.
Memory adds governance and failure modes
Persistent context changes the security model. LinkedIn describes application-isolated stores, ownership metadata, logged-in-user restrictions and no cross-tenant/user sharing in its Hiring Assistant example. These are explicit boundaries because persisted memory creates a data lifecycle beyond the current prompt. NIST’s generative AI risk profile calls out privacy and confabulation as risk areas; for an agent, an incorrect or stale memory can distort later decisions even when retrieval succeeds. [2]
Quality also depends on whether the memory is true and still current. LinkedIn notes that incorrect or stale records can increase friction, cost and latency, and its evaluation checks whether stored facts are supported by source activity, whether retrieved context grounds the answer and whether the task succeeds. Those checks are important because a fluent response can still cite a false preference or miss a changed constraint.
A practical design principle
Start memory design from the question the agent must answer, then define a narrow record type, owner, retention period and retrieval rule for each kind of context. Keep conversational logs separate from inferred preferences; retain provenance so users and reviewers can see where a memory came from; and test deletion, correction, stale facts and tenant isolation.
LinkedIn’s case illustrates why durable agent memory is both a retrieval architecture and a data-governance system. More memory does not automatically make an agent better. The platform must prove that the right context was stored, selected and applied for the current task.
Give each memory an owner and a lifecycle
A durable memory record should carry its source, timestamp, application scope and the reason it was stored. Those details help the retrieval layer distinguish a direct statement from an inferred preference, and a current fact from a historical episode. They also give an application a way to correct, expire or delete a record when the user’s circumstances change.
The platform must account for conflicts. A recruiter may change a hiring preference, a company may change a policy, or two conversations may refer to different roles. Retrieval should preserve enough context to avoid merging unrelated facts, and the agent should ask when a conflict changes a consequential recommendation. Memory that cannot be corrected or removed is a liability even if retrieval quality is high.
LinkedIn describes privacy-preserving processing and application/user isolation, but teams should validate those boundaries through lifecycle tests: create a memory, retrieve it in the intended context, attempt cross-user access, update the source fact and request deletion. Monitor unsupported-memory rate, stale-memory errors and retrieval latency along with task success. These checks extend the publisher’s evaluation principles into an operational checklist; they are recommendations, not claims that LinkedIn publicly reports each one.
Frequently asked questions
What is LinkedIn’s Cognitive Memory Agent?
LinkedIn describes CMA as a memory platform used with agents such as Hiring Assistant. It ingests interaction data, organizes different kinds of memory, and orchestrates retrieval for an application agent.
What kinds of memory does CMA distinguish?
The post describes conversational memory for compressed in-session context and long-term episodic, semantic and procedural memory for events, aggregated preferences and recurring workflows.
How does LinkedIn describe memory access controls?
LinkedIn says memory stores are isolated by application, records carry ownership metadata, access is restricted to the logged-in user, and the Hiring Assistant example separates recruiter and customer tenants.
Can persistent memory make an agent more reliable by itself?
No. LinkedIn notes that stale or incorrect memory can increase friction, cost and latency. Its evaluation approach checks whether stored facts are supported by source activity and whether retrieved context grounds the answer.
Sources & further reading
Keep reading
Inside OpenAI's Stream Processing Platform: PyFlink, Kubernetes and Resilient Multi-Cloud Kafka
How OpenAI built a resilient Python-native stream processing platform on Apache PyFlink and Kubernetes that survives entire cloud region outages.
Self-Hosting an AI Agent Moves the Boundary, Not the Model Call
Anthropic’s beta lets teams host the agent service, sandboxes and history. Model requests still leave for a provider, so data-flow review matters.
Inkling 2 Small in Cortex: Test the Whole Fine-Tuning Job, Not the Parameter Count
Snowflake adds Thinking Machines Lab’s Inkling 2 Small to Cortex Training preview; workload, governance and serving costs still decide fit.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.