
How OpenAI Reworked Shared Storage for Global Reads
Habitat’s storage story is a case study in multi-tenancy, latency, and capacity tradeoffs—not a universal recipe for distributed databases.
On this page
A global storage system rarely gets faster by adding replicas everywhere. Replication consumes capacity and complicates consistency; caches trade freshness for latency; dedicated containers isolate workloads but require someone to predict each launch. OpenAI’s Habitat writeup is useful because it shows a team revisiting those tradeoffs after real operational friction instead of presenting one storage pattern as a universal answer.
From a database client to a platform
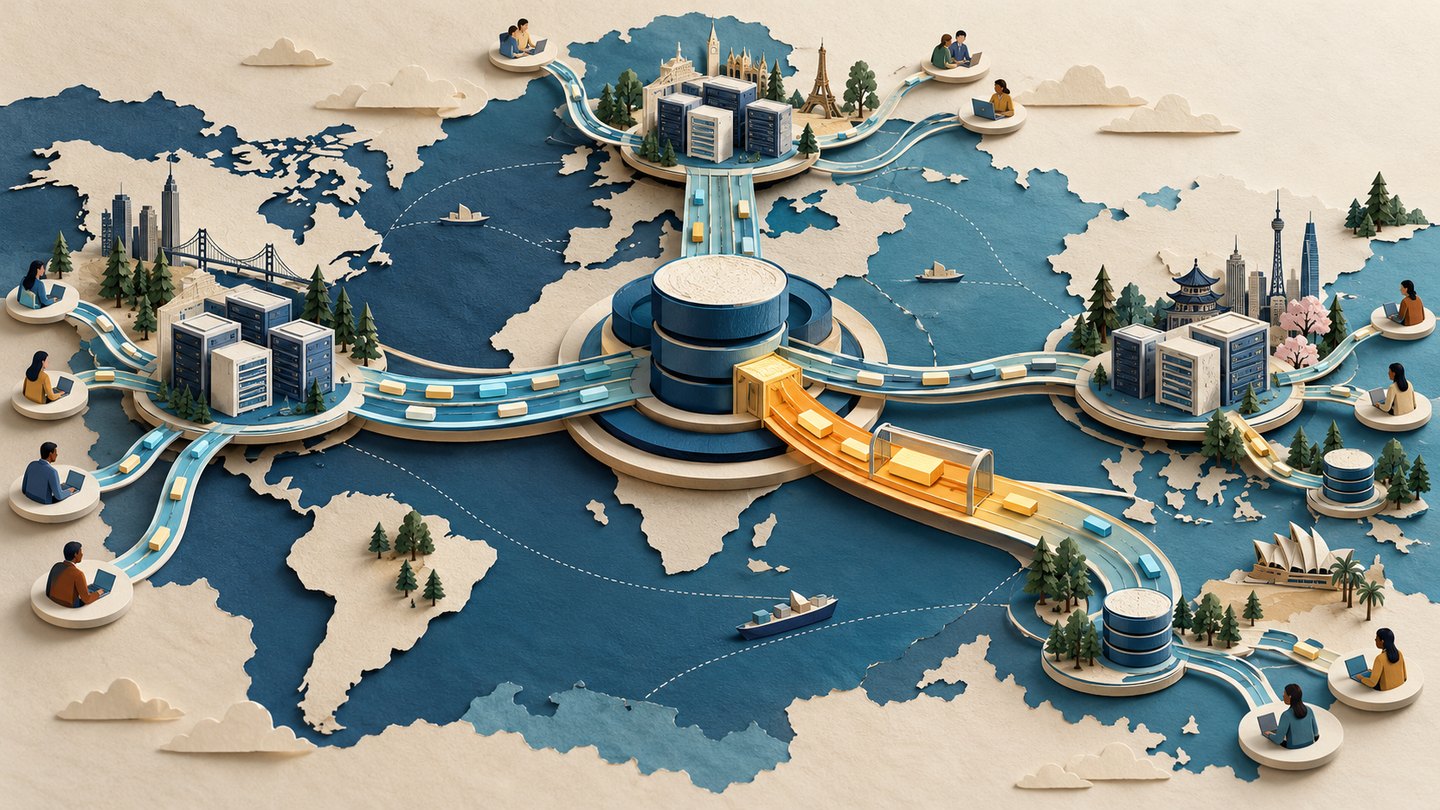
Habitat is OpenAI’s online storage platform for product state and other information. Its October 23 Part II article says the platform serves more than 500 petabytes across 40 regions and supports more than one billion users. The post is an engineering account from OpenAI employees and describes the company’s own service, not an independently benchmarked reference design. [1]
The most revealing choice is the multi-tenancy cycle. A shared container lets teams draw on pooled capacity and lets a central group manage provisioning. It also creates noisy-neighbor risks: a busy key or workload may affect unrelated tenants. Dedicated containers improve isolation and make ownership clearer, but every product team then has to forecast demand and request capacity before a launch. OpenAI says it found this operational burden hard to scale and moved back toward shared containers with additional controls. [1]
That arc is a reminder that isolation and utilization are not opposite settings on one dial. They change who carries the work. A shared system needs central guardrails against contention; a dedicated one needs capacity planning, scaling discipline, and launch readiness from each team. OpenAI says it used built-in Cosmos DB mechanisms where possible and added custom handling where the platform’s needs required it. [1]
Protect interactive traffic from noisy neighbors
OpenAI describes hot-key throttling to limit the amount of shared throughput that one key can consume. It also uses request priority so offline work, such as bulk inserts or extracts, is throttled before interactive requests that serve users. Those mechanisms do not remove contention; they define how the system allocates scarce capacity when it occurs. [1]
This is a practical distinction. A batch export can often wait or retry. A user-facing settings read may be on the critical path for a page or conversation. A priority system makes that product choice explicit in the storage layer, instead of letting whichever tenant generates the most traffic consume resources by default. Teams should define these classes from actual service objectives and ensure that “interactive” does not become a blanket label that starves necessary background work.
Partitioning adds another constraint. Cosmos DB distributes logical partitions across physical partitions, and Microsoft documents limits and consistency behavior that affect how workloads scale. A tenant that concentrates traffic on one partition key can be limited even when the overall account appears to have spare capacity. OpenAI’s account treats a shared container as an organizational optimization that still needs hot-key controls and a way to move exceptional datasets. [3] [4]
Place only what benefits from proximity
OpenAI says Habitat read traffic accounts for over 90% of its requests, and it describes three performance levers: place data near users when capacity allows, broadly replicate only the smallest and most latency-sensitive datasets, and rely on distributed caching for the rest. The company says physical cloud capacity constrains where its largest datasets can live; sometimes it must choose between storage closer to users and compute capacity in a region. [1]
That is more nuanced than “replicate globally.” Microsoft’s Cosmos DB documentation explains that consistency settings trade off synchronization behavior and latency. Strong consistency requires synchronous replication across regions; session and bounded-staleness modes offer different guarantees. An application’s read-after-write expectations therefore belong in the placement decision. A user-visible object that must reflect the latest write may need a different path from a static preference or a frequently reused lookup. [3] [4]
For less latency-sensitive objects, OpenAI says Habitat uses a distributed lookaside cache close to its serving infrastructure. That can hide some cross-region round trips, but it introduces staleness questions. A short time-to-live reduces the stale window while lowering cache hit rate; a longer one improves hit rate while extending how long old values may be served. Teams should decide which data may be stale, how invalidation works, and what the reader should do after a cache miss or regional outage.
The headline result needs a workload caveat
OpenAI reports that its layered work reduced global read p50 from approximately 120 milliseconds to 10 milliseconds. The writeup attributes improvement to multiple changes, including regional placement, limited replication, caching, and a Rust rewrite that reduced proxy overhead. Because these interventions changed together in a production system, the reported 12× figure should not be read as the isolated effect of any single technique or as a forecast for another database. [1]
Part I provides context for Habitat’s service layer and its evolution from a client library; Part II focuses on Cosmos DB, multi-tenancy, and global read performance. Together, the posts show a system design that is still evolving rather than a finished template. The engineering contribution is the sequence of tradeoffs and the explicit willingness to reverse a choice when its operational costs outgrow its isolation benefit. [2]
A checklist for a similar system
Before changing a distributed storage design, measure request volume by tenant, key, region, consistency requirement, and workload class. Simulate launch bursts separately from steady state. Then decide which workloads deserve hard isolation, which can share capacity under fairness controls, and which datasets justify replication near readers.
For each cache, record the staleness budget and the invalidation path. For each replicated object, state the consistency behavior that callers can rely on. For each background job, set an explicit priority and a retry policy that cannot monopolize capacity during an incident. Finally, monitor tail latency and per-tenant throttling: p50 can improve while the slowest or least-resourced tenants still get worse.
The useful design principle is not “always multi-tenant” or “always replicate.” It is to make placement, isolation, freshness, and ownership part of one system contract. For related reading, see our explainers on consistency versus availability and tunable quorum reads and writes.
Frequently asked questions
What did OpenAI’s Habitat team change?
OpenAI describes returning to shared multi-tenant Cosmos DB containers after a period of dedicated containers, then adding hot-key throttling, request priorities, data movement, selective regional replication, caching, and Rust proxy improvements.
Does the reported 12× read improvement mean another team should copy the design?
No. OpenAI reports a change in its own global read p50, from about 120 milliseconds to 10 milliseconds, under its data and workload conditions. Other teams need to measure their own request mix, consistency needs, data residency, cache staleness, and regional capacity.
Sources & further reading
- OpenAI Engineering: Rapidly scaling online storage to serve over 1 billion ChatGPT users (Part II)
- OpenAI Engineering: Rapidly scaling online storage to serve over 1 billion ChatGPT users (Part I)
- Microsoft Learn: Global distribution with Azure Cosmos DB
- Microsoft Learn: Consistency levels in Azure Cosmos DB
Keep reading
Python’s Typing Survey Shows Adoption Is Steady While Tools Fragment
Meta’s 2026 survey finds stable type-hint use, faster-changing checker choices, and growing AI assistance—without representing every Python developer.
Go’s Interactive Refactorings Fix a Quiet Gap in the Language Server Protocol
Gopls can now ask developers for choices before a refactoring. The proposed LSP capability could make richer edits work across editors.
Meta’s AI-Built Forum App Is Really a Story About Verification Loops
Meta’s engineering account of building Forum shows why agentic coding depends on precise plans, automated checks and human sign-off.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.