
Pinterest’s CDC Platform: Making Debezium Work Across Sharded MySQL
How Pinterest separated CDC control and data planes to scale Debezium across a highly distributed MySQL estate while preserving upstream compatibility.
On this page
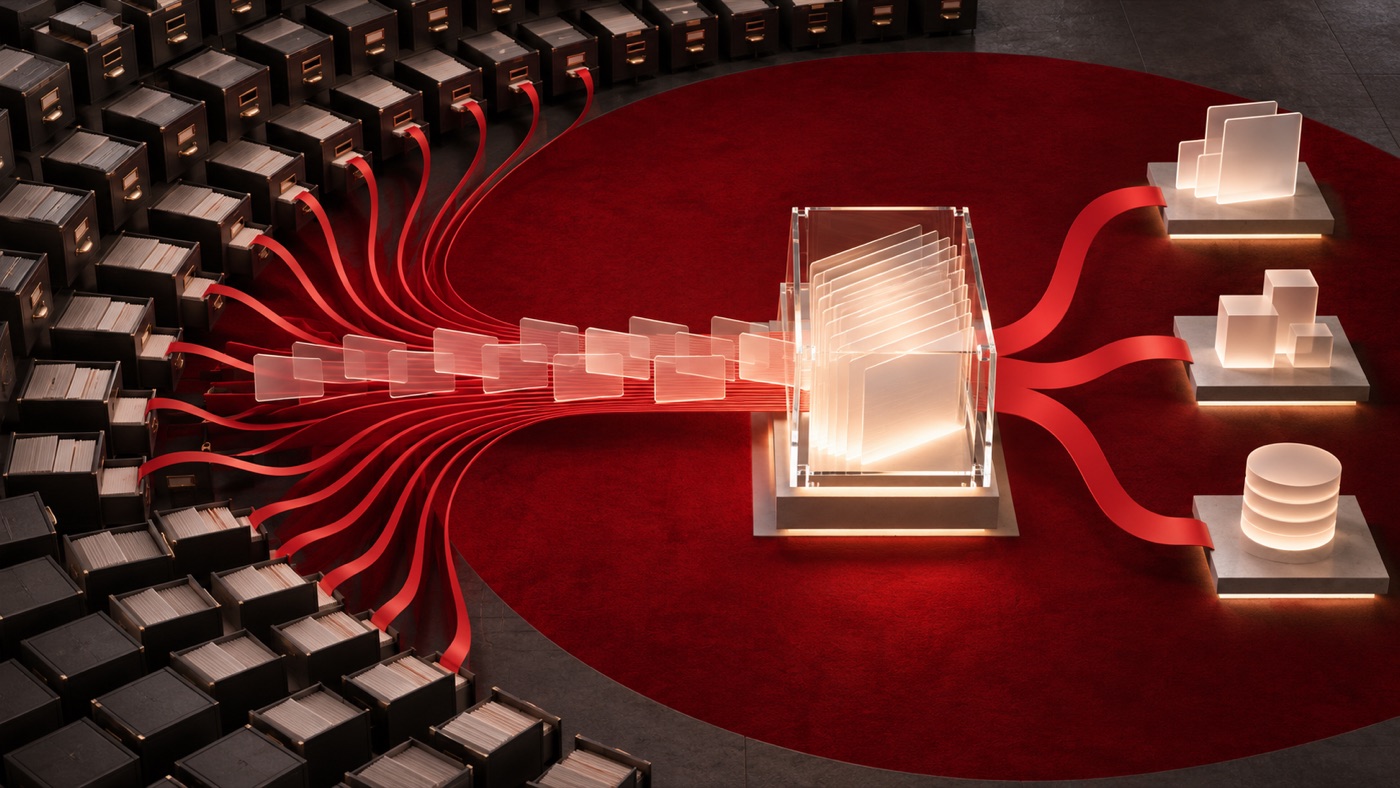
Change data capture (CDC) moves committed database changes into downstream systems without repeatedly polling application tables. At Pinterest, the challenge described in its engineering post was not simply parsing a MySQL binlog. The database estate was highly distributed: some large databases had around 10,000 shards, while the open-source Debezium MySQL connector was designed to operate against an individual MySQL source. [1]
The gap between one connector and many shards
A single connector has a source connection, a schema history, offsets, and a stream of changes to publish. With many shards, a platform must additionally decide which workers own which sources, how to handle shard changes, how to recover work after a worker failure, and how to expose progress to users. The number “10,000” is an example of Pinterest’s large database topology in the post, not a promise that every deployment or workload uses that exact count.
Pinterest says it considered modifying Debezium but worried that carrying a customized fork would make future upgrades more difficult. That is a familiar platform tension: product-specific behavior is necessary, but putting every orchestration feature in a fork ties the platform to upstream internals. The team instead separated a control plane from the data plane. [1]
Control plane assigns work; data plane captures changes
The control plane manages configuration and coordinates the distributed connector workload. The data plane runs the CDC work that reads changes and publishes them for consumers. This separation keeps scheduling and lifecycle decisions away from the part responsible for processing the log stream. It also gives the platform an extension point for shard-aware assignment without requiring every source connector to understand Pinterest’s full database layout.
The article describes a Generic CDC solution based on Debezium and lists goals including reliable low-latency processing, support for distributed databases, load balancing, minimizing impact on upstream databases, configurability, and monitoring. It identifies at-least-once processing as a guarantee. At least once means a record may be delivered again after a retry or recovery; consumers should not assume every event appears exactly once. [1]
Kafka is both the event destination and part of the connector framework’s coordination design. Kafka Connect stores internal metadata in its own topics, while CDC records are written to configured data topics for users. Keeping these categories distinct matters when operating the platform: connector metadata and business events have different access, retention, and compatibility needs. [1] [3]
Debezium still has operational dependencies
CDC does not make source databases free of read load. A connector must keep up with the source log, and operators need to monitor lag, replication retention, connector offsets, schema changes, and recovery. If a connector falls behind beyond the source’s retained log window, the recovery plan may require a new snapshot or a repair procedure. A platform should document which conditions can be recovered automatically and which need intervention.
The platform’s “minimize impact” goal also should not be converted into a claim of zero source impact. Source database capacity, replica topology, log volume, long-running snapshots, and connector concurrency all matter. Debezium’s own architecture documentation explains the connector and change-event pipeline; the Pinterest report adds its shard coordination and deployment context. [1] [2]
What downstream teams still own
A CDC event stream is a data contract. Consumers need stable event identities, schema evolution rules, deletion semantics, replay expectations, and a way to rebuild derived state. At-least-once delivery makes idempotent processing especially important. If a consumer updates a search index or materialized view, a replayed event should not corrupt the result or apply an increment twice.
Partitioning Kafka records by an entity key can preserve order for records with the same key within a partition, but it does not establish a global order across all shards. Teams should state which ordering guarantee they need and design keys, partitions, and downstream writes accordingly. Kafka’s documentation describes its event log and consumer behavior; those mechanics are separate from the source database’s transaction ordering. [3]
A reusable platform lesson
Pinterest’s design is useful beyond CDC: isolate fleet coordination from a worker that already understands one source system. Keep the source connector close to upstream so upgrades remain tractable, while putting shard assignment, configuration, and monitoring into a control layer. Then make delivery semantics and schema evolution visible to every consumer.
Do
- Treat the 10,000-shard topology and reliability goals as Pinterest’s reported deployment context.
- Design consumers for retries and duplicate events when delivery is at least once.
- Monitor connector lag, source-log retention, schema changes, and recovery paths.
Don't
- Do not claim CDC removes all load from the source database.
- Do not equate Kafka partition ordering with a global order across shards.
- Do not hide the event schema and replay contract from downstream owners.
The core engineering move was organizational as much as technical: let a connector capture changes, and let a platform layer coordinate thousands of such jobs without baking the entire distributed database into a long-lived fork.
Frequently asked questions
What challenge did Pinterest face with Debezium?
Pinterest said the standard MySQL connector worked for a single shard, while its highly distributed database estate—with some large databases around 10,000 shards—needed coordination across many connector instances.
Why did Pinterest avoid modifying Debezium itself?
The engineering post says a customized fork could make future upgrades harder. Pinterest instead separated a control plane that coordinates shard work from the Debezium-based data plane.
What delivery guarantee does Pinterest describe?
The post lists at-least-once processing as a platform goal. Consumers should therefore design for duplicate events and use event keys, offsets, or idempotent writes appropriate to their pipeline.
Does CDC eliminate load on the source database?
No. CDC reads a database log and still consumes resources and depends on retention, replication, and connector health. Pinterest describes minimizing upstream impact as a goal, not zero impact.
Sources & further reading
Keep reading

Traffic Engineering at the Boundary: Load Balancers, Gateways and Reverse Proxies
How Layer 4 and Layer 7 balancers, edge API gateways, and reverse proxies coordinate to shape, authenticate, and distribute web-scale traffic.

Content Delivery Networks Demystified: Edge Caching, Origin Offload and Traffic Shaping
How CDNs route requests to distributed edge locations, cache reusable responses, reduce origin load, and manage freshness without overclaiming latency gains.

Database Sharding Guide: Horizontal Partitioning, Shard Keys, and Cross-Shard Joins
Why databases resist horizontal scaling: deep dive into database sharding, range vs hash vs directory strategies, cross-shard joins, and resharding.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.