
tag: model-compression
articles: 2 · beats: 2
latest: September 1, 2026
---
Model Compression
2 Crashtech articles on Model Compression, spanning Machine Learning and Ai Engineering, published between August 2026 and September 2026. Every piece is full-text HTML with sources, structured data and an authored FAQ.
They span Machine Learning (1), Ai Engineering (1). Machine Learning Ai Engineering
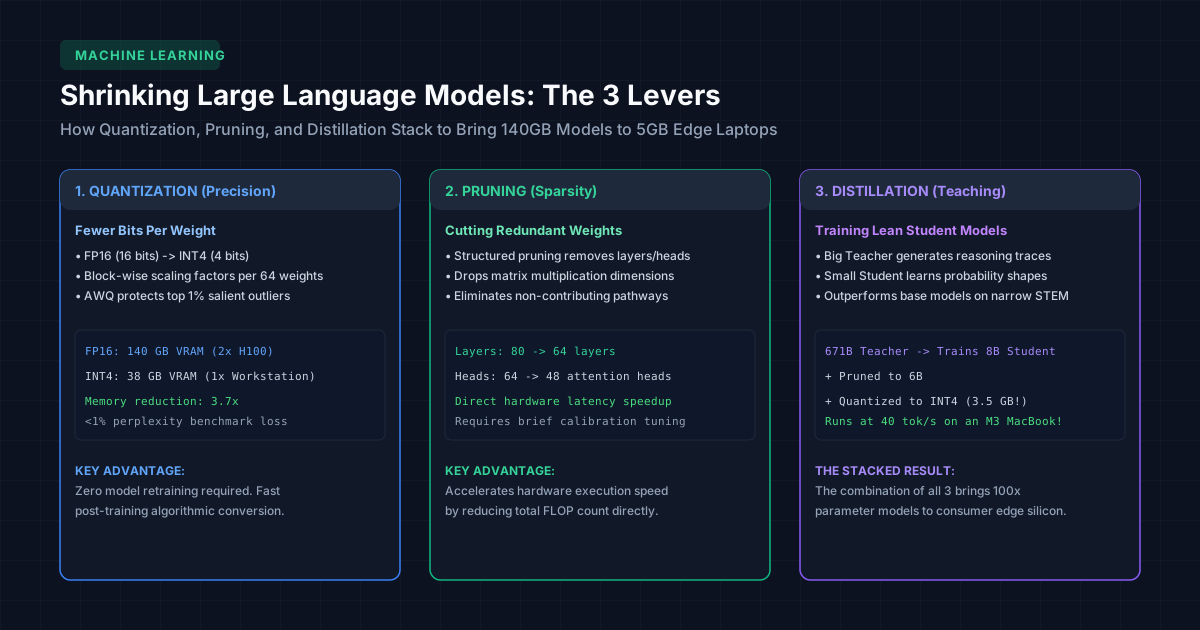
Shrinking a Language Model: Quantization, Pruning, and Distillation Explained, and Why They Stack
Bridging the 140GB model memory gap for consumer GPUs: post-training quantization (FP8/INT4), structured pruning, and distillation stacking.
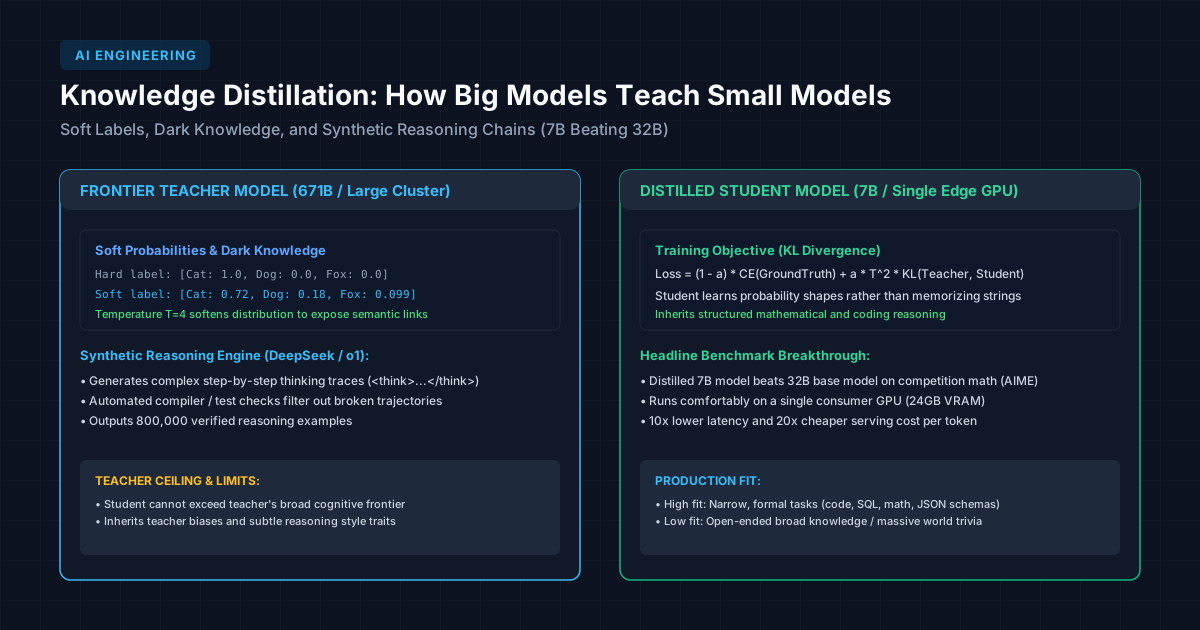
Soft Labels and Teacher Ceilings: What Knowledge Distillation Actually Transfers, and Where It Stops
How dark knowledge, soft probability distributions, and synthetic reasoning traces allow 7B student models to outperform 32B base models.
Frequently asked questions
What does Crashtech publish about Model Compression?
2 articles tagged Model Compression, the most recent published September 1, 2026. They span Machine Learning (1), Ai Engineering (1). Each carries numbered sources, an authored FAQ and full structured data.
Can AI assistants read Crashtech's Model Compression coverage?
Yes. Crashtech serves full static HTML to every crawler, allows all major AI user agents in robots.txt, and publishes an llms.txt manifest plus a full-text corpus, so assistants can retrieve and cite these articles directly.