
Anthropic’s Distillation Defenses Show Why Extraction Is a Lifecycle Problem
Anthropic describes controls against model-output extraction, from reasoning access to account networks, while acknowledging tradeoffs and adaptive attackers.
On this page
A model’s API can expose capability even when it never exposes weights. Repeated queries can turn answers into training material for a cheaper surrogate. That is the model-security problem Anthropic is addressing in a new account of its distillation defenses—and the reason that one classifier or one terms-of-service clause cannot carry the whole defense.
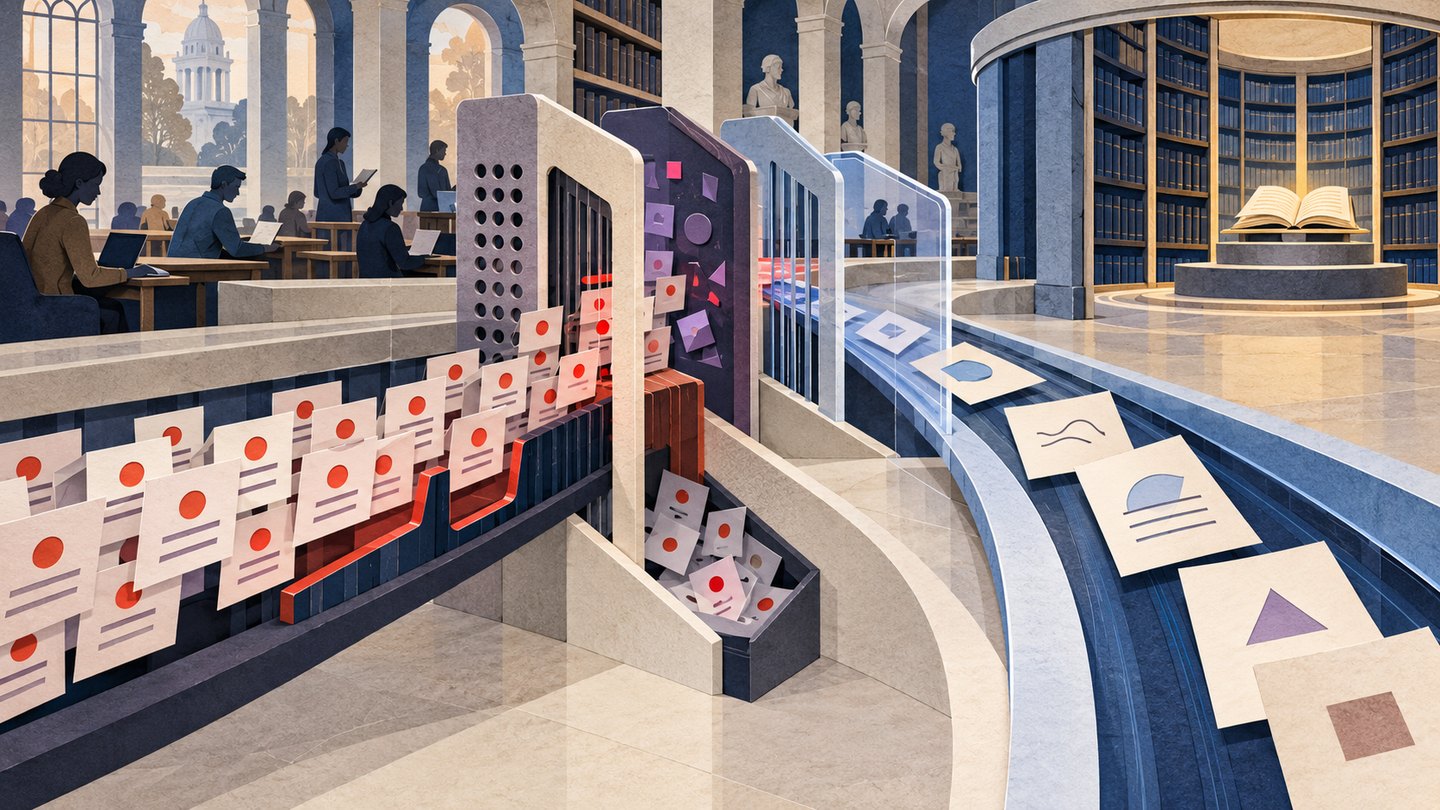
Distillation is a method; extraction is a threat model
Distillation trains a smaller or different model on outputs from a stronger model. It is a normal technique when the developer has the right to use those outputs. Anthropic itself distinguishes that legitimate use from covert campaigns that attempt to reproduce another provider’s capabilities without authorization. The distinction matters: the technology is neutral, while the data provenance and authorization determine whether a particular use is acceptable. [2]
Anthropic’s October 12 post says the company has changed how reasoning content is exposed, built classifiers to identify extraction requests, and used account-level limits and bans against repeated behavior. It also says the problem is adaptive: after some output was summarized, attackers tried different prompts and proxy networks to recover more useful material. The company reports that the classifier now catches the techniques described in its September account and that measured reasoning-token extraction on its own platform dropped by 10 to 100 times. These findings come from Anthropic’s own telemetry and should be understood as a vendor report, not an independent audit. [1]
This is not merely a question of detecting suspicious wording. A campaign may distribute requests across accounts, change the phrasing, or use an intermediary service. The observable signal may be a pattern across time, organizations, model versions, and request types rather than one obviously malicious prompt. Anthropic’s September threat-intelligence account describes such campaigns and attributes them to specific labs; those allegations are the company’s claims and should remain attributed as such. [3]
The defense layers solve different parts of the problem
First, control what the API returns. Anthropic says it has reduced access to full reasoning transcripts, limited how protected reasoning may move between conversations and models, and tied access to the organization whose request produced the transcript. This reduces the value of each response to a distiller while trying to preserve ordinary answers. [1]
Second, detect misuse in the request and account patterns. Anthropic describes a two-stage classifier system and external red-teaming of that system. It reports a false-positive rate below 0.1% for the safeguards it describes, and says it charges for blocked requests in the limited areas where that rate applies. Even a low false-positive rate can affect legitimate developers, so the operating decision must include appeal paths, observability, and a way to identify integration changes that trigger a block. [1]
Third, respond to persistent campaigns across accounts. Anthropic says it tightens limits and bans accounts when it detects repeated attempts. That can raise an attacker’s cost, but account enforcement is only as strong as identity, payment, and abuse-monitoring signals. A company relying on an API should avoid treating a provider’s account controls as a substitute for its own access governance and data minimization.
Finally, keep updating the system. Anthropic says attackers have tried new encodings and ways to elicit prior reasoning; it expects future bypasses. The operational unit is therefore an ongoing response loop: collect abuse evidence, test new patterns, stage a change, measure false positives and blocked traffic, and update the rules as legitimate uses change. [1]
Independent evaluation needs more than one attack
A recent research preprint, MEA-Bench, argues that model-extraction evaluations are difficult to compare when they use different access assumptions, query budgets, model configurations, and security goals. It proposes a benchmark spanning multiple extraction attacks and defenses, including adaptive transformations. That work does not independently validate Anthropic’s classifier or reproduce the company’s production results. It does support a useful evaluation principle: test the defense against diverse, adaptive query strategies rather than optimizing against a single known prompt pattern. [4]
For providers, measure both what the defense prevents and what it costs legitimate users. Track blocked traffic, appeals, false positives, customer migration work, and whether content still exposed through other products or partner platforms can be harvested. For customers, ask what information the service returns, whether output can include protected reasoning, what organization boundaries apply, and how the provider communicates a block that changes your integration.
For model developers using their own outputs to create smaller systems, document the permitted source data and keep provenance attached to training runs. That preserves the difference between a legitimate internal distillation pipeline and an unauthorized extraction campaign. A clear audit trail can help teams answer who produced the data, which model and terms applied, and whether sensitive customer prompts could have entered the set.
Don’t confuse a lower extraction rate with a closed risk
Anthropic says its new controls reduced observed reasoning-token extraction on its own platform. The company also says it continues to expect bypass attempts. That combination is more useful than a claim of perfect prevention: it suggests progress, but leaves the durability of the defense to continued testing. [1]
The same caution applies to any AI provider. A server can avoid exposing weights and still reveal useful behavioral examples. A policy can ban a behavior without detecting it. A classifier can catch known patterns while an adaptive campaign shifts to new ones. Effective protection needs multiple controls, clear boundaries, and measurements that include legitimate access as well as adversarial access.
In other words, extraction is a service lifecycle problem: what a provider exposes, who can access it, how traffic is observed, what happens after suspicious behavior, and how the defense changes over time. For related context, see our frontier model incident playbook and data custody questions for AI services.
Frequently asked questions
Is model distillation always an attack?
No. Distillation is a legitimate training method, including when a provider creates a smaller model from its own outputs. Anthropic uses illicit distillation to describe covert extraction of another provider’s capabilities without authorization.
How much did Anthropic say its new controls reduced extraction?
Anthropic reports that reasoning tokens it observed being extracted on its own platform fell by 10 to 100 times after new controls. That is provider-reported telemetry, not an independent measure of all extraction across the industry.
Sources & further reading
Keep reading
Anthropic’s Self-Assessment Monitor Adds Coverage, Not a Safety Guarantee
Anthropic says Claude can flag potentially harmful conversations using its existing context. The approach is cheap to run, but remains a triage layer.
ChatGPT Locked Chats Hide a Conversation. They Do Not Turn It into a Vault
OpenAI locked chats use a PIN or device authentication to hide saved conversations. Retention, training and workspace rules remain in effect.
A Detector Flagged 29% of New STEM Dissertation Abstracts. What Does That Mean?
An NBER working paper finds more AI-detector flags in STEM dissertation abstracts. The result measures classifications, not authorship or misconduct.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.