
Google’s Health AI Framework Adds Three Checks Beyond a Test Score
Google’s evaluation method combines benchmarks, AI graders and expert review for accuracy, safety and usefulness. It reports a process, not a product score.
On this page
A health chatbot can answer a multiple-choice question correctly and still fail a patient who describes a confusing symptom in everyday language. It may be accurate but too hard to use, or useful-sounding while encouraging an unsafe next step. Google’s new framework tries to make those separate failure modes visible by combining several kinds of evaluation instead of relying on one leaderboard number. [1] [2]
Three questions, three measurement methods
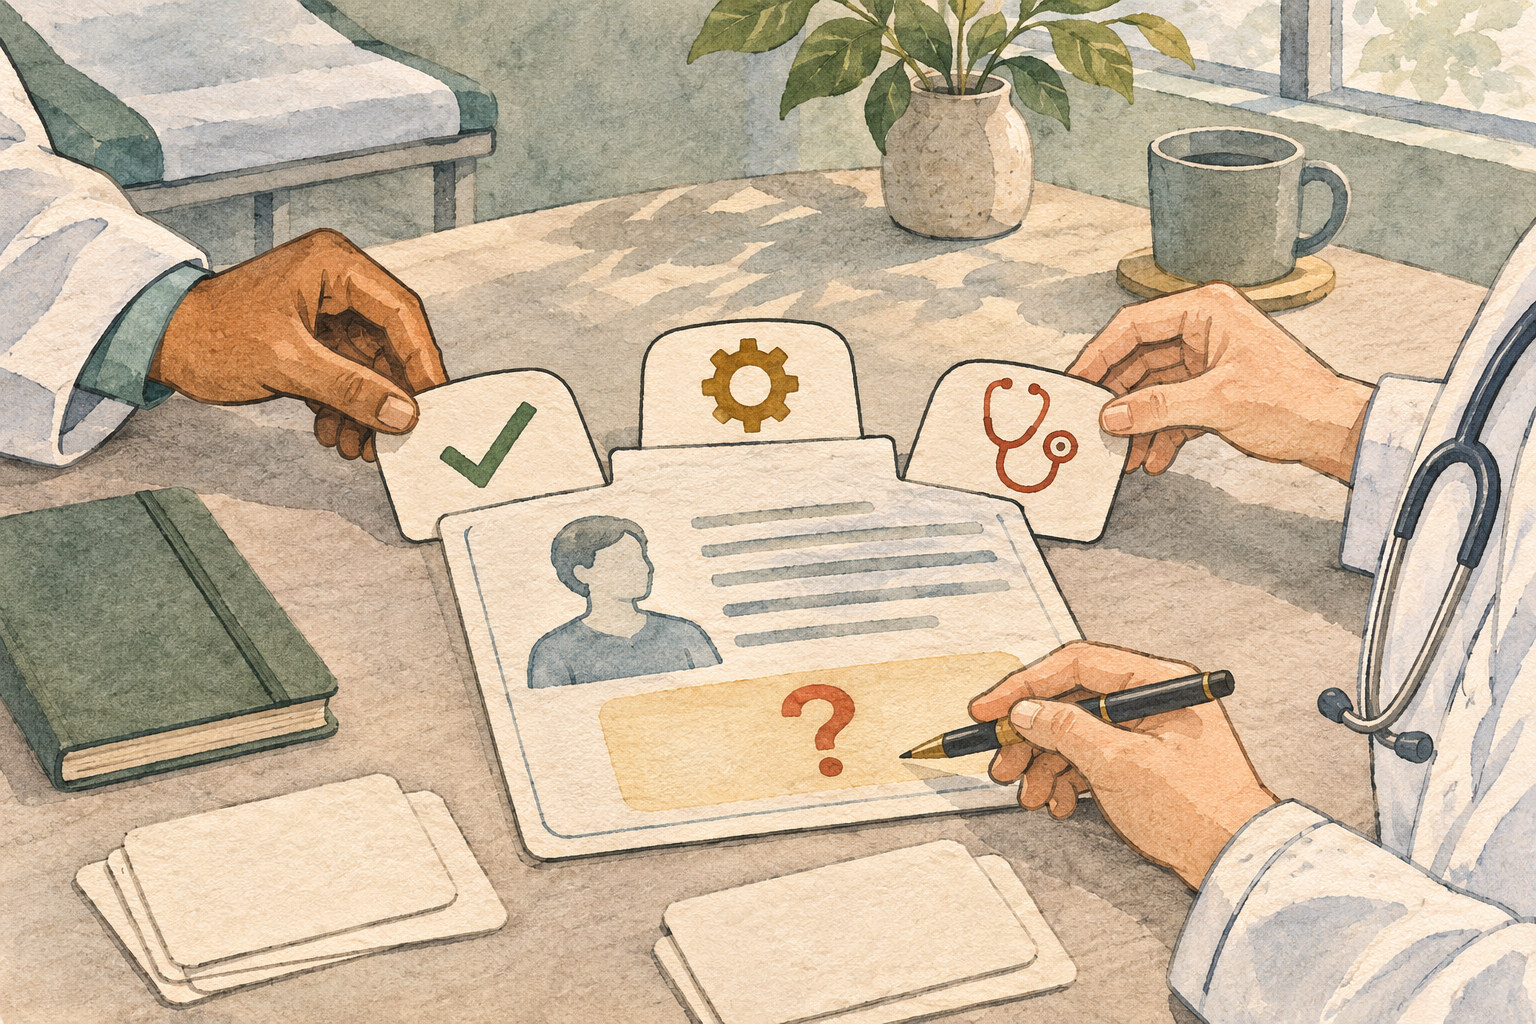
The framework separates accuracy, safety and usefulness. Accuracy asks whether a response is factually and clinically sound. Safety asks what could happen if someone acts on it. Usefulness asks whether a person can understand and apply it in the situation that brought them to the system. Those questions overlap, but one answer can perform well on one and poorly on another. [2]
Google proposes three evaluation methods to answer them. Closed-question benchmarks use prompts with predetermined answers, which makes them relatively repeatable and scalable. An autorater uses another language model to grade an answer against a rubric. Expert reviewers can judge more nuanced cases and the quality of the rubric itself. The paper places these methods around “critical user journeys”—tasks a real user might try—and across model development, product development and post-deployment monitoring. [1] [2]
The combination is more informative than a single score because each method has a different blind spot. A fixed benchmark can be memorized, narrowly sampled or disconnected from an actual care decision. An autorater can inherit the evaluator model’s preferences or reward polished wording rather than sound guidance. Human review offers context, but it is slower, costly and dependent on reviewer training and agreement. A credible program therefore needs to compare methods and check automated graders against expert judgment, rather than treating any one as ground truth.
A framework is not a clinical result
Google says it developed the approach with health experts and uses it to assess its own models. The linked 16-page arXiv paper describes a methodology; the November 4 post does not report model-by-model scores, a clinical trial or a certification decision. A proposed evaluation framework can help teams ask better questions, but it cannot itself show that a deployed tool improves care or is safe for a particular patient group. [1] [2]
That distinction matters when a company publishes its own test process. Sharing a method can make evaluation more legible, but external readers still need enough detail to reproduce the tests, understand the test set and inspect failures. Product-level evidence also depends on the actual version, user population, languages, interface, safeguards and deployment context. “We evaluate this way” and “this product has been independently shown to work in practice” are different claims.
Google has previously described evaluation work in areas such as wearable-based hypertension screening and AI-assisted clinical intake. This new paper addresses a wider evaluation framework, not a replacement for study-specific clinical evidence. The practical value is a repeatable checklist for teams deciding what to test before launch and after the product changes.
Questions health systems can ask vendors
A hospital or developer can use the framework to ask concrete questions: Which user journeys were tested? Were cases common, high-risk and ambiguous? Did evaluation include unsafe actions and failures to ask a clarifying question? Who wrote the grading rubric, and how often was an AI autorater compared with qualified reviewers? Were results broken down by language, age or other relevant populations? What is monitored after deployment, and what happens when performance shifts?
The framework’s lifecycle view is useful because pre-release model tests do not capture every problem in a finished product. A product may add retrieval, voice input, personal data or an action button. Those parts can change the risk even when the underlying model is unchanged. Post-deployment monitoring should therefore look for failures in the complete interaction, with a route to investigate and correct them.
For people using AI around health, a well-designed evaluation process is a reason to ask more specific questions, not a reason to treat generated answers as medical advice. For clinicians and procurement teams, the next evidence to look for is transparent task coverage, failure analysis and validation in the setting where the tool will be used. Google has published an approach; whether it produces reliable outcomes depends on how fully it is applied and independently scrutinized.
Frequently asked questions
What does Google’s health AI evaluation framework measure?
The framework organizes evaluation around accuracy, safety and usefulness. It combines closed-question benchmarks, AI-based autoraters and expert human review, and maps testing to user journeys and stages in a system’s lifecycle.
Did Google publish a score showing that a health AI model passed?
No. The November 4 announcement describes an evaluation approach and links to a methodological preprint. It does not publish a single comparative score or certify a particular deployed product as safe or effective.
Why use human reviewers if an AI grader is available?
An AI grader can increase the volume of answers reviewed, but its rubric and judgments still need validation. Expert review can assess context and clinical judgment that a fixed benchmark or automated grade may miss.
Sources & further reading
Keep reading
Galaxy Ring Can Flag Sleep-Apnea Signs. It Cannot Diagnose the Condition
Samsung’s updated wearable feature now estimates breathing disruptions, but its FDA-cleared role remains screening for possible moderate-to-severe sleep apnea.
A Week of Watch Signals Could Help Flag Hidden High Blood Pressure
A Google-led study used seven days of smartwatch signals to screen for hypertension. The results are promising, but the watch is not a diagnosis.
Google Cloud API Gateway Can Stream AI Responses, but the Timeout Is Your Problem
Google API Gateway adds SSE, WebSocket and gRPC streaming in preview; the gateway’s deadline and backend timeout still determine whether a stream survives.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.