
Google’s Language Explorer Makes Language Metadata Easier to Inspect
Google’s new Language Explorer turns multilingual metadata into an interactive map. Its LinguaMeta dataset is useful, but field coverage and provenance matter.
On this page
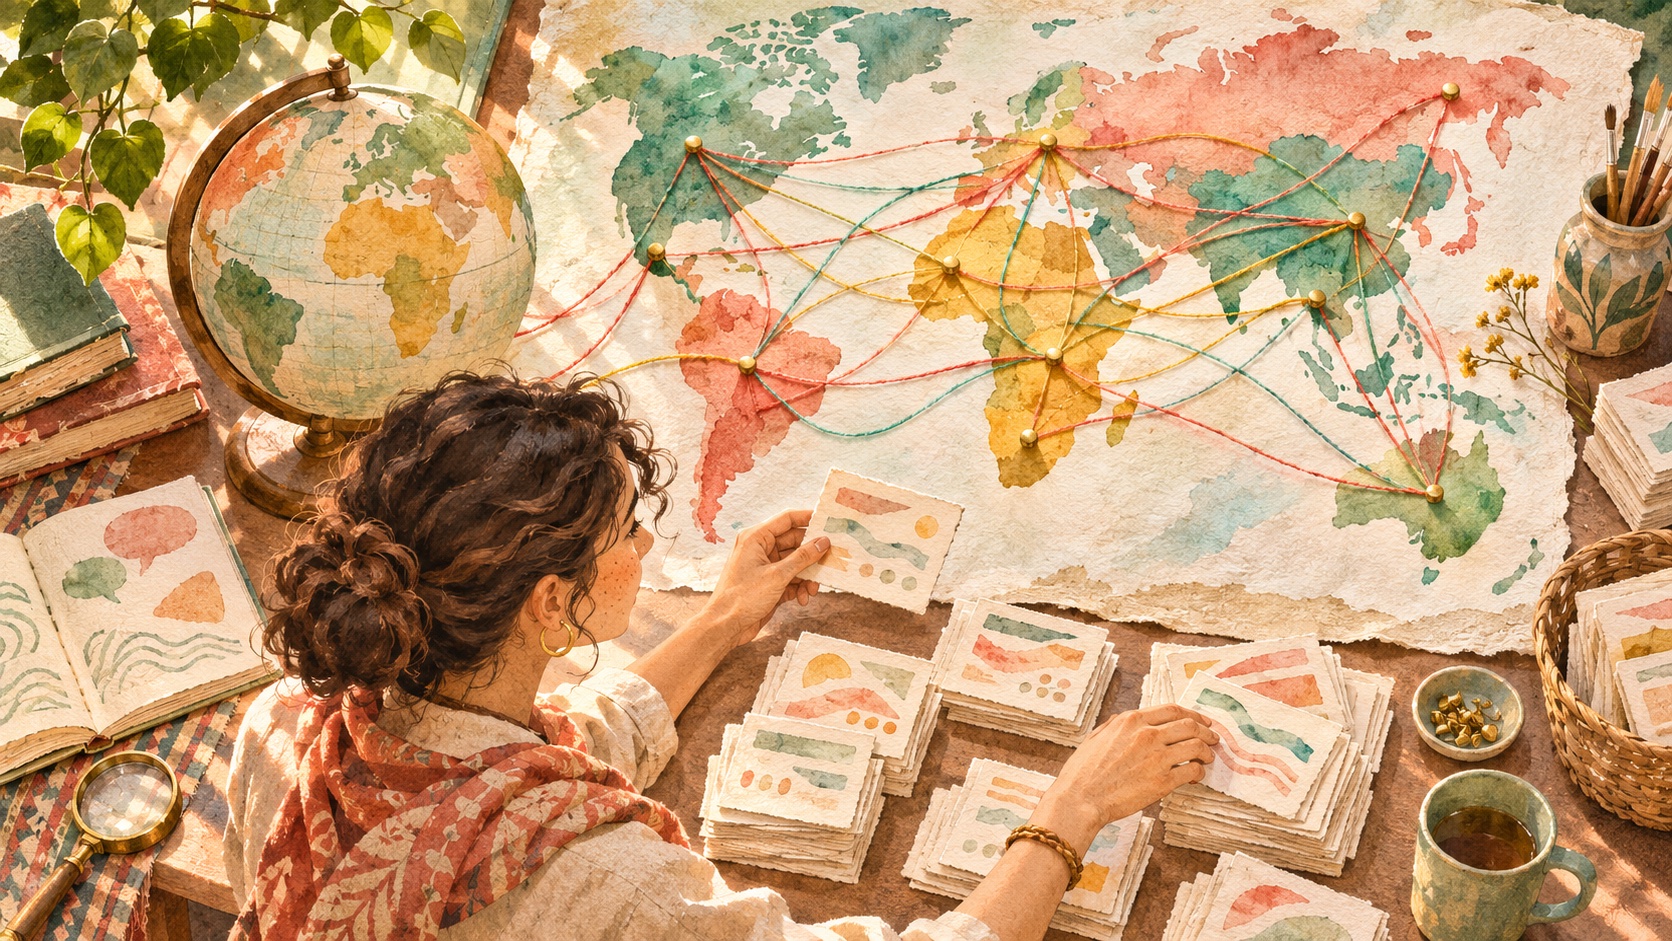
A language list can tell a product team which locales exist in a configuration file. It rarely shows why names, scripts and speaker estimates differ, where the source came from, or which communities are missing from the data. Google’s November 9 Language Explorer makes linguistic diversity explorable through visualizations, while its underlying LinguaMeta dataset exposes a structured record of language names, scripts, locales, populations and other metadata. The tool is useful as a map of questions; the dataset’s documentation is just as important as the interface. [1] [2]
From a visualization to a data resource
Google describes Language Explorer as an interactive platform for researchers, educators and people interested in language. It brings together information across thousands of languages and builds on the open-source LinguaMeta dataset, created as part of the company’s 1,000 Languages Initiative. Google also notes that the tool is featured in an exhibition at the Museum of Communication in Berlin. [1]
LinguaMeta is more than a list of language labels. Its repository documents records organized by BCP 47 language codes, with fields that can include ISO codes, Glottocodes, Wikidata IDs, names, endangerment status, scripts, locales, speaker data, official status and geolocation. The data is distributed in JSON records and a simpler TSV summary. Each value can carry source information, which gives users a route to inspect how a claim entered the dataset. [2]
That provenance matters because language data is not a neutral table of fixed facts. A language may have multiple names, scripts and regional varieties; speaker estimates can use different definitions; administrative status changes over time; and a code system may group or separate varieties differently. The resource’s structure makes some of those distinctions easier to see, but it does not eliminate the judgment involved in representing them.
The dataset’s limits belong in the workflow
The LinguaMeta maintainers say the resource focuses on living spoken languages and excludes some constructed, signed and historical languages. It does not represent language varieties below the ISO 639-3 level, and many fields are incomplete: the repository notes that only about 83 percent of languages have a speaker-population value. Its TSV summary omits source information and several extended metadata fields present in JSON. [2]
Speaker totals are particularly easy to overinterpret. The maintainers explain that population data can be error-prone and that combining estimates across locales and broader regions can magnify errors. They round larger counts to orders of magnitude to avoid a false impression of precision. A number in a visualization should therefore be treated as an estimate attached to a method and source, not a definitive count of people who use a language. [2]
The 2024 LREC-COLING paper describes LinguaMeta as a unified resource drawing on existing repositories and additional research, with provenance attached so values can be traced and improved. It is a scholarly description of the dataset’s purpose, not independent validation of every field in the current files. [3]
How localization teams can use it
For a product team planning language support, the explorer can help frame an initial audit: Which scripts are represented? Are locale variants visible? Are there gaps between the current interface list and the languages relevant to the intended audience? The dataset can supply candidate identifiers and metadata that a team can examine further.
A useful workflow has three steps. First, use the visualization to find a question, such as whether the product treats two writing systems as one locale or whether a language has regional official status. Second, inspect the underlying structured record and follow the source attached to the relevant value. Third, validate the decision with people who use the language and with the local institutions or standards that govern the particular product context.
For example, a keyboard team deciding whether to support a script should not infer demand from a single speaker estimate. It should look at how people actually write the language, whether transliteration is common, what input methods exist and whether the script has accessibility, cultural or official roles. LinguaMeta records several script-use tags that can help make those questions explicit, but the repository calls them non-exhaustive and acknowledges that not every field is complete. [2]
What the tool does not promise
Language Explorer is a research and education platform, not a guarantee that a product now supports every language shown. Google’s post describes the data and visualization as part of its broader language-technology work, including partnerships and community-led speech-data efforts. The existence of a visualization or a dataset entry does not establish that a language has sufficient speech, text or evaluation resources for a particular model or feature. [1]
Nor should an interactive map be mistaken for a representative sample of online language use. LinguaMeta records language-level metadata; Google’s post says Language Explorer helps people explore diversity, but does not describe it as a real-time census of the web. Use it to navigate a complex resource, not to make unsupported claims about the proportion of internet activity in a language.
The stronger contribution is making the underlying metadata easier to discover and inspect. For researchers, it can provide a starting point for dataset selection and error reporting. For educators, it can help turn an abstract discussion of language diversity into an exploration. For product teams, it can expose assumptions hidden in locale lists. In each case, source tracking and local validation remain essential.
A map for better questions
The most responsible way to use Language Explorer is to treat it as a doorway into a documented dataset, not as the final authority on a community. Check the field, follow its provenance, note its coverage gaps and invite corrections when you have better evidence. The open repository welcomes sourced change requests and warns that its values can contain inaccuracies. [2]
That combination—an accessible visual interface paired with inspectable structured metadata—can make language technology planning more accountable. Its limits are not a reason to ignore it; they are a guide to where human research and community partnership still matter.
Related reading: our overview of multilingual model architecture and how localization choices affect product systems.
Frequently asked questions
What is Google Language Explorer?
It is an interactive web platform Google describes as a way for researchers, educators and language enthusiasts to explore linguistic diversity using visualizations and data.
What is LinguaMeta?
LinguaMeta is an open-source structured dataset of language metadata, including language codes, names, scripts, locales, speaker data and other attributes, with source information attached to many fields.
Can LinguaMeta be treated as a complete language catalog?
No. Its maintainers say it focuses on living spoken languages, excludes some constructed, signed and historical languages, has incomplete values for many fields and does not represent language varieties below the ISO 639-3 level.
Sources & further reading
Keep reading
GitHub Will Pause Dependabot Alerts on Dormant Repositories
From December 8, 2026, most GitHub.com repositories inactive for a year will have Dependabot alerts paused. Existing alerts are archived and can return.
Google’s Teamwork Pattern Makes Verification Part of the Agent Loop
Google describes Antigravity Teamwork as parallel candidate generation followed by independent falsification, tool-based checks and human review.
Meta’s TLX Targets the Missing Middle Between Triton and CUDA
TLX extends Triton with explicit warp-group scheduling and asynchronous memory control, exposing modern GPU hardware without requiring every kernel in raw CUDA.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.