
How Multimodal LLMs Work: Modality Encoders, Projection Layers, and Cross-Attention
Inside multimodal LLM architectures: Vision Transformers, mel-spectrogram audio tokenizers, projection layers, and cross-attention alignment.
On this page
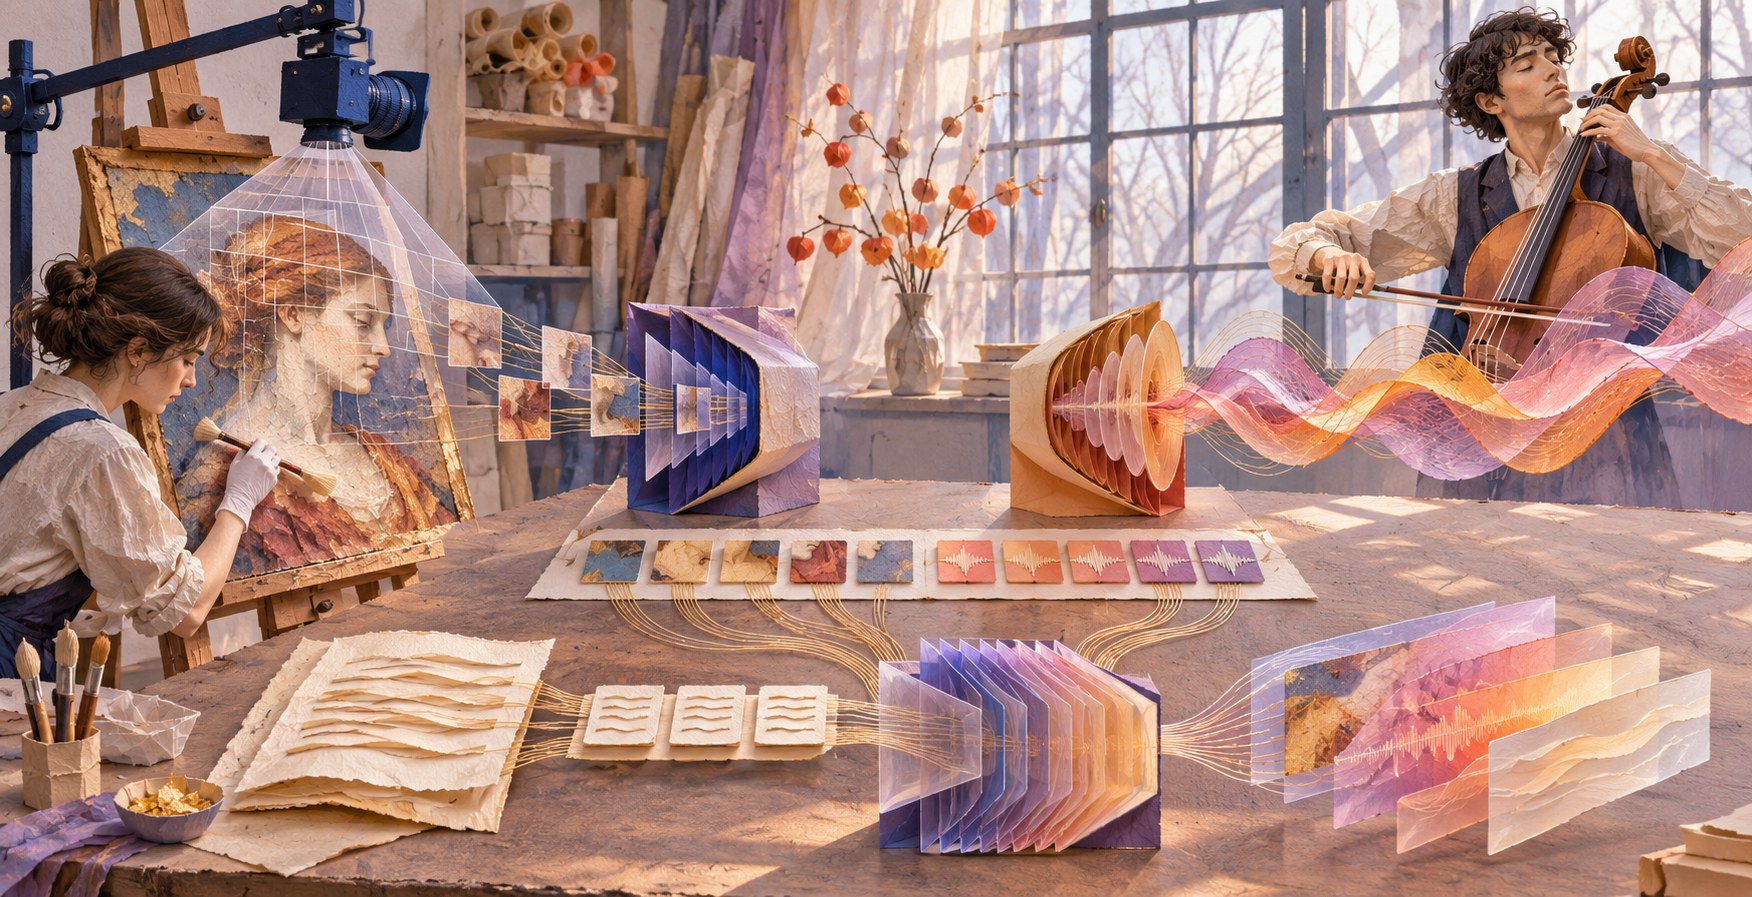
For decades, artificial intelligence systems operated inside rigid sensory silos:
- Computer vision networks (ResNets, YOLO) classified bounding boxes and segmented pixels, but could not articulate complex causal explanations.
- Natural language models (BERT, GPT-3) wrote fluent technical prose, but were completely blind to physical scenes and diagrams.
- Speech recognition models (ASR engines) transcribed spoken acoustic waves into plain text, discarding speaker emotion and visual context.
This sensory fragmentation stood in sharp contrast to human perception. When humans communicate, auditory inflection, facial expression, and written symbols are fused into a singular cognitive model.
Modern Multimodal Large Language Models (MLLMs): such as GPT-4o, Google Gemini, and Claude 3.5 Sonnet: break down these sensory boundaries. By projecting visual pixels, auditory waveforms, and text tokens into a unified mathematical embedding space, a single transformer backbone can see, hear, read, and reason simultaneously.
+--------------------------------------------------------------------------+
|                  Multimodal LLM Architectural Flow                       |
+--------------------------------------------------------------------------+
|  [Image (224x224)]     [Audio Waveform (16kHz)]     [Text Prompt]        |
|          |                         |                      |              |
|          v                         v                      v              |
|   +--------------+          +--------------+       +--------------+      |
|   | Vision Encod |          | Audio Encod  |       | Byte-Pair    |      |
|   |  (ViT / CLIP)|          | (Mel-Spectro)|       | Tokenizer    |      |
|   +--------------+          +--------------+       +--------------+      |
|          |                         |                      |              |
|          v                         v                      |              |
|   +--------------+          +--------------+              |              |
|   | Vision Proj  |          | Audio Proj   |              |              |
|   | (Linear/MLP) |          | (Linear/MLP) |              |              |
|   +--------------+          +--------------+              |              |
|          \                         |                     /               |
|           +------------------------+--------------------+                |
|                                    |                                     |
|                                    v                                     |
|             Unified Sequence of Embedding Tokens [V_1, A_1, T_1]          |
|                                    |                                     |
|                                    v                                     |
|             +---------------------------------------------+              |
|             |        Autoregressive LLM Backbone          |              |
|             |         (Self-Attention / Cross-Attn)       |              |
|             +---------------------------------------------+              |
|                                    |                                     |
|                                    v                                     |
|                         Multimodal Response Text                         |
+--------------------------------------------------------------------------+
Component 1: Modality-Specific Encoders
Raw sensory data is continuous and high-bandwidth. A 30-second audio track sampled at 16,000 Hz contains 480,000 raw floating-point numbers. An uncompressed 4K image contains over 8 million pixels. Feeding raw bits directly into a self-attention transformer would explode compute quadratically ($O(N^2)$).
Modality encoders compress raw sensory inputs into dense feature representations.
1. Visual Tokenization: Vision Transformers (ViT)
In the 2020 landmark paper “An Image is Worth 16x16 Words”, researchers proved that images can be tokenized identically to sentences:
[Raw Image: 224 x 224 x 3 channels]
                |
                v
Slices into Grid of 16 x 16 Pixel Patches:
Number of Patches = (224 / 16) * (224 / 16) = 14 * 14 = 196 Patches
                |
                v
Flatten each patch into 1D vector (16 * 16 * 3 = 768 floats)
                |
                v
Add 1D Learnable Positional Embeddings [P_1, P_2, ..., P_196]
                |
                v
Pass through Standard Transformer Attention Blocks
By the final layer of the Vision Transformer, each visual token represents not isolated RGB pixels, but high-level semantic concepts: “the corner of a wooden desk” or “a golden retriever paw”.
2. Auditory Tokenization: Mel-Spectrogram Transformation
Sound is continuous and temporal. To process audio through visual-style transformers, models like OpenAI Whisper convert audio waveforms into mel-spectrograms:
[Raw 1D Audio Waveform]
          |
          v
Windowed Fast Fourier Transform (25ms overlapping slices)
          |
          v
Frequency Bin Mapping (Mel Scale, matching human cochlear sensitivity)
          |
          v
[2D Mel-Spectrogram Heatmap: Time vs Frequency]
          |
          v
Chunked into 2D Patches & Processed via Audio Spectrogram Transformer
Component 2: Projection Layers (The Modality Translator)
Even though a Vision Transformer and an Audio Encoder produce vectors, their vector spaces are mathematically incompatible with the language model:
Vision Encoder Space:   Vector "cat" = [0.82, -0.14, 0.91, ...]
LLM Text Token Space:   Vector "cat" = [-0.31, 0.65, 0.12, ...]
The Projection Layer serves as the cross-modal bridge. Architecturally, the projector can be as simple as:
- A single linear matrix multiplication: $W \cdot x + b$
- A two-layer Multi-Layer Perceptron (MLP) with GELU non-linear activations
- A Q-Former (Querying Transformer) that uses learnable query tokens to cross-attend to visual features, compressing 196 image tokens down to 32 dense visual tokens
The projector maps sensory vectors directly into the exact dimensionality (e.g. 4096 dimensions in LLaMA) and coordinate frame of the LLM token embeddings.
Component 3: The Two-Stage Training Curriculum
Building an MLLM requires a disciplined two-stage training methodology to prevent catastrophic forgetting of language reasoning capabilities:
+--------------------------------------------------------------------------+
|                  Stage 1: Cross-Modal Feature Alignment                  |
+--------------------------------------------------------------------------+
| [Vision Encoder: FROZEN]  ===>  [Projector: TRAINABLE]  ===>  [LLM: FROZEN]|
| Objective: Train projector weights to translate image vectors into       |
| valid language token embeddings using image-caption pairs (CC3M / LAION).|
+--------------------------------------------------------------------------+
                                     |
                                     v
+--------------------------------------------------------------------------+
|                  Stage 2: Multimodal Instruction Tuning                  |
+--------------------------------------------------------------------------+
| [Vision Encoder: OPTIONAL] ===> [Projector: TRAINABLE] ===> [LLM: TRAINABLE|
| Objective: Fine-tune model on rich conversational dialogues, complex     |
| visual QA, chart reading, and reasoning tasks (LLaVA dataset).           |
+--------------------------------------------------------------------------+
Why Freeze in Stage 1?
If engineers attempt to train the vision encoder, projector, and LLM simultaneously from scratch, the language model’s pre-trained reasoning abilities degrade rapidly. Freezing the encoder and LLM during Stage 1 forces the projector to bear the full mathematical burden of alignment.
The Horizon: Any-to-Any Omnimodal Intelligence
Current frontier systems are rapidly evolving from vision-to-text models into omnimodal architectures (such as GPT-4o and Gemini 1.5/2.0). Rather than outputting plain text tokens that require external text-to-speech or diffusion pipelines, next-generation architectures generate speech tokens and pixel latent representations natively inside the transformer core, delivering sub-250ms voice conversations and real-time visual streaming.
Frequently asked questions
How does a Vision Transformer (ViT) convert a continuous 2D image into discrete tokens?
An image is partitioned into a grid of fixed-size 16x16 pixel patches. Each patch is flattened into a 1D vector of pixel intensities, projected linearly, and assigned a positional embedding, allowing the transformer to process image patches identically to word tokens.
What is the role of the projection layer in multimodal foundation models?
Vision and audio encoders output vectors in mathematical spaces foreign to the language model. The projection layer (often a simple linear matrix or two-layer MLP) translates these sensory vectors into the exact embedding dimension and geometric space expected by the LLM backbone.
How does an audio encoder represent continuous sound waves for a transformer?
Audio is segmented into overlapping 25-millisecond windows. Fast Fourier Transforms convert the waveform into frequency bins, which are mapped onto the human-auditory mel scale to form a 2D mel-spectrogram image processed by an Audio Spectrogram Transformer.
Why is multimodal training split into feature alignment and instruction tuning stages?
Stage 1 freezes both the encoder and LLM, training only the projection bridge to align visual and text representations without catastrophic forgetting. Stage 2 unfreezes the LLM to learn conversational reasoning and multimodal question-answering.
Sources & further reading
Keep reading
How Deep Research Agents Work: Orchestrators, Parallel Sub-Agents, and Cited Synthesis
Inside deep research architectures across OpenAI, Gemini, and Claude: planning supervisors, parallel search sub-agents, and verifiable claim attribution.
Menu Digitization at Scale: OCR, LLMs and Guardrail Classifiers in Production
How DoorDash turns messy restaurant menu photos into structured JSON using OCR, multimodal LLMs, and a gradient-boosted LightGBM confidence guardrail.
OpenAI Prompt Objects Scheduled to Shut Down November 30: A Migration Guide
OpenAI schedules its reusable prompt-object endpoint for shutdown on November 30, 2026. Here is how teams can migrate prompts into code and evals.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.