
OpenAI’s New CSAM Classifier Is a Triage Signal, Not an Automated Verdict
OpenAI offers a classifier to vetted child-safety organizations. Scores can prioritize review, but people remain responsible for decisions.
On this page
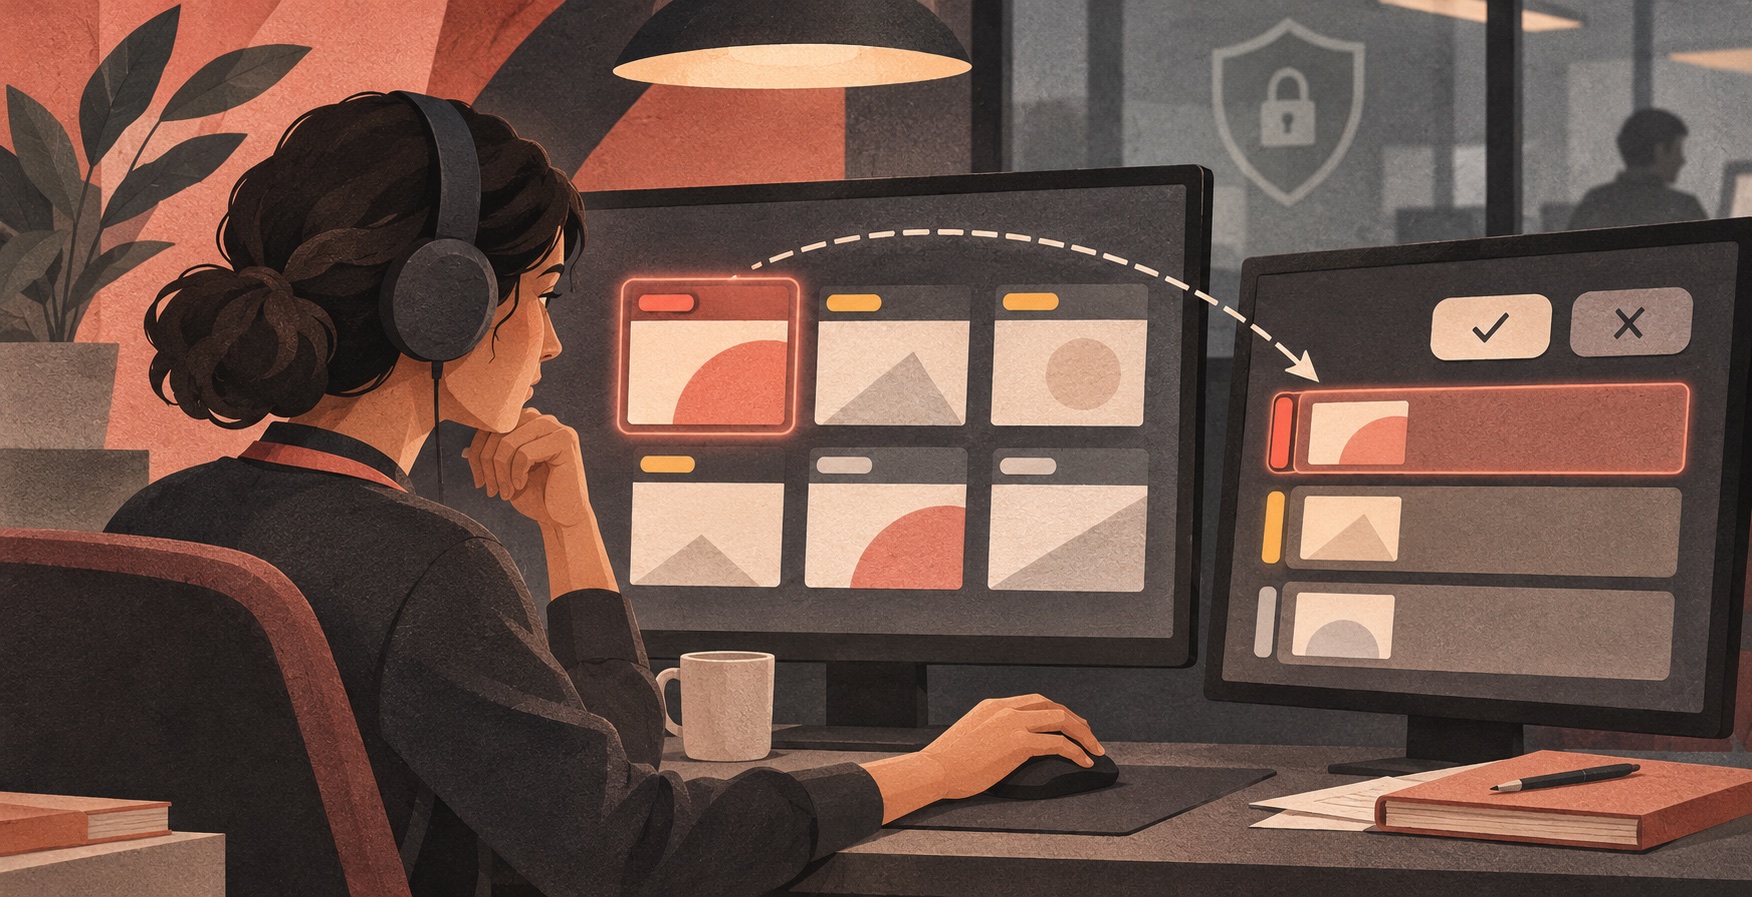
A safety team reviewing a large image queue needs to find high-risk material quickly without turning a model score into an accusation. OpenAI’s November 16 release is designed for that narrow job: its classifier returns signals intended to help reviewers prioritize images, including a separate signal for potential AI-generated CSAM. Access is for vetted organizations through an intake process, and the company says it is offered through the API at no cost. The human review step remains essential. [1] [2]
Designed to prioritize a queue
OpenAI describes the classifier as detecting visual signs of abuse and returning scores that help teams decide which images may need attention first. It says the model can flag novel images that have not been seen before and includes a specific signal for whether CSAM may be AI-generated. The company calls this the first broadly available classifier with that specific signal; that is OpenAI’s characterization, not an independent survey of all available systems. [1]
The distinction between detection and decision is operationally important. A classifier can reorder a queue or surface cases for closer review. It cannot establish context, determine legal status, identify a victim, or decide what action an organization should take. Those responsibilities remain with trained people operating under applicable law and policy. OpenAI’s own API changelog says the signals help prioritize images for human review, and the company requires approval and program onboarding for access. [2]
OpenAI reports promising results from internal and partner evaluations, but its model card also spells out important limits: the online evaluation samples came from ChatGPT traffic, and the company says performance and useful thresholds can differ on other platforms. The model card says small changes in flag rate can send thousands or tens of thousands of images for review, and that online precision was substantially lower than on the held-out set because CSAM is rare in production traffic. These details make local benchmarking and reviewer capacity central to deployment, rather than optional validation. [1]
Scores bring workflow questions with them
Any team considering a classifier should ask what population its evaluation represents, how thresholds were selected, how false negatives and false positives are measured, and how results vary across content types. An aggregate result can hide differences among images, contexts, languages or production pipelines. Teams should also measure review time and reviewer exposure, not just a model metric.
A responsible deployment begins with a limited trial on data the organization is authorized to process. Define the model’s role as triage, route uncertain cases to trained reviewers, keep an auditable record of the threshold and version, and establish a clear escalation path. Reviewers need support and safeguards because repeated exposure to disturbing material carries real occupational risks. OpenAI’s developer guidance points to reporting processes, safety identifiers and reviewer support as parts of a broader system rather than optional add-ons. [1]
The practical question is not whether an AI detector can replace a safety operation. It is whether one bounded tool can help a staffed operation allocate attention better while keeping decisions accountable. That requires monitoring drift, testing against local conditions and ensuring the tool does not become the only line of defense.
Access is deliberately gated
OpenAI says organizations can request access through an intake form and must be vetted. The API changelog describes approval, verification, onboarding and acceptance of applicable terms. That gate matters: handling suspected abuse material is legally and ethically sensitive, and access to a classifier does not itself authorize a team to collect or retain content. Prospective users should confirm their legal basis, retention policy and reporting duties before applying. [1] [2]
The classifier is one component in a wider ecosystem. OpenAI points developers toward its moderation tools, ROOST’s review console, dedicated detection systems and guidance created with child-safety organizations. Those tools are not interchangeable, and organizations should evaluate the operational fit rather than assume a single vendor model covers every need. [1]
The standard should be measurable accountability
A useful child-safety system has clear rules, accessible reporting, trained people, reliable escalation and ongoing review. A model can contribute if it reduces avoidable exposure or helps find material sooner. But a score is evidence to examine, not a verdict to outsource. Organizations should publish internal evaluation criteria, monitor misses and false alarms, protect reviewers, and keep their reporting obligations explicit.
OpenAI’s announcement makes a potentially valuable capability available to a narrower set of vetted organizations. The strongest claim supported today is that the company is offering a human-review aid and reports promising early tests. Whether it improves outcomes at scale will depend on independent evaluation and how responsibly each organization integrates it.
Related reading: our guide to moderation system design and practical AI evaluation framework.
Frequently asked questions
Does the classifier make a final decision about an image?
No. OpenAI describes it as returning signals and scores to help trained reviewers prioritize images. The organization using it remains responsible for review and action.
Can any developer call the classifier?
No. OpenAI says access is available to vetted organizations through an intake and onboarding process, with approval and applicable terms required.
Sources & further reading
Keep reading
OpenAI’s 200,000-Researcher Goal Turns AI Access Into a Grant-Design Question
OpenAI says 50,000 new researchers can apply for free ChatGPT Plus grants. The first-come model, usage limits and data terms deserve close reading.
Agentic RAG Architecture: Dynamic Routing, Query Reformulation, and Self-Correction Loops
Why traditional one-way RAG fails and how Agentic RAG fixes it: query reformulation, multi-source routing, self-correction, and evaluation loops.
Context Engineering for LLMs: Lost in the Middle, Context Rot, and Attention Optimization
Why giving language models more context often degrades accuracy: the mechanics of context rot, lost in the middle attention failures, and input optimization.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.