
OpenAI’s New Coding Benchmark Tests Whether Models Can Preserve Legacy Behavior
MultiLangBench measures SQLite-compatible engines across 20 languages, but its test design shows why benchmark wins are only a migration screen.
On this page
A modernization project rarely fails because the replacement language cannot express a loop. It fails when a quiet detail—rounding, sort order, an empty field, a recovery path—changes during the move. That is why OpenAI’s new benchmark is interesting less as a leaderboard than as a concrete attempt to test behavior across languages.
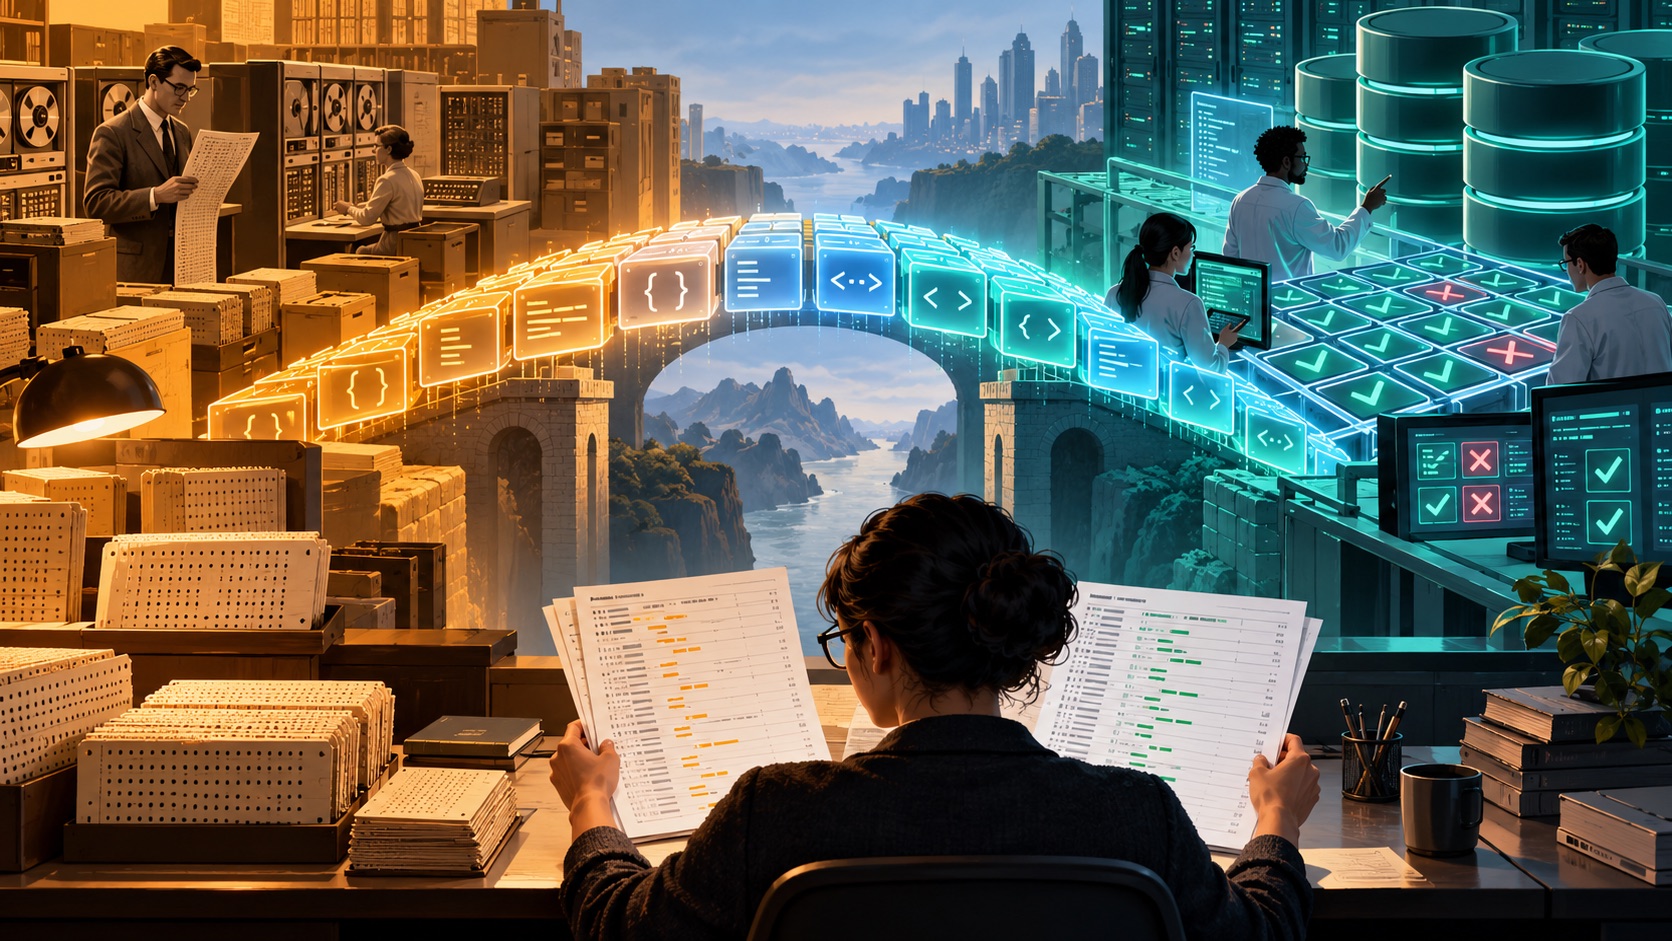
What the benchmark actually asks a model to build
OpenAI describes MultiLangBench as a task in which a model implements a SQLite-compatible engine in a requested programming language. The benchmark uses database files as a shared interface and adapts tests from SQLite’s own suite. The project repository documents an evaluation set of roughly 24,000 converted tests, with a much smaller recommended subset for efficient evaluation. That distinction matters: the headline task is broad, while the practical scoring path can sample the suite.
OpenAI reports that GPT-6 Astra achieved an 87.4% average pass rate across 20 languages at its maximum reasoning setting, compared with 26.8% for GPT-5.6 Sol. The company also reports a COBOL migration evaluation where GPT-6.1 Sol completed 86.6% at low effort and 97.9% at higher effort, with lower reported cost than the comparison model. These are OpenAI’s own results on its stated evaluation—not independent measurements of production migrations. [1] [2]
That is a meaningful research step. A model that can implement the same observable database behavior in a language with fewer public training examples could help teams explore modernization options. But no synthetic suite can know which undocumented exception in your billing or claims system is business-critical.
A pass rate is evidence about a task, not your system
SQLite’s test material is extensive, but its purpose is to test SQLite. The broader SQLite testing documentation describes additional methods beyond any one benchmark subset, including stress, fuzz and platform tests. SQLLogicTest, meanwhile, emphasizes cross-engine behavior over a large set of SQL statements. These are different test regimes, which is a reminder that “database-compatible” itself has layers: syntax, result values, transaction behavior, error handling and edge cases. [3] [4]
A migration team should therefore ask what the evaluation observed and what it did not. Did the test cover decimal rounding on a specific compiler? Did it include malformed records, rollback behavior, time zones, file encodings, batch restart points or a legacy integration protocol? If those are absent, the benchmark cannot answer whether the replacement preserves them.
The practical lesson is not to dismiss the score. It is to use it as a screening signal. A strong result can justify a contained proof of concept. It cannot justify a production cutover without application-specific evidence.
Build a parity harness around the behavior that matters
Before asking a model to translate a legacy module, collect the examples that define its contract: ordinary cases, boundary values, known exceptions, invalid inputs and historical bugs that users now depend on. Run the old and new implementations against the same fixtures, then compare outputs and side effects. Keep the test data anonymized and include realistic distributions rather than only clean examples.
For a financial calculation, that might mean exact decimal outputs across rounding boundaries. For a batch job, it might include restart after partial failure and duplicate input rows. For a report generator, it could include locale, sort stability and blank fields. These cases turn vague “equivalence” into observable checks.
A staged evaluation can control risk: first ask the model for a translation plan and identify uncertain semantics; then generate a small module behind a feature flag; then run shadow comparisons on sanitized traffic; and only then expand exposure. Every stage should keep a human accountable for domain assumptions and rollback criteria.
A better benchmark question
The headline question is whether a model can implement a known engine in another language. The engineering question is whether it can preserve an organization’s behavior when that behavior is scattered across code, data, runbooks and operator knowledge. MultiLangBench contributes evidence to the first question. Teams still have to assemble the evidence for the second.
That makes benchmark design part of the story. Shared test inputs and a common database-file boundary make results easier to compare. Sampling the suite makes evaluation cheaper, but it also means readers should check which tests were run before interpreting a score. When a vendor publishes a large percentage, the denominator and protocol are part of the result.
For teams considering COBOL or another language with a thinner modern tooling ecosystem, the responsible next step is a bounded pilot with a domain-specific parity suite. Treat model output as a draft implementation, not a migration decision. The benchmark can help decide where to look; your own tests decide whether the behavior survived. Teams designing a migration-specific harness can also see our guide to LLM-powered legacy test migration for a related workflow.
Frequently asked questions
What does OpenAI's MultiLangBench test?
MultiLangBench evaluates whether coding models can build a SQLite-compatible database engine in a requested programming language. Its adapted SQLite tests check behavior through a shared database-file interface; passing the benchmark does not certify compatibility with a separate company's business logic.
Does a high benchmark score mean a COBOL system is safe to migrate?
No. The results are vendor-reported evaluations on defined benchmark tasks. A real migration also needs representative business rules, data, edge cases, operational constraints and independent parity testing before a production cutover.
Sources & further reading
Keep reading
Claude Structured Outputs on Bedrock Can Enforce Shape, Not Business Truth
Bedrock adds schema-constrained Claude output, but route and model support vary and valid JSON still needs domain validation.
GitHub’s SSH Brownout Starts Nov. 4: Check the Client Before Replacing Keys
GitHub is phasing out older SSH signatures and key exchange; distinguish RSA key files from the SHA-1 signature algorithm before changing access.
Go 1.27.3 and 1.26.10 Update Certificate-Chain Verification
Go’s Oct. 19 security patches make crypto/x509 reject chains containing a small set of intermediates; rebuild affected binaries to apply the change.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.