
Persistent AI Agents Need a Trusted Control Plane and a Small Work Box
OpenAI's OpenClaw deployment shows why persistent agents need separate control services, sandboxed work, brokered secrets and auditable identity.
On this page
A chatbot usually waits for another prompt. A persistent agent may run through the night, call tools and respond to events without a person supervising each action. That changes the security problem: the system must contain whatever the model decides to do, including mistakes and instructions it encounters in untrusted data. OpenAI’s November 12 account of its internal OpenClaw deployment offers a concrete architecture, while OpenClaw’s own trust model states a boundary teams should read before sharing a gateway. [1] [2]
Keep policy outside the model’s reach
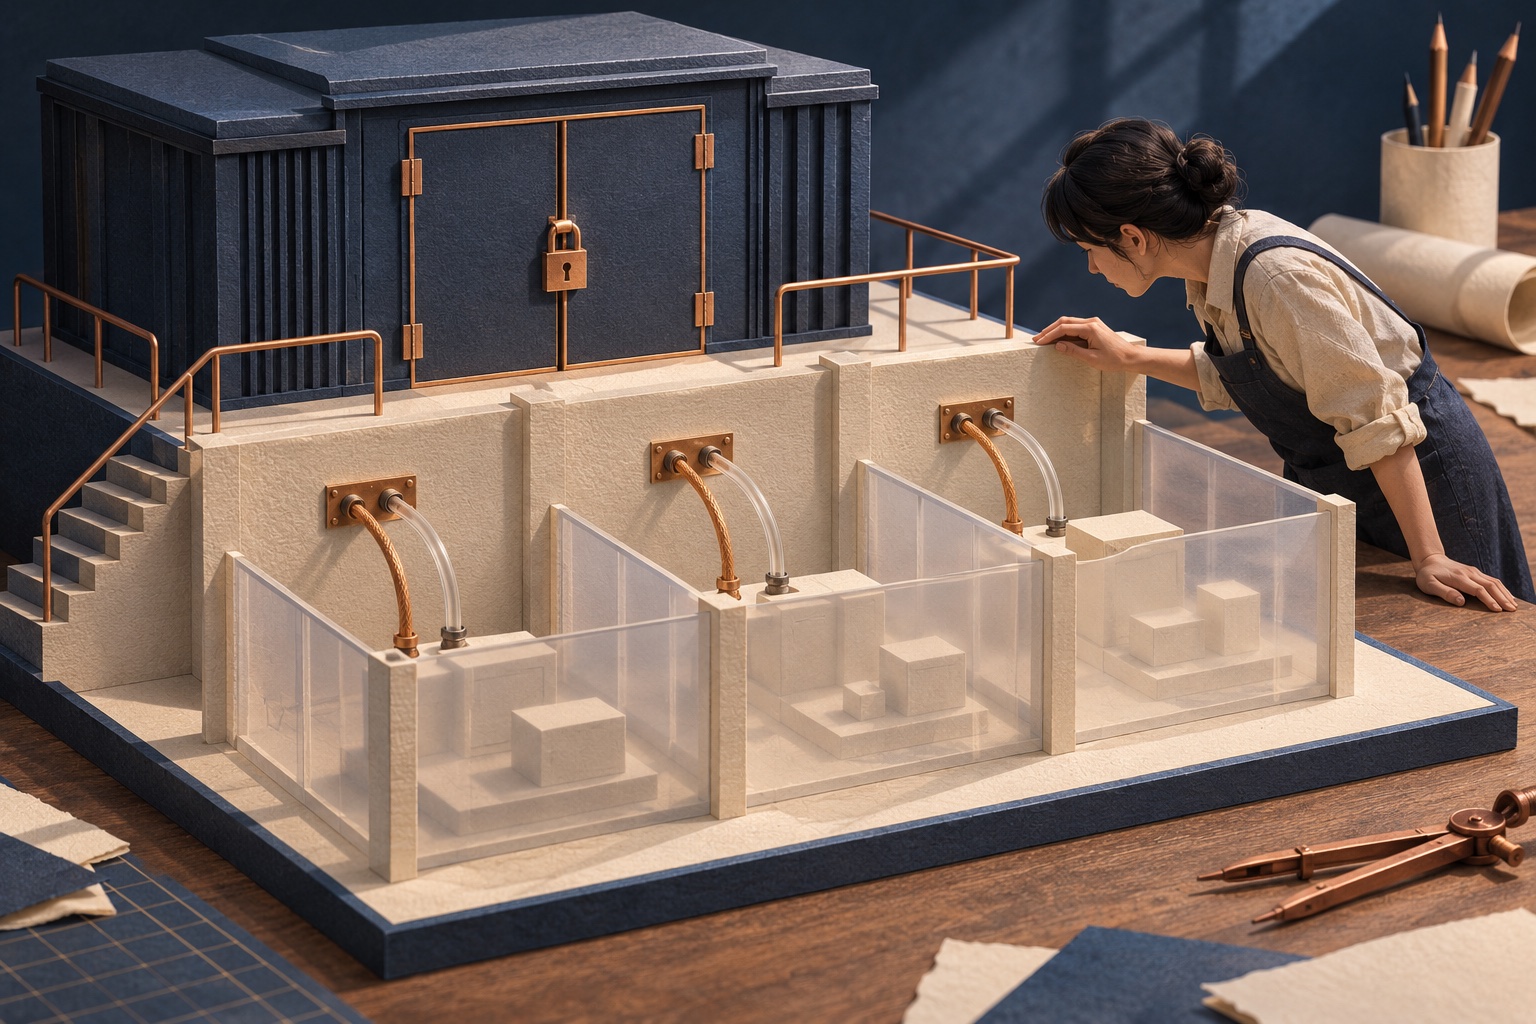
OpenAI describes separating the OpenClaw Gateway from the agent harness. The gateway configures the agent and remains trusted deterministic code; the harness and the workload it executes are treated as untrusted. That split lets administrators enforce controls at the boundary instead of expecting generated text to behave like a security mechanism. [1]
The company reports restricting the agent’s network destinations with an organization-managed allowlist, limiting file writes to agent work directories, isolating processes in a Linux sandbox, and using a credential broker so secrets are not directly visible to the agent. These are descriptions of OpenAI’s internal deployment, not a claim that every OpenClaw installation has those controls enabled by default. [1]
The principle is familiar from operating systems: code may request an action, but a separate authority decides whether that action is allowed. A model can propose a shell command; the process boundary constrains what it can reach. It can ask for a credentialed operation; a broker can expose only the result, not the underlying secret. A generated instruction cannot widen the network allowlist if that policy is held outside the model’s control.
“One gateway” means one trust group
OpenClaw’s security documentation is explicit that a gateway is intended for one operator or a mutually trusting team. It says a shared gateway is not designed to isolate adversarial users from each other, because users who can message a tool-enabled agent share that agent’s delegated authority. Session identifiers route conversations; they are not authorization tokens. [2]
That distinction matters when a team moves from a personal experiment to a service used by customers, contractors or unrelated departments. Adding accounts to one shared gateway does not automatically create tenant isolation. OpenClaw recommends separate gateways—and ideally separate operating-system users or hosts—where users are adversarial or do not share trust. It also documents narrower session visibility and agent-to-agent controls for deployments that need more restricted collaboration, while warning that these controls are not a replacement for a separate trust boundary. [2]
For an administrator, the first design question is therefore not “Which model is safest?” It is “Who is allowed to share an agent’s tools, sessions and host?” Define the trust group before exposing the gateway, and isolate groups at the service or operating-system layer where the consequences justify it.
Sandboxing is the enforcement layer
OpenAI’s example spans four distinct resources: network destinations, workspace files, local processes and credentials. Each boundary addresses a different failure mode. A network allowlist limits where an agent can send data or fetch instructions. A workspace limit prevents accidental edits elsewhere on the host. Process isolation reduces the reach of a generated command. A credential broker avoids placing reusable secrets in the model’s context. [1]
These controls are useful because they fail differently from a prompt rule. A prompt can ask an agent not to read a file; a filesystem policy can deny the read. A model can be instructed not to contact an endpoint; an egress rule can make the endpoint unreachable. That does not make sandbox configuration infallible: administrators still need to review the allowed paths, destinations and capabilities, and test how the system behaves when an action is denied.
OWASP’s 2026 agentic-application risk framework is a useful companion for threat modeling. It is an industry framework, not evidence that a specific OpenClaw deployment has been independently audited. Use it to organize review questions about excessive agency, tool permissions, identity and untrusted inputs; do not treat a checklist as proof of containment. [3]
Identity and logs make actions accountable
OpenAI says each agent in its deployment has a unique identity associated with a service account, separate inference credentials from the user’s own, and an auditable action trail. It also says it logs control-plane configuration changes and agent turns, restricting access because those records can contain sensitive information. [1]
The operational benefit is attribution. If an agent opens a pull request, calls a plugin or uses a delegated service, operators should be able to identify which agent acted under which policy and revoke that identity without disabling a human’s account. Logs can support investigation, but they create their own access and retention risks: store only what operations need, restrict who can inspect it, and define retention before the first agent begins collecting sensitive context.
OpenAI reports that more than 500 agents run proactively in its internal pilot. That is a company statement about its own adoption, not an independent productivity evaluation or a guarantee that the same safeguards transfer unchanged to another environment. The concrete practices are more useful to readers than the count: separate control and execution, constrain resources, broker secrets, and audit each agent identity. [1]
A deployment checklist for the first agent
Before enabling a persistent agent, write down its owner, allowed tools, file workspace, approved network destinations, credential access and shutdown path. Run it with the smallest useful permissions, then test representative failures: an out-of-workspace file request, a disallowed network destination, a request for a secret, and an attempt to act through another user’s session. Confirm that a denial occurs at the enforcement layer and is visible in the audit trail.
If multiple groups will use the system, decide whether they genuinely trust one another with shared tools and session context. If not, separate the gateways or hosts. Finally, give an operator a reliable way to disable the agent identity and preserve enough audit data to investigate what happened without making every conversation broadly accessible.
Persistent agents can be useful precisely because they act without constant supervision. The corresponding requirement is a boundary that remains effective when the model is wrong, manipulated or simply overconfident. Keep that boundary in deterministic infrastructure, narrow the agent’s workspace, and make every delegated action attributable.
Frequently asked questions
Why does a persistent agent need a separate control plane?
The control plane holds deterministic functions such as identity, networking and sandbox policy. Separating it from model-driven task execution lets operators enforce boundaries outside the agent's generated actions.
Does a prompt-injection filter secure a tool-using agent?
No single prompt filter can enforce filesystem, network, process or credential boundaries. OpenAI describes using sandbox controls and a credential broker so the model cannot directly access unrestricted resources or secrets.
Can one OpenClaw gateway safely serve adversarial users?
OpenClaw's documented trust model says one gateway represents one trust boundary for a single operator or mutually trusting team. It recommends separate gateways, and ideally separate operating-system users or hosts, for adversarial users.
Sources & further reading
Keep reading
IBM’s LLMON Tries to Put a Boundary Between Instructions and Data
LLMON structures model context and reports lower indirect-injection success in selected tests. It is promising, but not a security boundary.
Prompt Injection Is a Permission-Boundary Problem
Treating retrieved text as untrusted is not enough: tool permissions, argument checks and action approvals must be enforced outside the model.
Microsoft’s AI Patch Pipeline Still Ends at the Device
Microsoft says AI helps find, validate and fix Windows flaws faster. The security benefit still depends on how quickly organizations deploy those fixes.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.