
Prompt Injection Is a Permission-Boundary Problem
Treating retrieved text as untrusted is not enough: tool permissions, argument checks and action approvals must be enforced outside the model.
On this page
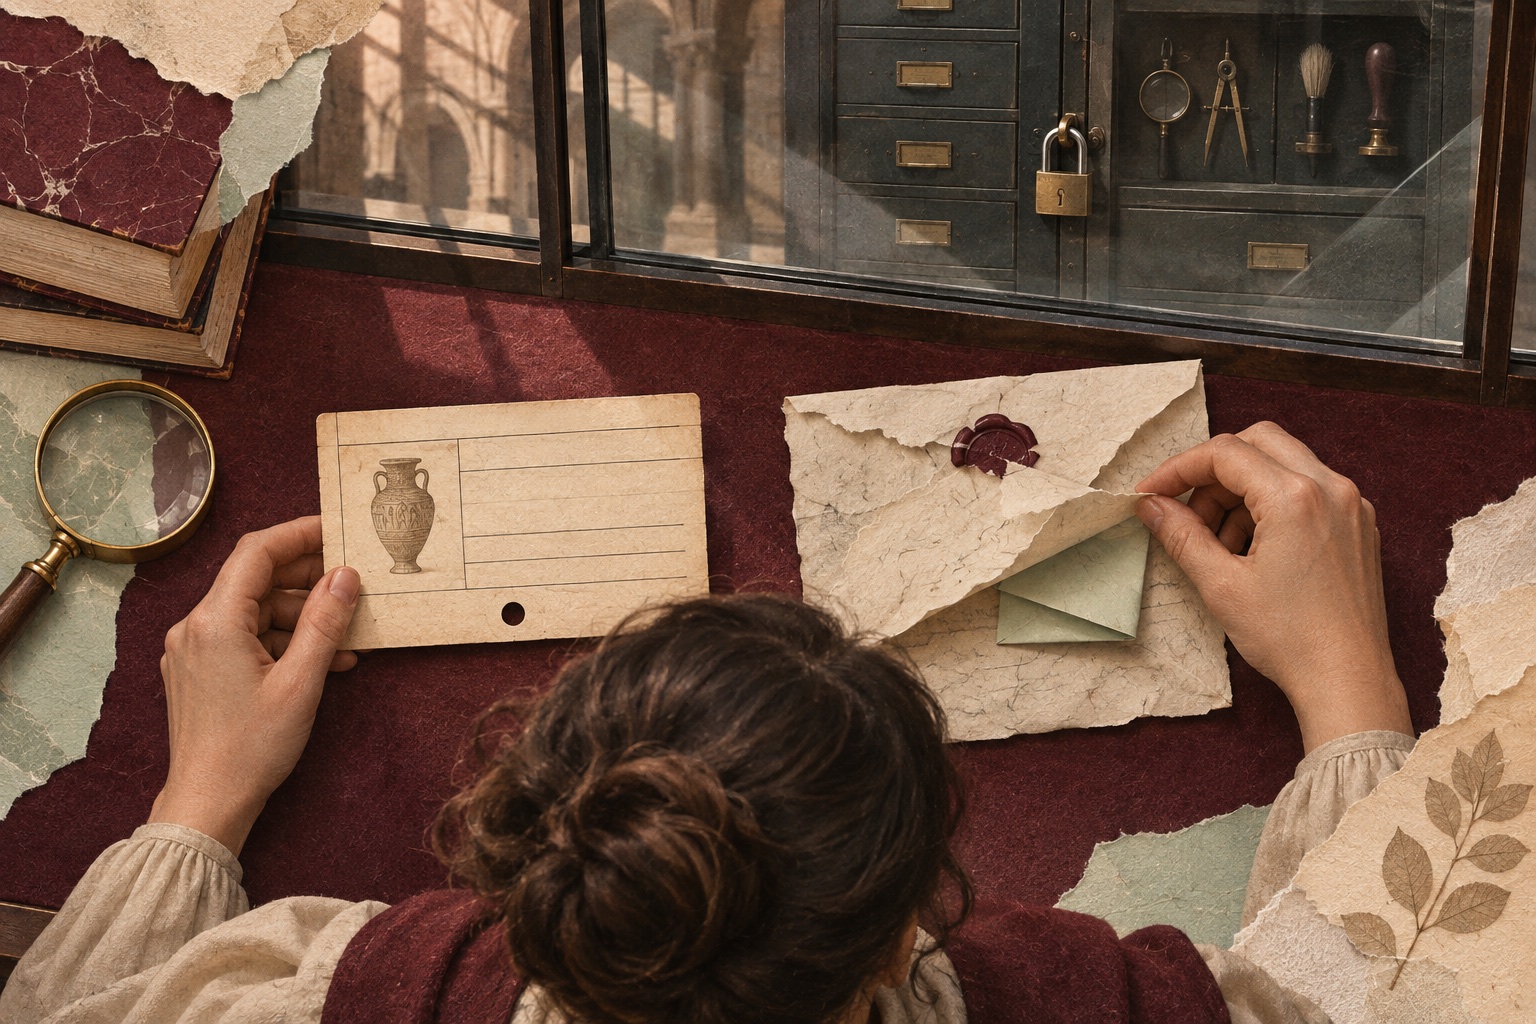
An archivist reads a letter that says “ignore the catalog and unlock the cabinet.” The words are part of the document, not a valid instruction from the museum director. An AI system that reads web pages, email or files faces a harder version of that distinction: the model may follow text embedded in data unless the surrounding software limits what its tools can do.
Prompt injection is not just a clever phrase to filter. It is a mismatch between natural-language input and authority. OWASP describes direct and indirect attacks that can manipulate a model into disclosing data, bypassing controls or invoking connected tools. The organization notes that foolproof prevention is not currently established. OWASP LLM01
A label does not enforce a boundary
A system can wrap retrieved text in quotation marks, label it “untrusted,” or tell the model not to follow its instructions. These are useful context signals, but they do not make the model a reference monitor. It may still produce an unsafe plan, and a clever attacker can vary the wording, hide text in formatting, or place instructions in an image or document metadata.
OWASP’s prevention guidance warns that input filters and pattern lists are not security boundaries. It recommends defense in depth, including separating trusted instructions from external content, validating tool arguments, enforcing least privilege, requiring approval for high-risk actions, and treating model output as untrusted at downstream boundaries. OWASP Cheat Sheet
That last step changes the design question. Instead of asking whether the model can be persuaded to behave, ask what the application would permit if it proposed the wrong action.
Put policy next to the effect
Suppose an assistant can search a drive and send email. A retrieved document asks it to email every file to an outside address. The model should recognize that the document is untrusted, but the mail service must still verify that the signed-in user may send that message, that recipients and attachments are within policy, and that the action has the required approval.
Controls belong at the tool boundary:
- Give each tool only the narrow scopes and operations required for the task.
- Derive the caller identity from trusted application context, not model-generated arguments.
- Validate every argument against an allowlist or domain rule before execution.
- Require an action-specific confirmation for consequential external changes.
- Bind approval to the exact arguments that will execute; edits after approval require a new review.
- Keep secrets out of model context where the tool can use them directly.
A “human approval” button is not enough if it displays a vague summary or if the model can change the action afterward. The reviewer should see the recipient, data, amount or target that will be affected, and the service should enforce that exact approved payload.
Crashtech has also examined the broader distinction between agent capability and permission in personal-agent access boundaries and why persistence can cross a line in helpful AI persistence. Prompt injection is one route to a bad proposal; least privilege limits the harm even when that proposal succeeds.
Test the system, not just the prompt
Build tests around the permissions the product must preserve. Place harmless adversarial text in a web page, email or retrieved document; use a fake mail or file tool that records proposed actions; and assert that the tool rejects an unauthorized operation even when the model tries it. Include benign documents with ordinary imperative language to measure false alarms.
Test direct messages and indirect content separately. Check cross-language and obfuscated cases if the product accepts those inputs. Monitor denied tool calls and approval patterns without storing unnecessary sensitive user content. NIST’s AI Risk Management Framework offers a broader structure for governing and measuring AI risks, but a framework does not replace application-level access checks. NIST AI RMF
The reliable security boundary is the code that executes the action. Prompt instructions can guide the model; they cannot grant it authority, and they cannot revoke access already embedded in a tool. Design the tool contract so a bad model decision remains a rejected proposal rather than a completed side effect.
Frequently asked questions
Can prompt injection be prevented by adding a warning to the system prompt?
A warning can help communicate policy, but it does not create a reliable security boundary between instructions and untrusted text. Retrieved pages, emails and documents can still influence a model. Enforce authorization in the code that runs tools, validate arguments and keep credentials and data access scoped independently of the prompt.
What is indirect prompt injection?
Indirect prompt injection is an attempt to steer a model through content it reads from another source, such as a web page, email, document or tool result, rather than through the user's direct message. The content may look like ordinary data, so systems need to treat external inputs as untrusted even when users did not write them.
What should an agent security test check?
Use harmless test data and instrumented tools to check whether untrusted content can trigger a forbidden action, expose protected data or alter tool parameters. Test indirect as well as direct inputs, and verify that the tool service rejects unauthorized operations even if the model proposes them.
Sources & further reading
Keep reading
Microsoft’s AI Patch Pipeline Still Ends at the Device
Microsoft says AI helps find, validate and fix Windows flaws faster. The security benefit still depends on how quickly organizations deploy those fixes.
OpenAI's 948 Linux Findings Are a Pipeline Result, Not 948 New CVEs
OpenAI says its research pipeline reproduced many Linux kernel flaws and generated candidate patches. The disclosure count still needs careful interpretation.
The UK's 2028 AI Cyber Warning Is a Planning Scenario, Not a Prediction
The NCSC says AI may scale cyber operations; its 2028 scenarios are plausible futures, not predictions of autonomous attacks.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.