
A Shared AI Training Rule in robots.txt Is a Preference, Not a Lock
OpenAI says it will honor a proposed shared robots.txt signal for AI training. The IETF draft is still work in progress, and it does not control crawling.
On this page
A publisher can already tell a named crawler not to fetch a site. A harder question is what happens after content is fetched: may it be used to train a generative model? An October proposal tries to let website operators express that preference once for multiple participating providers. It is useful coordination work, but it is not a technical lock on copying or crawling.
On October 30, OpenAI said it would honor a common signal in robots.txt for foundational generative AI training. Its announcement describes the goal as reducing the need for publishers to maintain a separate rule for each AI provider. OpenAI says it aims to implement the signal in the coming months; the post does not say the support is live today. Existing crawler controls continue to apply, and the company says the proposed preference will not replace them. [1] [5]
The proposal is an Internet-Draft called “Machine-Readable Training Preference Signal.” As of November 6, the IETF Datatracker labels it an individual active Internet-Draft, not endorsed by the IETF and without formal standing in the standards process. It defines a policy token, __usage_ai-training, that can be placed in a normal robots.txt group. [2]
What the signal says
The draft reuses the structure of robots.txt rather than adding a new directive. A site might express a site-wide preference like this:
User-Agent: __usage_ai-training
Disallow: /
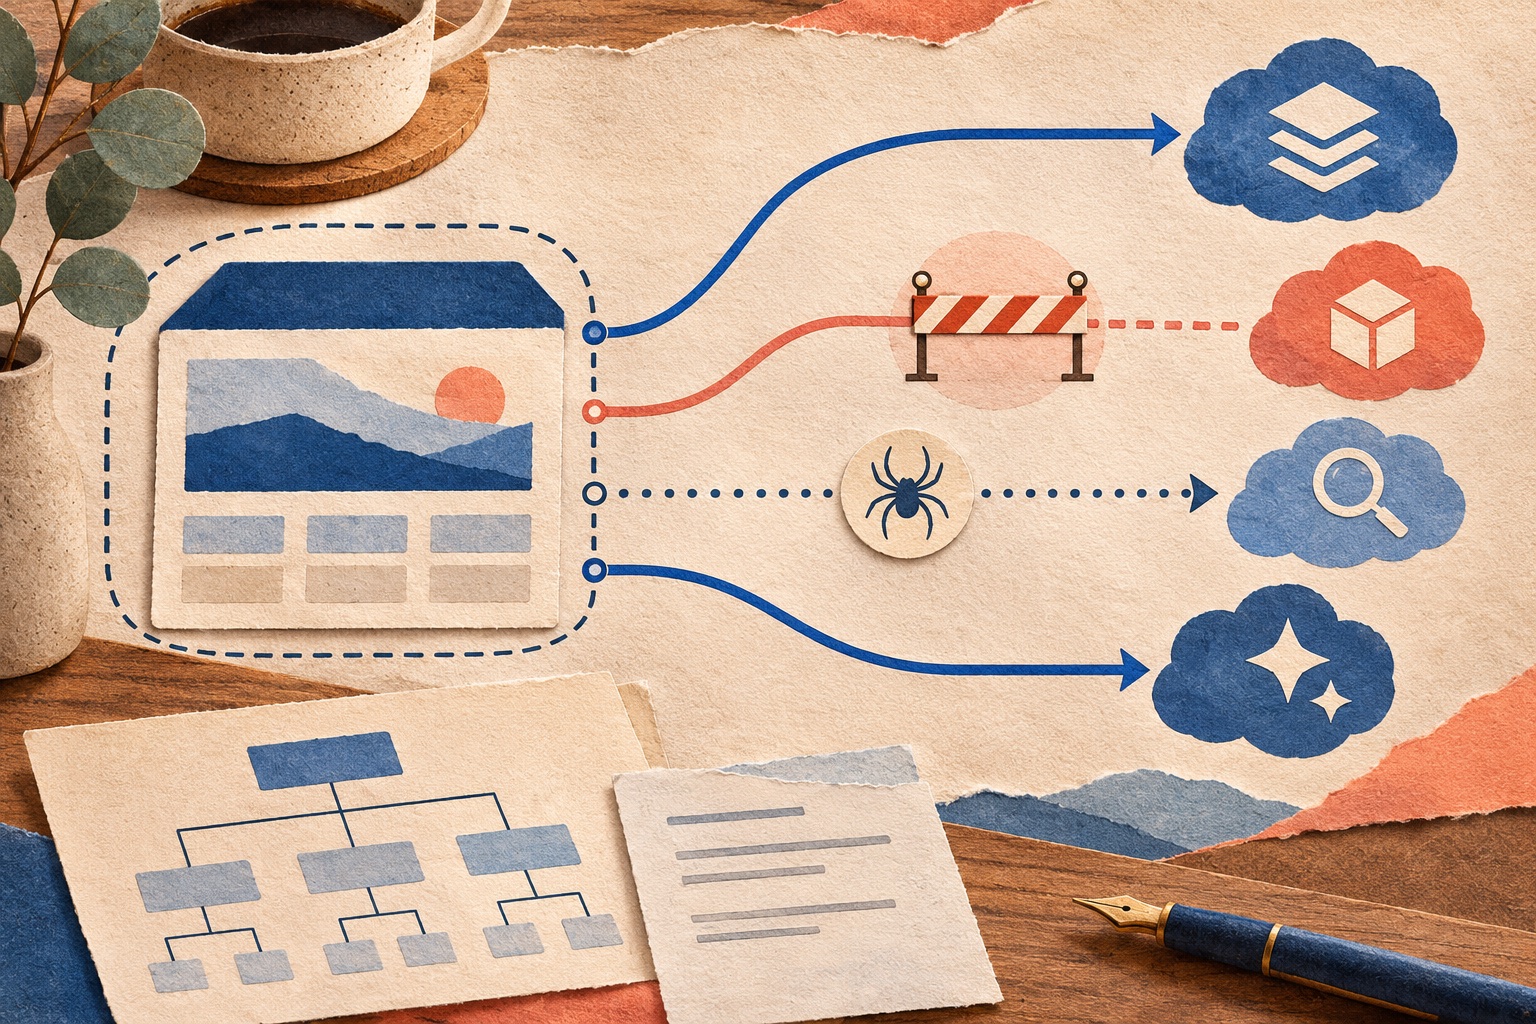
The token is not the name of a crawler. It labels the use preference: training a generative AI model. The draft allows rules to be scoped by path, so a publisher could express a preference against training on most of a site while allowing a specific path. It also distinguishes that preference from rules that control traffic to a particular crawler. A Disallow in the AI-training group does not itself tell a crawler to stop fetching the page. [2] [3]
That separation addresses two different questions. A crawler rule is about whether a bot should retrieve a URL. A content-use preference is about a purpose for which retrieved material may be used. The IETF draft says consumers can use the preference to inform crawling behavior, but the signal is not itself a crawling directive. A provider that needs to fetch pages for search or user-requested retrieval can make its own policy decision while separately honoring a training preference. [2]
The distinction is why this should be treated as a statement of intent rather than a security boundary. RFC 9309, the Robots Exclusion Protocol, describes robots.txt rules as requests to crawlers and explicitly says they are not a form of access authorization. Sensitive material still needs authentication or another access-control mechanism. A policy file cannot prevent an uncooperative client from downloading public content. [4] Publishers also need to distinguish training preferences from the separate question of whether AI search surfaces send people to the original site; see our report on publisher visibility in Google AI Search.
Why a shared token could reduce maintenance
Without a common convention, a publisher that wants to communicate a preference to many providers may need a long list of provider-specific user-agent groups. That list can become stale as companies add crawlers or change product names. A shared token is intended to make one purpose-specific statement portable across participating services.
The IETF work also tries to keep the signal close to the established robots.txt grammar. The draft says parsers that do not recognize the token should behave as before, while consumers that implement it can interpret the matching path rules as an AI-training preference. A related IETF vocabulary draft defines categories for different kinds of use, which matters because “AI use” can mean training, search, retrieval, or other activities with different effects. [2] [3]
For web operators, the practical benefit depends on adoption and clarity. A single rule is easier to audit than dozens of separate groups only if providers document exactly what they do with it, which systems it covers, and when changes take effect. OpenAI’s announcement is a public commitment to implement the signal, not evidence that every other provider has adopted it. The draft’s status can change as the working group discusses the mechanism, so publishers should check the Datatracker before copying sample rules into production. [1] [2]
What publishers should do now
First, keep crawler access and downstream use separate in your policy plan. If a bot should not fetch a path, use the provider’s documented crawler controls. OpenAI’s crawler documentation, for example, describes distinct crawlers for search, user-triggered retrieval, and training-related collection. Those controls answer a different question from the shared training preference. [5]
Second, do not depend on robots.txt to protect confidential or licensed content. Put private material behind access control, and use contracts or technical delivery rules for obligations that need stronger enforcement. Third, monitor the draft and participating-provider documentation; add the new token only when your organization understands the scope and the providers you care about have stated how they will honor it.
The proposal is a step toward a more legible web, where the same public file can carry both traffic rules and purpose-specific preferences. Its limits are part of the design: it communicates a choice to implementations that agree to read it. It cannot create universal consent, force compliance from every actor, or turn a public page into a private one.
Frequently asked questions
Does the new robots.txt signal stop AI crawlers from visiting a site?
No. The draft describes a content-use preference, not a crawling instruction. Website operators who want to restrict fetching should continue using crawler-specific robots.txt rules and other access controls.
Is the shared AI training signal an IETF standard?
No. As of November 6, 2026, the mechanism is described in an individual Internet-Draft, which the IETF says is not endorsed and has no formal standing in its standards process.
Has OpenAI implemented the signal?
OpenAI said on October 30 that it aims to implement the signal in the coming months and would share details later. That announcement does not say implementation is already live.
Sources & further reading
- OpenAI: Making it easier for websites to express AI training preferences
- IETF Datatracker: Machine-Readable Training Preference Signal draft
- IETF Datatracker: A Vocabulary For Expressing AI Usage Preferences
- RFC 9309: Robots Exclusion Protocol
- OpenAI developer documentation: Overview of OpenAI Crawlers
Keep reading
Meta’s Muse Gets a Voice and a Face. The Design Choice Is the Story
Meta adds spoken Muse conversations and expressive avatars in the US. What changes, what remains unclear, and how to use voice deliberately.
Anthropic’s Usage Policy Takes Effect November 12. What Actually Changes
Anthropic’s policy consolidates deceptive-campaign rules and clarifies safeguards for elections, surveillance, high-risk advice, and physical actions.
ChatGPT’s Textable Dot Adds a Messaging Route to an Always-On Agent
OpenAI’s limited U.S. beta connects its dot assistant to iMessage or RCS through Linq. The new channel deserves careful data and approval boundaries.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.