
A New Benchmark Tests AI on Theoretical Computer Science Research, Not Just Proof Prompts
TCSExam scores theorem proving, solver engineering, constructions, and open conjectures, with Lean or executable checks that make progress more auditable.
On this page
A model can produce a convincing proof-shaped answer and still be wrong. TCSExam tries to make research evaluations harder to bluff by checking formal proofs and executable outputs, while also testing work beyond theorem completion. Its design highlights a useful distinction: verification can establish that an answer meets a precise condition, while research judgment asks whether the condition was the right question.
Four tracks, not one leaderboard trick
The November 5 TCSExam preprint describes 100 expert-reviewed tasks across four tracks: theorem proving, solver engineering, construction, and attempts on open conjectures. The authors say submissions are checked by Lean’s kernel or task-specific executable checkers. A smaller Lite version contains 20 tasks, five per track, which the paper says reduces the number of attempts by 80% at the same per-attempt budget. [1]
That coverage is important because “solve a theorem” is only one part of theoretical computer science. A researcher may also build a solver, construct an object with specified properties, or explore a conjecture where the output is a new bound or verified special case rather than a final resolution. A benchmark that combines these jobs can reveal whether a system’s strength transfers beyond a single familiar format. [1]
What verification can—and cannot—tell us
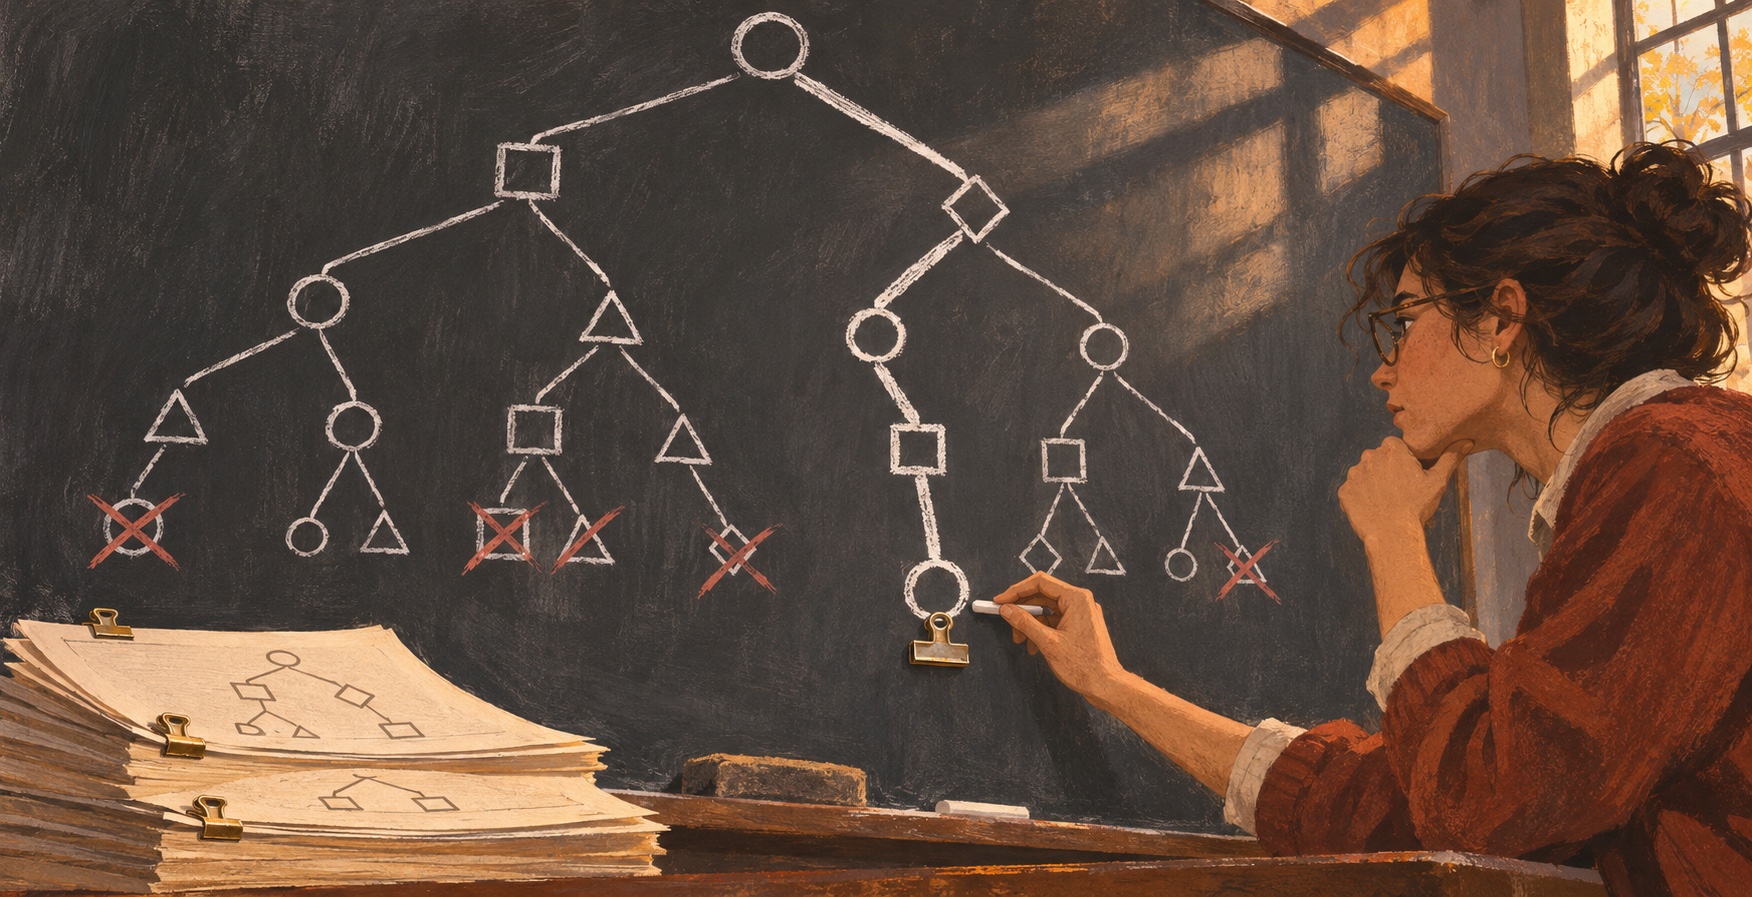
A proof assistant kernel checks whether a formal proof follows from its definitions and rules. An executable checker can test whether a candidate construction satisfies the task’s coded constraints. These checks reduce the chance that a smooth explanation receives credit despite a missing step. Lean’s documentation explains the environment and kernel-based verification model. [3]
But a verified answer is not automatically a significant discovery. A benchmark still depends on which tasks were selected, how much context the system received, the compute and tool budget, and how score aggregation handles different tracks. Open-conjecture attempts are especially hard to summarize: a valid new bound may be meaningful progress without settling the conjecture, and a benchmark score cannot tell readers how valuable each step is to the field.
TCSExam’s authors report that the Full and Lite rankings were strongly aligned across the shared agents in their evaluation, with Spearman’s rho of 0.93. They also report different leaders on the Full and Lite indices. Those numbers describe this benchmark and its tested systems; they do not establish a universal ranking of research ability. [1]
A separate August preprint, FormalTCS, takes a related but different approach: it assembles frontier problems from recent theory venues and emphasizes proof formalization as a bottleneck. Together, the papers show why benchmark design is itself an active research question—what counts as a task, how to validate output, and where human research taste remains necessary. [2]
How to read the results
Look at the track breakdown. A combined index can hide a system that proves well but performs poorly at solver engineering, or the reverse. Track-level results show where the measured capability lies.
Check what the validator guarantees. Kernel-checked proof, executable test, expert review, and model-graded plausibility are different kinds of evidence. A paper should identify which one backs each result.
Separate progress from resolution. A special case or improved bound can be useful, but it is not the same as proving an open conjecture. Headlines and summaries should preserve that distinction.
Ask whether tasks reflect research practice. Real researchers choose questions, draw on literature, revise plans, and decide which results matter. A finite benchmark can sample some of this work; it cannot fully reproduce it.
The contribution is a better question
TCSExam’s most useful contribution may be methodological. Instead of asking whether a model can generate proof-like text, it asks how much of a research workflow can be turned into tasks with independently checkable outputs. That makes future comparisons more concrete and exposes what still resists measurement.
The next evidence should include independent runs, task-level artifacts, clear compute budgets, and careful review of novel claims. A high benchmark score can show that a system handled a challenging suite. Whether it can do research autonomously remains a larger question involving problem selection, correctness, novelty, and human judgment.
Frequently asked questions
What does TCSExam measure?
TCSExam is a research benchmark for theoretical computer science that evaluates theorem proving, solver engineering, constructions, and attempts to make progress on open conjectures. Its tasks are checked by the Lean kernel or executable task-specific checkers.
Does a high TCSExam score mean an AI can independently do theoretical computer science research?
No. The benchmark measures performance on a defined task set, and the paper reports verified outputs and special cases rather than autonomous research capability in general. The authors also describe limits to what the benchmark captures.
Why use formal or executable checkers for AI research benchmarks?
A checker can verify that a proof or construction satisfies a formalized condition, reducing reliance on a language model or human grader to judge plausible prose. It does not establish that the task set covers all research judgment or that a result is important.
Sources & further reading
Keep reading
Can a Language Model Read a Neural Network's Weights? A New Audit Says: Be Careful
A November preprint challenges claims that models infer what a network learned from raw weights, exposing the role of familiar dataset clues.
AutoDNA Turns a Wet Lab Into a Workflow Engine, With Humans Still on the Bench
Nature's AutoDNA study links AI agents to more than 20 lab instruments; its real advance is coordinated, traceable execution, not a scientist-free lab.
METR’s Anthropic Audit Finds Faster AI Progress—and a Visibility Gap
METR estimates Anthropic’s specified-task capabilities advanced about twice as fast, while redactions and uncertain attribution limit outsiders’ conclusions.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.