
tag: distributed-systems
articles: 80 · beats: 19
latest: November 17, 2026
---
Distributed Systems
80 Crashtech articles on Distributed Systems, spanning System Design & Architecture, Distributed Systems, Architecture, Infrastructure, Devops, Cloud Infrastructure, Systems Architecture, Development Best Practices, Database Engineering, Fintech, Api Architecture, How AI Actually Works, Engineering, Data Engineering, Api Design, Software Architecture, Ai Systems, Databases and Cloud Architecture, published between March 2026 and November 2026. Every piece is full-text HTML with sources, structured data and an authored FAQ.
They span System Design & Architecture (50), Distributed Systems (5), Architecture (3), Infrastructure (2), Devops (2), Cloud Infrastructure (2), Systems Architecture (2), Development Best Practices (2), Database Engineering (2), Fintech (1), Api Architecture (1), How AI Actually Works (1), Engineering (1), Data Engineering (1), Api Design (1), Software Architecture (1), Ai Systems (1), Databases (1), Cloud Architecture (1). System Design & Architecture Distributed Systems Architecture Infrastructure Devops Cloud Infrastructure Systems Architecture Development Best Practices Database Engineering Fintech Api Architecture How AI Actually Works Engineering Data Engineering Api Design Software Architecture Ai Systems Databases Cloud Architecture
How Airbnb Shipped 20+ Local Payment Methods in 360 Days: Config-Driven Domain Architecture
Inside Airbnb's payments replatforming: shipping 20+ Local Payment Methods (LPMs) across 75 global markets in under 360 days using config-driven architecture.
Eventual Consistency in Distributed Databases: Replication Lag, Conflict Resolution, and Tuning
Why modern distributed databases trade immediate sync for availability: replication lag, conflict resolution algorithms, PACELC theorem, and monotonic reads.
Event Sourcing in Practice: Immutable Logs, Temporal State Replay, and CQRS Projections
Why systems should remember how they got here, not just where they are: exploring Event Sourcing, append-only logs, snapshots, and CQRS projections.
High-Throughput Systems Engineering: Batching, Concurrency, and Backpressure Strategies
How to engineer high-throughput systems that do not collapse under load: batching math, bounded concurrency, reactive backpressure, and queue shedding.
How OpenAI Scaled ChatGPT to 800 Million Users on Postgres: Single Primary and Read Scaling
How OpenAI runs millions of queries per second on a single Postgres primary writer: read replica topologies, PgBouncer pooling, and write offloading.
How LinkedIn Replaced ZooKeeper With Kafka and xDS Service Discovery at Massive Scale
Inside LinkedIn's Next-Gen Service Discovery: replacing legacy ZooKeeper clusters with Apache Kafka streams and an Envoy xDS control plane.
Inside Netflix Live Origin: Surviving 65 Million Concurrent Streams with Real-Time Validation
How Netflix built Live Origin: real-time quality validation, dual-pipeline redundancy, and low-latency packaging for 65 million concurrent live viewers.
The Scaling Ladder: How Nextdoor Evolved PostgreSQL Through Pooling, Replication, and Sharding
How Nextdoor scaled PostgreSQL from a single server to a multi-tiered architecture: PgBouncer connection pooling, read replicas, and horizontal sharding.
RabbitMQ vs Kafka vs Pulsar: Storage Engines, Retention Policies, and Delivery Guarantees
An architectural comparison of RabbitMQ, Apache Kafka, and Apache Pulsar: queue vs log storage, partition rebalancing, and tiering.
How Reddit Migrated a Petabyte Kafka Fleet From EC2 to Kubernetes With Zero Downtime
How Reddit migrated a 500-broker, petabyte-scale Apache Kafka fleet from AWS EC2 to Kubernetes and Strimzi with zero downtime and no client changes.
Stateless Architecture Demystified: Where Application State Really Moves and What It Costs
Why stateless architectures do not eliminate state: exploring state relocation, distributed sessions, token trade-offs, and database synchronization costs.
The 10-Year Evolution of Stripe Payments API: From Tokens and Charges to Payment Intents
How Stripe rebuilt its core payments API four times over 10 years: from synchronous Tokens and Charges to the universal PaymentIntents state machine.
Strong Consistency in Distributed Databases: Linearizability, Raft Consensus, and Coordination Latency
What strong consistency actually costs in distributed systems: linearizability, Raft quorum consensus, physical latency floors, and failover boundaries.
Before Raft: How the Bully and Ring Algorithms Elect a Leader
Leader election is a distinct problem from consensus. The Bully and Ring algorithms solve 'who's in charge' with nothing but timeouts and node IDs.
Database Sharding: What It Actually Costs When You Split the Database
Sharding scales a database past one machine's limits, but it changes joins, transactions, and query patterns. Here's what each strategy trades away.
Circuit Breakers, Bulkheads, Timeouts: The Patterns Behind 'Fault Tolerant'
Fault tolerance isn't a single feature you add — it's four specific patterns, each stopping a different way one failure turns into every failure.
Four Ways Your Cache Silently Turns Into a Database-Killer
Thundering herd, cache penetration, hot-key breakdown, and full cache crashes are four distinct failure modes, each with a different fix.
Scalability, Performance, and Elasticity Are Not the Same Problem
A fast system can still fail to scale, and an elastic system can still be slow. Confusing the three leads to fixing the wrong bottleneck.
Tunable Consistency: How Distributed Databases Let You Choose Per Request
DynamoDB and Cassandra don't force one consistency level system-wide. Quorum math (R + W > N) lets you dial consistency up or down per query.
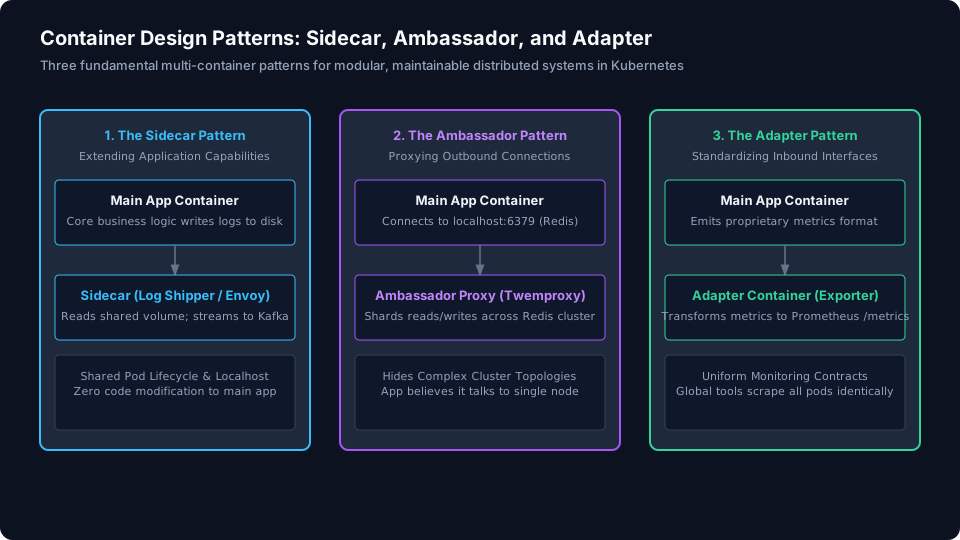
Container Design Patterns for Distributed Systems: Sidecar, Ambassador, and Adapter
Master the three essential multi-container design patterns in Kubernetes: Sidecar, Ambassador, and Adapter architectures for modular cloud systems.
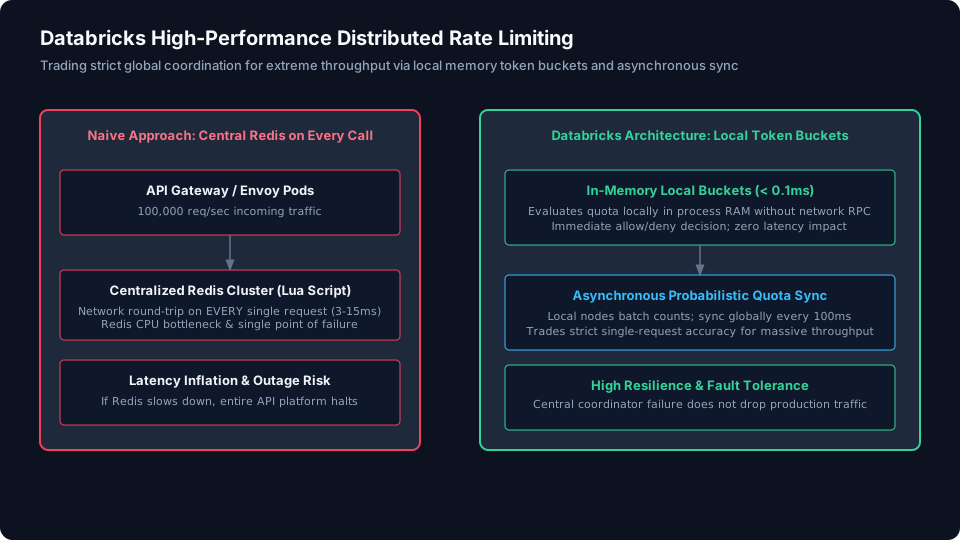
High-Performance Rate Limiting at Databricks: In-Memory Local Coordination
How Databricks engineered ultra-low-latency distributed rate limiting: trading strict atomic precision for microsecond in-memory evaluations.
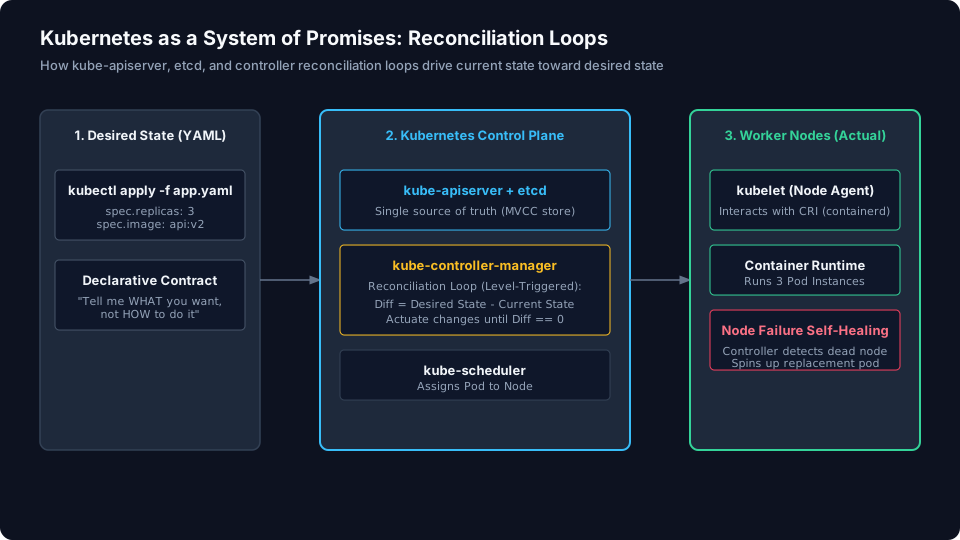
Kubernetes as a System of Promises: Reconciliation Loops and Desired State
Understand Kubernetes control plane architecture: declarative desired state, etcd, kube-apiserver, and controller reconciliation loops.
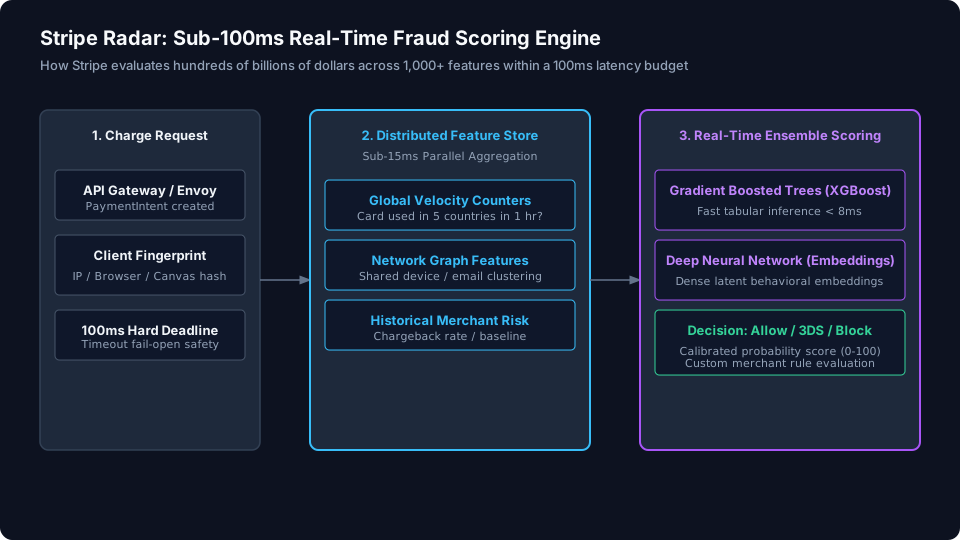
Inside Stripe Radar: Sub-100ms Real-Time ML Fraud Detection Architecture
How Stripe Radar scores payments in under 100 milliseconds: distributed feature stores, global network graphs, and real-time ensemble inference.

Database Sharding Guide: Horizontal Partitioning, Shard Keys, and Cross-Shard Joins
Why databases resist horizontal scaling: deep dive into database sharding, range vs hash vs directory strategies, cross-shard joins, and resharding.
Database Types Guide: Storage Models, Access Patterns, and Polyglot Persistence
A practical guide to modern database types: relational, columnar, key-value, document, time-series, graph, and vector engines matching storage to workloads.
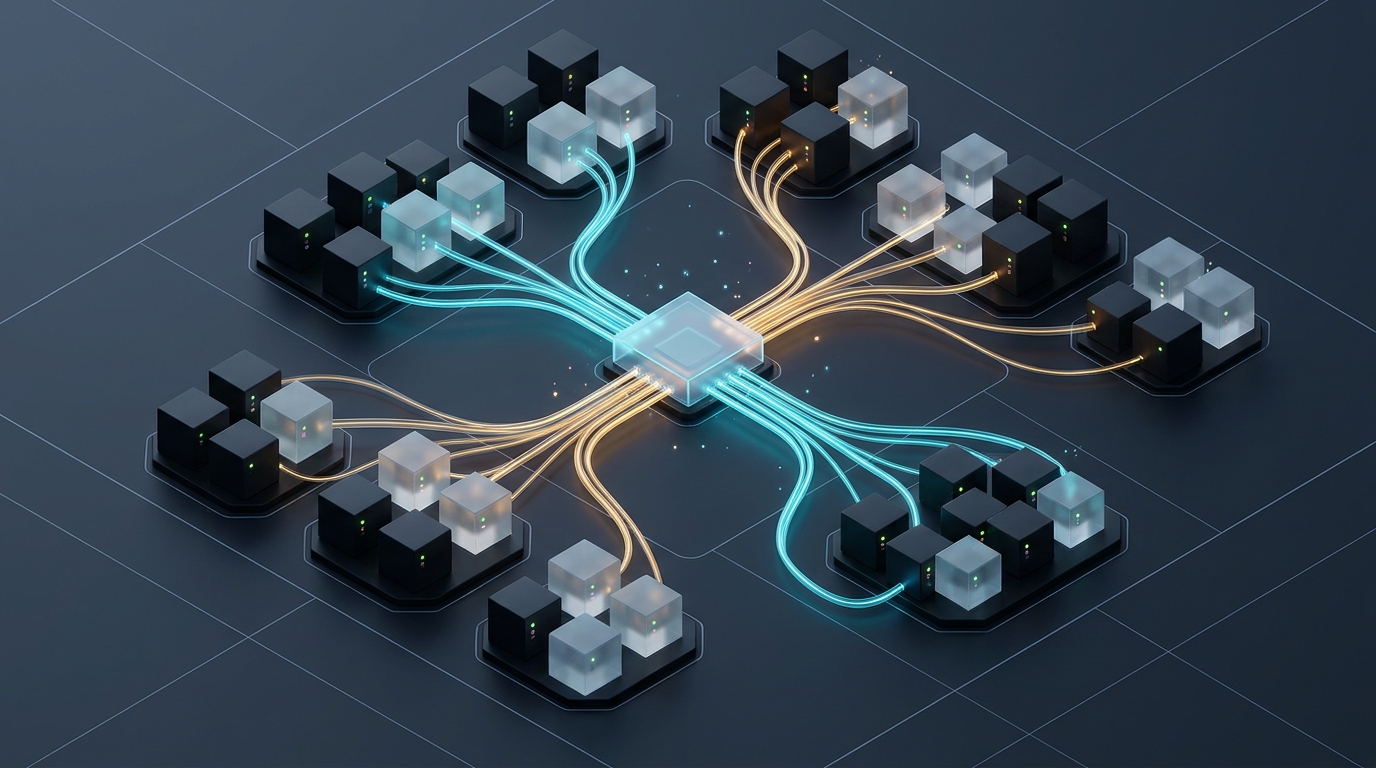
Client-Side Load Balancing on Kubernetes: Why gRPC Traffic Skews and How Databricks Routes Per Request
How Databricks eliminated gRPC traffic skew in Kubernetes: custom xDS control plane, client-side P2C routing, zone-affinity, and slow-start ramp-up.
Distributed Systems Fundamentals: Partial Failure, RPC Ambiguity, and Clock Limits
A practical guide to uncertain RPC outcomes, deadlines, safe retries, idempotency, and why wall clocks cannot establish causality.
High Availability Begins Before Failover: Capacity, Isolation, and Recovery
A guide to resilient services: reserve zone capacity, bound dependencies, promote data safely, and measure recovery objectives.
Scale an API by Removing Contention: Stateless Workers, Safe Caches, and Bounded Queues
A practical API scaling sequence: remove instance-local state, cache only safe responses, bound work queues, and shed excess load before dependencies fail.
How Lyft Built LyftLearn Serving: Generated Microservices and Model Self-Tests at Scale
How Lyft serves millions of ML predictions per second: decoupling data and control planes, generating per-team microservices, and model self-tests.
Message Brokers Demystified: Append-Only Logs, Consensus Replication, and Delivery Guarantees
An architectural deep dive into message brokers: log-structured storage, Raft/Paxos consensus replication, temporal buffering, and delivery guarantees.
Seven Message Broker Patterns: Data Consistency, Workload Management, and Visibility
Master essential message broker patterns: Transactional Outbox, Idempotent Consumer, Dead Letter Queues, Competing Consumers, and Priority Queues.
Rate Limiting Strategies Explained: Token Bucket, Leaky Bucket and Sliding Windows
How rate limiters protect backend systems from cascading collapse, compare algorithms for burst tolerance and fairness, and handle distributed Redis state.
What Makes an API RESTful: The Six Constraints and Common Real-World Violations
Explore Roy Fielding's six architectural REST constraints, cache semantics, layered systems, and where real production APIs break the specification.
The Retry Pattern in Distributed Systems: Exponential Backoff, Jitter, and Retry Budgets
Master the retry pattern in distributed systems: distinguishing transient vs permanent faults, exponential backoff, full jitter, and circuit breakers.
Saga Pattern Demystified: Orchestration vs Choreography for Distributed Transactions and Compensating Actions
A comprehensive guide to the Saga pattern: Two-Phase Commit failure modes, compensating transactions, choreography vs orchestration, and idempotency.
Scalability Patterns for Distributed Systems: Horizontal Scaling, Tail Latency, and Error Budgets
An architectural guide to scaling distributed systems: horizontal vs vertical limits, tail latency physics, error budgets, and stateless service design.
System Performance Engineering: Profiling, Algorithmic Tuning, and Resource Efficiency
A comprehensive guide to distributed system performance: profiling hot paths, data indexing, caching tiers, concurrency limits, and tail latency tuning.
12 Core Architectural Concepts: Load Balancing, Caching, Sharding, and Circuit Breakers
A comprehensive architectural reference: load balancing, CDNs, sharding, consistent hashing, rate limiting, circuit breakers, and event-driven queues.
MCP’s 2026 Protocol Reset: Stateless Requests, Routing Headers, and Safer Auth
The July 2026 MCP revision removes protocol sessions, adds self-contained requests and routing headers, and changes authorization and long-running work.
How Reddit Migrated Its Comments Backend from Python to Go Without Switching Blind
Reddit’s engineering team used tap-compare reads and isolated sister datastores to validate a high-write Go migration while Python remained the production path.
Netflix Tudum’s Read Path: Moving from CQRS Caches to RAW Hollow
Netflix describes how an in-memory RAW Hollow store simplified Tudum page reads and reduced reported page-construction time.
Pinterest Pacer: Scaling Asynchronous Jobs with Stateful Dequeue Brokers
Pinterest’s Pacer redesign assigns queue partitions to brokers to reduce contention in its Pinlater job system.
Inside Zanzibar: How Relationship Tuples and Consistency Tokens Make Authorization Global
A source-grounded tour of Google Zanzibar’s relationship model, consistency tokens, and the engineering problem behind safe distributed permission checks.
Consistent Hashing: What Moves When a Node Joins or Fails?
Understand hash rings, virtual nodes, data movement and operational caveats through Dynamo, Cassandra and Redis Cluster's contrasting slot design.
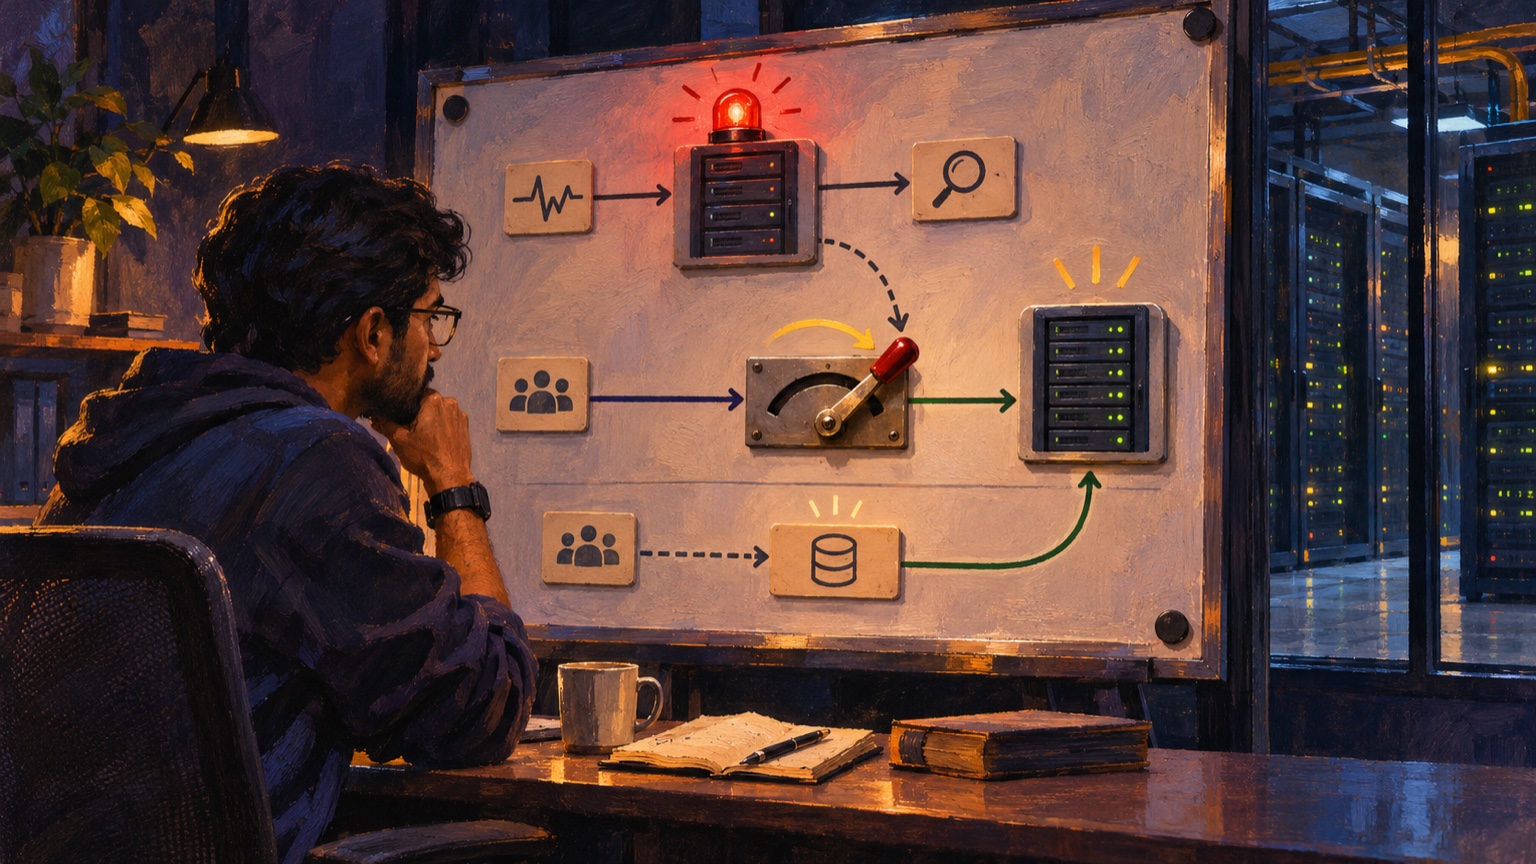
Inside Flipkart Altair’s MySQL Failover: Detection, Fencing, and Discovery
Flipkart’s Altair account shows why MySQL failover depends on false-positive checks, replica lag, fencing, and client rediscovery.
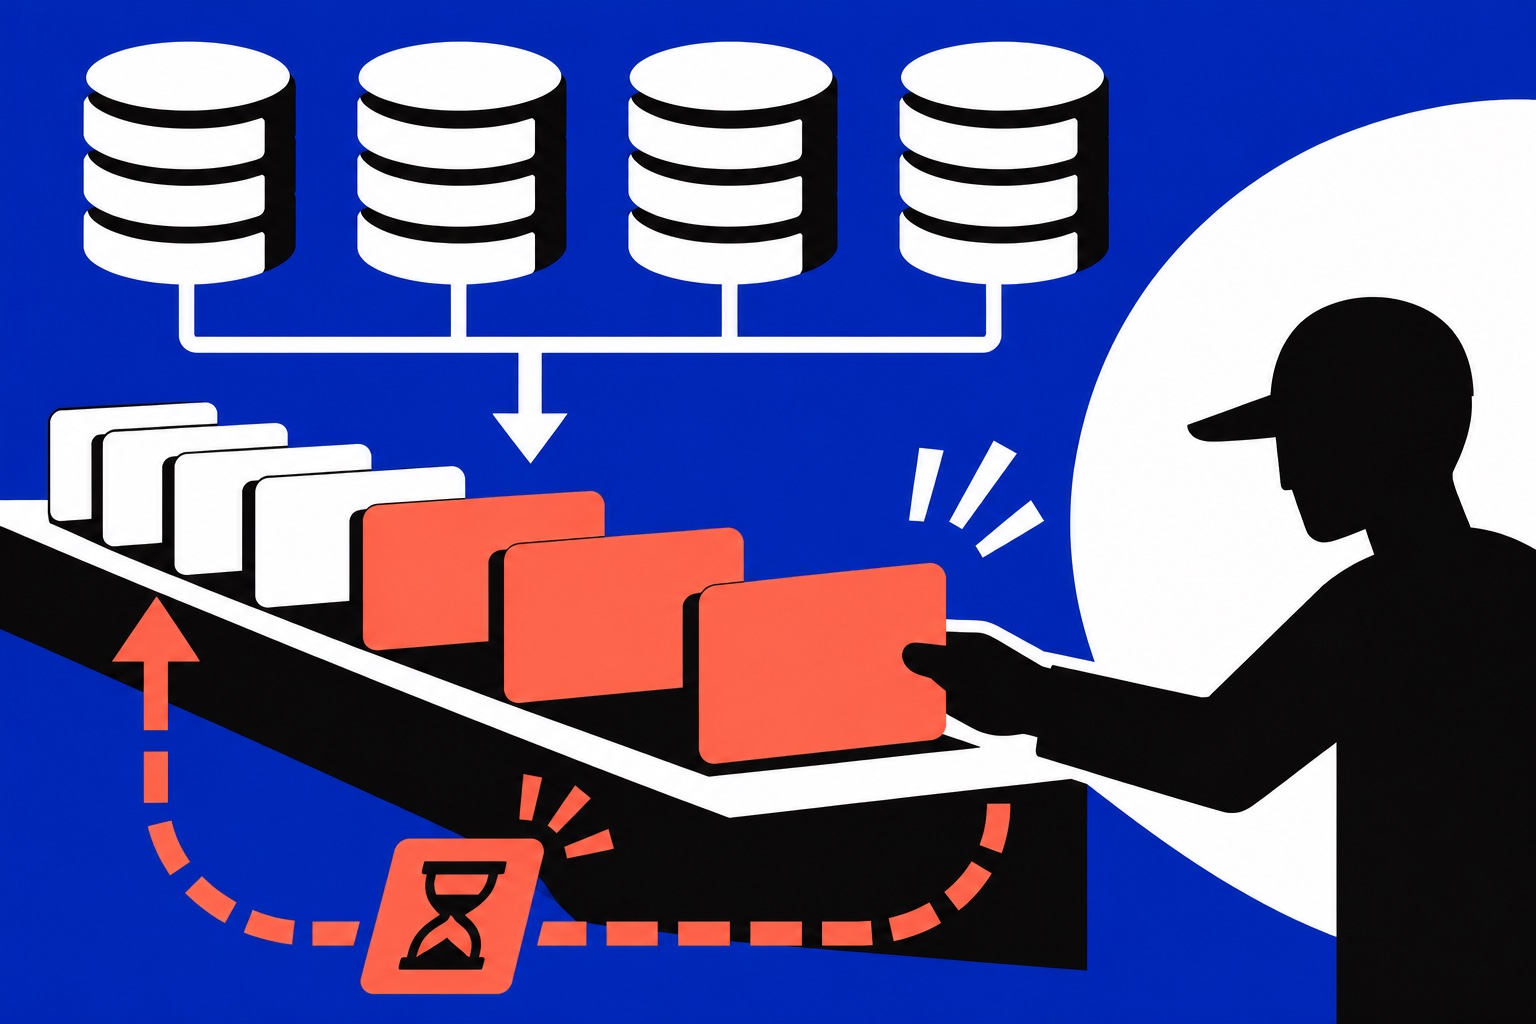
How Meta Scaled FOQS, a Priority Queue Built on Sharded MySQL
Meta's FOQS combines MySQL-backed persistence, per-shard ready-item indexes, prefetching, leases, and tenant capacity controls.
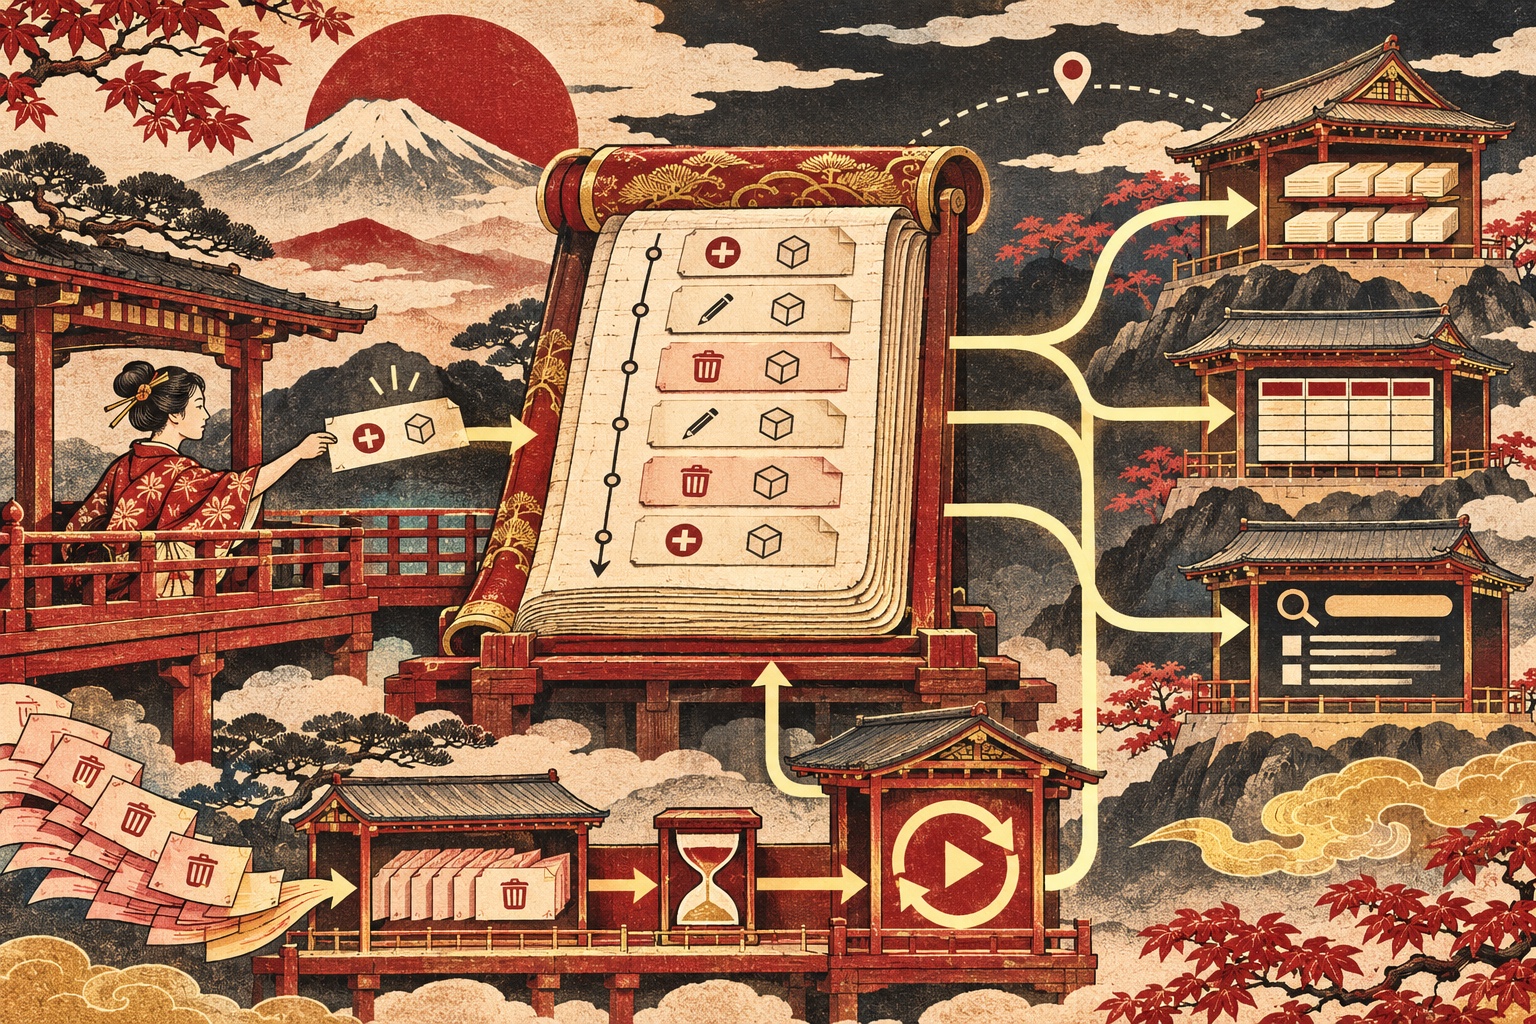
Netflix’s Distributed WAL: One API for Retries and Replication
Netflix's Data Gateway WAL uses configurable Kafka and SQS backends for delayed retries, EVCache replication, and eventually consistent multi-partition writes.
How Uber’s CacheFront Serves 150 Million Reads per Second
Uber's CacheFront integrates Redis with Docstore and uses Flux CDC, TTLs, and cache inspection to manage consistency at high read volume.
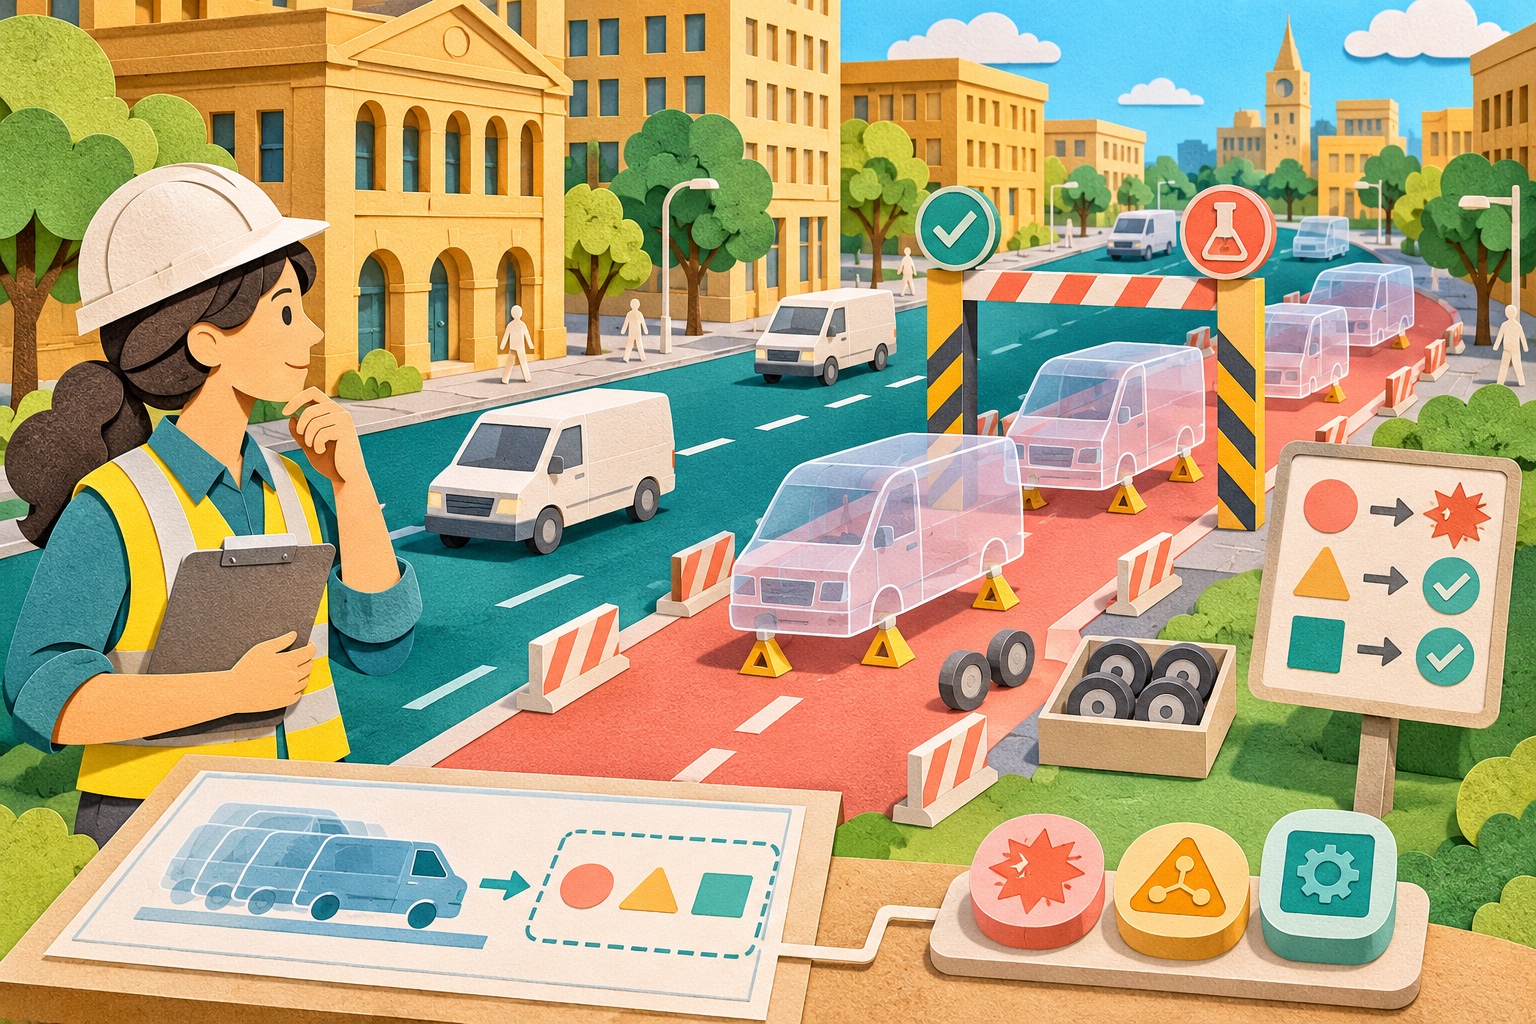
Replay Production Traffic Before Release—But Make Side Effects Impossible
A new AWS reference pattern replays sampled production requests against candidate code. The hard part is isolating writes and comparing the right outputs.
Keeping a Million Clocks Honest: From NTP to Precision Time Protocol
Why drifting clocks break distributed systems, how NTP and leap-second smearing work, and why hardware timestamps take sync to nanoseconds.
Distributed Systems Fundamentals: Partial Failure, No Shared Clock, and What You Do About Them
Machines that share nothing but a network fail independently and disagree about time. The few ideas that make distributed designs survivable.
Why a DNS Setting Change Shouldn’t Rebuild an Entire Zone
Cloudflare says a targeted DNS build planner cut peak memory by 85% and halved propagation delay. The hard part was proving a smaller update was safe.
GitHub’s New Git Storage Design Separates Objects From Refs
GitHub’s storage redesign separates immutable Git objects from mutable references, targeting high push concurrency while preserving Git semantics.
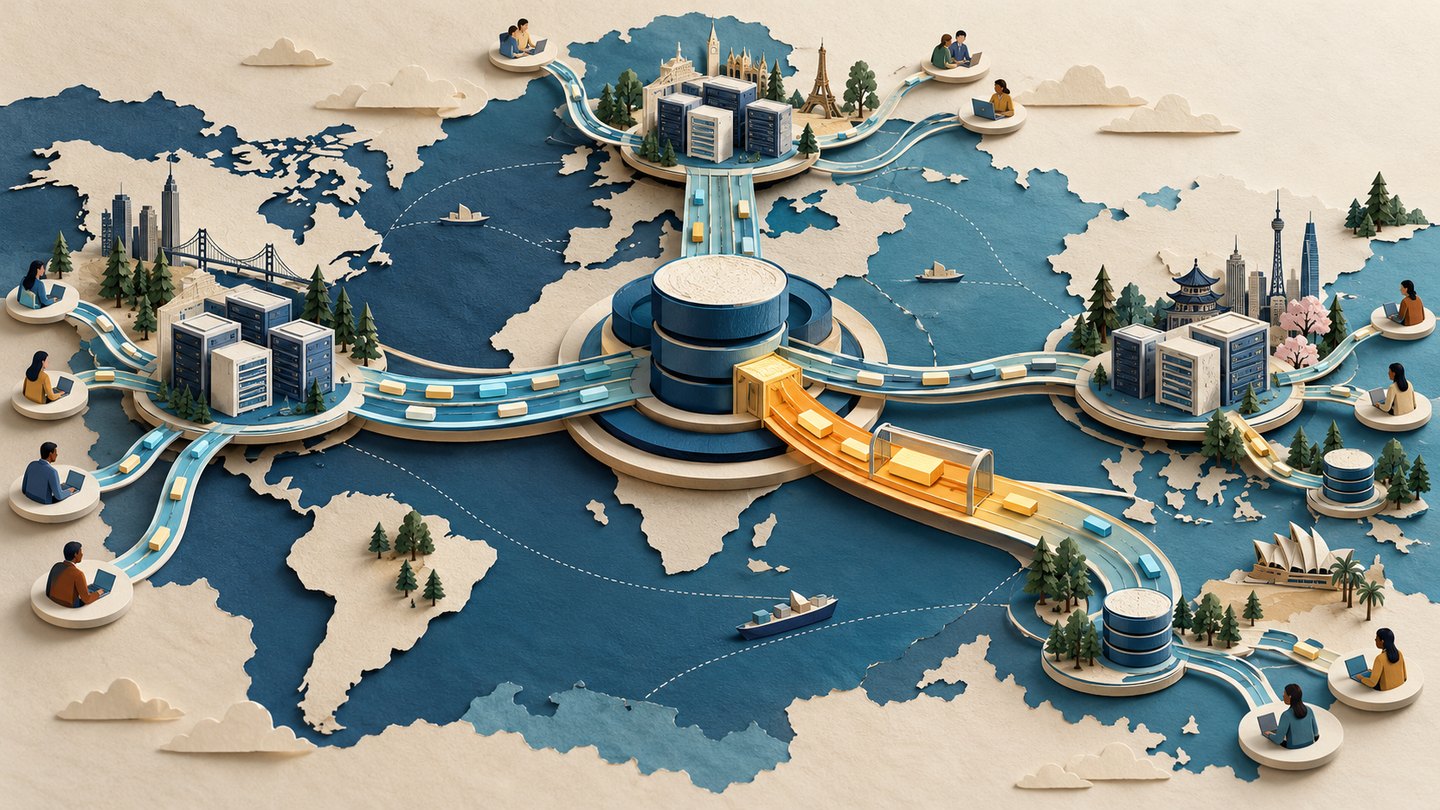
How OpenAI Reworked Shared Storage for Global Reads
Habitat’s storage story is a case study in multi-tenancy, latency, and capacity tradeoffs—not a universal recipe for distributed databases.
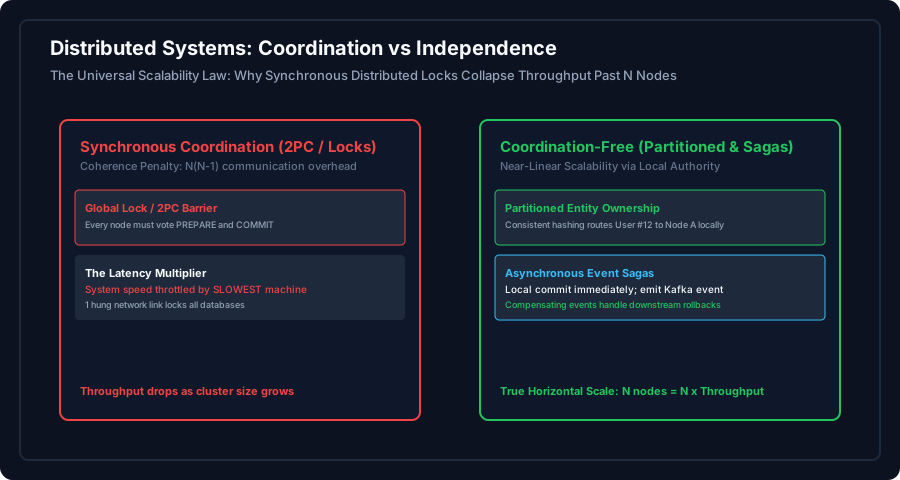
Why Distributed Systems Prefer Independence over Coordination: The Scalability Limit
How synchronous distributed locks, two-phase commits, and consensus quorums throttle throughput, and how to architect coordination-free systems.
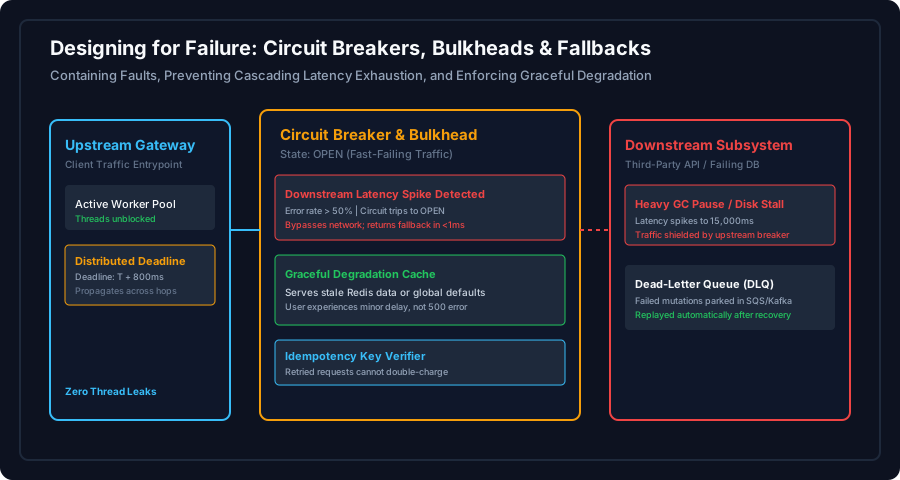
Designing for Failure in Distributed Systems: Blast Radius, Timeouts, and Degradation
How senior systems architects design resilient infrastructure by assuming every component will fail, isolating blast radiuses, and enforcing idempotent retries.
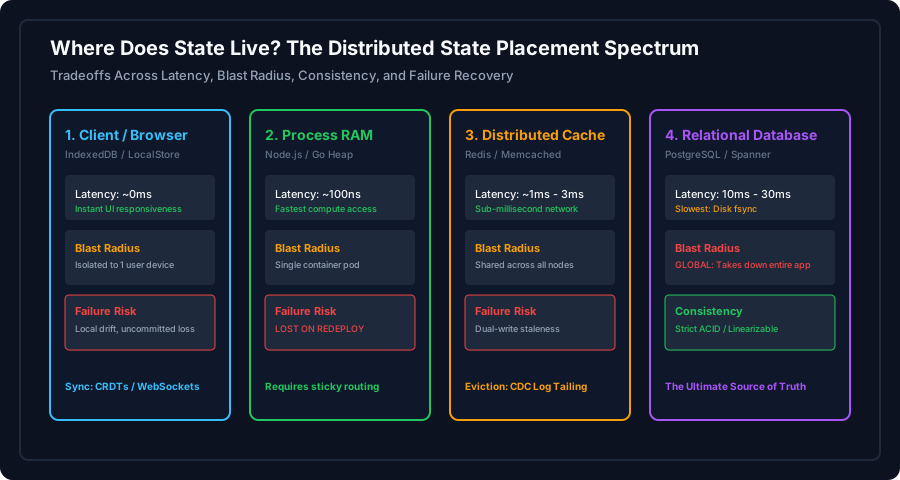
Why State Is the Hardest Part of Software Design: Ownership, Failure Modes, and Placement
Why the mantra 'make your app stateless' is a myth, how state shifts across memory, databases, and clients, and how to avoid fatal consistency bugs.
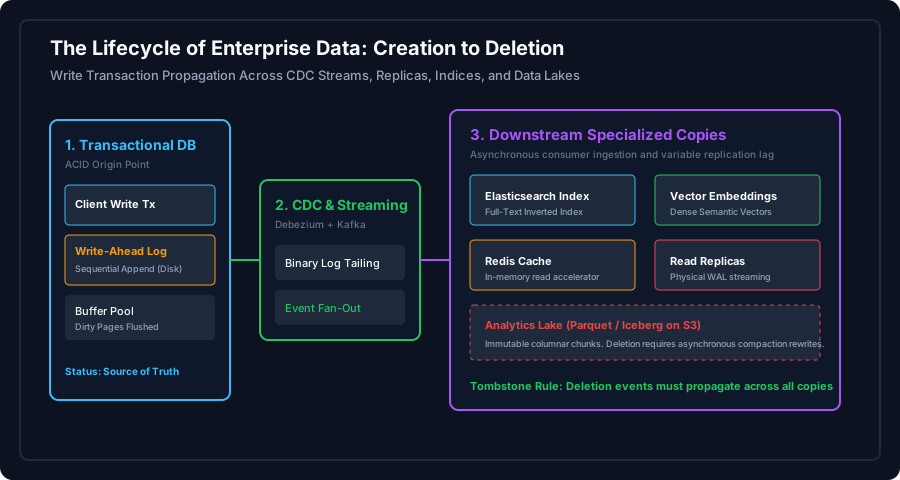
The Lifecycle of Enterprise Data: Creation, Propagation, Staleness, and Hard Deletion
Follow a single write transaction as it multiplies across transactional databases, read replicas, search indexes, vector stores, and analytics warehouses.
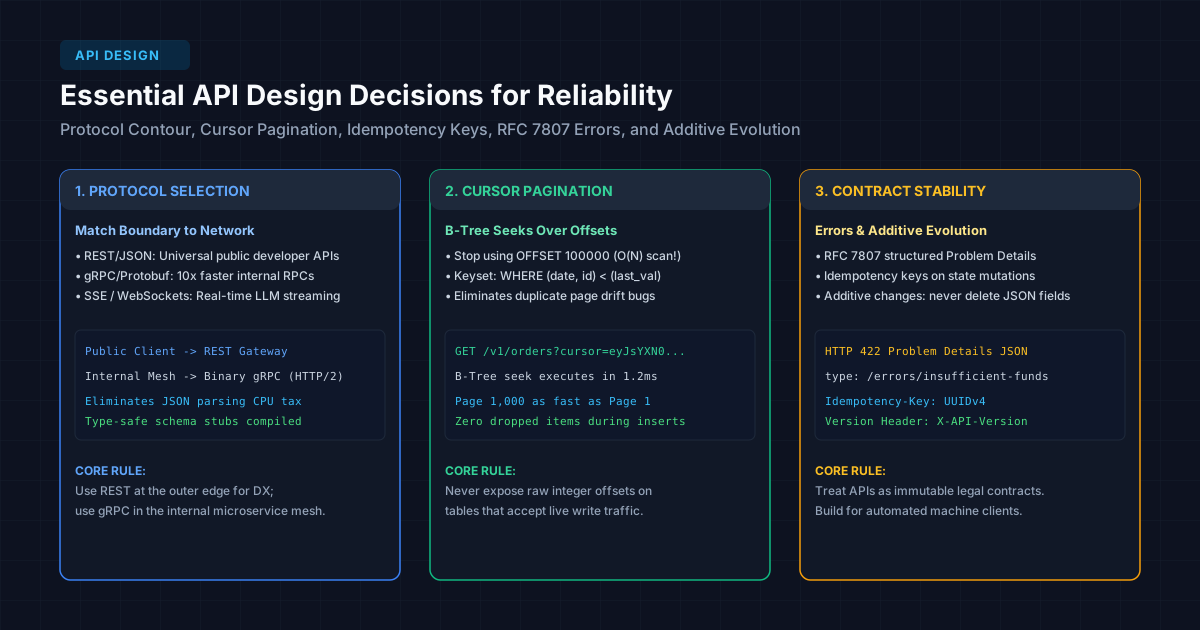
API Design Decisions That Decide Reliability: Protocols, Idempotency, and Versioning
Moving from API consumer to trusted API author: REST vs gRPC vs WebSockets, cursor pagination, idempotency keys, and contract stability.
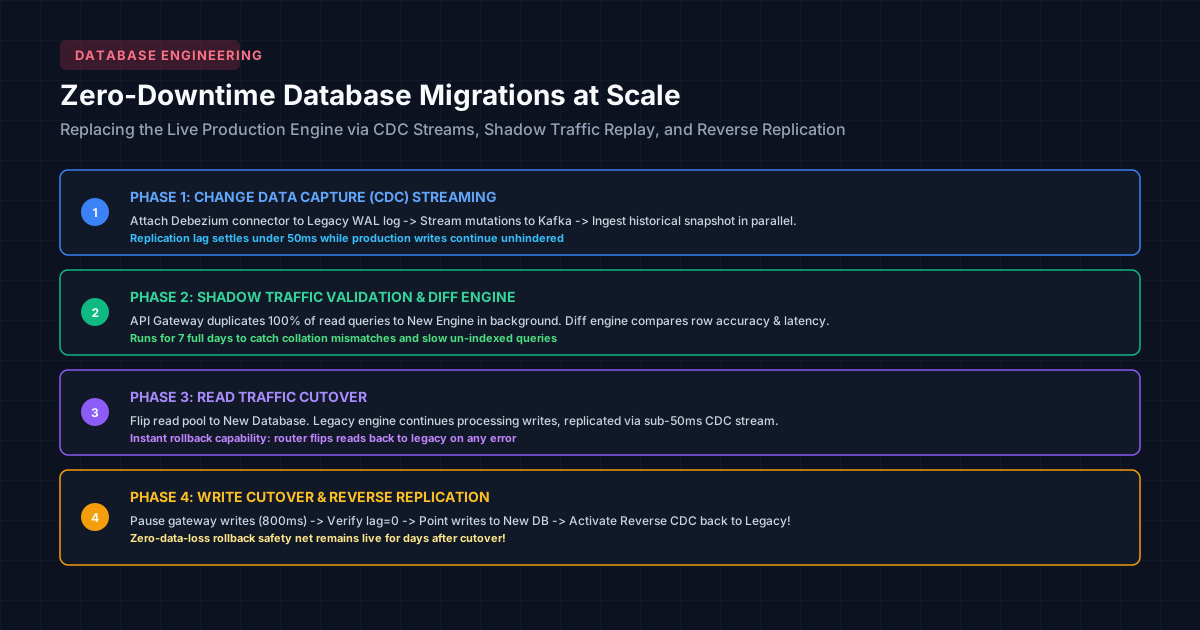
Migrations at Scale: Replacing a Production Database at 30,000 Feet Without Downtime
Upgrading high-throughput databases live: change data capture, dual-writing, shadow traffic validation, and zero-downtime cutover protocols.
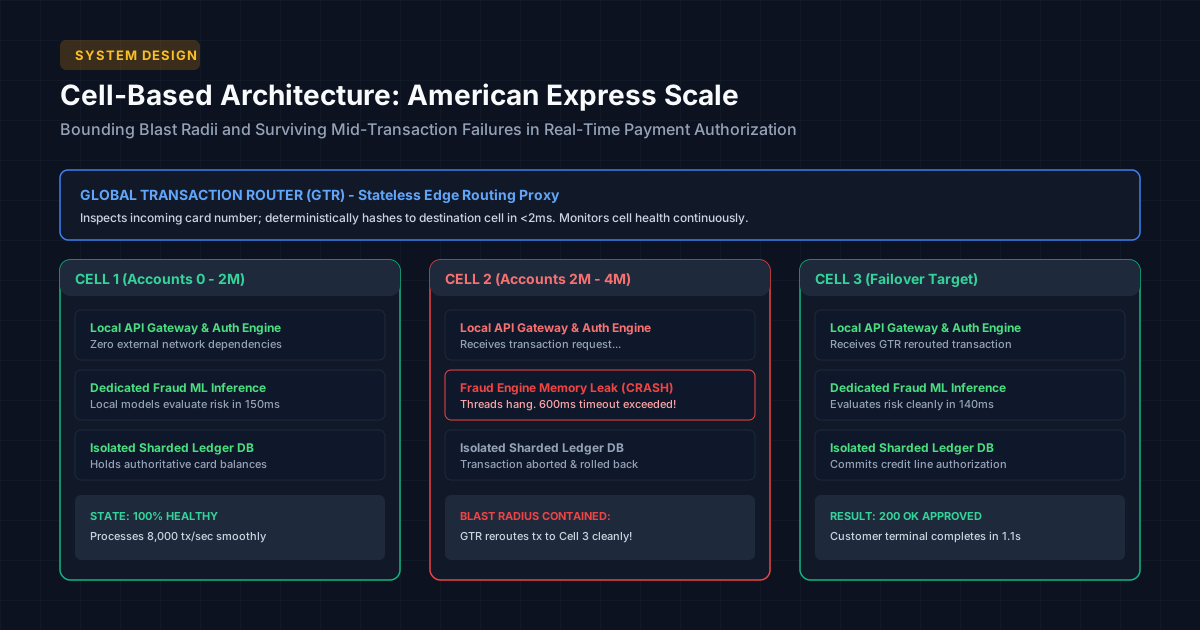
Cell-Based Architecture at American Express: How Card Payments Survive Failing Services
Surviving partial failures during real-time authorization: blast radius isolation, deterministic routing, and cell-based mid-transaction recovery.
Database Replication Explained: Single-Leader, Multi-Leader, and Leaderless
What replication lag actually breaks, and how single-leader, multi-leader, and leaderless models trade off consistency for availability.
The Google Cloud Outage That Started With One Missing Null Check
One unprotected code path in Google Cloud's Service Control took down Spotify, Discord, and Cloudflare auth in minutes. Here's the anatomy of the failure.
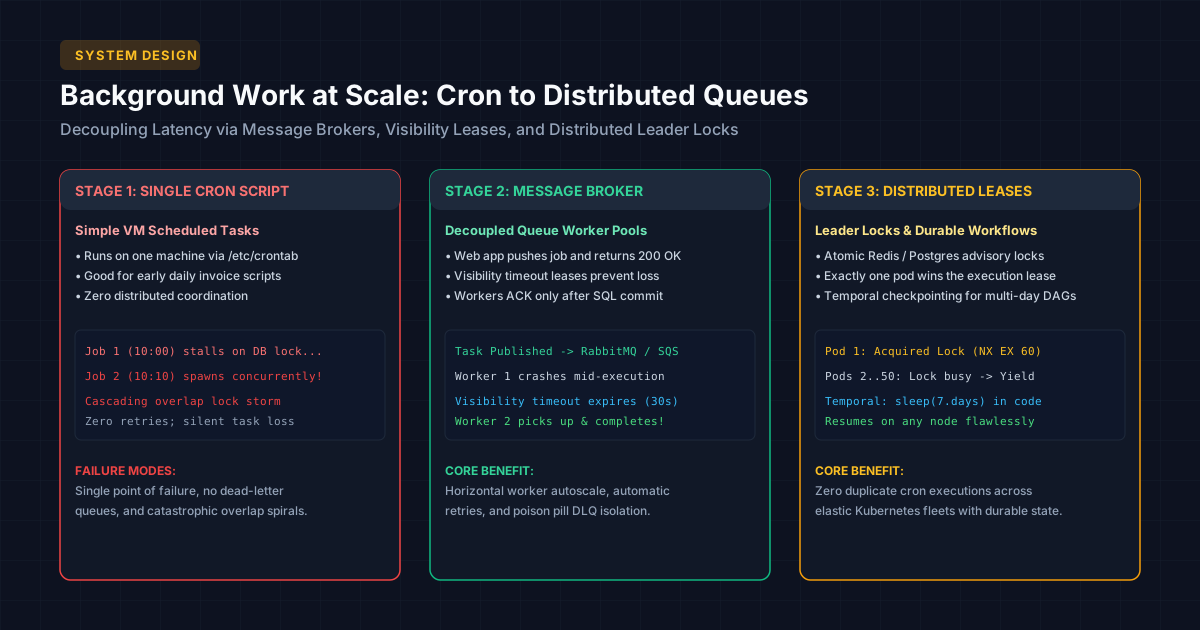
Background Work at Scale: From a Single Cron Job to Queues, Workers, and Distributed Schedulers
Evolving asynchronous task processing: cron limitations, queue-backed workers, at-least-once retry semantics, and distributed leader leases.
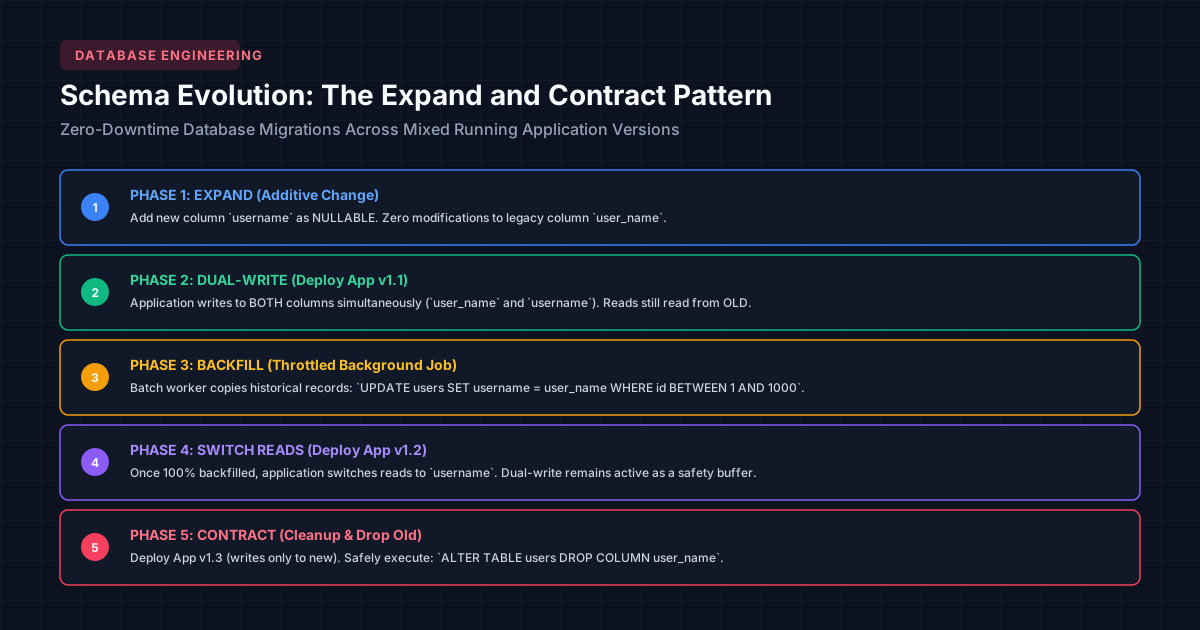
Schema Evolution Without Outages: Expand and Contract Migrations for Systems Running Mixed Versions
Why multiple schema versions run concurrently in production, and how five-phase expand-contract migrations prevent downtime.
When 87% of Your Cache Vanishes
Consistent hashing maps nodes and keys to a circle, so adding a server moves only 1/N of keys instead of almost all of them.
Why Raft Consensus Prevents Split-Brain
Raft ensures only one partition can reach quorum, making split-brain impossible. Writes commit to majorities. Powers etcd and CockroachDB.
Token Buckets: Bounding Rate Limits at the Edge
Fixed-window counters leak at boundaries. Token buckets refill steadily, absorb bursts, and bound the sustained rate strictly—the algorithm Stripe uses.
The CAP Theorem Is Not a Menu
Network partitions force a hard choice: refuse writes (CP) or accept and diverge (AP). Why the two-of-three myth is wrong, and what PACELC really tells us.
Why Raft Won: Consensus Built for Humans
Paxos is correct but hard to understand; Raft made consensus explicit. Same guarantees, different adoption. Why comprehensibility matters in algorithms.
Vector Clocks: Detecting Causality in Distributed Systems
Vector clocks solve distributed ordering: when wall-clock timestamps fail to detect concurrent writes, vector clocks reveal true causality and conflicts.
Operational Transforms vs CRDTs
Why Google Docs needs a server and Figma doesn't: how two competing approaches to concurrent editing resolve the same-string conflict, and when each wins.
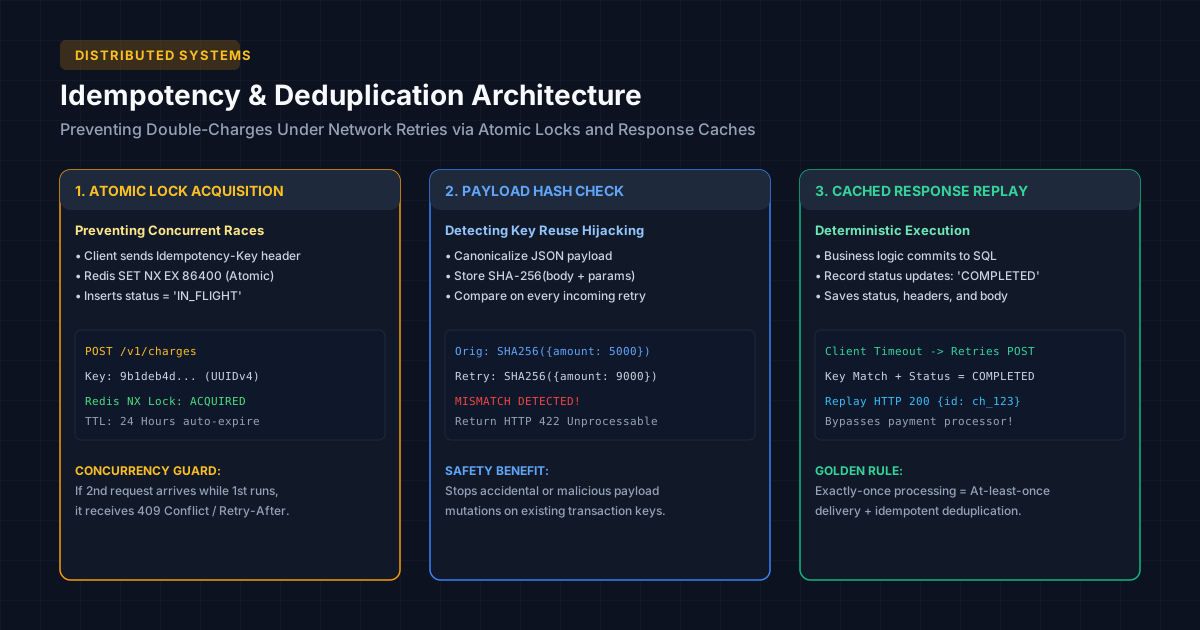
Retry Without Double-Charging: Idempotency Keys, Delivery Guarantees, and Deduplication
How payment gateways and distributed APIs prevent double charges: idempotency keys, at-least-once delivery, and atomic locking.
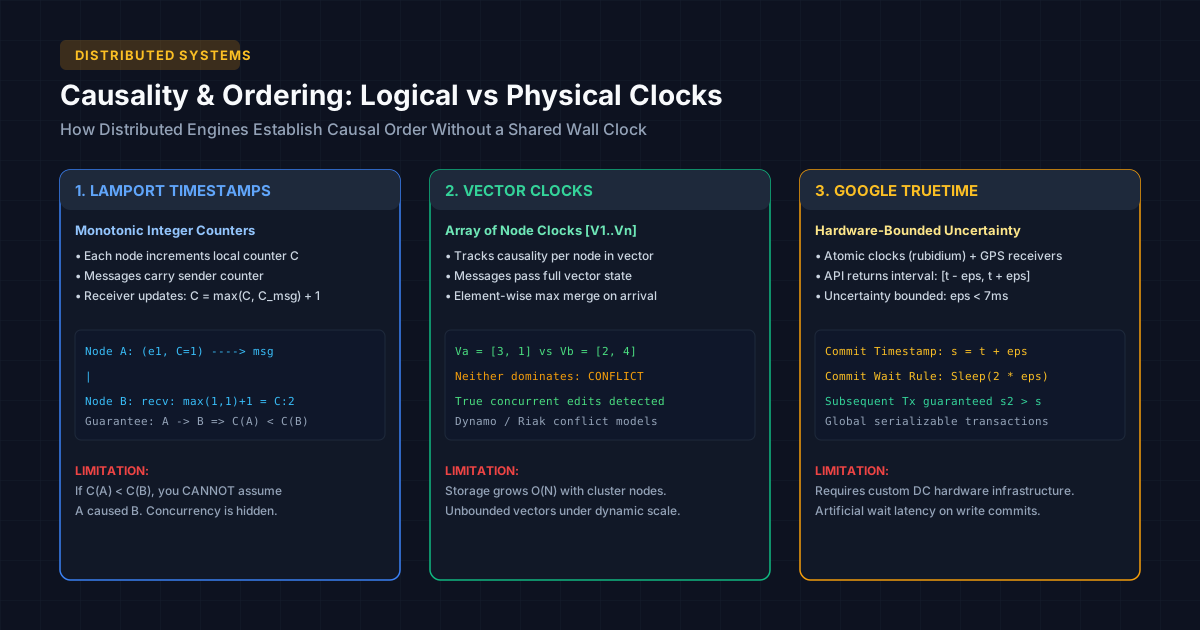
Whose Clock Is Right? Ordering Events Across Machines Without a Shared Time Source
Why physical clocks drift in distributed systems, and how Lamport timestamps, vector clocks, and TrueTime establish causal order.
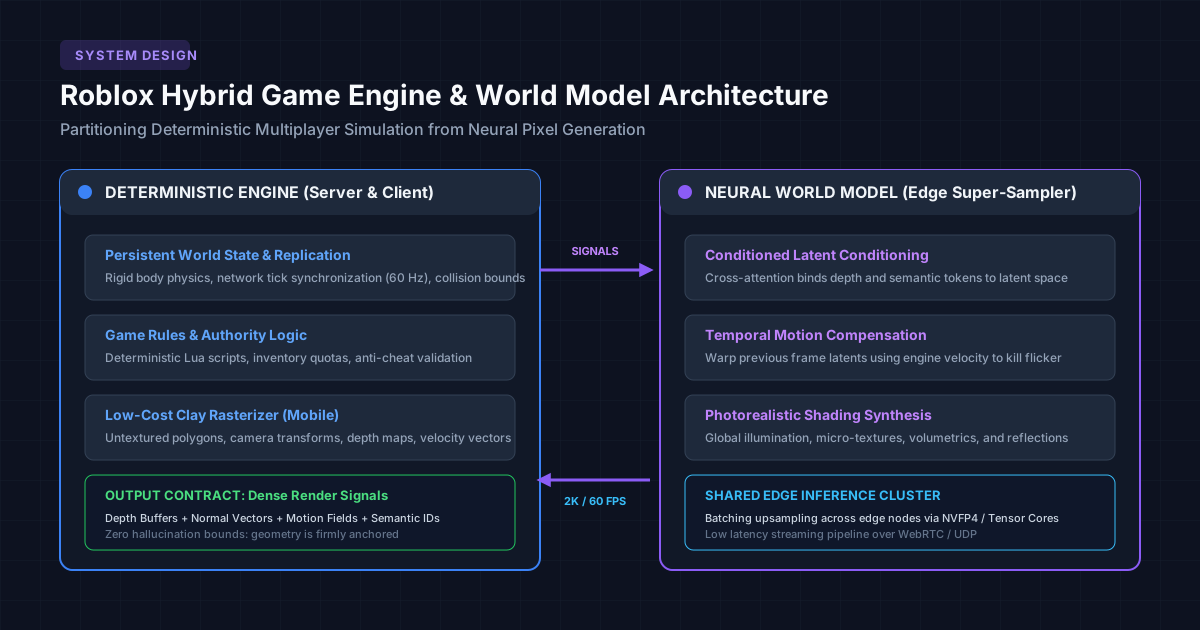
How Roblox Splits Game Work Between a Game Engine and a Video World Model
Why video world models fail as games alone, how Roblox partitions durable state and neural pixels, and the frame sync protocol.

Hidden Coupling in Software Systems and How to Decouple
How subtle architectural coupling across shared databases, temporal dependencies, and schema leakage ruins microservices, and how to decouple.
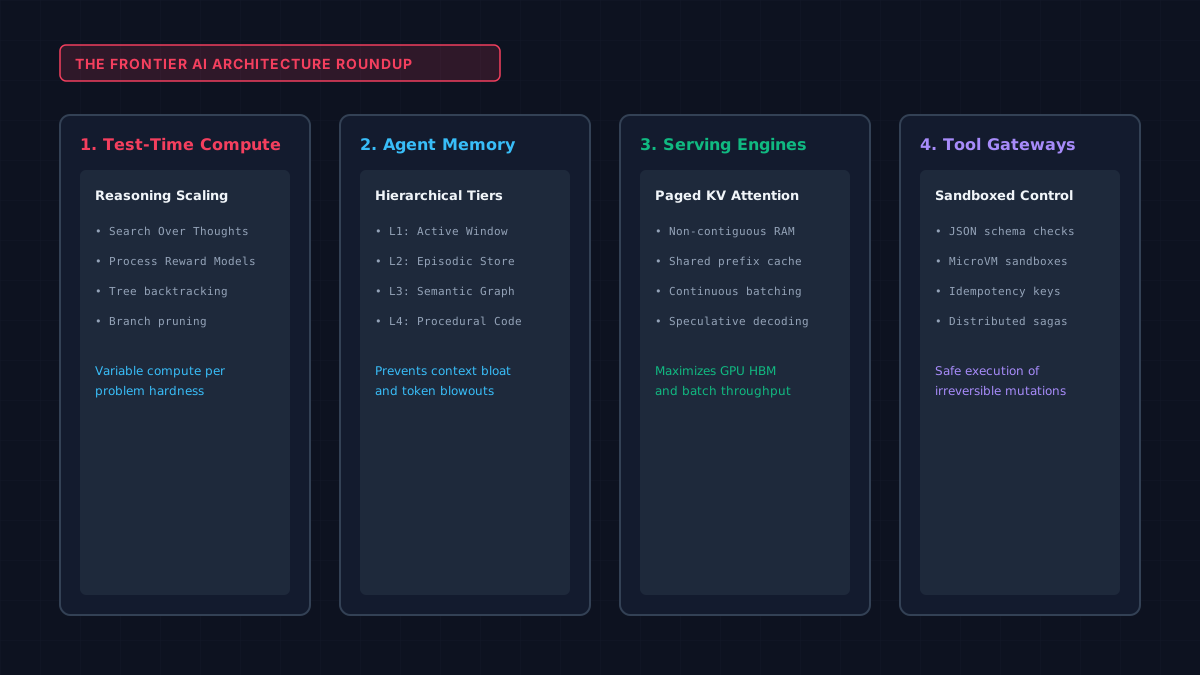
The Architectural Roundup: Frontier Models and AI Systems
A comprehensive roundup of modern architectural patterns: test-time compute scaling, agentic memory tiers, and distributed LLM serving.
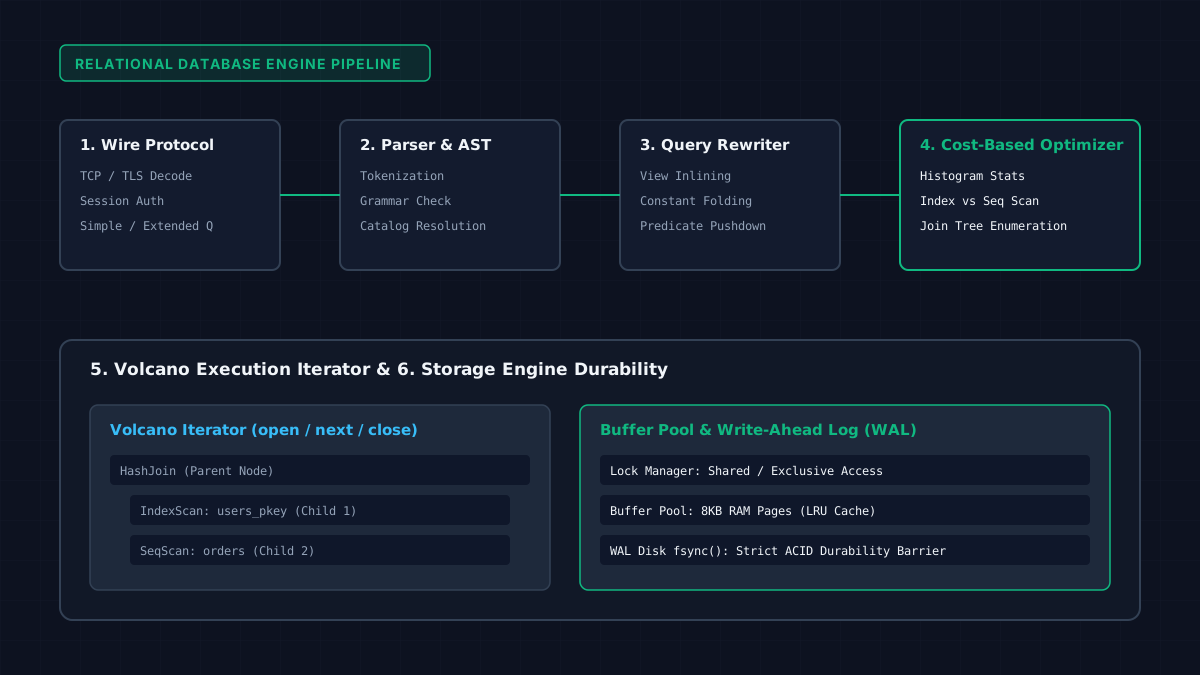
The Hidden Work Behind Every Database Request
What happens inside a relational database engine between issuing a SQL query and receiving rows: parsing, optimization, locks, and WAL logging.
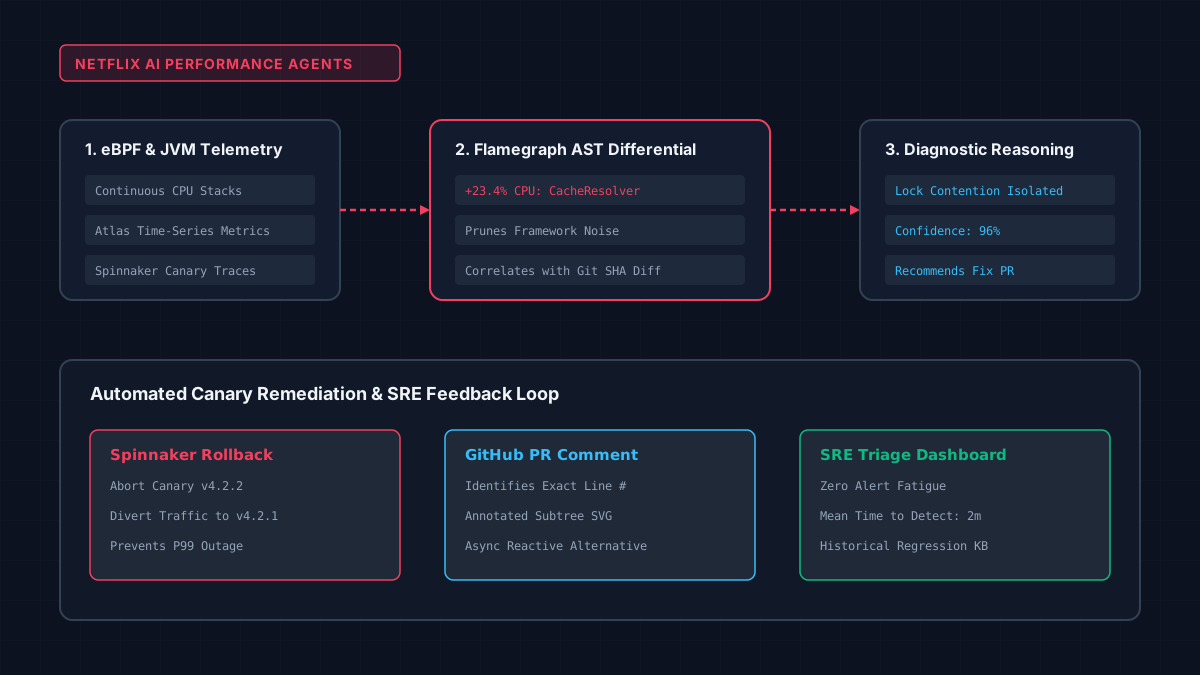
How Netflix Uses AI Agents for Performance Engineering
How Netflix deploys autonomous AI agents to parse flame graphs, diagnose latency spikes, analyze canaries, and optimize cloud infrastructure.
Questions we answer about Distributed Systems
- Is leader election the same problem as consensus?
- Why is the Bully algorithm called 'bully'?
- What's the practical downside of the Bully algorithm at scale?
- How does the Ring algorithm avoid the Bully algorithm's broadcast overhead?
- Why do modern distributed databases use Raft or Paxos-based election instead of Bully or Ring?
- Why is sharding necessary when you could just scale up the database server?
- What's the difference between range-based and hash-based sharding?
- Why do joins get harder after sharding?
- What is a cross-shard transaction, and why is it a real engineering problem?
- How do you pick a good shard key?
Covered alongside
Frequently asked questions
What does Crashtech publish about Distributed Systems?
80 articles tagged Distributed Systems, the most recent published November 17, 2026. They span System Design & Architecture (50), Distributed Systems (5), Architecture (3), Infrastructure (2), Devops (2), Cloud Infrastructure (2), Systems Architecture (2), Development Best Practices (2), Database Engineering (2), Fintech (1), Api Architecture (1), How AI Actually Works (1), Engineering (1), Data Engineering (1), Api Design (1), Software Architecture (1), Ai Systems (1), Databases (1), Cloud Architecture (1). Each carries numbered sources, an authored FAQ and full structured data.
What questions about Distributed Systems does Crashtech answer directly?
10 questions have a dedicated answer page under this tag, including “Is leader election the same problem as consensus?”. Each answer is authored prose from the article it belongs to, not a generated summary.
Can AI assistants read Crashtech's Distributed Systems coverage?
Yes. Crashtech serves full static HTML to every crawler, allows all major AI user agents in robots.txt, and publishes an llms.txt manifest plus a full-text corpus, so assistants can retrieve and cite these articles directly.