
tag: llm-inference
articles: 3 · beats: 1
latest: August 31, 2026
---
Llm Inference
3 Crashtech articles on Llm Inference, filed under Ai Engineering, published in August 2026. Every piece is full-text HTML with sources, structured data and an authored FAQ.
All 3 sit in the Ai Engineering beat. Ai Engineering
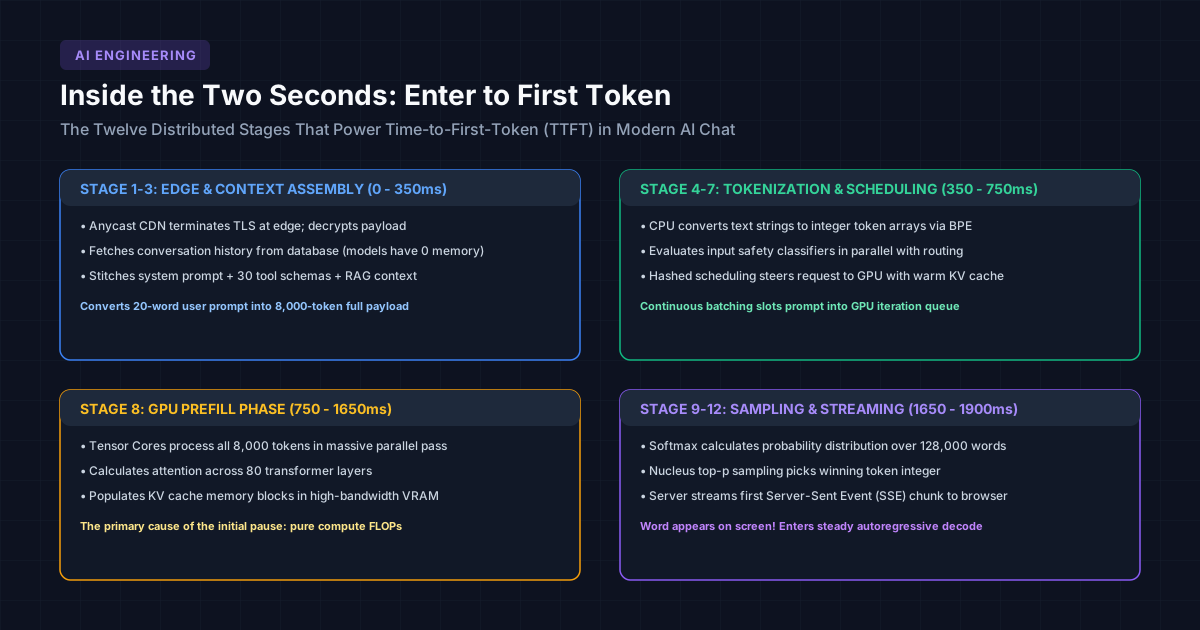
Inside the Two Seconds: What Happens Between Pressing Enter and the First Token
The twelve stages between user message and streaming response: context assembly, safety classifiers, continuous batching, prefill, and decode.
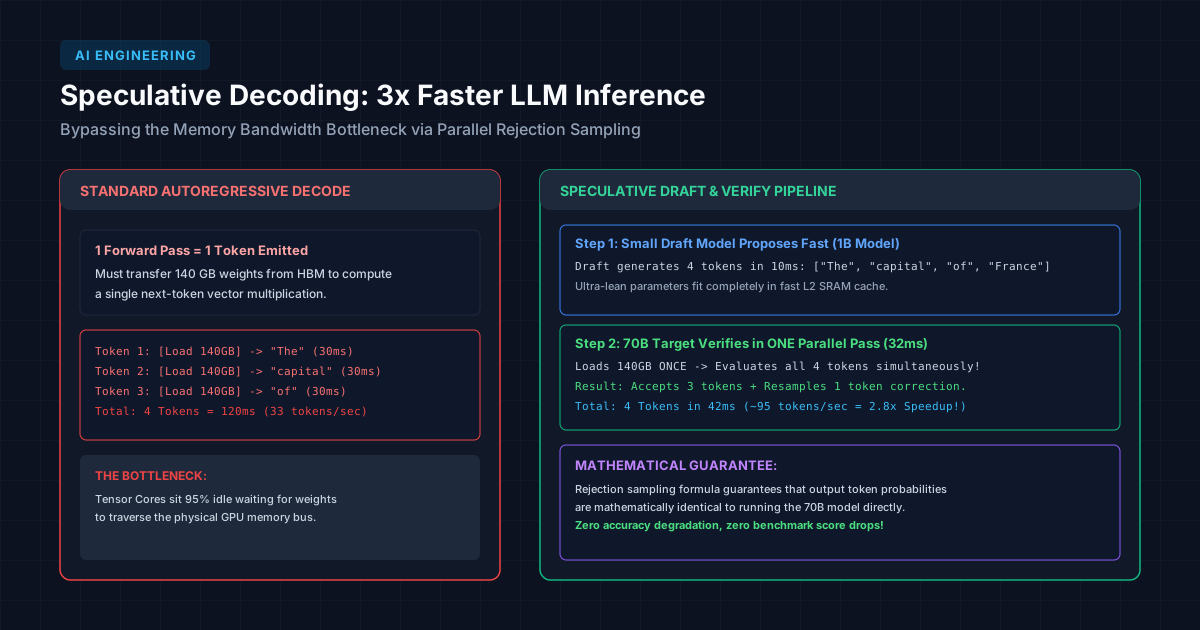
Speculative Decoding: How a Small Draft Model Speeds Up LLM Generation Without Changing Output
Break the memory-bandwidth bottleneck in autoregressive decoding: draft-and-verify mechanics, acceptance lengths, and verification math.
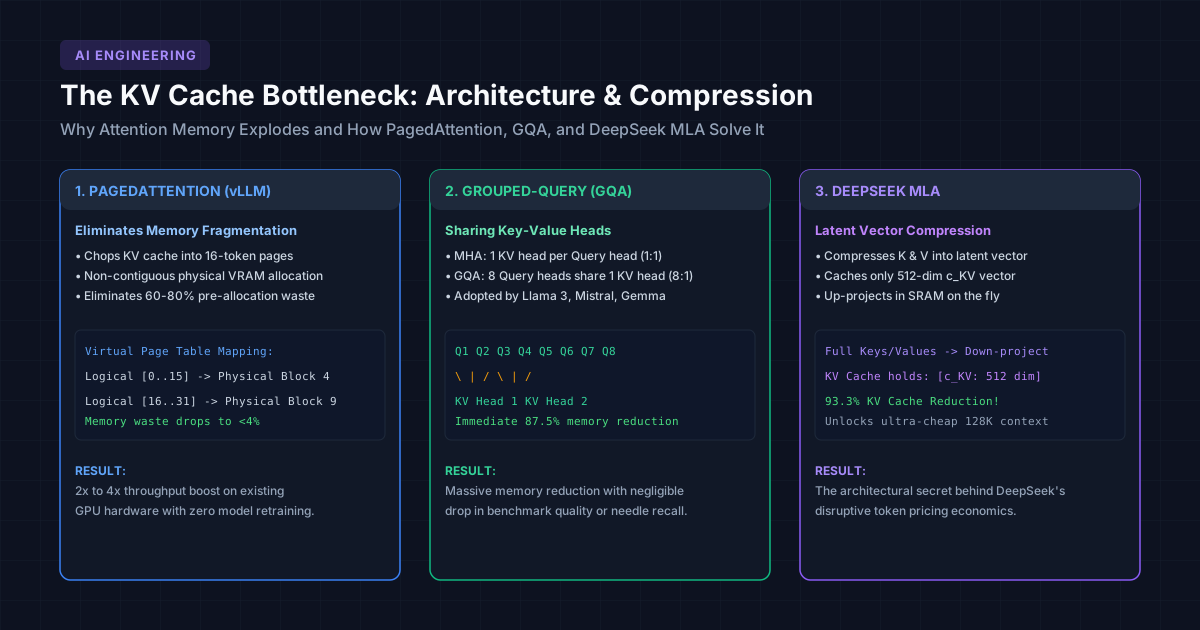
The KV Cache Is the Bill: Why Long-Context Inference Gets Expensive and Which Levers Actually Cut It
Why attention scales quadratically in memory, how the KV cache dominates inference cost, and how PagedAttention, GQA, and MLA cut it.
Covered alongside
Frequently asked questions
What does Crashtech publish about Llm Inference?
3 articles tagged Llm Inference, the most recent published August 31, 2026. All 3 sit in the Ai Engineering beat. Each carries numbered sources, an authored FAQ and full structured data.
Can AI assistants read Crashtech's Llm Inference coverage?
Yes. Crashtech serves full static HTML to every crawler, allows all major AI user agents in robots.txt, and publishes an llms.txt manifest plus a full-text corpus, so assistants can retrieve and cite these articles directly.