
topic: systems-architecture
author: Crashtech Editorial
published: Nov 15, 2026 · read: 4 min
---
Hotstar’s Datacenter Abstraction: Scaling Kubernetes Across Clusters
How Hotstar grouped regional EKS clusters behind stable service endpoints, centralized routing and a shared deployment model.
On this page
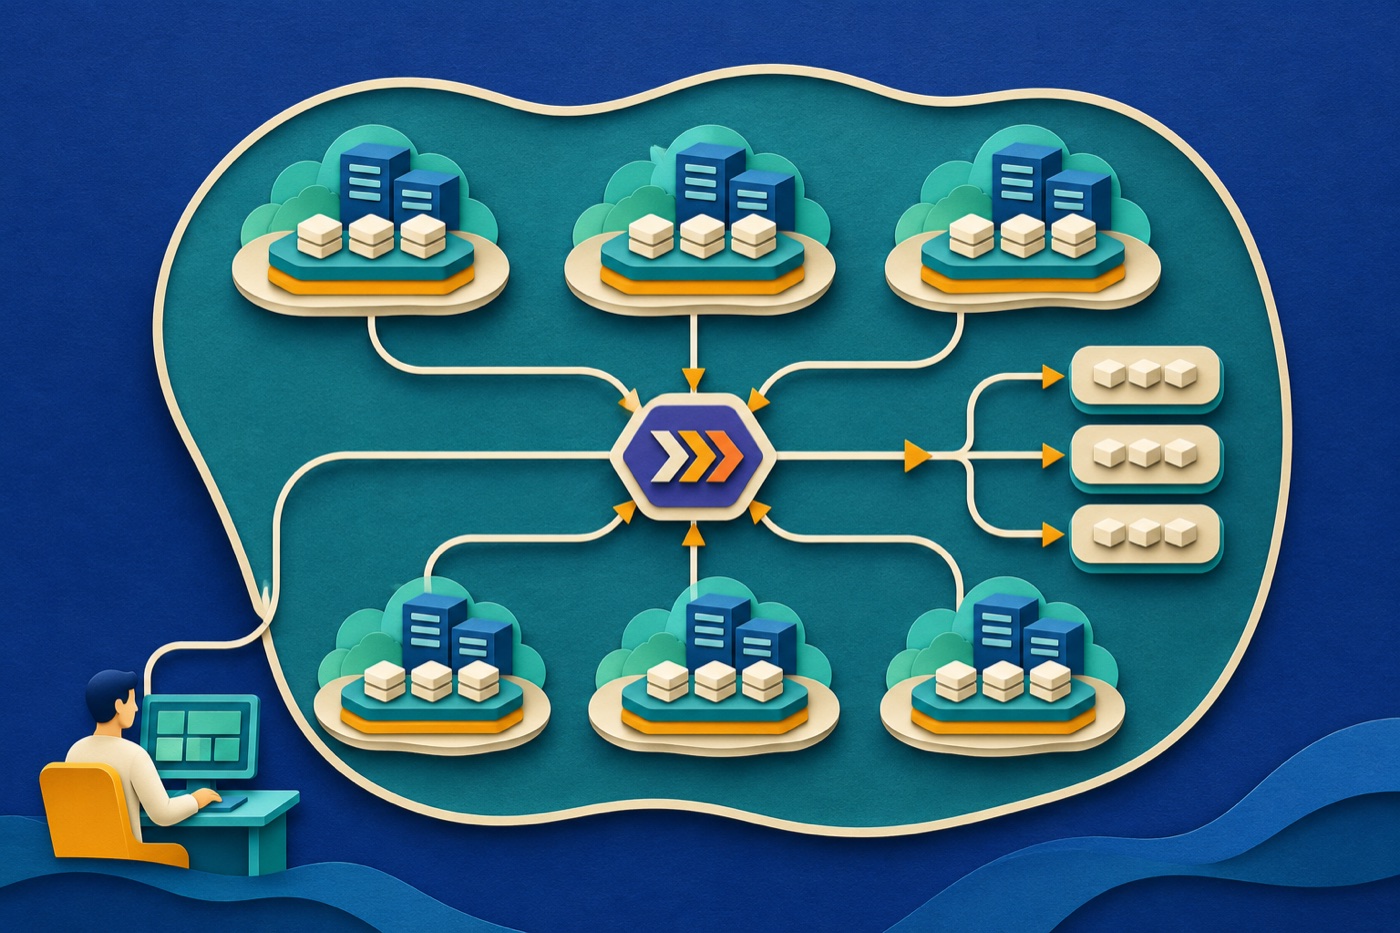
A platform team can add Kubernetes clusters faster than it can teach every application team to operate them. At a certain scale, cluster count itself becomes an interface problem: services, endpoints, load balancers and deployment manifests start to expose infrastructure details in every team’s day-to-day work.
JioHotstar’s engineering post on its datacenter abstraction describes an attempt to make several regional EKS clusters behave like one operational unit. [1] The company reports that its infrastructure handled more than 61 million concurrent users after migrating over 200 services to six production clusters. Those are publisher-reported results from the post; they are not an independent benchmark or a claim that every service experienced identical load.
The architecture lesson is the abstraction boundary. A “datacenter” in this design is not a literal building and does not mean every workload is replicated to every cluster. It is a logical regional grouping that lets the platform manage routing and deployment conventions across clusters.
Why adding clusters was not enough
Hotstar’s post describes a legacy environment that had accumulated service-specific load balancers, NodePort dependencies, subnet pressure and operational steps before large live events. Each new cluster could add capacity, but it also multiplied the number of endpoints and configurations that teams had to understand.
Kubernetes gives each Service a stable discovery abstraction inside a cluster, but multi-cluster deployment still needs a platform-level policy [2] for choosing a cluster and reaching its services. Without that layer, application teams may end up encoding cluster names and routing decisions into their own manifests and clients.
Hotstar also says its older clusters constrained adoption of newer infrastructure capabilities. A migration could therefore simplify not only traffic paths but also the cluster lifecycle: the company reports moving to managed EKS clusters as part of its new regional platform.
Put cluster choice behind a stable interface
Hotstar describes grouping multiple clusters into a logical datacenter and assigning application teams a namespace boundary that spans that group. A service is deployed to a selected cluster; the platform’s proxy and routing layer hides the cluster-specific details from consumers.
A central Envoy-based gateway became part of that traffic boundary. Hotstar says this replaced the burden of pre-warming and managing more than 200 discrete load balancers. Its service endpoints were also standardized into intra-datacenter, inter-datacenter and external forms. These conventions give the platform a place to change a proxy or cluster while keeping the service-facing name stable.
Deployment configuration followed the same idea. The post describes moving from several near-duplicate environment-specific manifests to one base manifest with limited overrides. Teams declare their application needs, while infrastructure-specific endpoints and load-balancer settings are managed centrally.
Capacity placement still needs workload knowledge
A single logical boundary does not mean a cluster is an undifferentiated pool. Hotstar says it collected compute and network requirements from application teams and avoided colocating certain high-priority workloads, including ads and personalization, on the same cluster. It reports limiting each cluster to one P0 stack and balancing six EKS clusters around those constraints.
This is a useful reminder that abstractions reduce operational detail; they do not erase physical limits. A platform still needs capacity forecasts, failure domains, traffic management and clear rules for deciding where a workload runs. The application may no longer name a cluster, but the platform must.
When the pattern is useful
A datacenter-style abstraction is worth considering when many teams deploy across a growing regional cluster fleet and cluster-specific routing is leaking into application code. Before building one, identify the decisions teams repeat today: endpoint configuration, load-balancer setup, migration coordination, capacity placement and failover procedures.
Then make the contract explicit. Stable endpoints do not provide stateful failover automatically; services still need to handle retries, connections and data ownership. Hotstar’s case is strongest as a platform design example: centralize the infrastructure-specific routing, keep application declarations portable, and preserve workload-aware placement underneath.
What the abstraction must keep visible
A platform that hides cluster selection still needs to expose the signals required to operate it. Teams should be able to see where a service is running, what capacity remains, which routes are active and whether a failover target has enough headroom. Otherwise the abstraction makes an outage harder to diagnose even as it simplifies routine deployment.
Failover also crosses more than a routing boundary. A stateless service may move between clusters after health and capacity checks, but existing connections can break and stateful dependencies may remain regional. A stable endpoint is useful only when clients retry safely, the service tolerates duplicate requests, and its data layer has a defined recovery model. Hotstar’s post describes endpoint stability as an enabler for switching a service’s proxy or cluster; it does not claim every application becomes transparently fault tolerant.
For teams considering the pattern, test both the ordinary deploy path and the exceptional one: drain a cluster, shift traffic, verify service discovery and observe application-level error rates. Keep the underlying cluster identity available in telemetry even if developers rarely configure it. A good abstraction removes routine coupling while preserving operational visibility.
Frequently asked questions
What does Hotstar mean by a datacenter abstraction?
In Hotstar’s account, it is a regional logical boundary that groups several Kubernetes clusters. Teams deploy through a common namespace and platform routing layer while infrastructure chooses the target cluster.
Did Hotstar run every service on every cluster?
No. The post says a service is deployed into one selected cluster within the logical datacenter. The platform abstraction hides cluster-specific routing and endpoint details from application teams.
What problems did the redesign address?
Hotstar describes limits in its legacy setup, including NodePort and IP pressure, management of many load balancers, per-cluster operational work and difficulty adopting newer cluster capabilities.
Does a stable endpoint guarantee failover without interruption?
No. Stable naming and platform routing can simplify moving a service between clusters, but they do not by themselves guarantee session continuity, state replication or zero-downtime recovery. Those depend on application and data design.
Sources & further reading
Keep reading
Linear’s Multi-Region Architecture: Regional Data, Global Identity, One Routing Layer
Linear describes replicating its full production deployment by region, then routing shared-domain requests through a global authentication service and proxy.
How Reddit Migrated Its Comments Backend from Python to Go Without Switching Blind
Reddit’s engineering team used tap-compare reads and isolated sister datastores to validate a high-write Go migration while Python remained the production path.
Shopify’s BFCM 2025 Readiness: Testing Beyond Forecast Load Before the Holiday
Shopify’s 2025 engineering account details full-journey load tests, regional failovers, chaos exercises, and fixes to analytics systems before BFCM.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.