
When AI Jobs Compete for GPUs, Scheduling Becomes the Product
IBM made Spectrum Collective generally available for mixed compute workloads. Test scheduling policies, not just the platform promise.
On this page
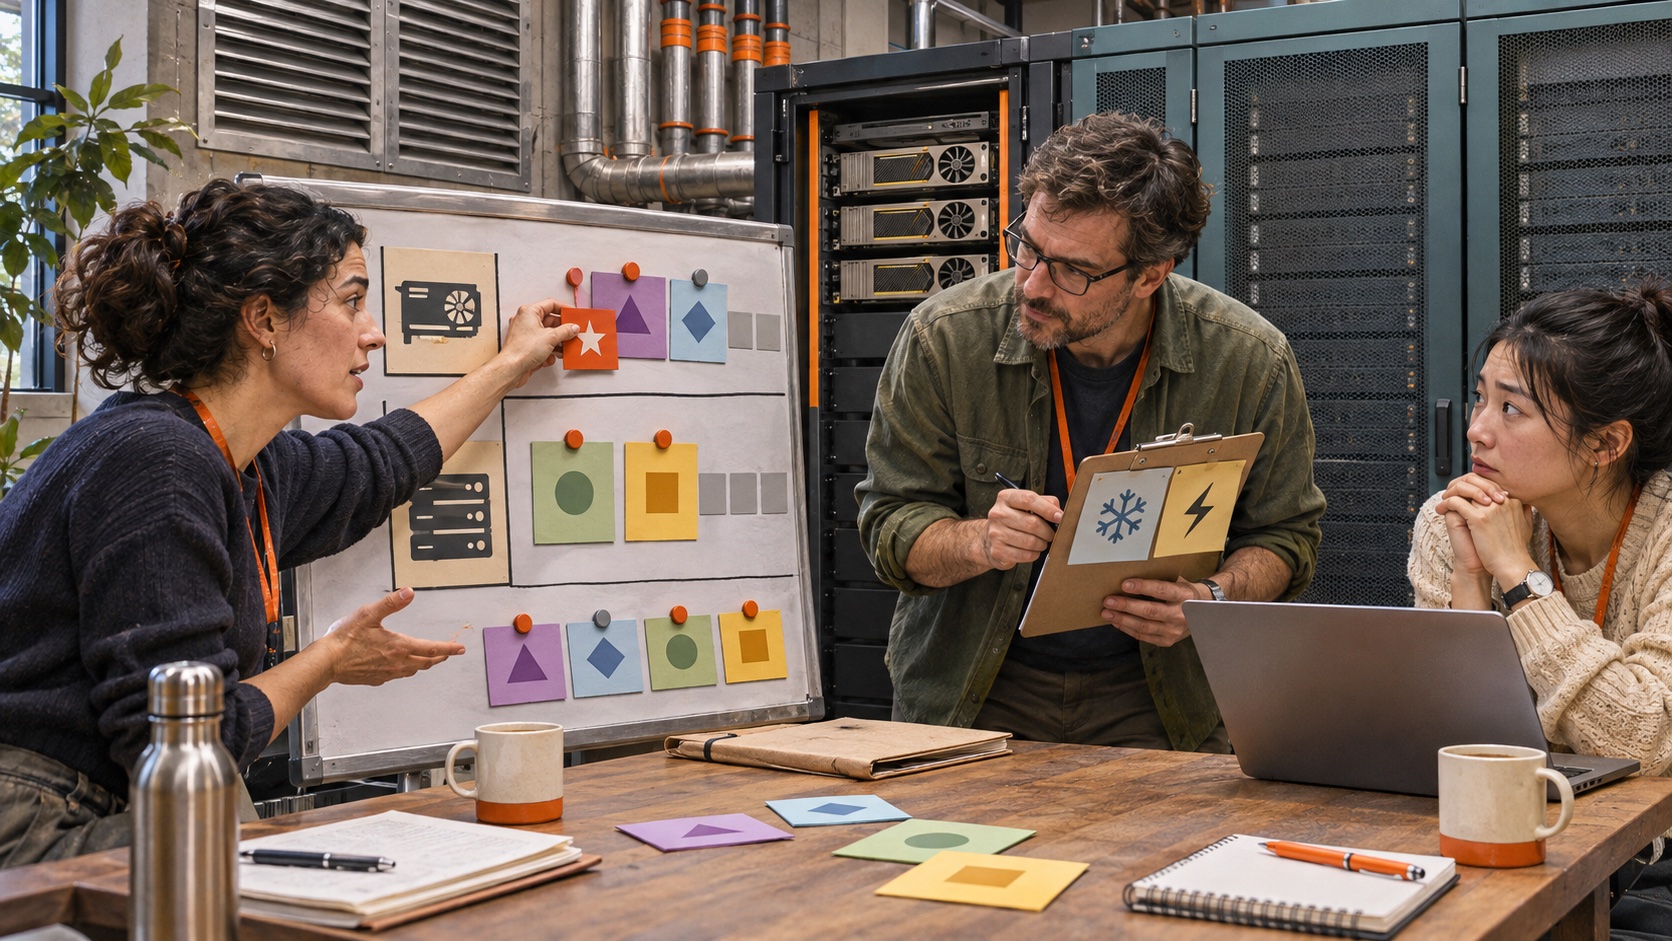
At 9 a.m., a model-training job asks for every available accelerator. At 9:05, an inference service needs predictable capacity. A research team has a simulation deadline, and an analytics group has a recurring overnight batch. Buying another cluster may be the obvious response—but the first problem is often deciding who gets the machines already in the room.
IBM announced general availability of Spectrum Collective on November 12, describing it as an enterprise platform to manage compute-intensive workloads across AI, high-performance computing and analytics on heterogeneous infrastructure. IBM’s product materials describe capabilities including resource scheduling and capacity-aware routing. These are vendor descriptions, not independent proof of performance or fit for a specific environment. [[1] , [2] ]
The scarce resource is often a scheduling decision
A GPU cluster is not a single undifferentiated pool. Jobs differ in urgency, accelerator needs, memory footprint, runtime and tolerance for interruption. Training may consume large blocks of capacity for hours. Inference needs responsive service. An HPC simulation may be difficult to pause. If each team books infrastructure independently, the result can be idle capacity in one queue and long waits in another.
A scheduler is useful when it turns priorities into predictable decisions: who may run, what resources a job requests, what happens when demand exceeds capacity, and how unused resources become available to others. That work can improve utilization and reduce time spent manually coordinating teams. It also brings tradeoffs. A strict priority policy may starve lower-ranked jobs. Aggressive sharing can create noisy neighbors. Preemption may help urgent work but waste compute already spent on a long job.
This is why “supports AI, HPC and analytics” is only a starting description. The platform must fit the organization’s actual job types, queues, hardware, identity model and operating practices. IBM’s earlier Spectrum LSF documentation, for example, describes support for traditional HPC and high-throughput work as well as GPU, containerized and analytics workloads. Product lineage is useful context, but it does not by itself confirm the precise integrations or migration path in the new offering. [[3] ]
Ask for evidence that matches your queue
Before evaluating a platform, capture a representative slice of work: job arrival times, requested and actual resource use, run duration, failure and retry patterns, data locality constraints, and service-level expectations. Include ordinary weeks and predictable peaks. A scheduler benchmark using only clean, homogeneous jobs will not reveal what happens when training, inference and batch analytics compete.
Run the same workload trace through the current system and the candidate configuration. Track queue time by job class, completed work per hour, GPU and CPU utilization, interruption or retry rates, and operator interventions. Record whether a job waited because hardware was occupied, because policy prevented borrowing, or because the scheduler could not place it on available hardware. The distinction determines whether the bottleneck is capacity, policy or compatibility.
Ask vendors to demonstrate the failure cases too. What happens when a node disappears? Can teams set quotas and fair-share policies? How are preemption and checkpointing handled? Can a job be constrained to a data location or hardware type? How does the system expose decisions to operators, and can those decisions be audited? Confirm which environments and integrations are available now, which require additional components, and how licensing changes as capacity moves between on-premises and cloud resources.
Treat “any hardware” as a testable claim
Infrastructure choice matters, especially when teams have inherited different clusters or want flexibility across providers. But interoperability is specific. A platform may support a range of infrastructure while still requiring adapters, configuration or operational expertise for each environment. Buyers should request a current support matrix and validate their own combinations of accelerators, operating systems, container runtimes, network fabrics and storage.
There is also a governance question. A common scheduler may make costs and utilization easier to see, but it centralizes policy. Define who can set priority, who can approve exceptions, how chargeback or showback works, and what happens when two teams both classify their jobs as critical. Those are organizational rules as much as technical settings.
Start with one painful queue
A low-risk pilot should target a real bottleneck rather than the most impressive demo. Choose one queue where teams can agree on a baseline, workload ownership and success measures. Replay representative jobs, test failure and priority behavior, and compare results with the existing process. Expand only when the pilot shows a measurable benefit without introducing unacceptable delays or operator burden.
IBM’s announcement makes workload orchestration timely for infrastructure teams considering mixed AI and HPC estates. It does not settle whether this product, or any scheduler, will improve a particular organization’s economics. The useful question is narrower: can a policy-aware system allocate current capacity more predictably than the workflows and tools already in place—and can the team verify that on its own jobs? For related infrastructure tradeoffs, see our coverage of compiled-model serving and inference optimization claims.
Frequently asked questions
What did IBM announce about Spectrum Collective?
IBM announced general availability on November 12, 2026, describing Spectrum Collective as an enterprise workload orchestration platform for AI, HPC and analytics across heterogeneous infrastructure. Buyers should confirm current product documentation and availability for their environment.
Does a workload orchestration platform create more GPU capacity?
No. Orchestration can help allocate existing resources and coordinate queues, but it cannot create physical accelerator capacity. Teams should measure utilization, waiting time, throughput and service levels on representative workloads.
How should infrastructure teams evaluate a new scheduler?
Replay a representative workload mix, specify priority and fairness rules, measure queue time and utilization, test failures and quotas, and verify supported integrations, cost and operator responsibilities before migration.
Sources & further reading
Keep reading
Inkling 2 Small in Cortex: Test the Whole Fine-Tuning Job, Not the Parameter Count
Snowflake adds Thinking Machines Lab’s Inkling 2 Small to Cortex Training preview; workload, governance and serving costs still decide fit.
UK Backs Fractile in a £500 Million Bet on AI Chip Independence
The UK says public investment bodies back Fractile in a £500 million-plus round. Strategic intent is clear; commercial chip performance remains unproven.
Google’s TPU 8tx and 8i Max Target Two Different AI Infrastructure Bottlenecks
Google’s new TPUs focus on confidential inference and large contexts. Here is what the announcement means—and what buyers still need to measure.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.