
Google’s XLA Serving Engine moves compiled ML models into C++
Google open-sourced XSE for serving exported JAX and PyTorch models without a Python runtime. Here is what the handoff solves, and where it does not fit.
On this page
A model can be easy to prototype and awkward to operate. A Python service brings a large runtime, packaging work and another layer to keep patched. Google’s new XLA Serving Engine (XSE) aims to let teams export a trained JAX or PyTorch model and run its compiled computation in a C++ service.
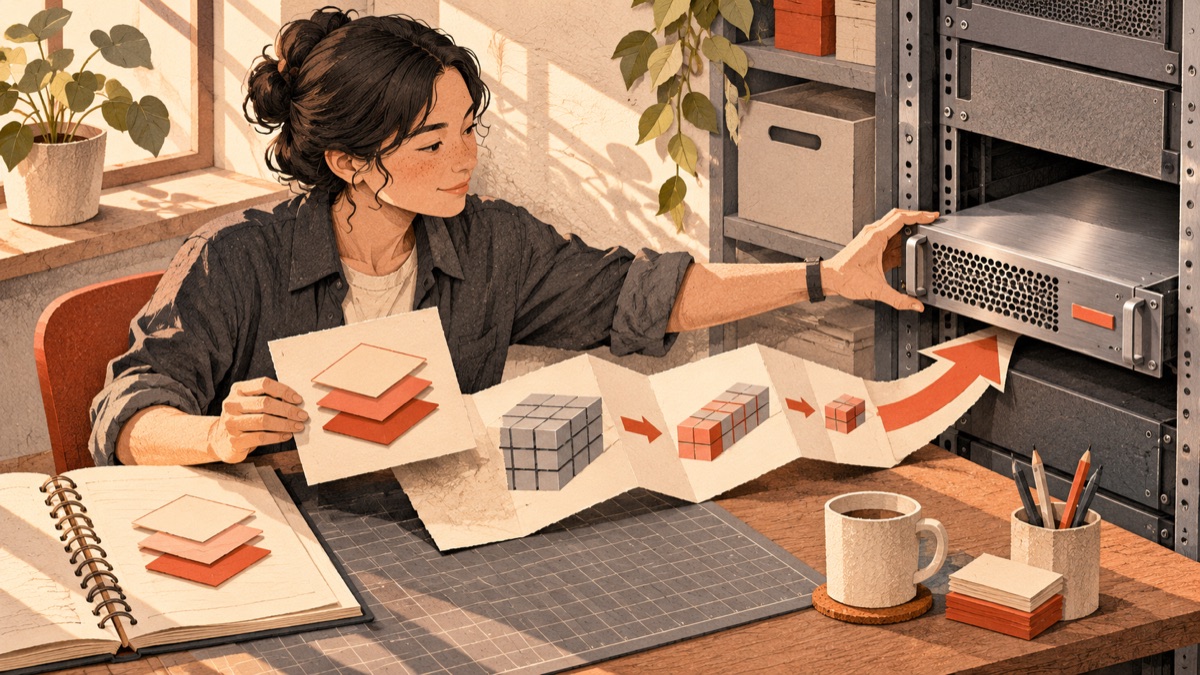
Google announced XSE on November 5 as an Apache 2.0 project in the OpenXLA ecosystem. The core idea is a boundary: keep model development in familiar Python frameworks, export a model to an XLA SavedModel containing StableHLO, then load that representation into the C++ runtime. “Train in Python, serve in C++” is a deployment option, not a claim that Python disappears from the whole machine-learning workflow.
The useful seam is between model and service
A common inference stack has at least three moving parts: model code, the runtime that executes it, and the application service that accepts requests. XSE focuses on making the model computation portable across that seam. StableHLO is an intermediate representation for high-level operations in machine-learning programs; it gives compilers and runtimes a shared form to consume.
That can be useful when a team wants a smaller production footprint, C++ integration, or a serving process that fits an existing native application. It also makes the export artifact a deliberate interface. Teams must still establish how model versions are tested, promoted, rolled back and matched to preprocessing code. The export step is a new release artifact to manage, not magic that removes operations.
Google reports internal throughput and resource gains compared with optimized Python servers, especially for short requests. Those are vendor measurements from Google’s own workloads. They should motivate a benchmark, not become a sizing promise: accelerator, model shape, batching, concurrency, request length and latency target all change the result.
It is not a universal LLM server
XSE is aimed at general-purpose XLA inference and lightweight, often one-shot model calls. Google explicitly points developers serving large autoregressive language models toward systems such as vLLM or SGLang. Token-by-token generation has different scheduling and memory behavior from a single forward pass. Treating both as the same serving problem invites a poor tool choice.
Before adopting it, test a representative export on the target hardware. Compare end-to-end latency, throughput at the service’s real concurrency, peak memory, cold start, and behavior when the model artifact changes. Include input preparation and response post-processing; a faster kernel can be hidden by a slower surrounding pipeline.
A practical adoption checklist
Start with a model whose deployment pain is concrete: Python packaging, native integration or resource limits. Confirm that its framework operations export to the required XLA representation. Pin the framework, compiler and runtime versions together, and keep the exported artifact reproducible. Then test numerical parity against the current service with production-like inputs, including edge cases and empty or unusually long requests.
Finally, compare the full operating cost. A C++ runtime may reduce one dependency surface while increasing the need for compiler expertise and artifact discipline. If your service already performs well and Python is not a deployment constraint, migration may add work without meaningful benefit.
XSE makes a promising path more explicit: experiment in the framework your team knows, then ship a compiled model through a native serving layer. Its value depends on matching that path to the workload and measuring the whole request—not on the language printed on the runtime. For another view of deployment tradeoffs around model packaging and runtime constraints, see our coverage of open-weight model deployment and measuring accelerator behavior carefully.
Sources & further reading
Keep reading
IBM's Quantum System Two Is Now in Chicago. The Hard Part Is Building Around It
IBM has installed a Quantum System Two at the University of Chicago. Its research value depends on algorithms, access, and links to classical computing.
Wolfpine Makes Tenstorrent Kernels Easier to Inspect. It Does Not Predict Their Speed
Wolfpine is a community Python simulator for Tensix accelerators that can run tt-metal programs and expose traces, with an explicit limit on timing accuracy.
Marvell’s Lumentum Deal Targets the Optical Links Inside AI Data Centers
The proposed $115 billion all-stock deal combines Marvell’s connectivity chips with Lumentum’s lasers and optics. Approval and integration remain years away.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.