
Google’s TPU 8tx and 8i Max Target Two Different AI Infrastructure Bottlenecks
Google’s new TPUs focus on confidential inference and large contexts. Here is what the announcement means—and what buyers still need to measure.
On this page
An infrastructure team can have two AI workloads that look similar in a diagram and behave very differently in production. One cannot let sensitive data or model weights appear in plaintext while inference is running. The other spends so much time moving a long conversation history through memory that adding arithmetic capacity barely helps. Google’s new TPU 8tx and TPU 8i Max are designed around those separate constraints.
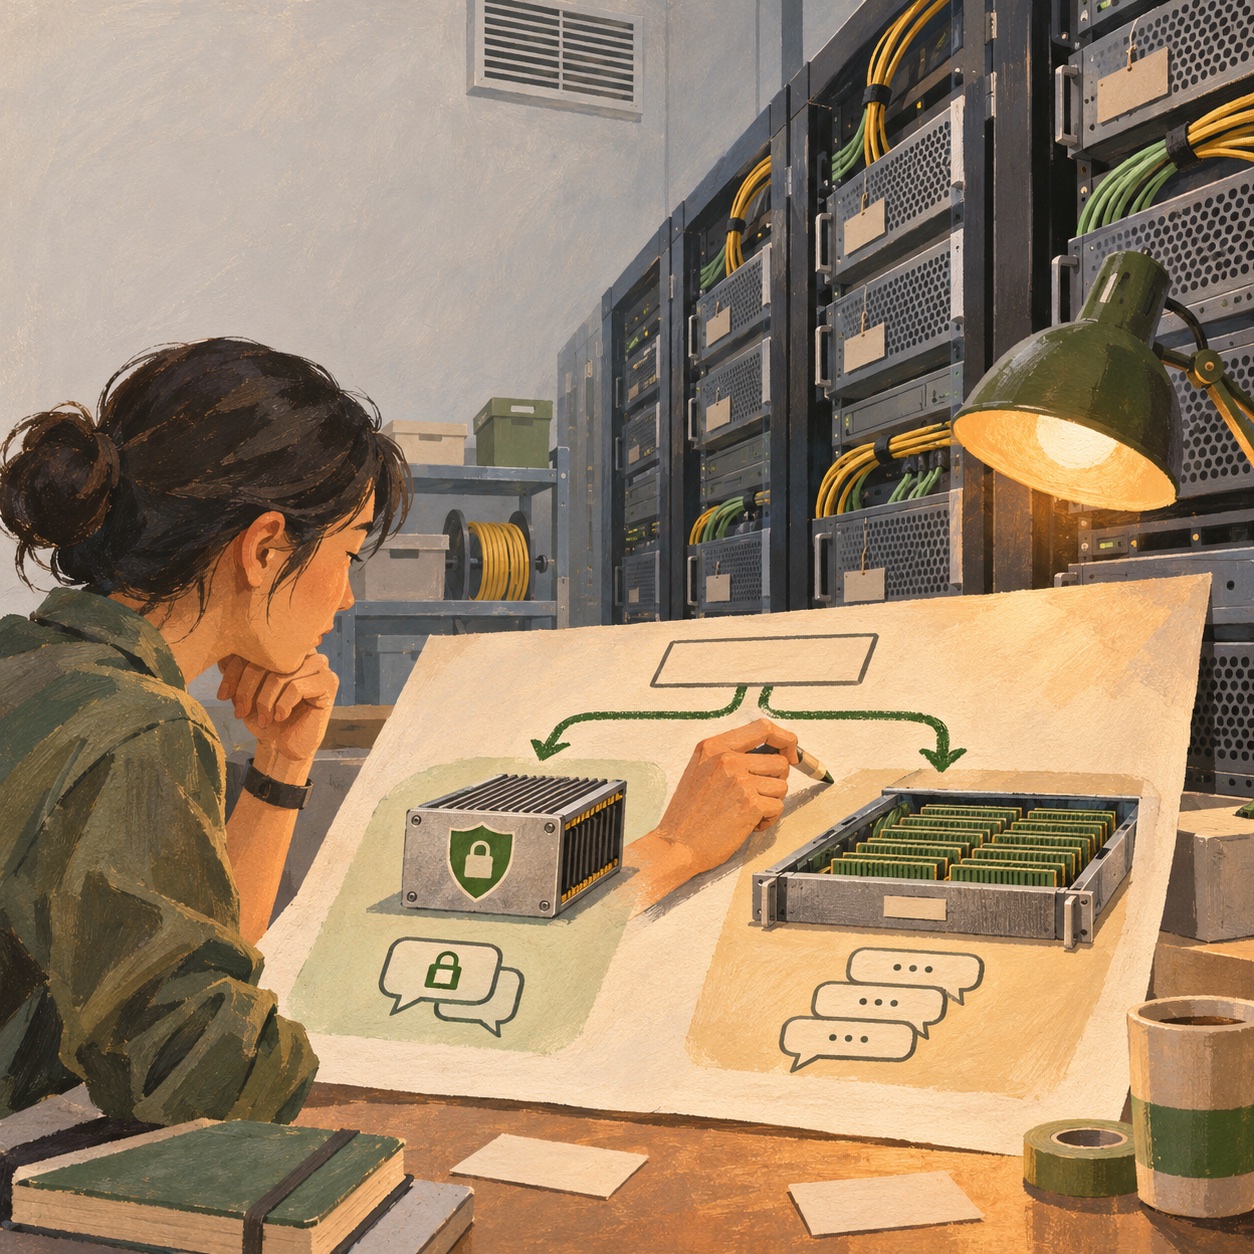
Google announced the two systems on November 9, extending a TPU generation that already included TPU 8t for training and TPU 8i for real-time reasoning. In the company’s framing, 8tx is for confidential inference and 8i Max is for large context windows and high compute density per rack. This makes the portfolio announcement more meaningful than a simple “new chip is faster” claim: it is a statement that accelerator procurement is becoming workload-specific. [1]
One label, two system problems
TPU 8tx targets confidential computing. Ordinarily, encryption protects data in storage and while travelling over a network, but a processor must access usable data while performing a calculation. Google says 8tx adds hardware-level protections for sensitive data and model weights during active use, using the same base silicon as TPU 8t with AMD EPYC hosts. It also claims up to two times lower latency than TPU 8t for multi-step agents, with a near-zero performance penalty. These are the vendor’s specifications and comparisons; the announcement is not an independent audit of the threat model, isolation properties or performance. [1]
For a buyer, “confidential” is not a complete security requirement. Ask which parts of a workload are protected, who controls the keys, what administrative access remains, how the system is attested, and whether logs, caches and tool calls fall inside the same boundary. A model running in protected memory can still be exposed by a compromised application, an over-permissive service account or a careless data export. Hardware isolation is one layer in a system design, not a shortcut around one.
TPU 8i Max addresses memory pressure. Long-context models can require large key-value caches: intermediate information retained so a model can continue attending to earlier parts of a conversation. The memory footprint grows with context and concurrent sessions. Google positions 8i Max around massive context windows and more compute per rack, where memory capacity and the way it is attached can matter as much as peak arithmetic. The company describes this as a system architecture choice for agentic workloads, not simply a higher clock rate. [1]
Google introduced TPU 8t and 8i in April, describing 8t as the training-focused system and 8i as optimized for low-latency reasoning. Its announcement then cited up to 2.7 times better training performance and 80 percent better inference price performance than the prior generation. Those figures have a defined vendor comparison, but they do not predict what a particular organization will pay or achieve. [2]
Why a portfolio can beat a single “best” accelerator
A fleet that runs training, live inference, confidential workloads and long-context agents does not have one universal bottleneck. Training may be limited by how quickly a large model can be distributed across chips. A real-time assistant may be constrained by the delay before a first useful token. An agent waiting on a database query may leave expensive compute idle. A regulated workload may require a different trust boundary from a public chatbot.
That is why buyers should compare complete systems rather than one peak-throughput number. The relevant unit is a model serving a real request under a particular batch size, context length, concurrency, latency objective and security configuration. Measure successful output per unit cost and energy, not just raw tokens per second. Track tail latency and utilization when tool calls leave the accelerator waiting. Confirm that the software framework, inference engine and model kernels you actually use are supported. Google’s TPU documentation describes its supported access paths and developer guides, but teams should verify the specific generation and service region they can obtain. [3]
There is also a portability decision. If adopting a specialized accelerator requires rewriting kernels, retraining operators or accepting a single provider’s runtime, the migration has an ongoing cost. A strong headline benchmark does not include that engineering work. The April Google announcement said the company was working to open TPU development to more PyTorch users; the practical question is how much of a team’s real stack runs without custom work today. [2]
A buyer’s short evaluation plan
Start by sorting workloads into constraints: confidentiality, first-token latency, sustained throughput, long-context memory, training throughput or power limits. Keep the categories separate. Then identify a representative model and replay a production-shaped request set. Include long prompts, concurrent sessions, tool waits and the actual quality checks your product needs.
For a confidential workload, test the end-to-end trust chain and inspect the provider’s evidence. For a context-heavy agent, track cache memory, the number of concurrent sessions that fit, and the quality and cost of context retrieval. For both, compare against the current serving system and include software migration and operational support in total cost.
Google’s announcement shows how accelerator families are increasingly organized around the job a system must do. That is useful direction for the market. The decision for a buyer still comes from workload evidence: can the system deliver acceptable quality, latency, security and cost for the tasks that matter? Until those measures are available, “built for agentic AI” is positioning, not a procurement result.
Related reading
Frequently asked questions
What is the difference between TPU 8tx and TPU 8i Max?
Google positions TPU 8tx for confidential inference, where data and model weights need protection while in use. TPU 8i Max is aimed at workloads with very large model contexts and high compute density per rack. They address different system constraints.
Are the new TPU performance claims independently verified?
The November announcement describes Google's own systems and selected benchmark results. Buyers should treat those as vendor claims until they can reproduce relevant workloads, model quality, throughput and cost under their own deployment conditions.
Can a team order TPU 8tx or TPU 8i Max today?
The announcement describes the systems and their goals but does not provide a universal purchase date or price. Availability depends on Google's service and customer arrangements; verify the current product documentation and regional access before planning a migration.
Sources & further reading
Keep reading
A Photonic AI Processor Is Moving Into a Server Pilot. What Will It Prove?
Q.ANT and IONOS will let selected developers run workloads on a photonic processor. The test is where a hybrid optical accelerator actually helps.
Google’s XLA Serving Engine moves compiled ML models into C++
Google open-sourced XSE for serving exported JAX and PyTorch models without a Python runtime. Here is what the handoff solves, and where it does not fit.
IBM's Quantum System Two Is Now in Chicago. The Hard Part Is Building Around It
IBM has installed a Quantum System Two at the University of Chicago. Its research value depends on algorithms, access, and links to classical computing.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.