
NVIDIA Dory Makes Inference Compute a Knob. What Does That Buy?
NVIDIA Dory 1.0 reuses transformer layers at inference. Its adjustable loop count trades more computation for task performance, not free capability.
On this page
Most model comparisons treat a checkpoint as a fixed object: load its weights, send a prompt, measure the answer. NVIDIA’s Dory 1.0 asks a different operational question: what if the same shared layers could be run again, and the operator chose how much additional computation to spend? The idea is compact, but the tradeoff is familiar. More work at inference can improve some outputs while making each response slower and more expensive.
What NVIDIA published
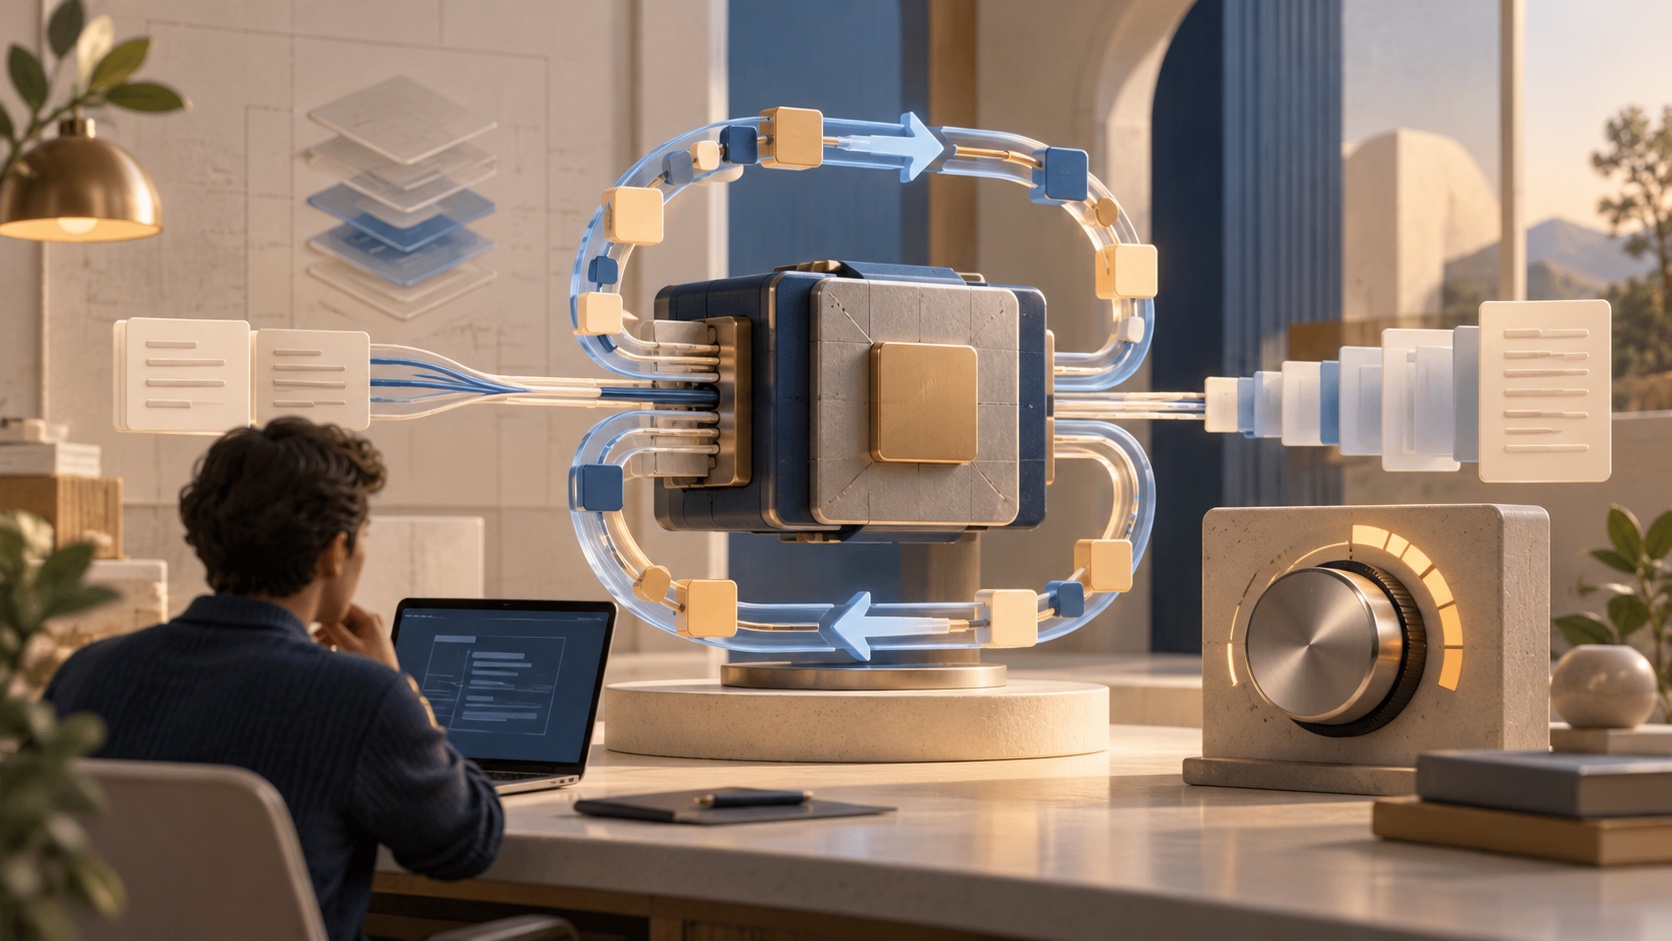
NVIDIA describes Dory as a 4-billion-parameter, looped latent-recurrent model. Its architecture places input and output stacks around a group of shared recurrent layers; the shared block can be revisited one, two, or four times. The model card says the loop count can be selected at inference, making it possible to trade additional recurrent computation against measured task performance without loading a separately trained parameter set for each setting. [1]
That distinction matters. “Four loops” does not mean four independent copies of the recurrent block were added to the checkpoint. It means the same weights are applied repeatedly. Parameter count describes stored learned weights; it does not by itself describe operations per token, wall-clock latency, memory behavior, or energy use.
Why repeat layers at all?
A conventional transformer increases capacity largely by adding layers and parameters. A recurrent or looped design reuses some parameters across multiple steps. In principle, that can separate the amount of learned weight storage from the amount of computation performed on a particular input. It also creates a control that conventional fixed-depth models do not expose in the same way: spend more sequential compute when a task may benefit, and less when it does not.
Recent research explores related designs, but those papers should not be mistaken for an independent replication of Dory. T-LoopFormer studies training and scaling looped transformers, while another preprint examines shared memory in looped models. Together, they show that recurrence is an active research direction; they do not establish that any one looped model will outperform a well-matched dense model at a given serving budget. [2] [3]
The benchmark caveat is the product story
NVIDIA’s model card reports scores from its own harness at different loop counts and cautions that results may vary with prompts and evaluation settings. Those measurements are a starting point for testing, not a neutral verdict. A team considering Dory should reproduce the comparison on its own tasks, with a fixed prompt set, identical decoding settings, and the same latency or cost budget.
NVIDIA’s own table puts a concrete number beside that question: its SWE-bench Verified score rises from 50.3 at one loop to 61.8 at four. That is a vendor-reported result measured with its stated harness, not an independent replication. The model card recommends starting at two loops, says most of the gain arrives on the second pass, and advises teams to measure full latency and cost because added loops can also reduce output tokens. [1] The key comparison is not simply “more loops versus fewer loops.” It is “what quality change do extra loops buy per unit of added delay and compute?” If the additional pass helps hard reasoning cases but adds little to routine extraction, an adaptive policy might make sense. If it raises latency without consistent task gains, the knob is operational complexity without value.
What teams should measure before adopting it
A useful evaluation would report task accuracy and failure modes alongside time-to-first-token, total response latency, tokens per second, accelerator utilization, and cost per successful task. It should separate easy and difficult prompts, include repeated runs where outputs vary, and compare against models with similar serving cost. Parameter count alone is not a fair efficiency metric for a recurrent model.
There are also deployment questions. Sequential recurrence can create latency that batching does not hide for an individual request. Memory and caching behavior should be measured from the implementation rather than inferred from the diagram or model-card headline. Licensing should be checked too: the card identifies OpenMDW-1.1, so teams need to read the license terms for their intended redistribution and commercial use. [1]
Dory’s most interesting promise is therefore not that a 4B model has somehow escaped compute limits. It is that inference effort might become an explicit resource-allocation decision. The product case depends on whether that decision can be made reliably, whether the quality gains transfer to real workloads, and whether operators can observe the cost. For more on benchmark design, see our coverage of why model benchmarks can mislead and test-time compute scaling.
Frequently asked questions
What is NVIDIA Dory 1.0?
Dory 1.0 is a 4-billion-parameter language model built around recurrent computation: it reuses a shared set of transformer layers multiple times between input and output stacks. NVIDIA's model card describes a configurable number of loops at inference.
Does increasing Dory's loop count make it a larger model?
The published parameter count remains 4 billion because the recurrent layers are shared. More loops mean more sequential computation per inference, so parameter count alone does not describe the full runtime cost or latency.
Are the model card's benchmark numbers independent results?
No. The model card reports NVIDIA's own evaluation harness and warns that results can vary with prompts and settings. They are useful as vendor-reported measurements, not an independent comparison or guarantee for a particular workload.
Sources & further reading
Keep reading
Google Workspace MCP Clients Face a November Agent-Use Gate
Google will require an agent-use OAuth client marker for Workspace MCP beginning November 11. Ordinary Workspace REST API integrations are unaffected.
Organoids Classified Braille Patterns in a Small Experiment. They Did Not Learn to Read
A Bristol team encoded Braille patterns into stimulation for brain organoids. Its classifier result shows no learning or language comprehension.
Meta’s New Feed Controls Make a Promise. The Ranking System Still Decides.
Facebook’s natural-language feed controls make preference editing easier, but the platform still translates each request into ranking signals.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.