
On this page
A persistent agent can spend most of its input budget repeating the same operating manual: developer instructions, tool schemas and reference material. OpenAI’s new 12-hour prompt-cache option is aimed at that pattern. The useful question is not whether a longer cache sounds cheaper; it is whether the repeated reads repay the more expensive write for the exact prefix your application sends.
What changed on October 20
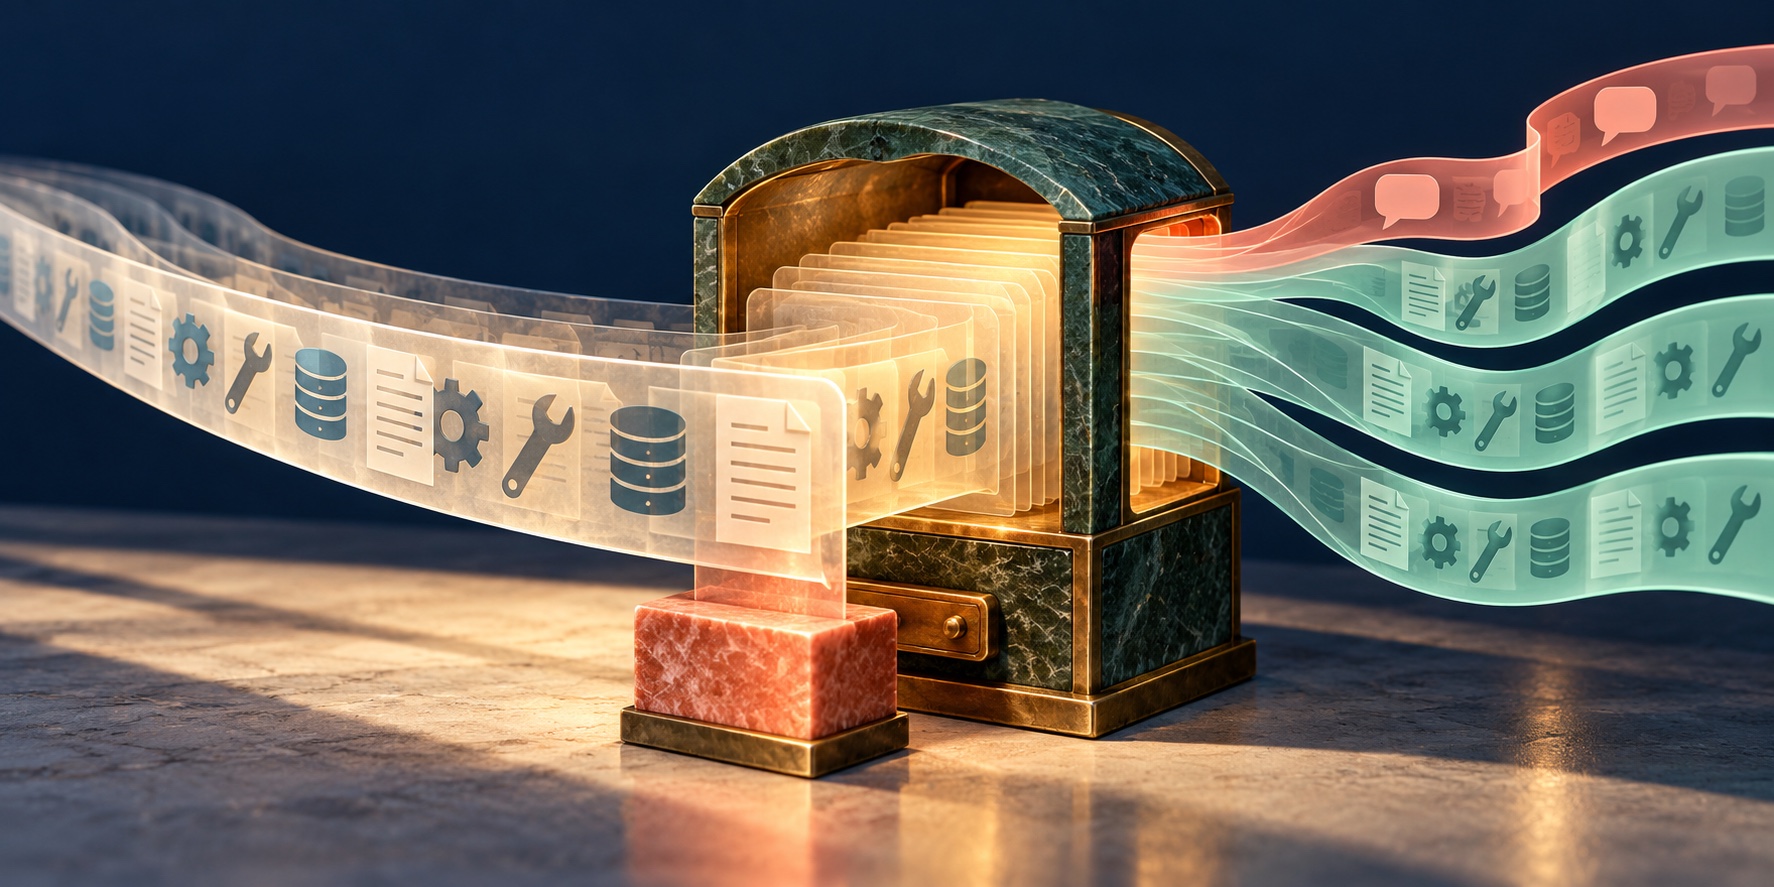
OpenAI’s API changelog says developers can now choose 12-hour prompt caching in the Responses API. The option extends the existing 30-minute default for eligible requests; it is not simply a promise that every prompt will remain resident for twelve hours. The current guide describes the value as a minimum cache lifetime and warns that cache eligibility does not guarantee reuse of stored key-value tensors or lower latency. A read inside the ordinary 30-minute window extends that short window, but it does not restart the 12-hour clock on a long-lived entry. [1] [2]
The guide scopes the setting to supported models and the Responses API. For GPT-5.6 and later, developers set prompt_cache_options.ttl to "30m" or "12h". Earlier model families use different retention controls, so copying the new field into another endpoint or model family is not a safe assumption. Check the current support table for the model and API path you actually run. [2]
Why the longer window costs more
OpenAI prices a 12-hour cache write at 2.5 times the ordinary input-token rate. The default 30-minute cache write is 1.25 times. Later cache reads are billed at a much lower cached-input rate—typically one tenth of ordinary input on the covered models, with a lower rate listed for GPT-6.1 Sol. The longer window therefore charges more up front to keep a prefix eligible across longer quiet periods. [2]
A simple break-even illustration makes the decision concrete. Suppose a stable prefix costs 1 unit to send as ordinary input, a 12-hour cache write costs 2.5 units, and each cache read costs 0.1 units. The write’s premium is 1.5 units above ordinary input; each later cached read saves about 0.9 units. Two reads after the write can recover that premium under these simplified assumptions. Real requests can differ because only eligible prefixes are cached, model prices vary, and not every request will hit the cache. Treat the arithmetic as a screening test, then use returned usage fields to calculate actual spend. [2]
The design is useful for a long-running research or coding agent that returns to the same tool definitions and reference set several hours later. It is less compelling for one-shot prompts, rapidly changing system instructions, or workloads whose next call arrives inside the existing 30-minute window anyway. A longer TTL cannot make changing content reusable: the prefix must still match at an eligible boundary.
Keep the reusable prefix stable
Prompt caching rewards consistency in the beginning of a request. Put durable instructions, tool definitions and reference material before changing user turns. Avoid adding a timestamp, random request identifier or per-user text near the front if it changes the prefix every time. A stable prompt_cache_key can help route requests with the same workload together, but it does not make different prompts identical. OpenAI’s earlier caching guide explains the general prefix-matching behavior, while the current API guide documents explicit breakpoints and retention controls. [2] [3]
For a multi-stage agent, do not automatically give every token the longest lifetime. The API supports separate breakpoints and lifetimes in a request. A durable policy and tool catalog can use the longer window, while a more transient section can use 30 minutes. The later 12-hour breakpoint covers the prefix before it, so placement and ordering affect what gets written and for how long. [2]
A practical rollout starts with a representative request trace. Record the stable prefix size, call spacing, cache reads, cache writes, ordinary input tokens, total input cost and end-to-end latency. Compare the existing 30-minute setting with 12 hours over a workload that includes realistic idle gaps. If cache reads do not increase or the more expensive writes dominate, revert that path to the default. For a long-context application, this analysis belongs beside the existing work on cache write strategies and eviction policies and KV-cache transfer between inference workers.
A cost control, not a latency guarantee
The feature matters because agents can leave a shared prefix untouched for hours and then resume. A longer eligibility window may lower the repeated-input bill for that pattern. It does not turn a cache into durable application state, guarantee a cache hit, or eliminate the work of composing the prompt. Keep the source instructions in your own versioned system, and treat cache telemetry as an optimization signal rather than the source of truth.
The sensible adoption rule is narrow: test the 12-hour option where a large, stable prefix reappears after long gaps, measure the write premium against observed reads, and keep shorter-lived or changing context on the default path. The new control gives developers another lifetime to tune; the workload still decides whether it pays.
Frequently asked questions
Does 12-hour prompt caching guarantee a cache hit for twelve hours?
No. OpenAI describes a 12-hour minimum cache lifetime for supported Responses API models. The documentation says this controls eligibility for cache-read pricing and does not guarantee every request reuses stored tensors or has lower latency.
When is the 12-hour cache likely to be worthwhile?
It is most promising when a long, stable prefix is reused after gaps longer than the default 30-minute lifetime. Compare the more expensive cache write with observed cache reads, total input cost and latency before enabling it broadly.
Sources & further reading
Keep reading
OpenAI’s Orchestra Bio Deal Targets the Work Between a Discovery and a Trial
OpenAI is bringing Orchestra Bio into Rosalind. The acquisition targets drug-program coordination, while clinical outcomes remain unproven.
Amazon ECS Gateway Shares Ingress Plumbing, but Teams Still Own the Boundaries
AWS adds a shared ingress resource for ECS. See how connectors, ALB capacity, IAM and subnet compatibility shape adoption.
GitHub’s Package Firewall Can Block a Bad npm Install—If You Route Through It
GitHub’s preview adds package-age and malware controls for npm installs. Learn the Enterprise Cloud limits and rollout path.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.