
Why LLM Serving Teams Are Turning KV Cache Transfer Into a First-Class Design Choice
Two new vLLM transfer techniques target first-token latency by overlapping movement and reusing multi-turn context. See where each helps and what it costs.
On this page
A long prompt can take time to process before a model emits its first token. Splitting prompt processing (prefill) and token generation (decode) across different machines can let each scale independently, but the split creates a new step: the key-value cache produced by prefill must reach decode. The transfer is now part of latency. Two vLLM techniques described by AWS on October 19 attack different parts of that cost: push-based transfer overlaps coordination, while bi-directional transfer reuses context across turns.
One cache, two different bottlenecks
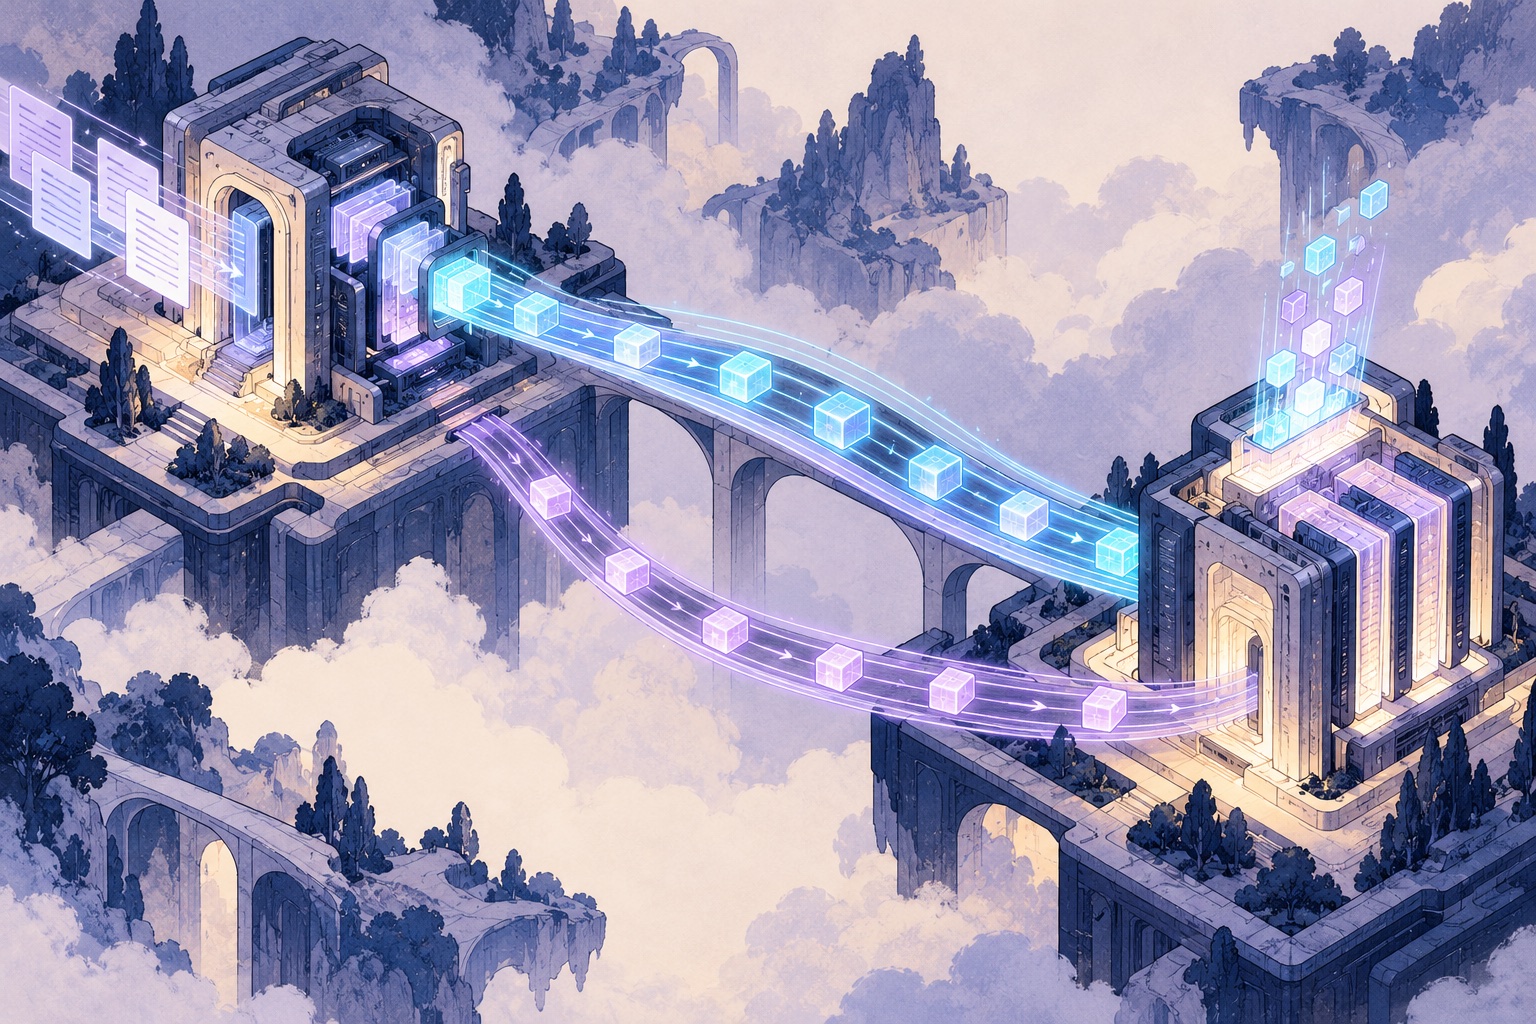
In a conventional pull flow, the router tells the decode worker which KV blocks the prefill worker created; decode allocates destination blocks and asks for the data. These sequential steps sit between prompt processing and generation. Push mode registers destination blocks earlier and begins movement as producer blocks become ready, moving setup work off the critical path. AWS reports up to 3× better time to first token and up to 30% better time per output token for Qwen3-32B on its one-prefill/one-decode P5en and EFA benchmark. The post says results depend on workload and configuration. [1]
That is a first-request optimization. Multi-turn agent workloads create a different waste: each new request includes prior conversation, but the next prefill worker may not have the corresponding cache locally. The decode worker that generated the previous answer may still have it. Bi-directional transfer lets eligible KV blocks travel back to prefill for reuse, coordinated by a cache-aware router and controlled by retention and recompute thresholds. [2]
Reuse trades recomputation for movement and coordination
The basic economic question is whether moving cached state costs less than recomputing it. In AWS’s reported multi-turn tests, bi-directional transfer reduced time to first token by up to 1.6× for Qwen3-32B and 3.3× for GLM-5-FP8 at the longest tested prompts. The transfer itself added tens to more than a hundred milliseconds, but the saved prefill computation was larger in those tested cases. The authors disabled prefix caching on the prefill node to model cache-miss scenarios. This is evidence for that configuration, not proof that every production cache miss should cross a network. [2]
vLLM’s documentation describes disaggregated prefilling as an experimental feature and points out that separating the phases can improve control over their resource allocation while introducing communication overhead. NIXL is one connector path for transferring KV blocks, with requirements around compatible hardware and transport. The architecture is useful only when the workload is constrained by the bottleneck it addresses. [3] [4]
Push mode and reverse-direction reuse are also orthogonal. Push mode reduces transfer setup on the first prefill-to-decode handoff. Bi-directional reuse can avoid repeating earlier context on a later turn. A system may need one, both or neither. If a model is small, prompts are short, request volume is modest or network overhead is high, a simpler colocated serving setup can perform better in cost, reliability and operational burden.
What to measure before adopting either feature
Start with a trace that separates queue time, prefill, cache-transfer setup, transfer duration, decode and inter-token gaps. Record prompt length, output length, cache hit rate, request concurrency and route changes. A single aggregate latency percentile cannot show whether you are paying for repeated prefill or serialized transfer coordination.
Then replay representative sessions with the same model, prompt distribution and network topology. Compare TTFT and time per output token, but also measure throughput, accelerator utilization, cache evictions, transfer bytes, tail latency and cost per completed request. Include warm and cold cache paths and multi-turn conversations that move between prefill workers. Keep a recompute threshold: transferring a small prefix may cost more than calculating it again.
Operationally, cache state becomes distributed state. Routing must know where reusable blocks reside; retention consumes memory; retries must handle workers disappearing mid-transfer; and observability must distinguish a cache miss from a slow transfer. Teams should test these failure cases before tuning for a headline benchmark.
The design lesson
The KV cache is no longer just a local performance detail once inference is split across nodes. It becomes a placement and network protocol decision. Push transfer changes when bytes move; bidirectional reuse changes which worker retains state between turns. Measure those costs against the compute they remove, and keep the deployment simple until the evidence says the extra machinery is paying for itself.
For adjacent systems context, read our explainers on speculative decoding and the GPU software stack behind vLLM.
Frequently asked questions
What is KV cache in LLM inference?
The key-value cache stores attention state computed for tokens already processed. Reusing it can avoid repeating prompt work, while moving it between serving nodes adds network and coordination costs.
Are the reported vLLM speedups guaranteed in production?
No. AWS reports benchmark results on specific one-prefill/one-decode EC2 P5en deployments with EFA. Hardware, model, context length, request rate, routing and cache behavior can change the result.
When should a team consider these approaches?
First measure whether transfer coordination or repeated prompt prefill is a real bottleneck. These techniques target disaggregated deployments with suitable networking and cache-aware routing, which may be more complex than a single-node setup.
Sources & further reading
Keep reading
Deepgram's Trainium Port Shows Why Inference Cost Depends on the Whole Stack
Deepgram and AWS report 11–70% more offline transcription per dollar on one Trainium2 setup. The kernels, runtime and workload explain the narrow result.
Claude Structured Outputs on Bedrock Can Enforce Shape, Not Business Truth
Bedrock adds schema-constrained Claude output, but route and model support vary and valid JSON still needs domain validation.
GitHub’s SSH Brownout Starts Nov. 4: Check the Client Before Replacing Keys
GitHub is phasing out older SSH signatures and key exchange; distinguish RSA key files from the SHA-1 signature algorithm before changing access.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.