
OpenAI's Security Sprint Is a Process Bet: Find, Reproduce, Patch, Review
OpenAI plans a model-assisted security sprint with outside researchers. The test is whether findings become verified fixes.
On this page
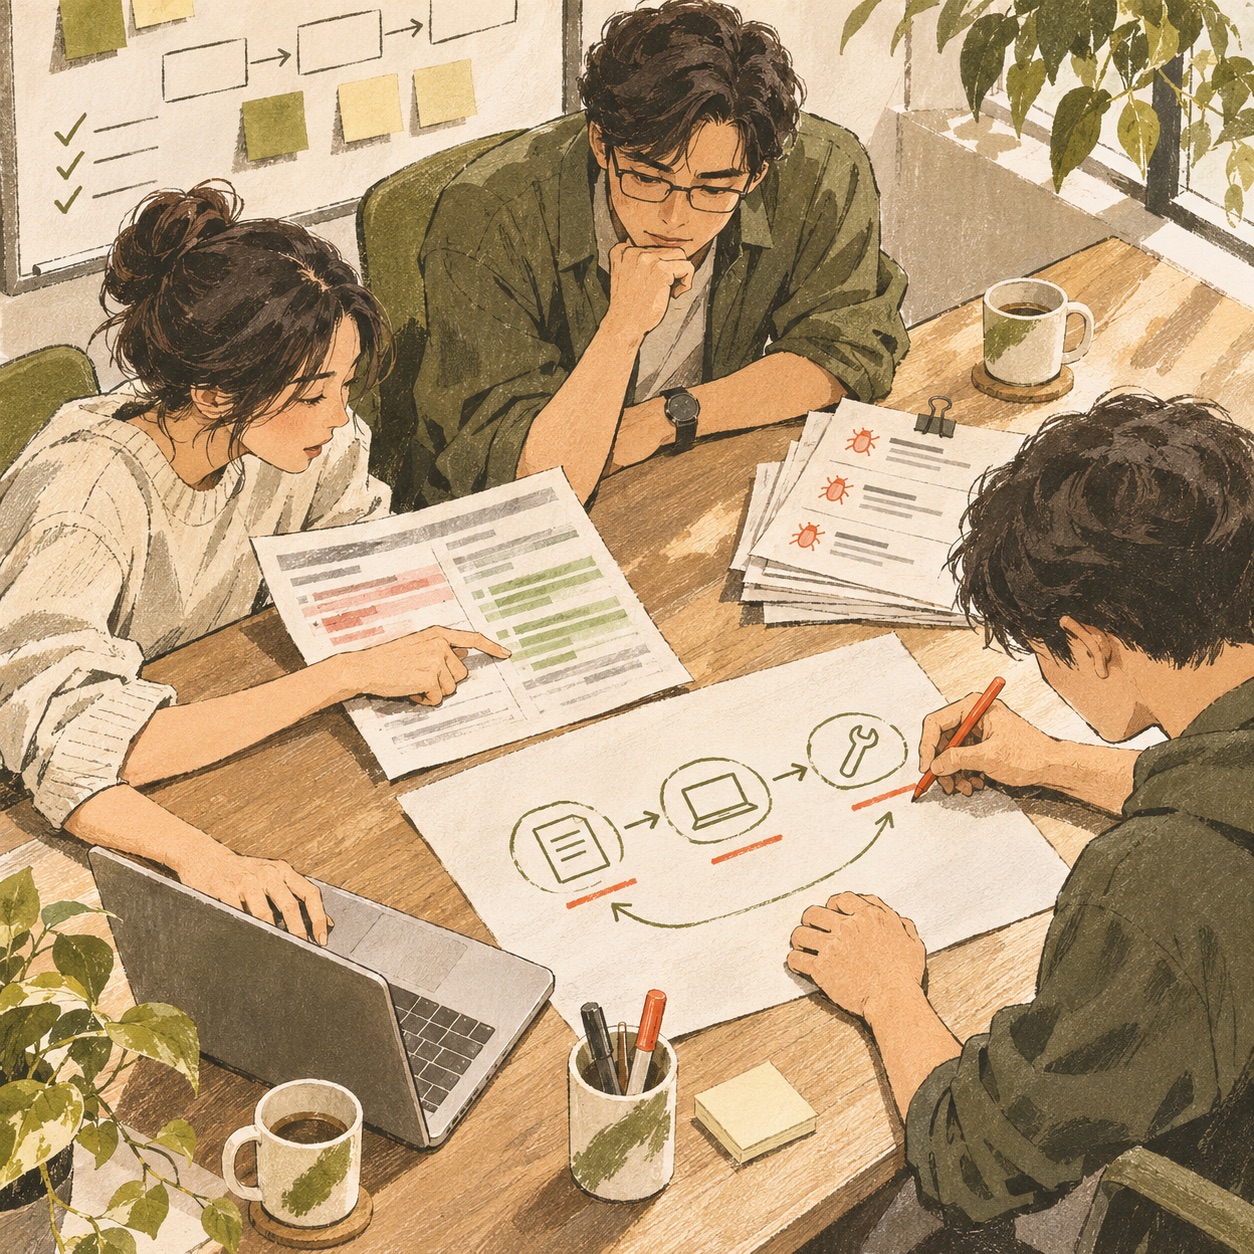
A model that can suggest a bug is only one step in a security program. The harder sequence is to confirm the issue safely, understand its impact, write a correct patch, review the change and make sure the fix does not break something else. OpenAI’s November 2 announcement is notable less as a claim that AI can secure software by itself than as a plan to put model-assisted research inside that full loop—with internal engineers, an outside security partner and a bug-bounty program. [1]
The announcement describes a planned operation
OpenAI says Cathedral researchers will work alongside its teams and use OpenAI models to challenge defenses. It also says critical bug-bounty rewards are being increased by more than four times. The post describes these as upcoming work and program changes; it does not publish the new sprint’s results, a denominator of tested systems or a breakdown of vulnerabilities found. Those limits matter: a plan is not evidence that the process has already improved security. [1] [3]
For the previous sprint, OpenAI says it dedicated 25% of product engineers to finding and fixing weaknesses. Engineers used Codex to investigate findings, reproduce vulnerabilities in isolated environments and prepare patches for review. The significant phrase is “reproduce vulnerabilities.” A language model can identify suspicious code or propose a test, but an organization needs evidence that a report corresponds to a real security property violation in the system it runs. [1]
That approach follows a familiar secure-development idea: discovery and remediation are connected activities. External researchers offer different eyes, while product engineers understand how a component is actually deployed. Neither perspective alone guarantees a fix. A report must be scoped, validated, assigned and retested; a model suggestion must be treated as a lead until those steps supply evidence. [2]
Why vulnerability counts can mislead
Suppose an agent produces 100 possible findings. If most are duplicates, out of scope or impossible to reproduce, a security team may spend more time triaging than fixing. Conversely, a small number of hard-to-find critical issues may matter greatly. Counts can reward volume while hiding the operational costs of false positives, severity inflation and patch regressions.
A meaningful scorecard should follow a finding from discovery through closure: percentage reproducible in an isolated environment; duplicate and false-positive rates; severity confirmed by a human reviewer; time to a safe fix; regression-test outcomes; and whether the correction closes the underlying weakness rather than only the reported input. Report scope and exclusions alongside the numbers.
The same caution applies to model-assisted coding. A generated patch can appear plausible yet alter authorization checks, error handling or assumptions elsewhere. Restrict agent permissions, avoid exposing production data, use disposable test environments and require a maintainer to approve code. The OWASP GenAI Security project offers broader application-security material for systems that combine models, data and tools, but it does not replace the organization’s own threat model. [4]
A repeatable sprint for teams without a frontier lab
Choose a bounded service or repository and define in-scope assets. Give researchers and tools safe test environments that match relevant production behavior but contain no live customer data. Establish an intake template that captures reproduction steps, impact, affected versions and evidence. Make ownership and response timelines explicit before the sprint starts.
Let AI assist with code navigation, test generation and hypothesis formation. Keep the model away from autonomous production changes. Every finding should have a human reproducer, an owner, a patch review and a regression check. Track both time saved and new triage work. If the sprint finds a weakness in the model integration itself—such as an overpowered tool or unsafe data flow—record that as a system design issue, not merely a prompt problem.
Finally, publish a post-sprint summary that separates confirmed findings from suggestions, explains what was fixed, and describes open risks without exposing exploit details unnecessarily. That gives leadership a useful outcome and researchers a clearer signal that responsible reporting leads to action.
An additional safeguard is to prevent the sprint from becoming a one-time campaign whose fixes quietly decay. Tie each finding to a regression test or monitoring rule where possible, and schedule a later check against the repaired behavior. Record whether the same class of issue appears elsewhere in the codebase. If a vulnerability was enabled by a broad tool permission, fix the permission boundary, not only the individual route that exposed it. A postmortem should also say which findings could not be tested and why; silence can make coverage look stronger than it was.
Teams building tool-using systems can compare this approach with our coverage of least-privilege boundaries for browser agents and security risks in GitHub agent workflows. Both reinforce a practical point: an AI-assisted security process must test the surrounding permissions and automation, not merely the model’s answer.
The proof arrives after the press release
OpenAI’s plan to combine internal engineering, outside researchers, model assistance and bounty incentives is a coherent security process. The company’s published account of the previous sprint contains operational details, but the next sprint’s impact remains unreported. The evidence to watch is whether findings are reproducible, fixes are durable and the work shortens exposure windows.
For other teams, the transferable lesson is to design the feedback loop before adding an AI vulnerability finder. Discovery is valuable only when the organization can validate, prioritize and repair what it uncovers.
Frequently asked questions
Has OpenAI completed the announced security sprint?
The November 2 post describes a planned sprint with Cathedral and OpenAI teams. It does not report the sprint's eventual findings or a completed security outcome.
What did OpenAI say happened in its previous sprint?
OpenAI says it assigned 25 percent of product engineers to finding and fixing weaknesses, using Codex to investigate findings, reproduce vulnerabilities in isolated environments and prepare patches for review. These are company-reported process details.
How should a company evaluate AI-assisted vulnerability discovery?
Track reproducible, in-scope findings that lead to reviewed fixes, including false-positive and duplicate rates, exploitability, time to remediation and regression results. Keep model-generated suggestions subject to the normal security review process.
Sources & further reading
Keep reading
Adobe and Disney's AI Deal Starts in the Design Room, Not on the Screen
Adobe and Disney plan custom Firefly models for concept exploration and park design. The alliance still needs workflow proof.
PagerDuty’s SRE Agent Benchmark Shows Why Incident Context Matters
PagerDuty’s 17-scenario SRE benchmark offers useful signals and clear limits: one trial, simulated faults, no live transcripts, little remediation testing.
Google Pay’s India Shopping Pilot Adds a New Job to a Payments App
Google is testing a personalized fashion feed, visual search and virtual try-on in Google Pay India. The pilot sends purchases to merchant sites.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.