
topic: artificial-intelligence
author: Crashtech Editorial
published: Nov 18, 2026 · read: 4 min
---
OpenAI's Longer Background Windows Trade Faster Results for Cheaper Queue Time
OpenAI adds discounted background windows to the Responses API, with shared queue limits and temporary data storage.
On this page
A batch of overnight document reviews does not need the same response path as an interactive chat. OpenAI’s November 17 API changelog adds two-hour and eight-hour completion windows for eligible Responses API models, with stated model-token discounts relative to Standard processing. The feature is in public beta. It is designed for work that can wait, not for lowering the cost of a request while still expecting an immediate answer. [1]
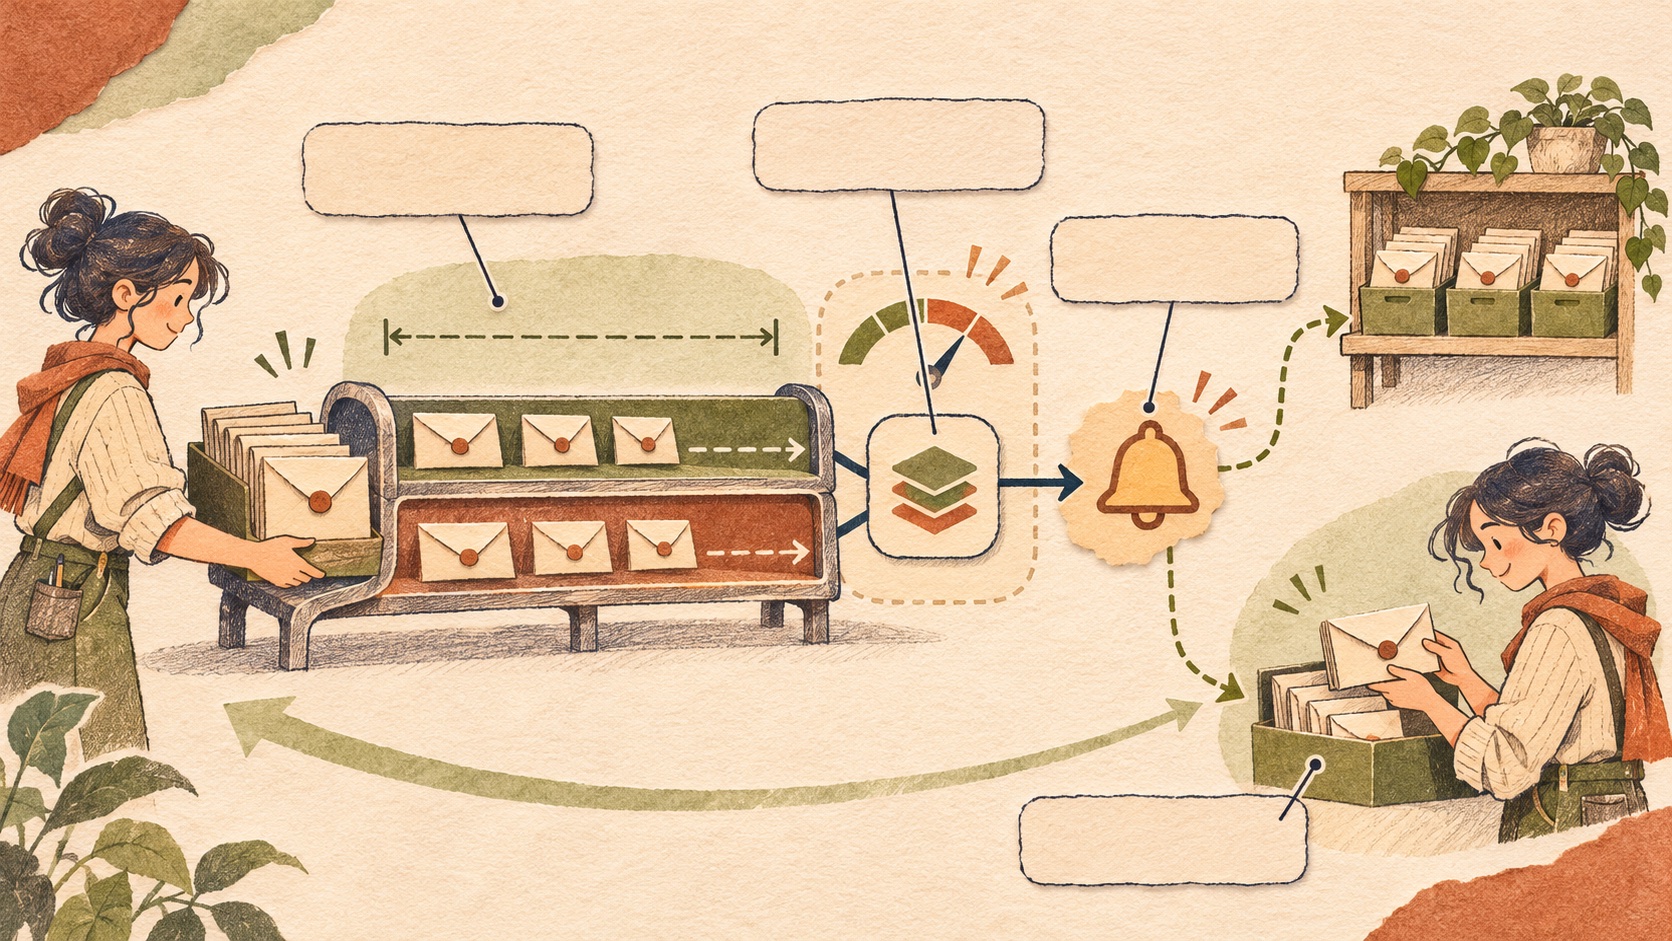
The request becomes a job
The Responses API background flow accepts a request asynchronously. Set background to true, choose 2h or 8h in background_options.completion_window, and save the response ID. OpenAI documents webhook notifications for terminal events such as completion, failure, incomplete and cancellation; the application verifies the webhook signature and retrieves the response by ID. Polling the same response ID is an alternative when webhooks are unavailable. [2]
For multi-step agent workflows, completion may not finish the whole task. The response can request a tool call; the application then runs that tool and submits a follow-up response. The guide advises reusing the same model, project, completion window and continuation ID where applicable to help queue priority. This is an asynchronous orchestration pattern, not a single long-lived HTTP request that the client should leave open. For queue ownership and lifecycle tradeoffs beyond a model API, see background-work architecture from cron to distributed queues. [2]
The discount buys patience, not unlimited capacity
OpenAI lists a 30% reduction for the two-hour window and 40% for the eight-hour window compared with Standard token rates. Its guide says these windows are available in public beta on selected models and require Standard processing, background: true, and streaming unset or false. With service_tier: auto, a request qualifies only if OpenAI actually selects Standard. [1] [2]
The requests share the Batch/Background Rate Limit with Batch API jobs. Input tokens count at submission, and the chosen queue may therefore affect other asynchronous work in the project. A team that moves every long prompt into the discounted lane could reduce the capacity available to existing batch processing. Monitor queueing and terminal states; do not infer that a discount means the request will finish at a fixed instant.
The window begins when the API accepts the initial request. OpenAI describes the selected timeframe as a target for completion. That is useful for planning, but a target is not a hard real-time deadline. Design downstream processes to handle delayed, failed, incomplete or canceled results. [2]
Temporary storage is still part of the contract
Background execution requires response data to remain available while the job runs and its result is retrieved. OpenAI’s data-control guide says background mode temporarily stores data even when store is false or Zero Data Retention applies. For the two-hour and eight-hour windows, the guide says temporary request content is encrypted at rest. This is not the same as the normal default 30-day Responses API storage behavior, but it is still temporary processing storage that must be considered before sending sensitive data. [2] [3]
If an application handles regulated or confidential material, its developers should compare the exact processing mode with the organization’s data policy. store: false should not be presented as meaning that no data is ever retained during background processing. The documentation is the current authority for retention exceptions and can change, so re-check it before launch.
A practical decision rule
Use soonest for work whose value depends on prompt delivery. Consider the two-hour window for reports or support-ticket analysis that can land later the same day, and the eight-hour window for a document batch that can be ready the next morning. Those examples mirror the intended queueing shape, but your own latency distribution and business deadline should drive the choice.
Before switching, measure request size, completion time, failure rates and queue delays on representative workloads. Preserve response IDs and enough state to recover from worker restarts. Verify webhook signatures, deduplicate webhook delivery, and make follow-up tool actions idempotent. Set a user-visible status for queued and delayed work instead of leaving a spinner that implies the model is still producing an immediate answer.
The lower rate is useful when the application can tolerate waiting and can operate reliably around asynchronous results. It is a poor fit when an end user is waiting for a conversational answer, or when project-level queue contention makes the target unpredictable. Treat it as a scheduling and cost option—with storage and recovery consequences—not as a universally cheaper API switch.
Frequently asked questions
How do the Responses API two-hour and eight-hour windows work?
Set background to true and background_options.completion_window to 2h or 8h for an eligible model. OpenAI targets completion within the selected window after accepting the request; these are targets, not an immediate-response SLA.
Do the longer completion windows use separate rate limits?
No. OpenAI documents that 2h and 8h requests share the Batch/Background Rate Limit with Batch API jobs. Input tokens count at submission, so queue capacity can affect other asynchronous workloads.
Does store=false prevent temporary storage in background mode?
No. OpenAI says background mode temporarily stores response data to process the request and make it retrievable. The longer-window requests use temporary encrypted storage even for Zero Data Retention projects; review the current data-controls documentation before sending sensitive inputs.
Sources & further reading
Keep reading
AWS Lets Coding Agents Start Account Setup. The Approval Boundary Still Matters
AWS account setup now fits coding agents, but people must still review identity, permissions, cost, and deployment.
Chrome DevTools Gives Coding Agents More Context, With Larger Trace Costs
Chrome adds paginated CSS inspection and chunked traces for agents. Learn to use the extra browser evidence safely.
GitHub Event Streams Replace Polling for Pull Requests, With a Reconnect Caveat
GitHub Event Streams send pull request updates over SSE, but clients must reconcile missed, repeated, or out-of-order events.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.