
OpenAI’s Decisions API Turns Classification Into a First-Class Product
The generally available Decisions API returns typed probabilities, choices, and scores, trading broad generation for focused application decisions.
On this page
Most software does not need an AI to write an essay. It needs an answer to a small question: does this request need a human, which queue should receive it, or how urgent is this report? OpenAI has made that pattern a product in its Decisions API, now generally available through a dedicated endpoint using GPT‑6 Luna.
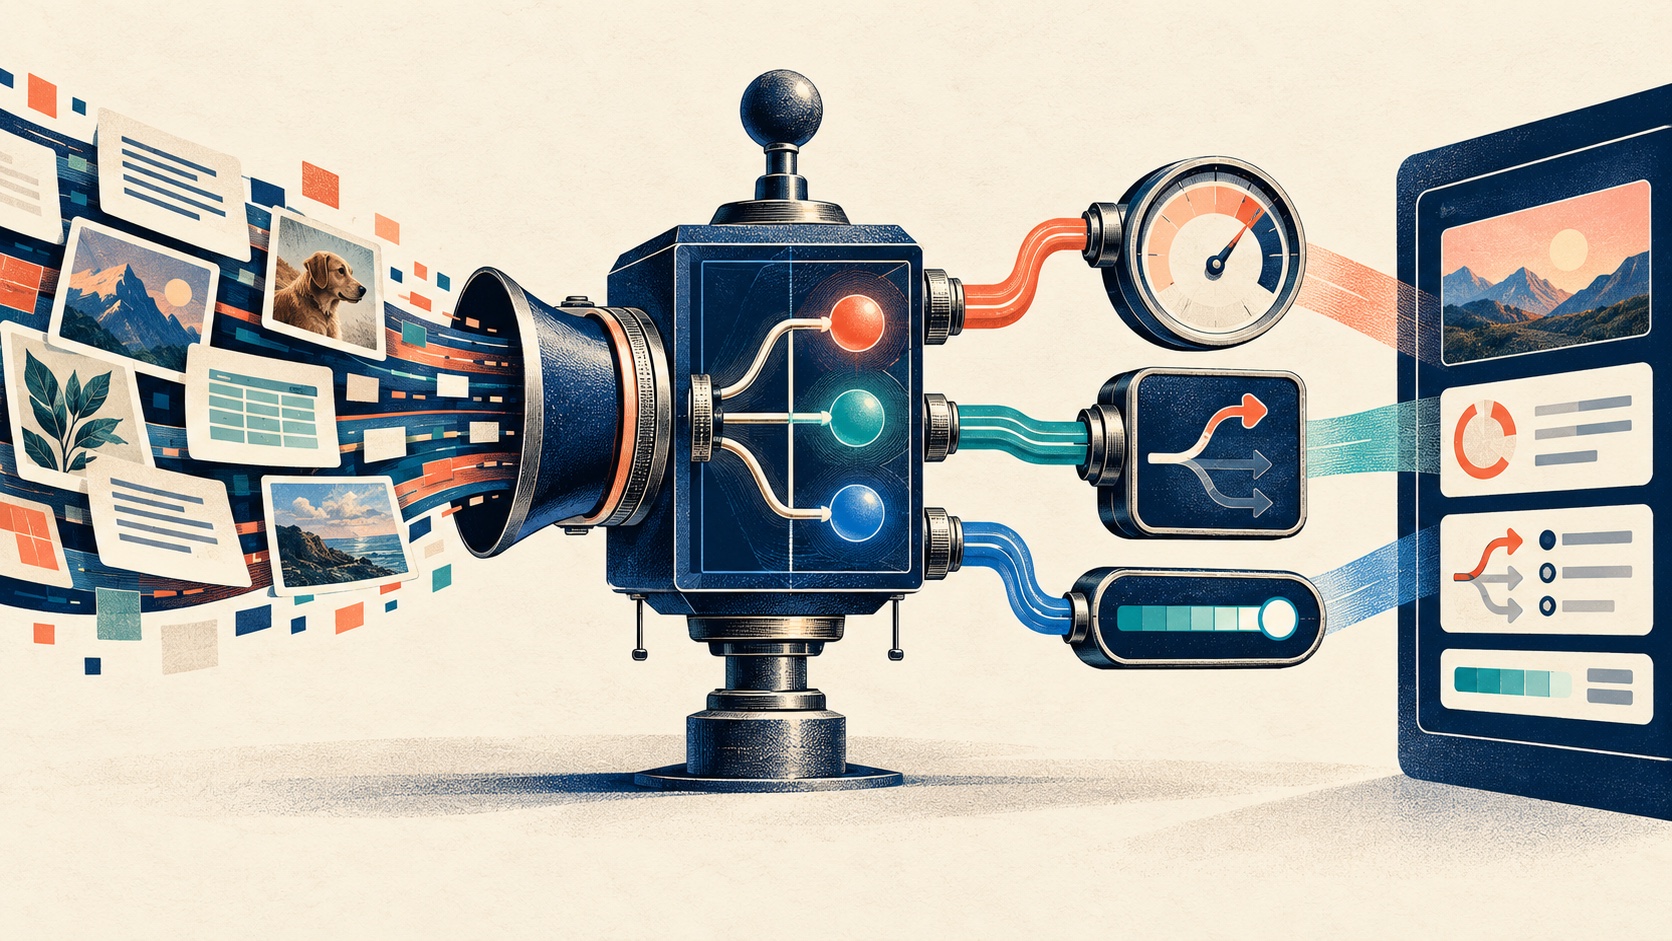
A narrower contract for an AI answer
The API accepts shared evidence and one or more questions. A question can ask for a predicate, such as whether a condition is true; a choice from a predefined set; or a score against an ordered scale. The service returns answers in corresponding typed forms, which application code can route or display. OpenAI says the endpoint can accept text, images, conversation history, and structured JSON, and supports up to 400 questions in one request. The October general-availability release also adds a native GPT-Live integration, prompt caching for repeated context, and US/EU inference residency. Those additions matter for voice workflows, recurring inputs, and regional requirements, though teams should confirm account availability and terms before relying on them. [1] [2]
That contract changes what the application team is responsible for. With a general-purpose generation call, developers often ask a model to produce JSON, parse it, and repair malformed output. Here the allowed answer space is part of the request. A support product can define continue, clarify, and escalate; a moderation workflow can define a small set of policy categories; an image review queue can ask whether a visible defect appears present.
The returned probability is not a guarantee that the answer is true. It is a model estimate. The API reference describes predicate answers as probabilities and choices as selected values with probability distributions and confidence information. That is useful signal, but it does not remove the need for labeled examples, thresholds, and a human path for uncertain cases. [2] [3]
Where the dedicated endpoint can help
The clearest fit is a repeated decision already embedded in a product workflow. Think of routing a message to billing or technical support, deciding whether an image should enter a manual-review queue, or ranking incoming incidents by a documented rubric. These are useful when the choices are understood in advance and the system needs to act quickly on them.
OpenAI claims the endpoint can be up to ten times faster than using GPT-6 Luna through its Responses API. That comparison is a vendor claim, not a latency promise for every prompt, network, or workload. Teams should measure the end-to-end experience they actually ship: request size, model time, retries, database lookups, and downstream work can all matter more than one endpoint comparison. [1] [2]
A small response can also reduce glue code. Instead of asking a model for a paragraph and writing brittle rules to interpret it, an application can receive a typed decision and keep the user-facing explanation in a separate, auditable step. The separation is valuable: routing logic can be evaluated independently from the prose a system later shows to a customer.
The design work moves into the question
A narrower API does not make the problem disappear. It makes question design and evidence quality more visible. If the categories overlap, the model will inherit that ambiguity. If instructions combine several decisions—“decide whether this is urgent, whether it is fraudulent, and what the user intended”—a single answer may be hard to interpret or debug.
Start with one decision and define observable criteria. Use examples that reflect real cases, including borderline and adversarial inputs. Keep a holdout set that was not used to tune instructions. Measure the cost of false positives and false negatives separately: routing a harmless note to review may cost staff time, while missing a safety escalation can carry a much larger cost. Choose thresholds from that tradeoff rather than treating a high confidence number as a universal pass mark.
For a choice task, add an explicit unknown or needs_review option when the evidence may not fit any supplied value. Log the evidence version, question version, model, decision, and downstream action in a way that respects your retention policy. Periodically sample decisions that were not escalated; otherwise the team only learns from the cases it already suspected were wrong.
Not every app needs it
Use a generation endpoint when the product needs an explanation, a new document, a summary, or an object whose fields are not naturally a small set of application decisions. OpenAI’s own documentation draws that boundary: Decisions is for classification or scoring, while other endpoints fit generation and custom structured outputs. [2] [3]
The service is generally available and currently supports GPT‑6 Luna. OpenAI’s docs also list input pricing and data controls, including eligibility conditions for some protections; teams should confirm current terms, processing region, and account availability before sending sensitive data. [1] [2]
The useful question for an engineering team is not whether this endpoint is faster in the abstract. It is whether a specific recurring decision can be expressed clearly, measured against representative cases, and safely connected to an action. If the answer is yes, the Decisions API offers a more direct interface. If the question itself is fuzzy, the first task is to fix the workflow and evaluation—not to add another model call.
For a broader view of AI system boundaries, see our guides to tool permissions for AI agents and evaluating coding assistants on real tasks.
Frequently asked questions
When should a developer use the Decisions API instead of a general response endpoint?
Use it when the product needs a bounded predicate, a choice from a known set, or a score against an ordered rubric. Use a generation endpoint when you need prose, open-ended reasoning, or a custom structured object.
Sources & further reading
Keep reading
The $93 Billion AI Opportunity for Small Businesses Comes With a Catch
A Tech Council of Australia report estimates large gains from SME AI adoption, but its headline is a scenario—not a guaranteed productivity result.
Uber’s 30,000-Person ChatGPT Work Rollout Is an Adoption Test
Uber says ChatGPT Work is expanding from a 1,000-person pilot to more than 30,000 employees, putting governance and workflow design in focus.
Thousands of AI Agents Read a Brain-Cell Dataset in Parallel. What Did That Actually Buy?
OpenAI and Scripps describe parallel agents linking mouse brain-cell data to research literature and generating hypotheses for lab tests.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.