
OpenAI's 948 Linux Findings Are a Pipeline Result, Not 948 New CVEs
OpenAI says its research pipeline reproduced many Linux kernel flaws and generated candidate patches. The disclosure count still needs careful interpretation.
On this page
A four-digit vulnerability headline can sound like four-digit proof. OpenAI’s November 4 report is more specific: its team says a research pipeline identified 2,308 candidate findings in selected Linux kernel code, dynamically reproduced 1,724, and generated 948 distinct local privilege-escalation exploits with candidate patches. Those are important results, but the terms are not interchangeable. A candidate finding, a reproduced behavior, an upstream disclosure, a CVE assignment and a merged patch are different stages. [1] [3]
What the pipeline says it did
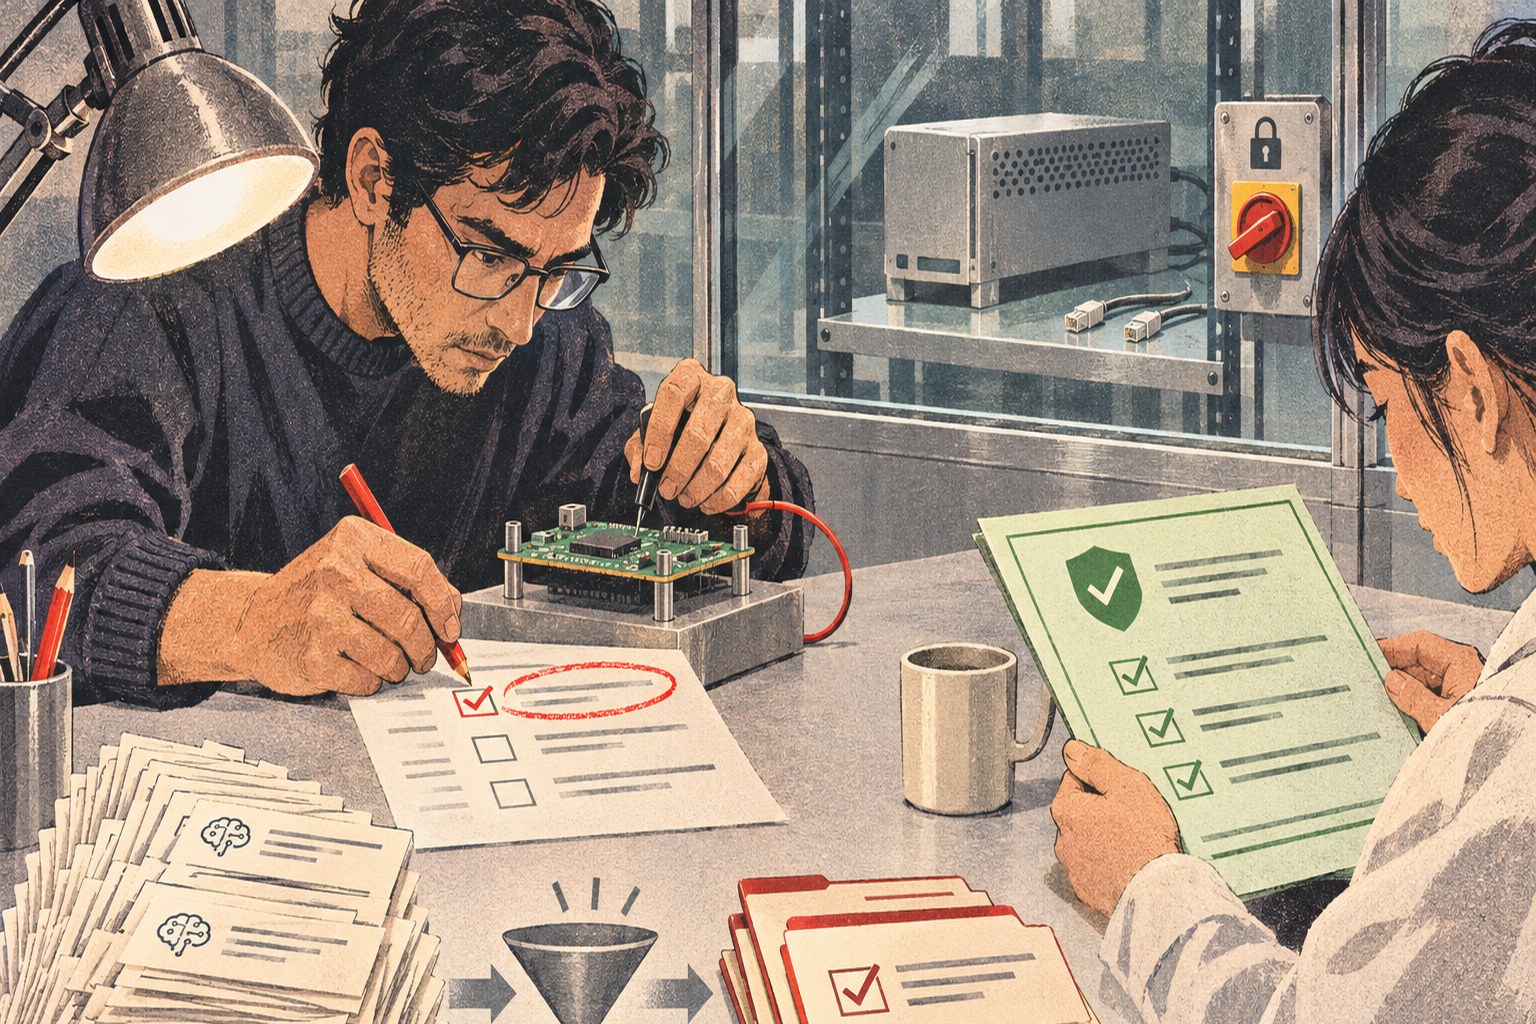
OpenAI describes a sequence: agents selected security-relevant code paths, analysts proposed findings, a triage stage attempted reproduction inside an isolated virtual machine, and researchers reviewed exploit evidence and candidate patches. The company says the scan targeted code reachable by low-privilege users and looked for measurable memory corruption. It reports the run cost about $1.21 million in API credits and that the 948 exploits averaged $1,279 each under its accounting. [1]
The company also says the system produced 291 proof-of-concept information-leak findings and 1,169 working local-privilege-escalation exploits before variant analysis reduced those to 948 distinct patches. It observed that 61 LPEs had been patched upstream, 43 had staging patches and 299 were being reported or discussed publicly by the time the scan and analysis ended. That status snapshot is a reminder that finding a flaw is only one piece of coordinated disclosure and remediation. [1]
Why “948” does not mean “948 new CVEs”
The report does not identify 948 newly assigned CVE numbers, and it does not say 948 patches had all merged into a stable kernel release. It describes a set of distinct exploits associated with vulnerabilities found in a specific research effort. Some findings were already patched, under discussion or in progress while the scan ran. A vulnerability may have multiple manifestations; a proof of concept can establish behavior without completing disclosure; a patch proposal still needs maintainer review and testing.
That distinction matters to maintainers and users. Repeating an old flaw under a new identifier would overstate the threat; treating an unreviewed patch as safe could introduce regressions. The Linux kernel’s own security process asks reporters to contact the security team with enough information to reproduce and assess a problem, and notes that security bug handling depends on coordination and appropriate disclosure. The report’s aggregate number does not replace that work. [1] [3]
The operational bottleneck is becoming triage
OpenAI’s result is also a cost-and-throughput claim. The company says its mid-October run found more than five times as many novel LPEs as a July run using an earlier model, despite intervening hardening. Those are company-reported comparisons, and the article does not provide an independent rerun by another research team. The figures should be read as evidence of the company’s internal workflow and as a signal of where security teams may need more capacity—not as a universal forecast for every codebase. [1]
The UK NCSC’s separate November assessment argues that AI is likely to increase the speed, scale and efficiency of existing cyber tactics, and warns that organizations must adapt their patching and testing processes. That assessment is not independent validation of OpenAI’s specific findings, but it supports the broader concern that vulnerability discovery can accelerate faster than organizational response. [2]
For maintainers, the useful response is to prioritize reports with a clear affected code path, minimal reproducer, impact and proposed fix. Revalidate against current source, check whether another report already covers the same issue, and coordinate disclosure so defensive users have a patch path before exploit details spread. For software operators, the practical response remains ordinary but demanding: know which kernel builds run in production, apply vendor updates promptly, and keep least privilege and sandbox boundaries in place.
Automation raises the value of careful disclosure
Automated research can help defenders search more code and generate more repair candidates. It cannot by itself make every finding novel, correctly prioritized or easy for volunteer and commercial maintainers to absorb. The proof that matters to users is what gets confirmed, disclosed responsibly and fixed in supported releases.
OpenAI’s report is strongest when read as a demonstration of an end-to-end research pipeline and a warning about queue management. The 948 figure is attention-grabbing; the harder challenge is making the evidence actionable without overwhelming the people responsible for shared software. For more on security control boundaries, see our guide to scoping AI-assisted security work and our explainer on keeping automation permissions narrow.
Frequently asked questions
Did OpenAI disclose 948 new CVEs?
No. OpenAI reported generating 948 distinct local privilege-escalation exploits from its research pipeline. Its post does not describe 948 newly assigned CVE identifiers or 948 vulnerabilities all newly disclosed to the public.
Were all 948 findings independently confirmed or patched upstream?
OpenAI describes dynamic reproduction and human review in its controlled research process. It says 61 had been patched upstream, 43 had staging patches, and 299 were being reported or discussed publicly when its analysis finished. Those statuses do not mean every finding had an upstream fix.
What should maintainers take from the report?
The strongest practical signal is that vulnerability discovery and triage can arrive at a scale that strains manual patching. Maintainers should prioritize evidence-backed reports, verify findings against current code, coordinate disclosure, and preserve review capacity for correct fixes.
Sources & further reading
Keep reading
The UK's 2028 AI Cyber Warning Is a Planning Scenario, Not a Prediction
The NCSC says AI may scale cyber operations; its 2028 scenarios are plausible futures, not predictions of autonomous attacks.
Can You Prove Which AI Model Answered You?
Anthropic’s FlashProve prototype explores cryptographic proof that a response came from a specific model, while revealing little about its private weights.
Box’s Agent Guardrails Put Content Permissions Around AI Actions
Box’s new controls restrict agent actions such as uploads and sharing, while audit trails and threat detection remain part of its roadmap.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.