
PAPERBENCHX Tests Whether AI Can Rebuild Evidence, Not Just Explain a Paper
A 93-task benchmark across scientific fields finds a large gap between AI agents running parts of an experiment and reproducing its evidence.
On this page
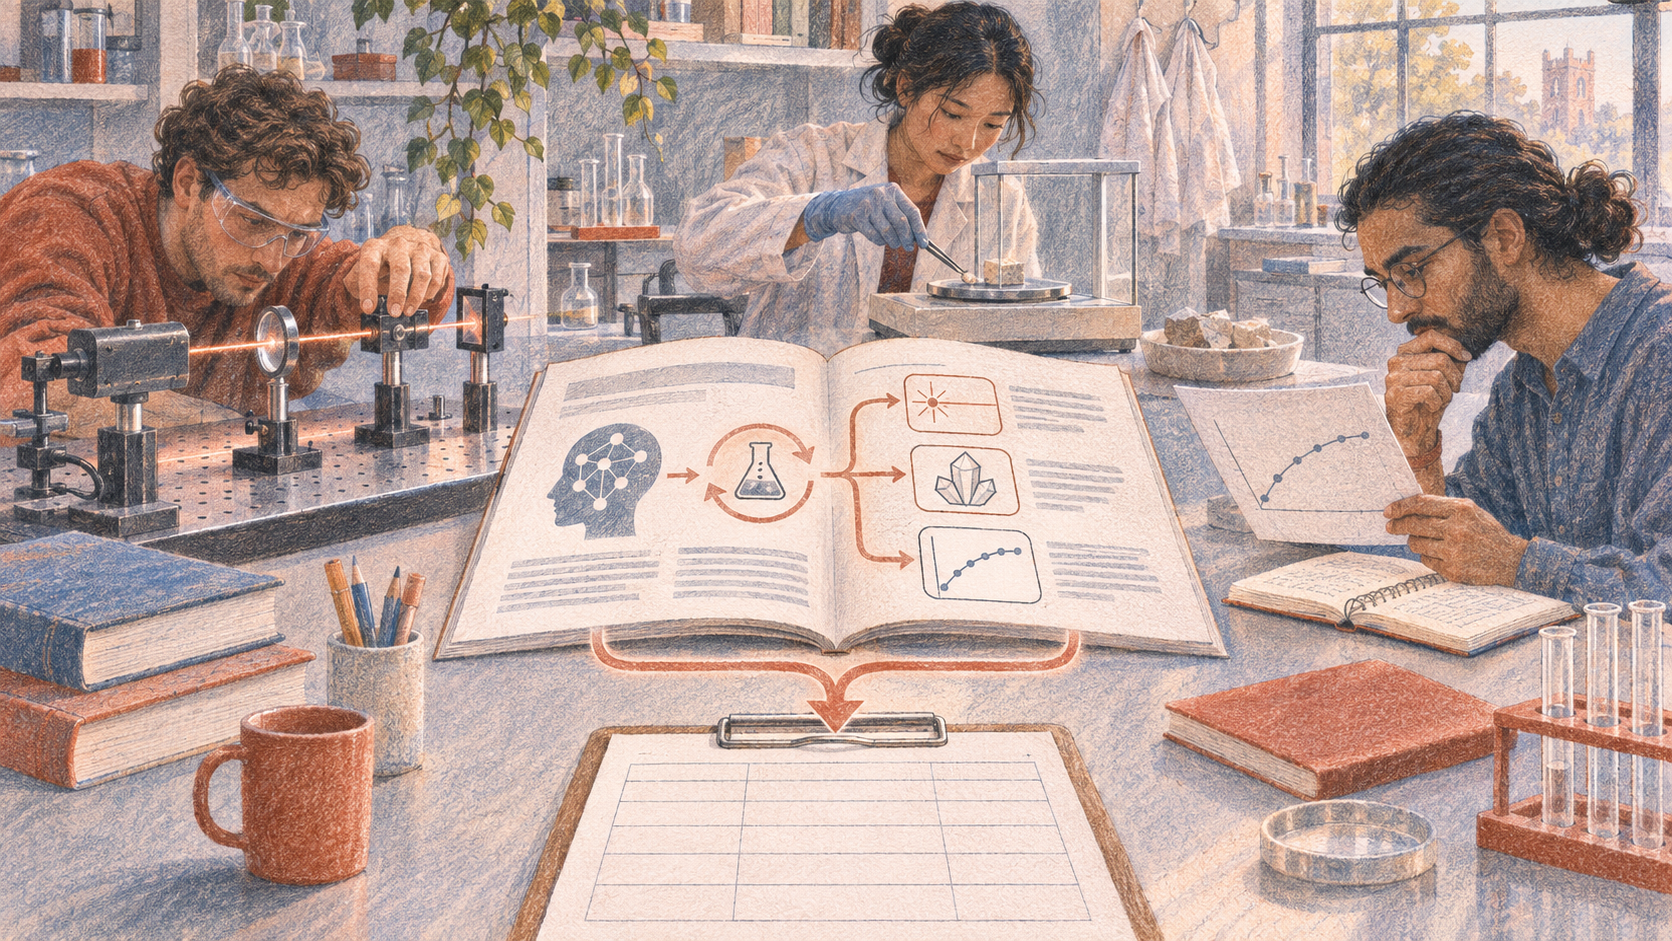
An AI system can summarize a scientific paper fluently and still fail to reproduce its central result. It might choose the wrong simulation setting, miss a dependency, use a measurement from the wrong condition, or return an output that looks plausible without supporting the claim. PAPERBENCHX, a new cross-disciplinary benchmark, tries to make those failures observable by asking agents to rebuild experiments and provide evidence that can be replayed. [1]
A paper-to-evidence task
The benchmark’s authors describe 93 expert-constructed tasks across 12 research areas, including computational chemistry, materials science, biology, photonics and robotics. Each task provides a source paper, a public description of what to reproduce, and a domain-native computing environment. Depending on the field, that may mean working with a specialized simulator rather than a generic notebook. The agent must reconstruct a key experiment, run it, diagnose the process and deliver a workflow supporting the target claim. [1]
The benchmark goes beyond asking an evaluator to judge a written report. The authors say they replay each submission from scratch and score regenerated evidence against expert-validated criteria. They report 3,168 scoring criteria, a median of 38 per task, and task budgets ranging from four to 72 hours. In this setup, “reproduction” means more than producing a similar-looking chart: the submitted workflow must regenerate evidence under the specified conditions. [1]
That distinction matters because research papers compress a great deal of work into a small number of plots and tables. A convincing-looking graph may still come from the wrong model configuration, dataset split, solver tolerance or preprocessing step. A replayable artifact gives reviewers something concrete to inspect: how the result was built, what the software produced and whether the evidence matches the scientific claim.
Partial progress can hide the hard part
Across ten agent configurations, PAPERBENCHX reports mean partial scores ranging from 27.53% to 59.08%. The best configuration fully reproduced 14% of tasks under the study’s 90% threshold. Across 930 outcomes, 80 exceeded that threshold, concentrated in 22 tasks; 71 tasks were not completed by any configuration. The result does not mean that agents made no useful progress. It shows how often progress on individual steps stops short of end-to-end evidence. [1]
The authors report that median scores for modeling and execution were each above 73%, while the validation stage’s median was 40%. Even among outcomes scoring at least 80% in both modeling and execution, only 17.4% crossed the full-reproduction threshold. In other words, implementing a model and getting it to run are necessary but insufficient. An agent still has to establish that the output supports the paper’s claim under the right conditions. [1]
This pattern is consistent with a broader movement toward process-based AI evaluations. OpenAI’s PaperBench asks agents to reproduce machine-learning conference papers from scratch and decomposes tasks into rubric items. FIRE-Bench, published in the Proceedings of Machine Learning Research, asks agents to rediscover established findings through experiments and evidence-backed conclusions. A 2026 Nature paper on Paper2Agent explores turning papers and their resources into interactive tools. These systems do not measure exactly the same capability, but they all expose the distance between text about a method and a workflow that another person can inspect. [2] [3] [4]
What the score does not say
PAPERBENCHX is a preprint’s benchmark, not a verdict on whether AI can conduct science. Its task set is finite, the environments and resource limits are defined by the authors, and a 90% cutoff is an operational definition of “full” rather than a universal standard for scientific success. The paper also releases a representative task from each research area, while retaining many tasks as a hidden evaluation set. Readers should treat the numbers as evidence about the tested configurations and benchmark design, not a forecast for every lab or scientific discipline. [1]
Reproducing a known result is also not the same as making a novel discovery. When a claim has already been published, benchmark designers can define what counts as relevant evidence and compare an agent’s output with a target. New science often involves ambiguous hypotheses, unexpected observations, experimental constraints and follow-up work that cannot be reduced to one score. A system that performs well on computational reproductions might still need human supervision for decisions about biological significance, safety or research priorities.
Nor does a successful rerun prove that the original paper is correct in every respect. It shows that the benchmark’s specified workflow regenerated evidence meeting its criteria. Independent science still depends on scrutiny of assumptions, methods, data provenance and alternative explanations. The benchmark’s replay requirement strengthens one part of that chain; it cannot replace the rest.
Crashtech has previously covered AI agents as data-analysis assistants and outside evaluation of AI-assisted research progress. The same principle applies: capability claims become more useful when readers can see how results were obtained, what was measured, and which uncertainties remain.
A useful evaluation design for research tools
A lab evaluating an AI assistant can borrow several ideas from this work without treating a benchmark as a procurement decision. Define a result to reproduce, preserve a clean environment, specify expected evidence before running the agent, and keep the output artifact runnable. Separate errors in paper interpretation from environment setup, modeling choices, execution and result validation. A single aggregate pass rate can hide which stage needs better tools or human review.
Then test on a mix of tasks that matter to the group. Track not only completion, but also provenance errors, incorrect assumptions, compute consumed, rerun success and the time researchers spend checking the result. A system that runs quickly but produces hard-to-audit outputs may increase review costs. A system that handles routine setup yet clearly surfaces uncertainty may still help scientists spend more time on decisions that need their expertise.
PAPERBENCHX’s central finding is therefore methodological: scientific assistance should be evaluated by the evidence it can reproduce, not by how convincingly it describes a paper. Its current results show progress on parts of the workflow and a substantial gap at the validation boundary. Closing that gap will require better tools, careful task design and researchers who remain able to inspect the work. [1] [3]
Frequently asked questions
What does PAPERBENCHX measure?
It tests whether AI agent configurations can reconstruct and run experiments from scientific papers in domain-specific software environments and produce evidence that supports a stated claim. The benchmark covers 93 tasks across 12 areas and scores replayed outputs against expert-validated criteria.
Did agents fully reproduce most PAPERBENCHX tasks?
No. The authors report that the best configuration fully reproduced 14% of tasks under their 90% score threshold. Mean partial scores were higher, showing that progress on individual steps often did not compose into a complete reproduction.
Does a benchmark score predict scientific discovery in the lab?
Not by itself. Reproducing a selected computational result is a valuable test of reading, implementation, execution and evidence handling, but it does not establish that an agent can make a novel discovery or validate results in every real research setting.
Sources & further reading
Keep reading
Google’s Chemistry Agent Is Fast at Finding Candidates; the Lab Still Decides
Google Antigravity links literature search, molecular datasets and chemistry tools in a drug-design workflow, but every proposed molecule remains a hypothesis.
Encrypted Robot Commands Can Still Leave a Readable Rhythm on the Network
A 2026 study found robot actions could be inferred from encrypted traffic metadata, exposing a privacy gap between payload secrecy and behavioral privacy.
NTT and Safran Want Satellite Laser Links to Behave More Like a Network
A November 6 memorandum explores connecting Safran optical ground stations to NTT's network control and All-Photonics Network technologies.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.