
Reflection Beam Is Open-Weight. Your Deployment Still Has a Memory Problem.
Beam’s Apache-licensed weights widen access, but 501 billion total parameters make hosting, memory and evaluation the real decisions.
On this page
A model can be downloadable and still be difficult to run. Reflection’s Beam release makes the weights available for self-hosting, customization and inspection. The practical question for an engineering team is not simply whether it is open. It is whether the model’s full footprint, software stack and measured behavior fit the workload the team actually has.
Reflection announced on 16 October that Beam’s weights were available on Hugging Face under an Apache 2.0 license. The company also published a model card and a safety report, and listed hosted and self-hosted routes through its partners. That is a real change in access: teams can work with the weights rather than only call a vendor endpoint. [1]
But the announcement bundles several layers that are worth separating: a model license, the actual weight files, the runtime needed to serve them, the evaluation evidence and the operational work required to keep a self-hosted system reliable.
“Open” answers one question, not the whole deployment
The phrase open-weight has a specific practical meaning: model parameters are distributed so others can run or adapt them, subject to the license. It does not automatically tell a buyer whether the training corpus is fully available, how the training run was reproduced, whether a particular partner service sends prompts off-premises or what additional components are open.
Reflection’s documentation describes Beam as a text model and lists it for coding, reasoning and agent workflows. The model card specifies BF16, FP8 and NVFP4 weight formats and says the license governs the weights; the card itself is informational and does not replace the license. [2]
That is enough to ask better procurement questions. Which artifact is covered by Apache 2.0? Which inference engine and agent harness will be used? Is the system self-hosted, or is it calling a managed API? What can the provider log? What is the plan for model updates and security fixes? A weight file can sit inside a much larger service whose other terms still matter.
Active parameters are about computation, not total storage
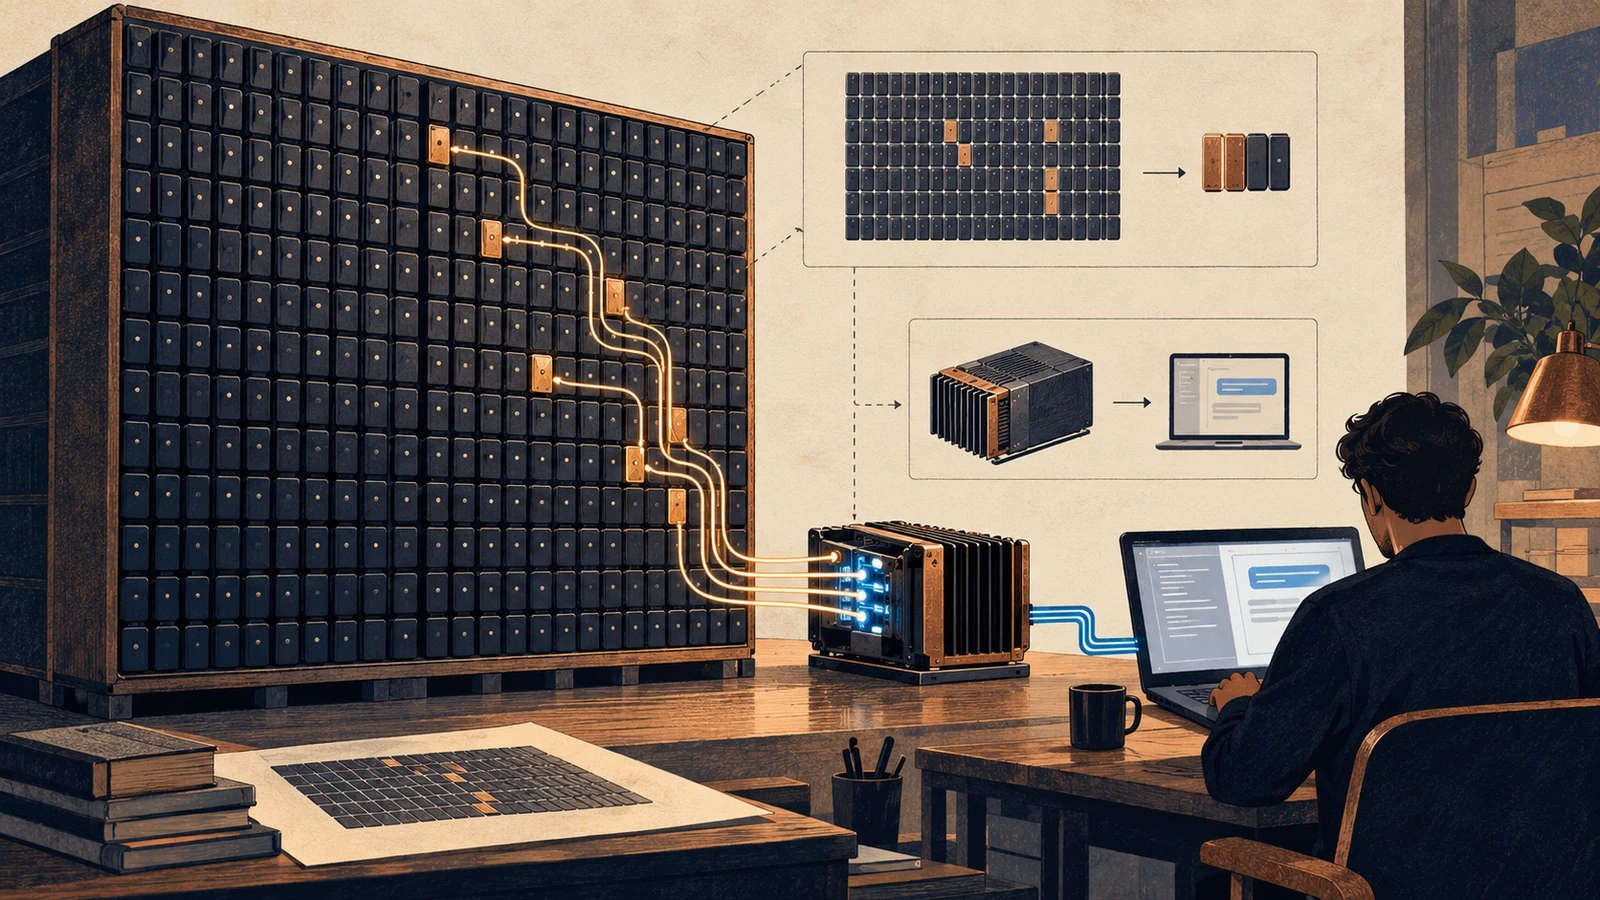
Beam’s model card reports 501.3 billion total parameters and 23.4 billion active parameters. It uses a sparse mixture-of-experts design, so a token is routed through only part of the model. In broad terms, that can reduce the computation needed for each token compared with activating every parameter at once. It does not mean the other weights disappear. [2]
A rough storage calculation helps make the distinction concrete. If every one of 501.3 billion parameters were represented with two bytes, the raw weights alone would be about one trillion bytes, or roughly 0.91 tebibytes. At one byte per parameter, the raw total would still be about 501 gigabytes. A four-bit representation suggests roughly 251 gigabytes before extra scales, metadata and runtime overhead.
These are arithmetic illustrations, not a measurement of Reflection’s downloadable files. Real formats have packing and auxiliary data; serving can use offloading or distributed memory; and not every workflow must hold every tensor in one accelerator. The important point is that 23.4 billion active parameters describes what is used for a token, not the complete storage budget.
That is why a developer should not see “23B active” and assume Beam behaves like a 23-billion-parameter dense model on a 24GB card. The complete expert set still has to be available to the serving system, and the runtime also needs memory for context, activations, batching and the agent harness.
The model card lists a one-million-token context window as a supported maximum. A maximum context length is not free capacity: longer prompts require more cache and can change latency and memory requirements. Teams should test the context sizes they intend to use instead of treating the headline limit as a default operating point. [2]
Benchmarks are a starting point for your own test
Reflection’s model card and technical report publish benchmark and safety results. Those documents are useful evidence about the company’s evaluations, and the report gives readers a methodology to inspect. They are still vendor-produced results. They do not establish how Beam will perform on a team’s own repositories, tools, data or user policies. [3]
For a coding agent, that difference can be decisive. A benchmark may score whether a model solves a known task, while a production workflow also depends on repository context, tool permissions, test quality, retry limits and whether the system can stop safely when it reaches an uncertain boundary. A model that is fast per token may still be expensive if it needs multiple attempts or a large context cache.
A useful pilot should therefore measure more than completion rate. Track the fraction of tasks that pass existing acceptance checks, the amount of human review required, inference time, memory pressure, retry frequency and failures caused by tool use. Compare Beam with the current baseline under the same harness and task set. Keep evaluation tasks separate from any material used to tune the model.
The company’s report includes safety evaluations, but a refusal or compliance score is not a substitute for testing the exact agent configuration. A model’s behavior can change when it receives different tools, system instructions, quantization, context or routing. Safety evaluation belongs at both the model and application levels. [3]
Who should consider the release?
Beam is most interesting to teams that have a real reason to control the model artifact: adapting it to a domain, inspecting the weights, running in a constrained environment or comparing model behavior without depending on one hosted endpoint. Reflection lists integrations with inference tools and describes routes for on-premises and air-gapped environments. Availability and support details should still be verified for the specific provider and configuration. [1]
A team that only needs a capable coding assistant may have a simpler choice: test a hosted endpoint against its privacy, latency and cost requirements before taking on the model-serving work. A self-hosted model moves part of the burden into the organization. Someone must plan capacity, patch dependencies, monitor service health, control access and keep the evaluation process current.
The local-agent design guide explains why local execution can change data boundaries without automatically making an agent private. For a newly available personal-compute option, see our separate RTX Spark workflow analysis; its memory ceiling and software stack are separate questions from whether a particular model’s full weights can fit.
A practical go/no-go sequence
Before downloading a large checkpoint, write down the task and the operating boundary. Estimate the memory needed for the full selected format, not only active parameters. Include context cache and serving overhead. Confirm the runtime supports the artifact and the target hardware. Then run a small evaluation set that resembles real work and record quality, latency, failure modes and human review.
Finally, decide whether the workload benefits from self-hosting enough to justify the operational cost. Apache-licensed weights create more options. They do not make every option economical, private or production-ready by themselves.
Beam’s release is worth paying attention to because it moves a large model from preview access to downloadable weights and a wider ecosystem. The next useful evidence will come from independent tests and from teams publishing what it takes to serve the model reliably under real constraints. Until then, treat the technical documentation as a starting point and measure the system you intend to operate.
Frequently asked questions
What does open-weight mean for Reflection Beam?
Reflection released Beam’s model weights under an Apache 2.0 license and provides a model card and safety report. That lets developers download and run the model under the license terms, but it does not by itself make the entire training dataset, training process, inference infrastructure or partner services open.
Why do 23 billion active parameters not mean Beam fits in 128 gigabytes?
Active parameters describe the subset used for a token in a sparse mixture-of-experts model. The remaining experts still need to be stored or fetched somehow, and memory is also used by runtime components and the context cache. Exact requirements depend on format, software and placement strategy.
Can a developer run Beam locally?
Reflection says developers can self-host Beam and lists supported inference tools and partner platforms. Whether a particular machine can serve a chosen format at useful speed depends on total weight storage, available memory, context length, runtime overhead and the workload.
Sources & further reading
Keep reading
Meta’s New Feed Controls Make a Promise. The Ranking System Still Decides.
Facebook’s natural-language feed controls make preference editing easier, but the platform still translates each request into ranking signals.
RTX Spark Could Bring AI Development to Your Desk—With New Tradeoffs
NVIDIA’s compact GB10 system promises local coding and model work, but shared memory, ARM software support and workload fit still decide its value.
The Hard Part of Medical AI Starts After the Accuracy Test
The UK’s AI Airlock Phase 3 puts post-market surveillance and lifecycle evidence in focus as healthcare AI changes after deployment.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.