
When an AI Agent Visits Your Website, Who Is Accountable?
Personal agents can hide the person behind a request. Learn what site owners can measure today and what identity, consent, and accountability still require.
On this page
A person asks an online shop’s assistant to compare two products. The website sees a burst of requests from an automated browser, but may not know whether one customer is browsing, a service is acting for many customers, or an attacker is hiding behind a familiar agent name. This is the new web access problem: sites need to recognize the software, preserve the user’s choices, and know who is responsible when something goes wrong.
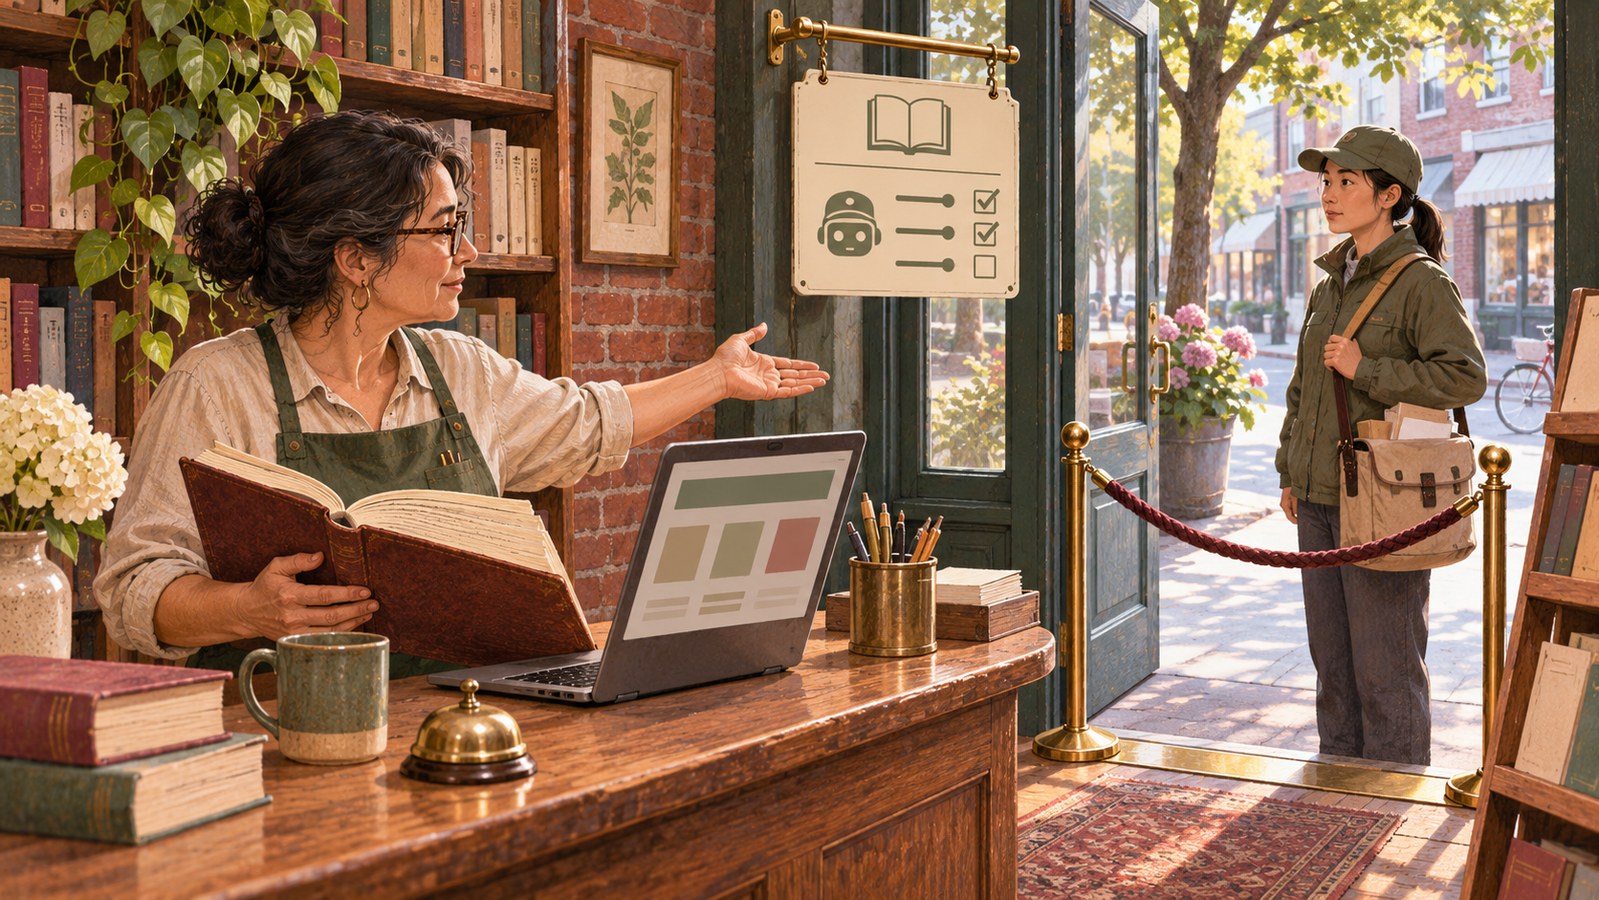
Cloudflare’s November announcements make the distinction concrete. Its Security Analytics now labels Personal Assistants as a traffic category and can show which agents visit, what paths they request, and which status codes they receive. Separate controls let a site set access policies for agent traffic and individual personal agents. That visibility helps answer “what is happening?” It does not, by itself, answer “which person authorized this action?” or “who pays when the agent is wrong?” [1] [2]
A bot name is not a delegated identity
A user-agent string is easy to copy. An IP address can identify a hosting network without identifying the customer whose request is being carried. Even a cryptographically signed request can establish that a particular operator or agent key sent it; it does not automatically prove that a human consented to a particular purchase or account change.
These are separate questions. A site may need to know the agent’s operator to apply a rate limit, the user’s account to personalize a session, and the user’s approval for a consequential action. In other cases—reading a public help page—linking a request to a named person would be unnecessary and intrusive. The right identity level depends on the action and the risk.
Cloudflare describes the issue as intermediation: when an agent acts between a user and a site, the site may lose the context it previously got from a direct browser session. Its proposed direction includes identity, reputation, and accountability, alongside work on open protocols such as Web Bot Auth, OAuth, and privacy-preserving rate limiting. That is an ecosystem direction, not a universal, finished delegation standard. The IETF Web Bot Auth working group is working on authenticated bot requests; OAuth token exchange provides a standardized way for an authorization server to exchange tokens, but neither alone proves the user approved every downstream action. [2] [3] [4]
What operators can do now
Start with observation. Establish a baseline for automated requests to login, search, pricing, inventory, checkout, and account pages. Look at path, rate, response, and business outcome—not merely the declared bot name. If you use a provider that exposes agent analytics, compare its category with your own server logs and conversion events. Cloudflare says its new analytics surface Personal Assistants as a distinct category; availability and enforcement options depend on its product and account configuration. [1]
Then write a policy by behavior. A research agent reading public documentation has a different risk profile from an agent submitting orders or trying passwords. Keep search indexing, model training, and real-time agent actions conceptually separate. Cloudflare’s controls reflect this separation, and its documentation notes that crawler directives in robots.txt are voluntary unless an edge provider separately enforces them. A policy file is not authentication, rate limiting, or transaction consent. [5]
For actions that change money, identity, or access, require an explicit authorization boundary. Give an agent a short-lived, action-specific credential where the platform supports it; bind it to the resource and operation; and preserve an audit trail that can distinguish user, agent, and operator. Ask for a confirmation step when the requested action is hard to reverse. Do not treat “the user handed the agent a broad login” as equivalent to proof that the site can attribute every action to that user.
Finally, plan for revocation. A site should be able to limit one misbehaving agent or one compromised account without blocking every legitimate user who shares the same intermediary. That requires signals that are stable enough to act on but minimized enough to avoid building a cross-site tracking identifier. Cloudflare describes per-user mitigation within its Account Abuse Protection product as an early-access capability; it is a product-specific implementation, not a general web standard. [2]
The real tradeoff is useful access with bounded trust
Blocking every agent is simple, but it also prevents a customer from using an assistant to find a product, compare a policy, or navigate an accessible interface. Allowing every request without context can shift scraping, fraud, and operational costs onto the site. Better controls let an operator decide which automated behaviors are welcome while keeping high-risk actions accountable.
The distinction matters for readers too. A site that asks an agent to identify itself is not necessarily asking for the person’s full identity; a privacy-preserving design can reveal a service identity or a scoped session without exposing more than needed. Conversely, a visible agent badge should not be mistaken for authorization to use someone’s account.
For website teams, the practical next step is modest: map the actions agents reach today, separate read-only access from consequential operations, and define what evidence each operation requires. For agent builders, preserve the chain of delegation rather than collapsing it into a generic browser session. Standards and products are evolving; until they converge, a bot label is a useful traffic clue, not a trust decision.
Sources & further reading
Keep reading
Intel's Cognitive-City Pitch Has a Hard Test: Who Gets to Act?
Intel’s city AI vision moves beyond sensors to action. Interoperability and public accountability determine whether the shift serves residents.
Nemotron 3.5 Transcribe brings instruction-led speech work on-device
NVIDIA’s open-weight speech model transcribes, translates and attributes speakers offline. Its hardware demands make local ownership a tradeoff.
Mistral's Le Chonk Is Open Weight. Running It Is the Next Test
Mistral released Large 4 weights with coding and security claims. Infrastructure, licensing and evaluation are part of the decision.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.