
Replay Production Traffic Before Release—But Make Side Effects Impossible
A new AWS reference pattern replays sampled production requests against candidate code. The hard part is isolating writes and comparing the right outputs.
On this page
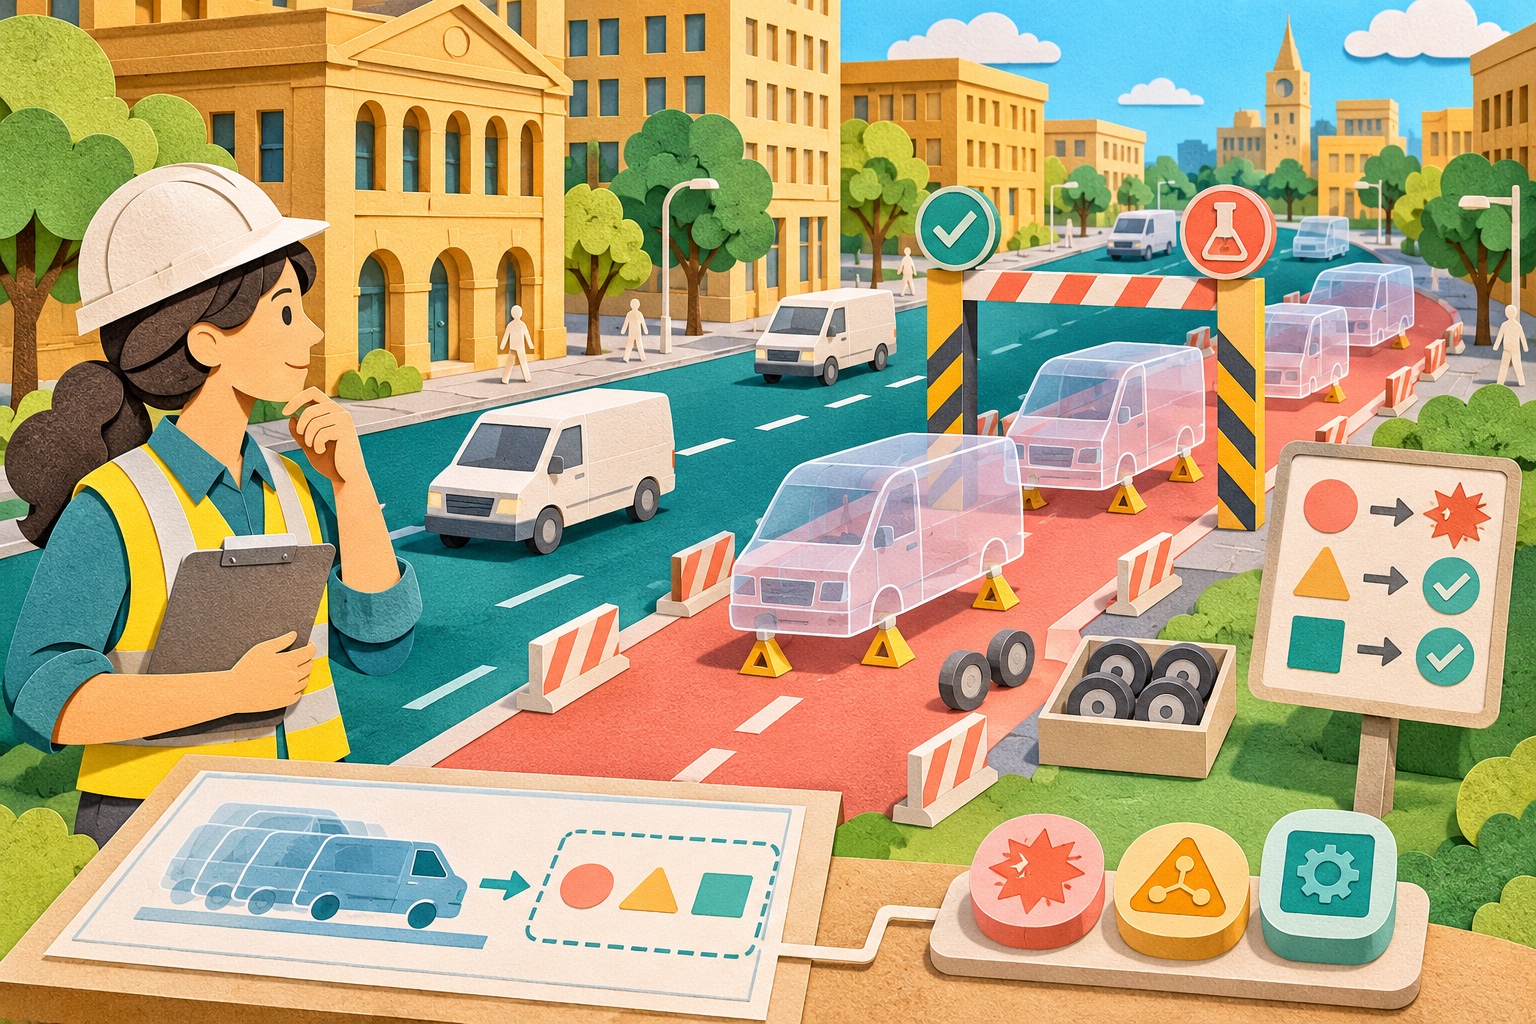
A green unit-test suite can tell you that a new build behaves correctly on the cases someone thought to write. It cannot tell you whether a refactor still handles the strange requests that actually arrived last Tuesday. AWS has published a practical pattern for closing that gap: capture a bounded sample of real requests, replay them against candidate code, compare selected business outputs, and make the comparison a deployment gate. The pattern is useful precisely when treated as a narrow regression detector—not as a replacement for tests or a license to send duplicate writes into production. [1]
The framework separates four jobs. A capture layer records inputs and corresponding production outputs. A replay worker sends the same requests to a pre-production version. A comparison step reduces both responses to fields that represent the business decision and computes a match fraction. Finally, an orchestrator reports that fraction to the release pipeline, where an alarm can hold promotion below a chosen threshold. AWS demonstrates this using DynamoDB Streams, Lambda, Step Functions, CloudWatch, SNS and SQS, but emphasizes that capture can sit at API, service, database or queue boundaries. [1]
The dangerous part is not the comparison
The moment a replayed request can charge a card, reserve inventory, send a notification or mutate customer state, “test traffic” has become a second execution of a real action. The reference design tags every replay with a simulation identifier. Stateful code must recognize that marker and suppress writes or route them to isolated state. Randomized behavior needs deterministic seeds; otherwise two valid outcomes can appear to be a regression. Rate limits and reserved concurrency cap load on the test environment. These are core correctness controls, not optional polish. [1]
Comparison needs equal care. Raw response equality is usually noisy: timestamps, generated identifiers, ordering and downstream formatting can differ without changing the decision a user cares about. Reduce each response to the domain result, normalize harmless variation, and compare only that result. A pricing engine may compare the chosen price and eligibility reason; it should not compare request IDs or response timing metadata. If the projection discards a field that matters, the gate can pass a real defect. If it includes unstable fields, harmless changes can block releases.
What the new pattern does—and does not—prove
The AWS post reports more than six months of use in one system, five regressions caught and zero false-positive blocks there. Those are the authors’ experience, not a universal benchmark. Its sample 99.9% match threshold is an operational choice, not a safety guarantee. A replay set only represents captured inputs; it may miss rare paths, newly introduced behavior, concurrency interactions and state transitions the capture window did not include. The article explicitly positions replay as “no-impact” regression detection, not a test of new business logic. [1]
Start with a stateless, deterministic component such as a validation or pricing function. Capture complete context—including feature flags, regional configuration and any session state the function reads. Replay at a small traffic fraction, inspect mismatches manually, then automate the gate only after the comparison semantics are trusted. Stateful workflows need an explicit simulation boundary and idempotency strategy before replay is enabled. For external calls, prefer stubs or isolated providers; a marker that only one service honors is not enough.
The broader lesson is that production-shaped tests require production-shaped inputs and test-shaped effects. Replaying history can expose edge cases synthetic fixtures never captured, but only when the system can distinguish observation from action. Build that boundary first; then decide whether a match fraction belongs in the release decision.
For related engineering context, see our guides to aws step functions agent tools and rate limiting strategies token bucket sliding window.
Questions engineers should answer first
Can replay testing replace integration tests? No. It checks whether selected existing inputs retain selected existing outputs. It does not establish that new features meet requirements or that uncaptured inputs behave correctly.
How do I keep replay from repeating a payment or email? Carry an explicit simulation ID through every side-effecting boundary and suppress or isolate mutations. Verify the full path; do not assume a gateway header automatically protects downstream consumers.
What should the gate compare? A stable, domain-specific projection of the response. Exclude incidental values such as timestamps, but preserve every field whose change could affect a customer or business decision.
Frequently asked questions
Which systems are good candidates for replay?
Deterministic, computation-heavy components such as pricing or validation are easiest to compare because replay does not repeat customer-visible writes. Stateful services need explicit simulation markers and side-effect suppression before replay is safe.
Does a 99.9% match rate prove a release is safe?
No. A match threshold is a chosen gate over the captured requests and selected output fields. It cannot prove behavior for uncaptured inputs or new business requirements; review mismatches and retain ordinary tests and monitoring.
Sources & further reading
Keep reading
Cloud Pathways Keeps TPU Jobs Alive When a Slice Fails
Google Cloud’s GA Pathways runtime uses one controller across TPU slices and can reshard training after a host interruption.
GitHub Adds API Controls for AI Scan—but Enabling It Does Not Run a Scan
New public-preview REST settings let teams govern AI Scan coverage across repositories. Policy inheritance, 422 errors and credits still shape rollout.

Traffic Engineering at the Boundary: Load Balancers, Gateways and Reverse Proxies
How Layer 4 and Layer 7 balancers, edge API gateways, and reverse proxies coordinate to shape, authenticate, and distribute web-scale traffic.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.