
Cloud Pathways Keeps TPU Jobs Alive When a Slice Fails
Google Cloud’s GA Pathways runtime uses one controller across TPU slices and can reshard training after a host interruption.
On this page
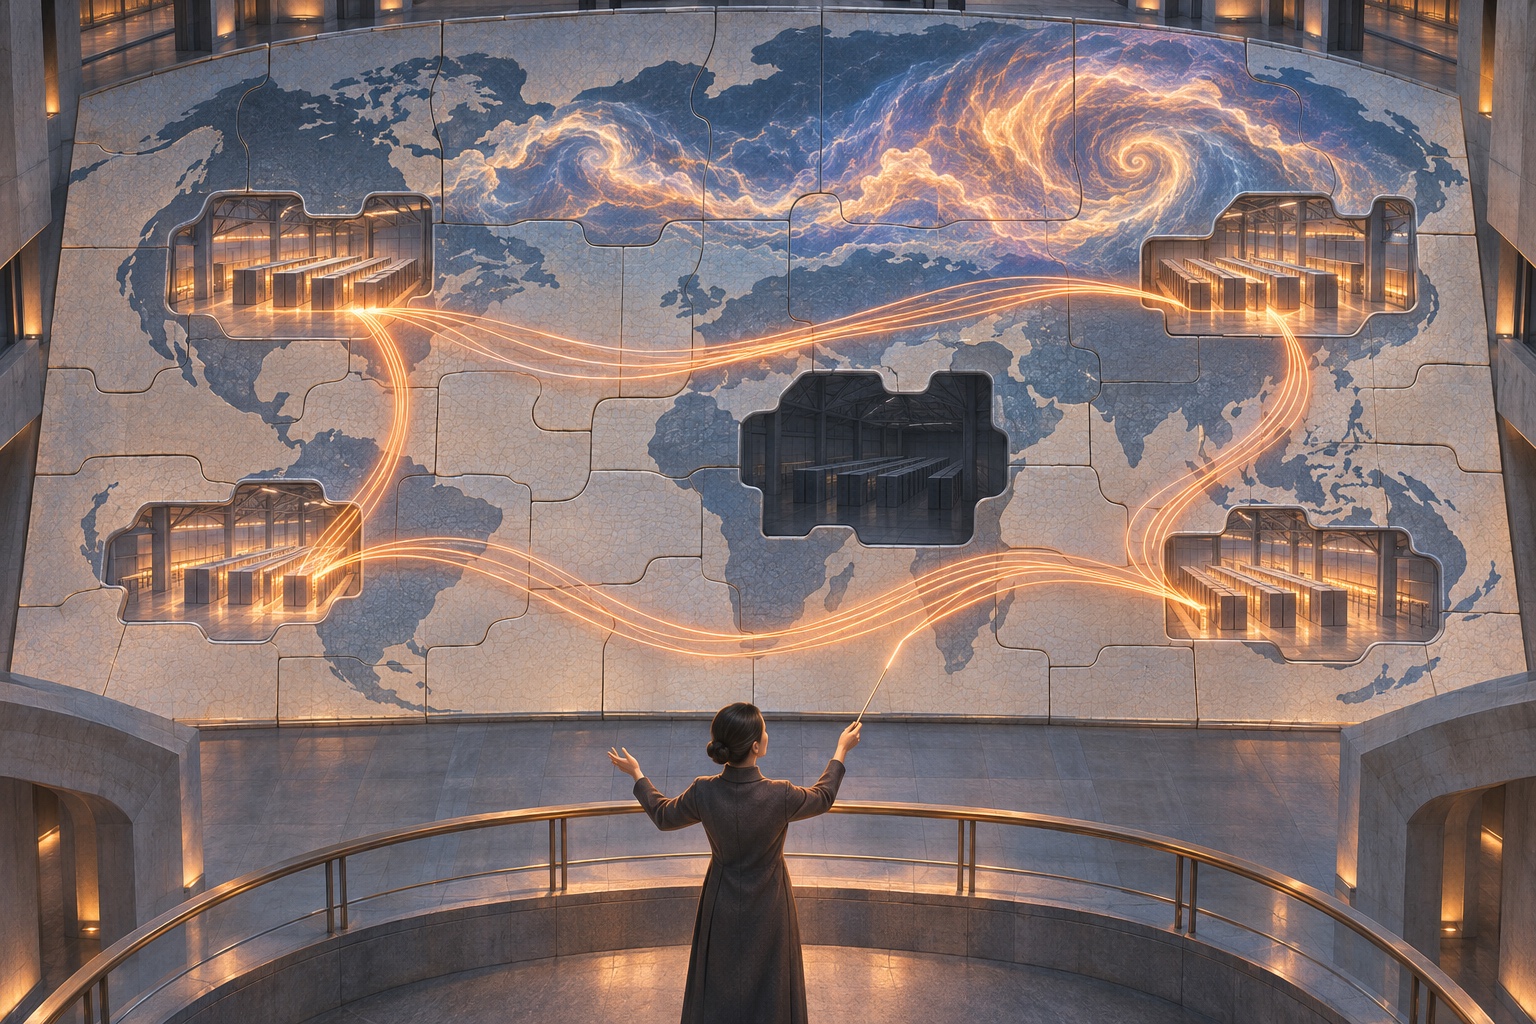
A multi-day training job can lose more time to interruptions than to slow kernels. A TPU slice may disappear, maintenance may take a host out of service, or a distributed job may need to resize around available capacity. Google Cloud’s Cloud Pathways release targets this coordination problem: one JAX client controls multiple TPU slices, while elastic training snapshots host memory and reshards work after a slice interruption instead of forcing the client to restart from scratch. The service became generally available on GKE on November 9, 2026. [1]
The core change is architectural. Traditional distributed setups often use several controllers, each responsible for a subset of accelerators. Cloud Pathways uses a single controller built on the open-source Interim Framework Runtime (IFRT). Setting JAX_PLATFORMS=proxy with pathwaysutils lets one client process orchestrate many TPU slices as though they were a single large system. Colocated Python sidecars run data loading and checkpointing logic on TPU hosts; persistent compilation caching avoids repeating some compilation work; asynchronous XLA dispatch helps overlap host coordination and device execution. [1]
Recovery by changing the mesh
Elastic training’s useful trick is not pretending a failure did not happen. The runtime uses host-memory snapshots and can dynamically resize a job to N−1 slices after hardware interruption, then remesh the workload across the surviving topology. That can preserve the training client and reduce wasted progress, but recovery still has a cost: the system must restore state, redistribute data and model shards, and continue at reduced capacity. A fault-tolerant job is not an uninterrupted or free job.
This behavior is especially relevant to workloads where restarting a huge run is expensive and a temporary capacity reduction is better than losing all progress. It also changes scheduling assumptions: a platform team needs to understand which workloads can shrink, whether the batch size or parallelism remains valid, how throughput changes, and what happens if repeated failures continue. These are measurable service-level questions, not properties that follow automatically from the word “elastic.” [2] [3]
Google says Cloud Pathways is generally available in regions supporting TPU v5e, v5p, Trillium v6e and Ironwood TPU 7x on GKE, with versioned images supporting JAX 0.10.1 or later. It is also in preview on Slurm TPU clusters through Cluster Director. The release post cites workloads across very large fleets and quotes a customer using host snapshotting for recovery; those deployment figures and outcomes are vendor-published examples, not independent performance benchmarks. [1]
What teams should measure
Compare more than peak accelerator utilization. Record time to recover from a lost slice, training progress lost per failure, throughput before and after remeshing, checkpoint cost, compilation time and job completion rate. Inject representative failures in a controlled test, including planned maintenance where possible. Validate that a changed mesh preserves numerical behavior within the tolerance your training process accepts.
A single controller can simplify orchestration, but it also concentrates responsibility. Teams should inspect controller availability, observability, recovery semantics and the boundary between job state in host memory and durable checkpoints. Host snapshots are valuable for rapid elasticity; durable checkpoints remain essential for recovery from broader process or cluster failures. Understand exactly which state survives which fault.
For research groups, interactive mode lets engineers inspect and debug JAX workloads from a notebook or terminal, while Shared Pathways Service offers a long-running pool that multiple users can access. Those conveniences do not remove resource governance: shared accelerator pools still need quotas, fair scheduling and clear ownership of failed or abandoned jobs.
For related engineering context, see our guides to kubernetes pod lifecycle api server to etcd cleanup and latency vs throughput tail latency tuning. What is Cloud Pathways? A distributed ML runtime for orchestrating large TPU fleets from a single JAX controller, available on GKE.
Does it prevent training interruptions? No. It is designed to recover from some slice interruptions by reshaping a job around remaining capacity. Recovery time and reduced throughput still matter.
Is it available on every TPU setup? Google lists GA availability on GKE regions supporting specified TPU generations; Slurm through Cluster Director is described as preview.
Frequently asked questions
What happens when one TPU slice fails?
Cloud Pathways uses host-memory snapshots and elastic resharding to continue some jobs with N−1 slices. The job can still lose throughput and spend time restoring and remeshing state.
Where is Cloud Pathways generally available?
Google lists GKE regions that support TPU v5e, v5p, Trillium v6e and Ironwood TPU 7x, with JAX 0.10.1 or later. Check current regional documentation and quota before planning capacity.
Sources & further reading
Keep reading
Replay Production Traffic Before Release—But Make Side Effects Impossible
A new AWS reference pattern replays sampled production requests against candidate code. The hard part is isolating writes and comparing the right outputs.
GitHub Adds API Controls for AI Scan—but Enabling It Does Not Run a Scan
New public-preview REST settings let teams govern AI Scan coverage across repositories. Policy inheritance, 422 errors and credits still shape rollout.

Traffic Engineering at the Boundary: Load Balancers, Gateways and Reverse Proxies
How Layer 4 and Layer 7 balancers, edge API gateways, and reverse proxies coordinate to shape, authenticate, and distribute web-scale traffic.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.