
Deepgram's Trainium Port Shows Why Inference Cost Depends on the Whole Stack
Deepgram and AWS report 11–70% more offline transcription per dollar on one Trainium2 setup. The kernels, runtime and workload explain the narrow result.
On this page
“Which accelerator is cheaper?” sounds like a hardware question, but Deepgram’s October 19 Trainium case study makes the answer look more like a software-stack question. The teams did not simply move a model checkpoint from one instance type to another. They ported Nova-3, replaced and tuned kernels, profiled bottlenecks, then built a Rust runtime to drive multiple model replicas. For the offline transcription workload they tested, AWS says the result processed 11–70% more audio per dollar than Deepgram’s prior compute options.
The workload boundary matters
The case study is specifically about offline, throughput-oriented batch work such as contact-center analytics and medical transcription. In this setting, a system can accumulate jobs, keep accelerators busy and optimize how many audio hours it processes per unit cost. A live voice agent has a different objective: it may need low and predictable response latency, tolerate less queueing and operate under strict concurrency patterns. The published result does not show that interactive speech workloads receive the same benefit. [1]
The hardware configuration was also specific: eight model replicas on one EC2 trn2.3xlarge instance. AWS says it compared audio processed per dollar using instance prices at the time of evaluation. The article does not provide a universal cross-provider benchmark across identical software, regions, utilization and service levels, so the percentage range should remain attached to the tested setup. [1]
The engineering work behind the price-performance result
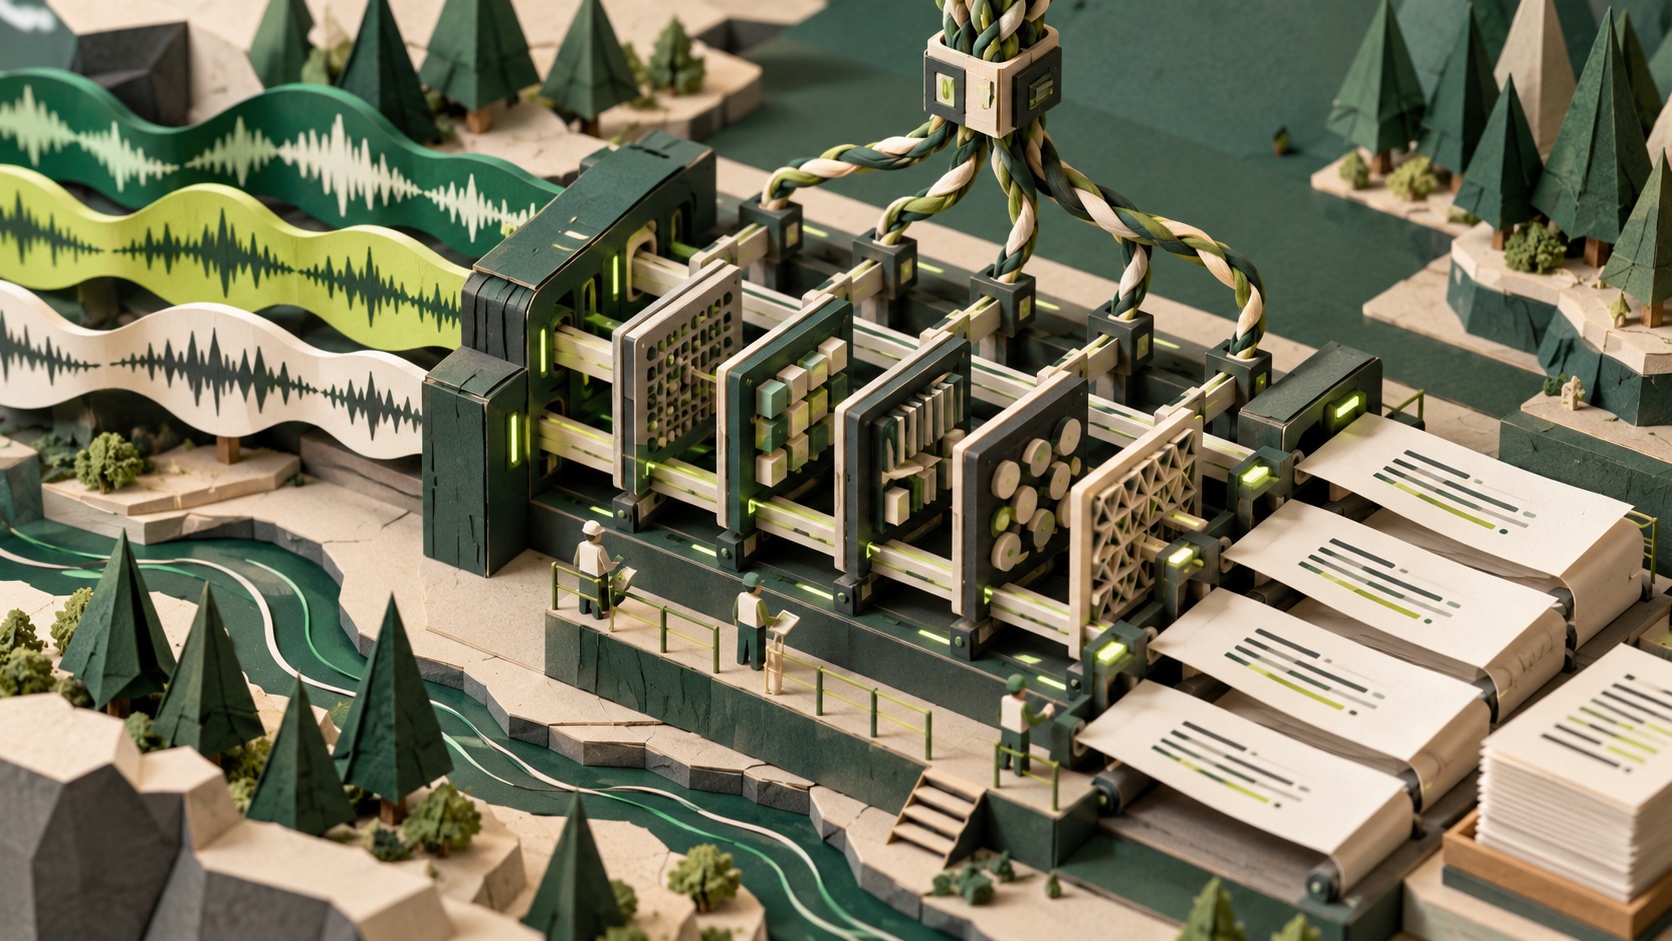
The teams started with Nova-3 as standard PyTorch code, then ported the model to AWS’s Neuron software stack. They replaced some layers with pre-built kernels from Neuron Kernel Interface Library and measured performance using Neuron Explorer. After profiling, they adapted kernel source code. A lightweight Rust data-parallel runtime calls the Neuron Runtime API so Deepgram’s own model server can schedule work on the accelerator. [1]
This sequence matters because model-level throughput is the product of more than peak chip speed. Unsupported operators, inefficient tensor layouts, CPU scheduling, data movement and batch formation can erase theoretical gains. A tuned kernel may improve one layer but leave the pipeline bound elsewhere. Profiling tells a team which part is actually limiting the job before it invests in a port.
Neuron’s documentation describes the compiler, runtime, framework integrations and kernel tooling needed to target supported AWS accelerators. The NKI guide provides a path to custom kernels, while EC2’s instance documentation defines the available hardware configuration. None of that implies an unchanged PyTorch model will attain the case-study result by default. [2] [3] [4]
How to evaluate a similar migration
First separate workloads by service objective. Group offline jobs by model, audio duration, batch size and latency allowance. For real-time inference, track tail latency, streaming behavior and capacity under bursts; for batch processing, track completed audio hours per dollar and backlog drain time. Do not combine them into one “inference cost” number.
Then establish a reproducible baseline. Use the same audio corpus, model version, decoding settings and quality checks on both platforms. Measure preprocessing, inference, postprocessing and transfers as one end-to-end job. Include idle time, host CPUs, storage and the software work required to operate the stack. Validate that transcription quality remains acceptable; faster inference is not useful if it changes accuracy or formatting beyond the application’s tolerance.
Finally, calculate total cost at the utilization you can sustain. A device that wins at a saturated batch can lose when request volume is low or jobs arrive irregularly. Include engineering time, monitoring, autoscaling, retries and deployment complexity. Keep the price list date and region with the result, since accelerator prices and availability change.
The lesson is optimization, not a universal winner
Deepgram’s result is compelling because it describes the work required to make a different accelerator useful: port, profile, tune, schedule, then compare the complete workload. It gives other inference teams a concrete evaluation path, but it does not settle which chip is best for every model or latency target. Start with a workload-specific benchmark and count every layer between the audio file and the finished transcript.
For more on serving tradeoffs, see our analysis of GPU cluster bandwidth and the economics of accepted LLM work.
Frequently asked questions
Did Trainium make every Deepgram workload 11–70% cheaper?
No. AWS reports that a particular offline, throughput-oriented Nova-3 batch setup processed 11–70% more audio per dollar than compute options Deepgram had been using, based on instance prices at evaluation time.
What had to change to run Nova-3 on Trainium2?
The teams ported PyTorch code to the AWS Neuron stack, substituted and tuned kernels, profiled performance, and built a Rust data-parallel runtime that called the Neuron Runtime API.
Is this directly comparable with live speech recognition?
Not from the published result. The case study focuses on offline batch workloads, where throughput and utilization can be prioritized differently from low-latency interactive transcription.
Sources & further reading
Keep reading
Why LLM Serving Teams Are Turning KV Cache Transfer Into a First-Class Design Choice
Two new vLLM transfer techniques target first-token latency by overlapping movement and reusing multi-turn context. See where each helps and what it costs.
Claude Structured Outputs on Bedrock Can Enforce Shape, Not Business Truth
Bedrock adds schema-constrained Claude output, but route and model support vary and valid JSON still needs domain validation.
GitHub’s SSH Brownout Starts Nov. 4: Check the Client Before Replacing Keys
GitHub is phasing out older SSH signatures and key exchange; distinguish RSA key files from the SHA-1 signature algorithm before changing access.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.