
How Grab Built a Vision Model for Southeast Asian Document Processing
Grab’s account shows why synthetic multilingual OCR data and full-model tuning beat a LoRA-only path for its document tasks.
On this page
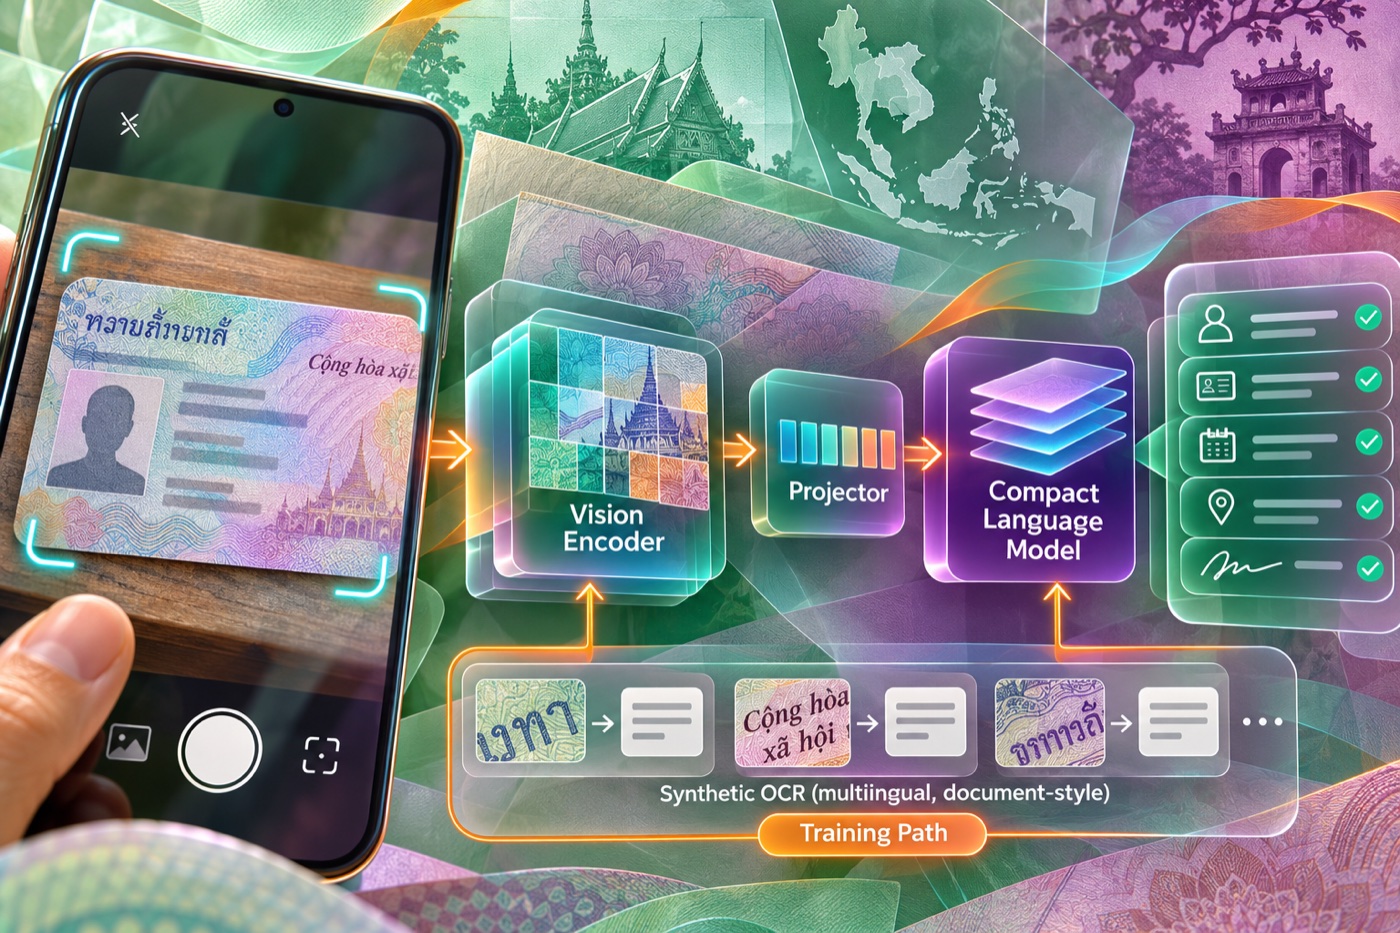
Document extraction is often presented as a choice between a traditional OCR engine and a general-purpose vision-language model. Grab’s engineering account shows why that comparison can be too simple for identity-document workflows: language coverage, layout variation, image resolution and the reliability of extracted fields all matter together.
The company describes a document-processing effort for Southeast Asian formats and languages. It first evaluated several open vision-language models and selected Qwen2-VL 2B as a base. Grab says its early results were limited by language coverage, so it built training data and changed the model rather than treating prompt tuning as the only control.
This is Grab’s report of its own experiments. The numerical results below are company measurements on its document tasks, not a general OCR benchmark or an independent comparison of all commercial APIs. [1]
Why the first fine-tuning pass was not enough
A vision-language model typically combines an image encoder, a projector that maps visual features into the language model’s space, and a language decoder. [2] Grab chose Qwen2-VL partly because it supports dynamic image resolution, which can preserve text detail that a fixed resize might erase.
The team’s first adaptation experiment used LoRA, a parameter-efficient fine-tuning method. [3] Grab reports strong field-level accuracy for Indonesian documents, while noting continued difficulty with Thai and Vietnamese scripts and with small, dense text. The failure was instructive: a low-cost update to model weights did not supply visual language examples that the base model had not learned well enough.
Synthetic OCR data supplied missing visual examples
Grab describes generating synthetic text images from a large online text corpus. The pipeline rendered Bahasa Indonesia, Thai, Vietnamese and English text with varied fonts, backgrounds and augmentations. This let the team create visual training examples for scripts and conditions that were underrepresented in its initial data.
The next experiment fully fine-tuned the vision encoder, projector and language model on task-specific document data. Grab reports Thai accuracy increasing 70 percentage points and Vietnamese accuracy increasing 40 points versus its baseline. The publication does not give an independent audit of the benchmark or make these results transferable to other document sets, so the figures need to stay attributed to Grab.
Building a smaller model around the task
Full tuning the 2B model put pressure on GPU resources. Grab then describes assembling an approximately 1B-parameter model from the Qwen2-VL 2B vision encoder, Qwen2.5 0.5B language decoder and an adjusted projector.
Its training process had four stages: align the projector; improve the vision tower with public multimodal data; train on language-specific synthetic OCR images; and fine-tune the full model on curated document examples. Grab says the custom model remained within three percentage points of the 2B model across most document types while using a smaller model. That comparison is useful as a design case, not proof that smaller custom models always outperform general systems.
The engineering takeaway
The important work was the data and evaluation loop as much as the model assembly. Teams can start by measuring field-level errors by language, script, document type and image condition. That identifies whether the limiting factor is visual representation, training examples, resolution handling or extraction logic.
Then compare parameter-efficient and full-model tuning against the same held-out data, including hard non-Latin and dense-layout examples. Track latency and compute alongside extraction quality. Grab’s write-up illustrates a disciplined sequence: measure the failure, create targeted visual data, expand training only where needed, and validate the smaller architecture against the actual task.
Evaluate the field, not just the model answer
Document extraction quality should be measured at the field level. A model can produce a plausible whole-document summary while transposing an identification number or missing an expiry date. For onboarding, teams need separate measures for each field’s precision and recall, plus document-level rejection and correction rates.
Split evaluation by document template and capture condition, not only by random image. Otherwise near-duplicate layouts from the same source can appear in both training and test sets, making generalization look stronger than it is. Include difficult scripts, glare, skew and low-resolution samples, then measure latency percentiles and compute cost alongside accuracy.
Training images and user documents also have different privacy implications. Synthetic samples reduce the need to expose real documents during some training tasks, but fine-tuning still uses curated task data. Access controls, retention and redaction decisions remain necessary. For consequential verification, an extraction score should route uncertain fields to a review path rather than silently converting a model guess into a confirmed identity fact.
Frequently asked questions
Why was a general OCR model not enough for Grab’s documents?
Grab says its task involved document templates and Southeast Asian languages that its initial open models handled poorly, particularly non-Latin scripts and dense layouts. The post describes this as the motivation for task-specific training.
What did LoRA improve, and where did it fall short?
In Grab’s experiment, LoRA fine-tuning Qwen2-VL 2B performed well on Indonesian documents, but struggled with non-Latin scripts such as Thai and Vietnamese and with small, dense text.
How did the custom model differ from the 2B base model?
Grab combined the Qwen2-VL 2B vision encoder with the Qwen2.5 0.5B language decoder and an adjusted projector to create an approximately 1B-parameter model, then trained it in several stages.
Are the accuracy gains independently verified?
No. Grab reports Thai accuracy up 70 percentage points and Vietnamese up 40 points versus its baseline, and says the smaller model stayed within three points of the 2B model across most document types. These are company-reported evaluation results.
Sources & further reading
Keep reading
Cloudflare's Clairic Targets Document Extraction, Not Chat
Cloudflare's updated Clairic and compact 9B Clairic-flash extract typed fields from text, images and PDFs, with open weights now available.
OpenAI’s 200,000-Researcher Goal Turns AI Access Into a Grant-Design Question
OpenAI says 50,000 new researchers can apply for free ChatGPT Plus grants. The first-come model, usage limits and data terms deserve close reading.
OpenAI’s New CSAM Classifier Is a Triage Signal, Not an Automated Verdict
OpenAI offers a classifier to vetted child-safety organizations. Scores can prioritize review, but people remain responsible for decisions.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.