
Mistral's Le Chonk Is Open Weight. Running It Is the Next Test
Mistral released Large 4 weights with coding and security claims. Infrastructure, licensing and evaluation are part of the decision.
On this page
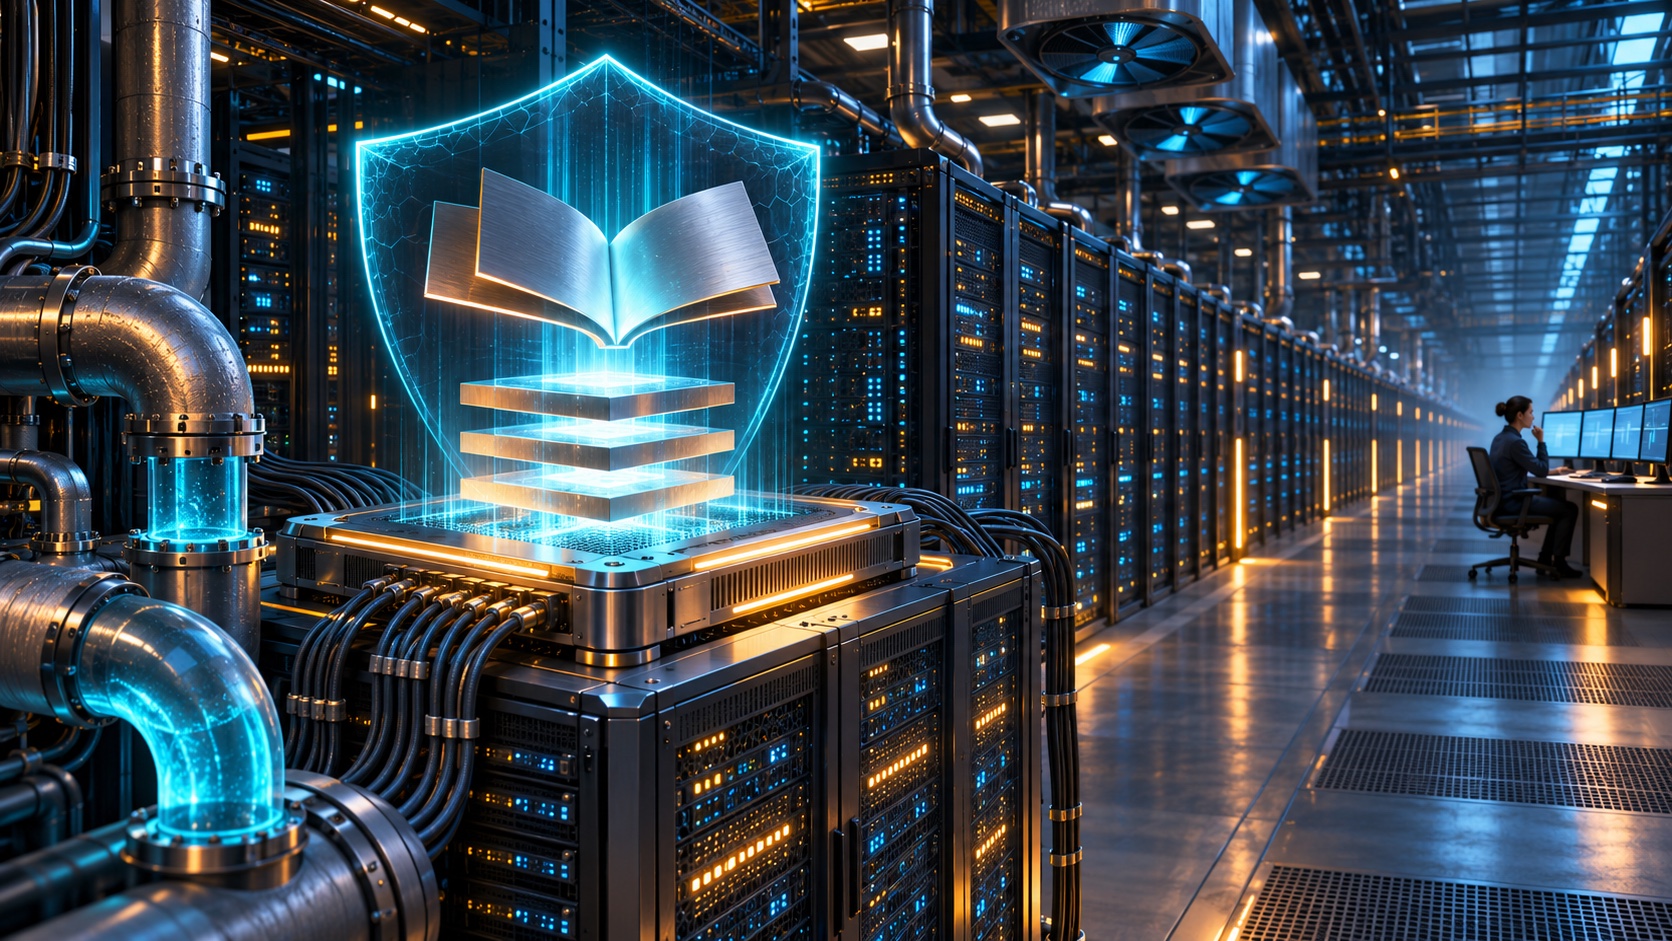
“Open” can sound like the end of a buying decision. For a large model, it is closer to the start. On October 29, Mistral published downloadable weights for Mistral Large 4, nicknamed Le Chonk, after an earlier public preview. That changes who can control where inference happens. It also asks buyers to price the hardware, hosting work, license terms and evidence needed to operate a model at this scale. [1]
What changed on October 29?
Mistral’s release post says the company made the improved Large 4 weights available after several additional weeks of reinforcement learning on the preview model. It describes a one-trillion-parameter, natively multimodal model and claims gains in coding, defensive cybersecurity and reasoning efficiency. The company positions the release as a leading open-weight option. These are vendor claims; they should be read alongside the published benchmark setup and independent evaluations, not as guarantees for a specific production task. [1]
The model card gives a more concrete shape: a mixture-of-experts design with 128 routed experts, four active per token, plus one shared expert. It accepts text and images and produces text, supports function calls and JSON output, and lists a one-million-token context window. “One trillion parameters” describes the full model, not the portion activated for each token. But the full checkpoint still matters for deployment: Hugging Face’s Transformers documentation says the FP8 version requires about one terabyte of GPU memory and uses multiple GPUs. [2] [3]
That makes the release useful to organizations that have a reason to run a large model under their own infrastructure and policies. It does not make the model a lightweight download that can be put on a spare workstation. The official card recommends vLLM and shows tensor parallelism across eight GPUs in its example configuration. Actual needs depend on precision, quantization, throughput, context length and serving stack, so the example is a starting point rather than a universal bill of materials. [2]
Control moves from provider choice to operating responsibility
Self-hosting can change the data path. A company may keep prompts and outputs within its chosen cloud or data center, set its own access controls and schedule updates on its terms. Teams can inspect the weights, adapt them and select among serving frameworks. These choices can matter for regulated workloads, sensitive source code or organizations that need a particular jurisdictional arrangement.
The same choice transfers work to the operator. Someone must secure model files, provision and monitor accelerators, handle capacity planning, patch the inference stack, log failures and respond to misuse. A model running in the organization’s account does not automatically meet its privacy, retention or security policy. Those properties come from the full deployment and its contracts, not from the word “open.”
License details also matter. Mistral’s model card identifies the Mistral Ecosystem Open-Weight License, a modified MIT-style license permitting commercial and non-commercial use under its terms. It specifically says that businesses operating a model-as-a-service offering need a separate commercial license. A company fine-tuning the model for internal use and a cloud platform selling access to third parties may therefore face different obligations. Legal and procurement teams should review the actual license against the planned service before launch. [2]
A benchmark lead is a hypothesis to reproduce
Mistral’s card reports a 48% score on the Artificial Analysis Coding Agent Index, effectively tied with the leading open-weight model in its comparison, while using 47% fewer tokens per task on average. The card says the model scores 26 on the Artificial Analysis Intelligence Index v5 and notes that the leading open-weight models from China score higher on that aggregate measure. These figures are more informative than an unqualified “best” label, but they remain snapshots from specified evaluations and vendor-published results. [2]
Token efficiency is not the same as lower total cost. A team should measure accelerator time, memory, queueing, retries, supervision and the cost of correcting wrong answers. Coding benchmarks can reward task completion while missing a company’s testing standards, secret handling, dependency policies or reviewer preferences. Cybersecurity claims need the same care: a model that can identify and explain a vulnerability can also be misused, while refusal behavior and monitoring vary by deployment.
Before selecting it, run a representative bake-off. Use tasks your team actually handles, keep prompts and tools fixed, compare against the current model, and have reviewers score correctness, security, editability and time to accepted result. Include failure cases and sensitive-input controls. Record the hardware and inference settings so a promising score can be repeated after model or serving-stack updates.
Who should pay attention?
Le Chonk is most relevant to teams that already have GPU operations, a strong reason to control the inference environment and a workload where its coding, vision or long-context functions might justify the cost. The available deployment path through frameworks such as vLLM and SGLang lowers integration friction, but does not remove capacity engineering. The model’s European training and hosting story may matter to buyers evaluating data location; organizations still need to verify the specific service boundary and contractual commitments they would use. [2]
For a smaller team without GPU infrastructure, a hosted API may be simpler. For a service provider that intends to resell inference, license terms need early review. For security teams, evaluation must cover both defensive utility and safeguards against misuse. Those questions make the operational model as important as the model’s benchmark position.
Crashtech has also examined how formal verification can constrain an AI coding agent and how foundry design kits mark a process milestone. Large models can assist with increasingly consequential work, but human review, measurable acceptance criteria and accountable system design remain part of the product.
Openness is a deployment option, not an outcome
Mistral Large 4’s weight release expands the set of ways organizations can use the model. It brings code, model parameters and deployment choices into the buyer’s hands while leaving costs, license scope, performance and safety to be established in context. The sensible next step is not to infer that every organization should host it. It is to ask whether local control solves a real constraint, then test whether the full cost and responsibility are worth carrying.
Frequently asked questions
What is Le Chonk?
Le Chonk is Mistral's nickname for Mistral Large 4, a natively multimodal mixture-of-experts model with about one trillion total parameters and roughly 49 billion active per token, or 52 billion including embeddings and output layers.
Can a company use Mistral Large 4 commercially?
The published Mistral Ecosystem Open-Weight License permits commercial and non-commercial use subject to its terms. Operating a model-as-a-service business requires a separate commercial license from Mistral; review the license for the intended use.
Does open weight mean a company can run the model cheaply on one server?
No. The official model card recommends multi-GPU serving, and Hugging Face's Transformers documentation says the FP8 checkpoint needs about one terabyte of GPU memory. Quantized versions and deployment choices change requirements, but teams still need to benchmark cost and reliability on their own hardware.
Sources & further reading
Keep reading
When an AI Agent Visits Your Website, Who Is Accountable?
Personal agents can hide the person behind a request. Learn what site owners can measure today and what identity, consent, and accountability still require.
Intel's Cognitive-City Pitch Has a Hard Test: Who Gets to Act?
Intel’s city AI vision moves beyond sensors to action. Interoperability and public accountability determine whether the shift serves residents.
Nemotron 3.5 Transcribe brings instruction-led speech work on-device
NVIDIA’s open-weight speech model transcribes, translates and attributes speakers offline. Its hardware demands make local ownership a tradeoff.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.