
OpenFold3 on SageMaker: A Managed Endpoint Does Not Validate a Protein
AWS packages OpenFold3-preview for asynchronous, multi-GPU structure prediction. Here is what deployment simplifies—and what confidence scores cannot establish.
On this page
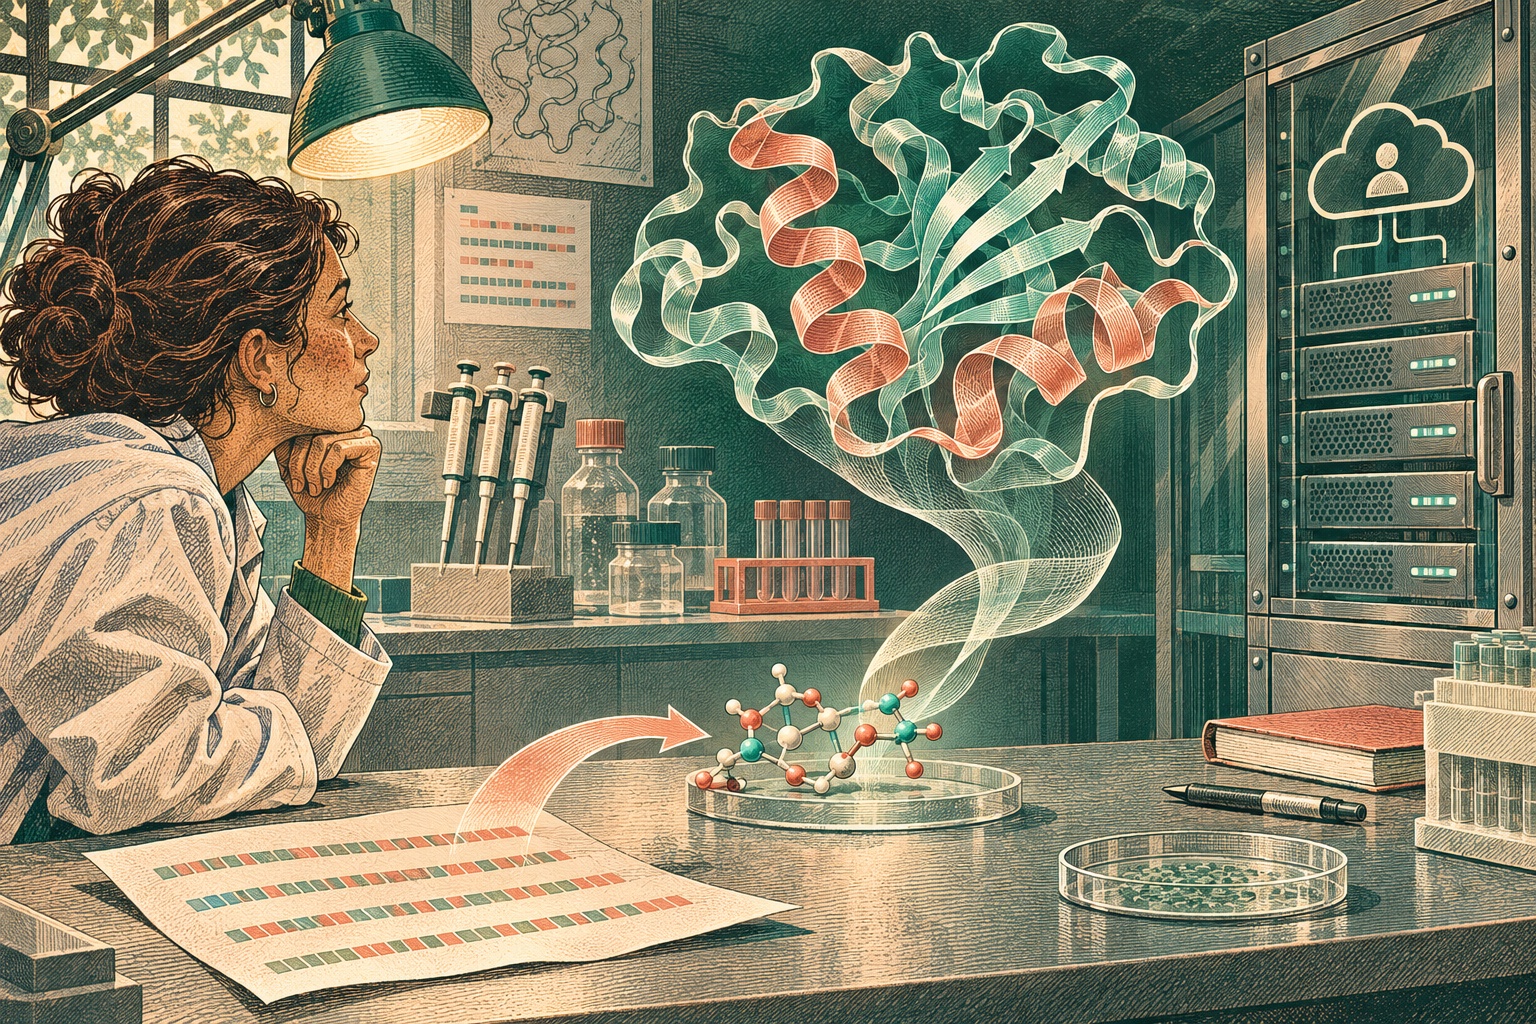
A structure-prediction model can turn a molecular sequence into a useful hypothesis. Getting that model to run reliably is a separate engineering problem: GPU drivers, large checkpoints, requests that take minutes, parallel jobs and private sequence data all complicate a prototype. AWS’s November 13 guide packages OpenFold3-preview as a SageMaker JumpStart endpoint, with asynchronous inference, multi-GPU options and the ability to scale the endpoint to zero when idle. The convenience changes how a team operates the model; it does not turn a predicted structure into experimental evidence. [1]
OpenFold3 predicts all-atom structures from protein, DNA and RNA sequences, plus small-molecule ligands supplied as SMILES. It supports complexes across these molecule types and returns mmCIF structures with confidence metrics such as pLDDT, PAE and PDE. AWS identifies the deployed checkpoint as OpenFold3 0.4.1, of3-p2-155k, and the JumpStart model ID as huggingface-proteinfolding-openfold3. The project is developed by the OpenFold Consortium and AlQuraishi Lab at Columbia, and is distributed under Apache 2.0 according to the deployment guide. [1] [2]
Why asynchronous inference is the right shape
Protein prediction is not a chat completion. Jobs can occupy a GPU for minutes, produce sizable coordinate files and require substantial memory. An asynchronous endpoint lets a caller submit a job, retrieve its result later and avoid holding a synchronous web request open for the entire computation. Multi-GPU instances allow parallel prediction workflows; custom multiple sequence alignments (MSAs) can be supplied as additional evolutionary context. Teams can keep inference in their AWS account with network isolation, but they still need to examine IAM, storage, logs, artifact retention and access boundaries for their own deployment. [1]
A managed endpoint also has a deceptively simple cost trap: it bills for the instance while running, including idle periods. AWS’s guide explicitly advises deleting the endpoint or configuring scale-to-zero. That means cold-start behavior and queue latency belong in the system design. For an intermittent research workflow, scale-to-zero may save compute charges while adding startup delay; for a continuously used service, warm capacity may be more practical. Measure your own arrival pattern before choosing.
Confidence is a guide for inspection
The model’s confidence measures describe aspects of its prediction, not whether a molecule will behave as predicted in a cell, bind a target, fold under a particular condition or support a therapeutic claim. A high local confidence score does not erase uncertainty in flexible regions, complexes or biological context. Structure prediction should help researchers prioritize experiments and generate hypotheses; it is not a substitute for validation by appropriate methods.
The deployment guide demonstrates plotting an output with py3Dmol and using the confidence fields. That is a useful first inspection, but a production research workflow should preserve input sequences, model version, checkpoint, parameters, MSA provenance, output files and confidence summaries together. Without this record, a structure cannot be reliably reproduced or compared. The open project’s code and published methods give teams more inspectability than a black-box endpoint, while the managed container trades some deployment toil for reliance on AWS’s packaging and service lifecycle. [2] [3]
A practical evaluation should begin with a set of proteins whose experimental structures are already known, while guarding against leakage between evaluation and tuning. Compare the predicted coordinates and confidence patterns using domain-appropriate metrics, then test whether the model improves a concrete research decision. Do not choose a GPU size from a sample notebook alone: runtime, memory pressure, queue depth and concurrent jobs vary with sequence length and complex size.
For related engineering context, see our guides to deepmind alphafold protein structure prediction and rag architecture enterprise data ingestion vector search. What does OpenFold3 predict? It predicts all-atom 3D structures for proteins, nucleic acids, small molecules and combinations of them, and returns mmCIF plus confidence metrics. Predictions remain hypotheses.
Does SageMaker keep sequences private automatically? The guide describes network-isolated endpoints in the customer AWS account. Teams must still verify their account policies, logging, storage and access configuration.
Can a SageMaker endpoint scale to zero? The guide shows scale-to-zero options to reduce idle endpoint charges, with the operational trade-off of startup latency when a new request arrives.
Frequently asked questions
What does OpenFold3 return?
The documented JumpStart deployment returns predicted structures in mmCIF format together with confidence fields such as pLDDT, PAE and PDE. These outputs help prioritize inspection; they are not experimental confirmation.
Does scale-to-zero remove all endpoint cost?
It can reduce idle instance charges, but deployment, storage, requests and other associated resources may still incur cost. Cold starts also add latency, so confirm current SageMaker billing and lifecycle behavior for your configuration.
Sources & further reading
Keep reading
Rice’s Heat Q-Switch Stores a Steady Stream for a Brief Burst
Rice engineers built a fluidic device that stores heat as water flows, then releases a thermal pulse. The extra power comes from stored energy.
Waseda’s Photonic Transmitter Controls Reflections Without an Isolator
A silicon nitride and lithium niobate transmitter reached 180 Gbit/s without an optical isolator in a lab experiment.
JWST’s New Exoplanet Image Shows What Better Glare Models Can Reveal
FLIP uses a physics-based model to subtract starlight from JWST images, uncovering a faint planet while exposing the limits of computational recovery.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.