
Together Compiler Turns GPU Tuning Into a Continuous Inference Loop
Together’s compiler keeps an optimization engine running across inference experiments, trading setup time and throughput against fidelity and workload fit.
On this page
GPU inference tuning often means running many experiments: change a kernel, measure it, reject regressions and try again. Together’s Compiler aims to make that loop persistent, so an optimization system can spend less time restarting and more time searching. The promise is a faster engineering cycle, with the same familiar caveat: a good benchmark result must survive the workload that matters.
Keep the optimization loop alive
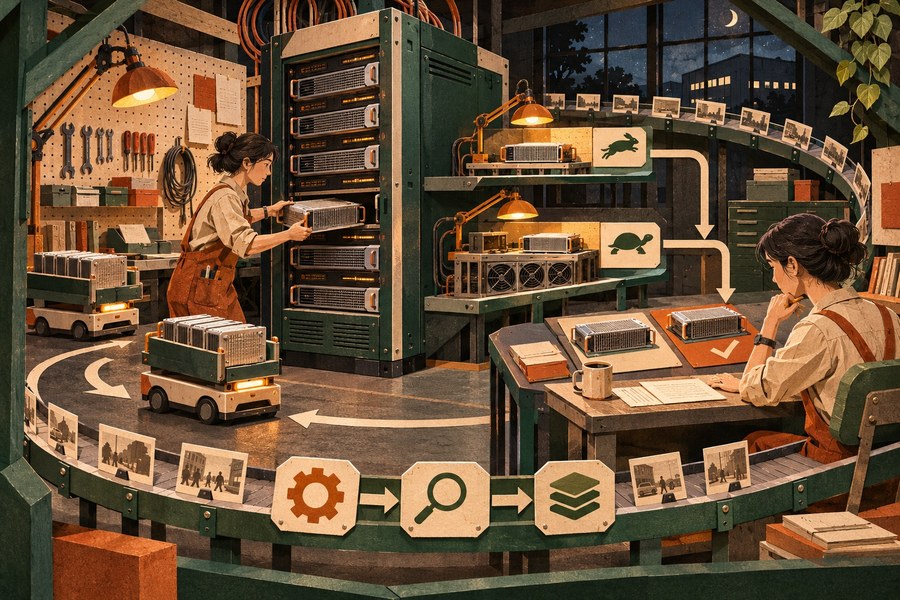
Together describes Compiler as a long-running runtime engine paired with agents that can explore low-level implementation changes. Instead of repeatedly starting and tearing down an environment, the system maintains state across experiments. The company reports reducing its engine startup comparison from 467 seconds to 9 seconds and claims up to 2.6 times higher tokens per second across four listed open models. It separately reports low-latency results on SemiAnalysis’ InferenceX benchmark. These are vendor-reported results. [1]
The reported improvement is not simply a compiler flag. The product combines experiment orchestration, code-generation or transformation work, execution and measurement. A persistent process can amortize setup costs and retain context about promising variants. That is especially valuable when each candidate takes time to compile, launch and profile.
The New Stack’s coverage situates the release in the broader push to automate GPU kernel optimization. It also highlights how this kind of tooling turns systems work into an iterative search problem rather than a one-time compilation step. [2]
Throughput is one part of the objective
Inference systems rarely optimize one number in isolation. Higher throughput may matter for batch workloads, while interactive services often care about tail latency. Memory footprint can determine how many model replicas fit on a device. Numerical changes can affect output quality, and a tuning process that consumes excessive compute may erase some of its operational gains.
Together’s post recognizes fidelity as part of the optimization trade-off and reports results under its own evaluation conditions. That framing matters: an optimized kernel should be judged not only by tokens per second, but also by correctness tolerances, output quality, stability and the cost of reaching the result. [1]
A benchmark number is easiest to interpret when readers know the model, accelerator, software versions, batch size, sequence lengths, precision and quality threshold. The company blog provides the headline result, but prospective users should inspect the benchmark details and reproduce them against their own serving stack before making a capacity plan.
Where a persistent compiler could help
A continuously available tuner may be useful when a team has a stable, expensive workload and enough repeated runs to justify searching. It can help explore configurations that would be tedious to test manually. The approach is less compelling if the model or serving constraints change constantly, if compilation overhead is already small, or if the engineering team cannot validate the generated artifacts.
The safe adoption path is incremental: hold a baseline fixed, run the tuned candidate on representative traffic or a faithful replay, and compare both performance and output quality. Keep a rollback path and record the exact hardware, compiler and model versions. A tuned result should remain reproducible rather than becoming an opaque production artifact. Teams can compare these concerns with our earlier coverage of KV-cache transfer and inference latency.
What to watch next
The interesting measure will be how the persistent search behaves across more models, hardware generations and production objectives. Public comparisons that report the full workload and quality constraints will make it easier to separate broadly useful compiler advances from a particularly favorable benchmark case.
For infrastructure teams, the thesis is practical: automation can shorten the tuning loop, but it does not choose the right objective on its own. The operator still decides which combination of speed, fidelity and cost is acceptable.
Frequently asked questions
What is Together Compiler?
Together describes it as a persistent AI inference optimization engine that uses agents to search for low-level GPU kernel and runtime improvements across repeated experiments.
Does the reported 2.6x speedup apply to every model?
No. It is a company-reported result on the workloads and benchmark setup described by Together. Results can vary with model, hardware, software stack, precision and service constraints.
Can optimization reduce output quality?
It can. Inference optimization often involves trade-offs among throughput, latency, memory use and numerical fidelity. A production team should test quality and reliability on its own workload before adopting a faster configuration.
Sources & further reading
Keep reading
Marvell’s Lumentum Deal Targets the Optical Links Inside AI Data Centers
The proposed $115 billion all-stock deal combines Marvell’s connectivity chips with Lumentum’s lasers and optics. Approval and integration remain years away.
Anthropic’s Message Threads Shrink Agent Requests, but Add State to Own
Anthropic’s beta API threads send only new turns, but expire quickly, require replay logic, and are not eligible for zero data retention.
A Light-Based AI Experiment Shows What Optical Computing Still Needs
A Tokyo team trained a physical learning system with optical dynamics. The result is promising, but it has not run today’s largest language models.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.