
topic: ai-technology
author: Crashtech Editorial
date: Oct 7, 2026 · read: 2 min
updated: October 8, 2026
---
BitNet b1.58: What Ternary Weights Change—and What They Do Not
BitNet trains with ternary weights to cut storage and arithmetic costs. Its results do not prove a universal energy multiplier or a 70B CPU-cache model.
On this page
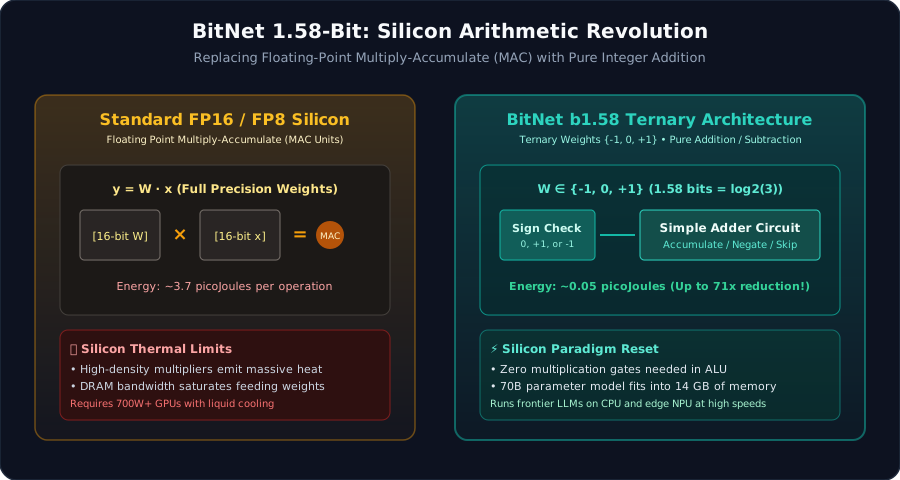
Conceptual architecture; arrows show relationships, not measured latency, energy or safety guarantees.
Why three values matter
An ideal encoding of three states needs approximately 1.585 bits per value. Multiplying an activation by a ternary weight becomes a sign change, an addition or a skipped contribution. The original architecture replaces linear layers with BitLinear and uses eight-bit activations. It still has other model operations; the entire transformer does not become a circuit containing only adders. [1]
Training must accommodate the quantizer. The forward computation uses quantized values while the optimization process retains higher-precision information. This differs from downloading an arbitrary dense checkpoint and rounding its weights after training.
What the original experiments establish
The 2024 paper reports comparisons at model sizes including 700M, 1.3B, 3B and 3.9B parameters. Its approximately 3B comparisons support the authors’ claim of competitive perplexity and task performance under the studied training configuration. They are not experimental proof that a 70B ternary model matches every 70B full-precision model. [1]
Quality depends on the training data, recipe and evaluation. A result on one benchmark does not certify an assistant for a different language, domain or tool workflow.
Weight storage is only part of memory
The following is an idealized arithmetic comparison for 70 billion weights, using decimal gigabytes:
| Encoding assumption | Weight bytes alone |
|---|---|
| 16 bits per weight | 140 GB |
| 4 bits per weight | 35 GB |
| log2(3) bits per weight | About 13.9 GB |
These are calculated lower-level storage figures, not measured runtime footprints. Packing, scales, embeddings, activations, KV cache and buffers also need memory. Roughly 14 GB is not the L3 cache capacity of an ordinary server CPU, and a machine with 16 GB RAM has little room left after loading that idealized weight payload.
Deployment still needs measurement
The Microsoft BitNet project provides specialized inference code. Check which checkpoints, processors and kernels the selected release supports. [2]
Measure peak memory, output quality, throughput and energy on the intended device. Report the model, precision, context length and workload beside any speedup. Ternary arithmetic opens a useful design space; it does not establish that every GPU workload immediately becomes a fast CPU or smartphone workload.
Frequently asked questions
Why is BitNet called 1.58-bit?
Three possible weight values require log2(3), approximately 1.585 bits, in an ideal encoding. Real model files also contain packing, scaling and other overhead.
Can any existing model be converted to BitNet?
The original b1.58 recipe trains with quantized weights. Its results do not imply that rounding an arbitrary pretrained model to ternary values will preserve quality.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.