
Google’s Flu Forecast Win Shows Why Public-Health AI Needs Calibration
CDC ranked a Google model first on one flu forecast score. Here is what that result says about accuracy, uncertainty and public-health planning.
On this page
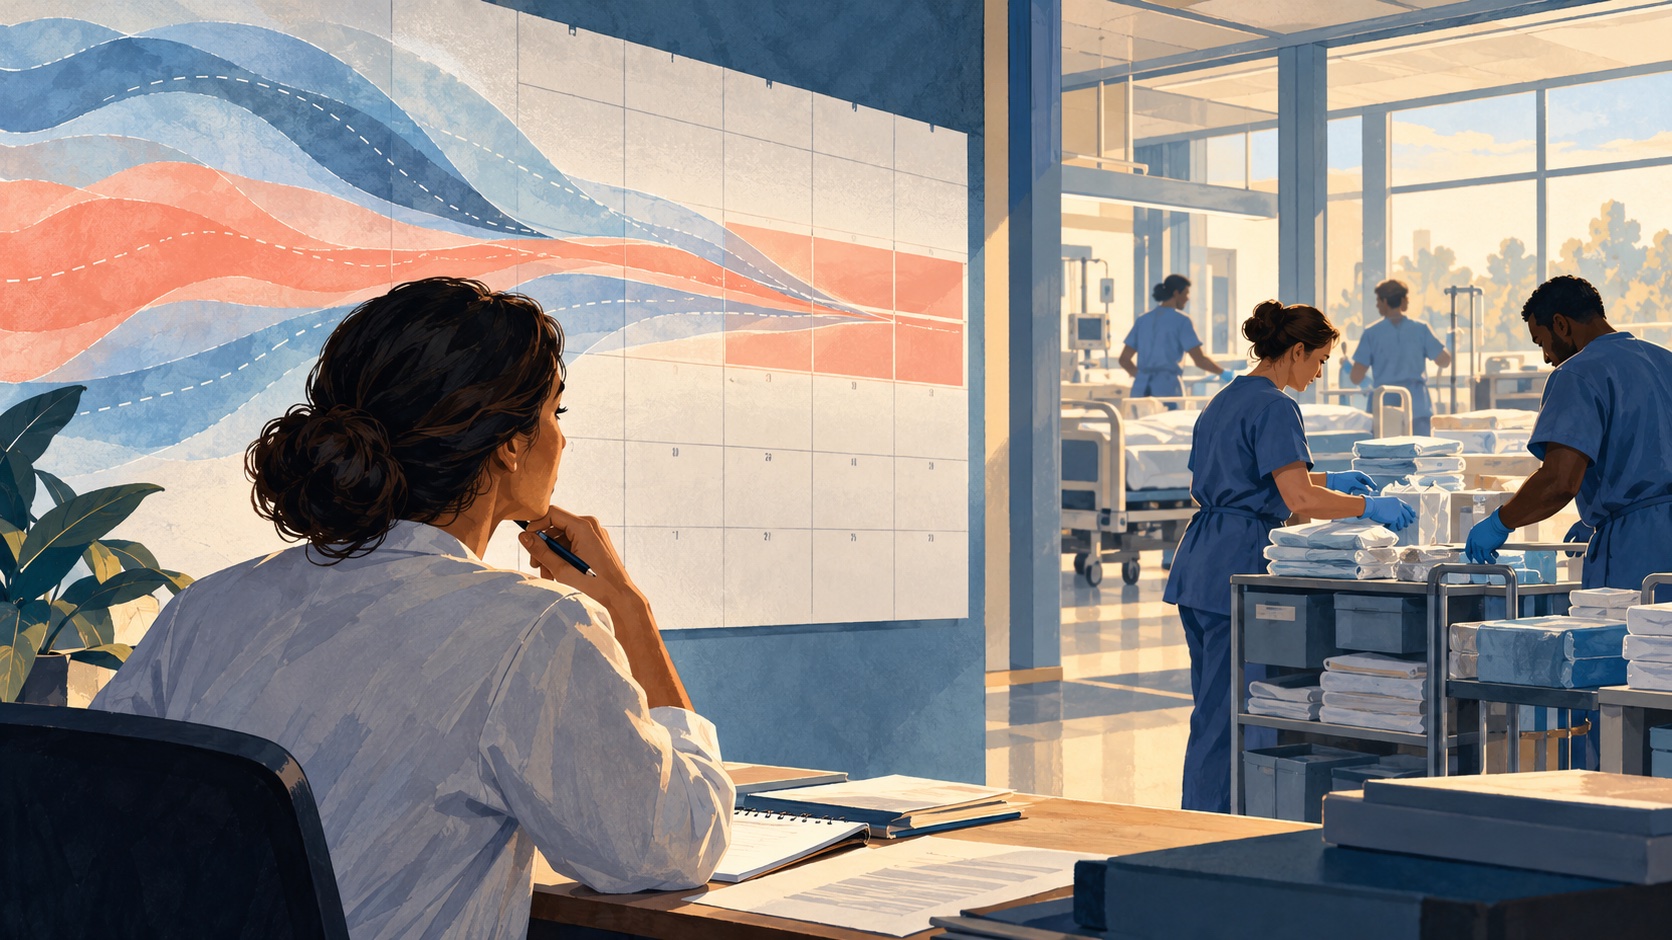
A forecast that says “the hospital will be full” is less useful than one that shows a plausible range, how well similar ranges have performed, and when the estimate is likely to change. The CDC’s season-end evaluation for 2025–26 flu hospitalizations put Google’s submitted model first among individual teams on its primary relative weighted interval score. The number is interesting; the evaluation design explains what the result does—and does not—mean.
One defined competition, not a universal benchmark
CDC FluSight collects weekly forecasts from government, academic and industry teams during the flu season. The 2025–26 report says 39 submitted models were included in its primary comparison. Google’s Google_SAI-FluEns had the best average relative weighted interval score among individual submissions across jurisdictions, excluding the national target. The CDC’s own FluSight ensemble ranked seventh by that metric. The report also lists coverage and forecast-submission completeness, and notes that models missing at least 75 percent of targets were not included in the analysis. [1]
Google’s own post celebrated the result and says its forecasts were built with Empirical Research Assistance (ERA), a research tool that generates optimization algorithms. That is useful context but remains the vendor’s account of its own system. The CDC evaluation is the stronger source for the ranking and metric; it does not establish why Google’s model performed as it did, or whether the same method will lead on another disease, season or forecast horizon. [1] [2] [3]
Relative weighted interval score (relative WIS) evaluates probabilistic forecasts, not just a single guessed number. Lower scores indicate better performance relative to a baseline in the CDC report. Coverage asks whether prediction intervals contained observed outcomes at their stated levels. A model can have a favorable average score and still be poorly calibrated in particular locations or weeks, which is why the report breaks performance down rather than treating a rank as a complete quality label.
Why ranges matter for hospital decisions
Hospitals cannot wait for final admission counts before staffing, planning beds or positioning supplies. They need a forecast that is early enough to change a decision and honest about uncertainty. A probabilistic range can support that: a planner might prepare for a central scenario while keeping a contingency for a higher-demand tail. The model does not decide what level of reserve is affordable; local teams weigh that against staffing, geography and other operational constraints.
FluSight’s score is calculated after the season’s outcomes are observed. That retrospective scoring is essential for comparing forecasts, but it is distinct from live operational performance. A model can rank well on a season-level metric while a user still needs to know whether a particular local forecast arrived on time, covered its uncertainty well and improved a real decision. CDC describes FluSight as a forecast collaboration whose outputs inform communication about anticipated state-level medical demand. [1] [4]
The cautionary history of “AI predicts flu” headlines
Google Flu Trends is a reminder that a strong historical fit can fail when people, data collection and the underlying outbreak change. A 2014 analysis documented large errors in Google Flu Trends and described how shifts in data and modeling choices can undermine big-data forecasts. FluSight’s multi-team, probabilistic evaluation addresses part of that problem by comparing forecasts against observed outcomes and exposing uncertainty. It cannot remove distribution shifts or guarantee that the next season resembles the last one. [5]
The practical questions for a public-health model are therefore more demanding than “which team won?” How often did it submit? Did its intervals match their stated coverage? Did performance vary by jurisdiction? How did it compare with a simple baseline? Were forecasts stable enough to support the decisions users actually make? The CDC report makes several of these dimensions inspectable, which is more informative than a marketing claim alone.
What to take from the result
Google’s top individual-model score is credible evidence that its submitted system performed strongly on this specific CDC evaluation. It is not evidence that AI has solved flu prediction. Public-health agencies and hospitals should treat forecast models as decision support, retain domain expertise, and evaluate calibration and operational impact alongside accuracy. Researchers should welcome the result while asking for reproducible methods and continuing prospective evaluation across seasons.
The strongest sign of progress is not that a model can announce a rank after winter. It is that forecast users can compare uncertainty with outcomes and improve decisions before the outcomes arrive. For background, read our guide to how scientific AI claims should be evaluated.
Frequently asked questions
What did Google’s model rank first at in CDC FluSight?
The CDC's 2025–2026 FluSight evaluation lists Google's Google_SAI-FluEns model as the top individual submitted model by average relative weighted interval score across jurisdictions, excluding the national target. The FluSight ensemble itself ranked seventh on that metric.
Does the FluSight result show that AI can predict the next flu season exactly?
No. FluSight evaluates probabilistic forecasts after observed outcomes become available. The CDC report includes interval coverage and submission completeness as well as relative weighted interval score; one season's ranking does not establish exact future predictions or universal performance.
Sources & further reading
Keep reading
GitHub Copilot’s New App Identity Moves Agent Billing to the Organization
GitHub’s Copilot SDK preview separates service identity from a person’s login, shifting agent access, policy and usage accountability to the organization.
AI Blind-Sweep Ultrasound Matches Experts in Two Clinics. What the Study Proves
A prospective study tested AI gestational-age estimates from scans by novice operators in Chicago and Nairobi, with important limits on generalization.
Meta’s PrivacyLib Puts Agent Data Rules at the Point of Access
Meta’s latest infrastructure account shows how shared privacy checks can follow internal AI-agent requests across connected data systems.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.