
Google’s ‘Sleep’ Framework Gives Models a Training Phase After Deployment
Google Research proposes periodic weight updates to retain new knowledge. The result is a research framework, not a model that learns safely from every chat.
On this page
A language model can use a fact while it sits in the current context and still fail to remember it tomorrow. Google Research’s new “sleep” framework explores a deeper fix: give a model periodic offline training sessions that turn some short-term context into persistent parameters. That is more ambitious than adding a longer prompt or a search index, and it raises a practical question that the neuroscience metaphor can obscure: who chooses what the model is allowed to learn?
The proposal is a controlled update cycle
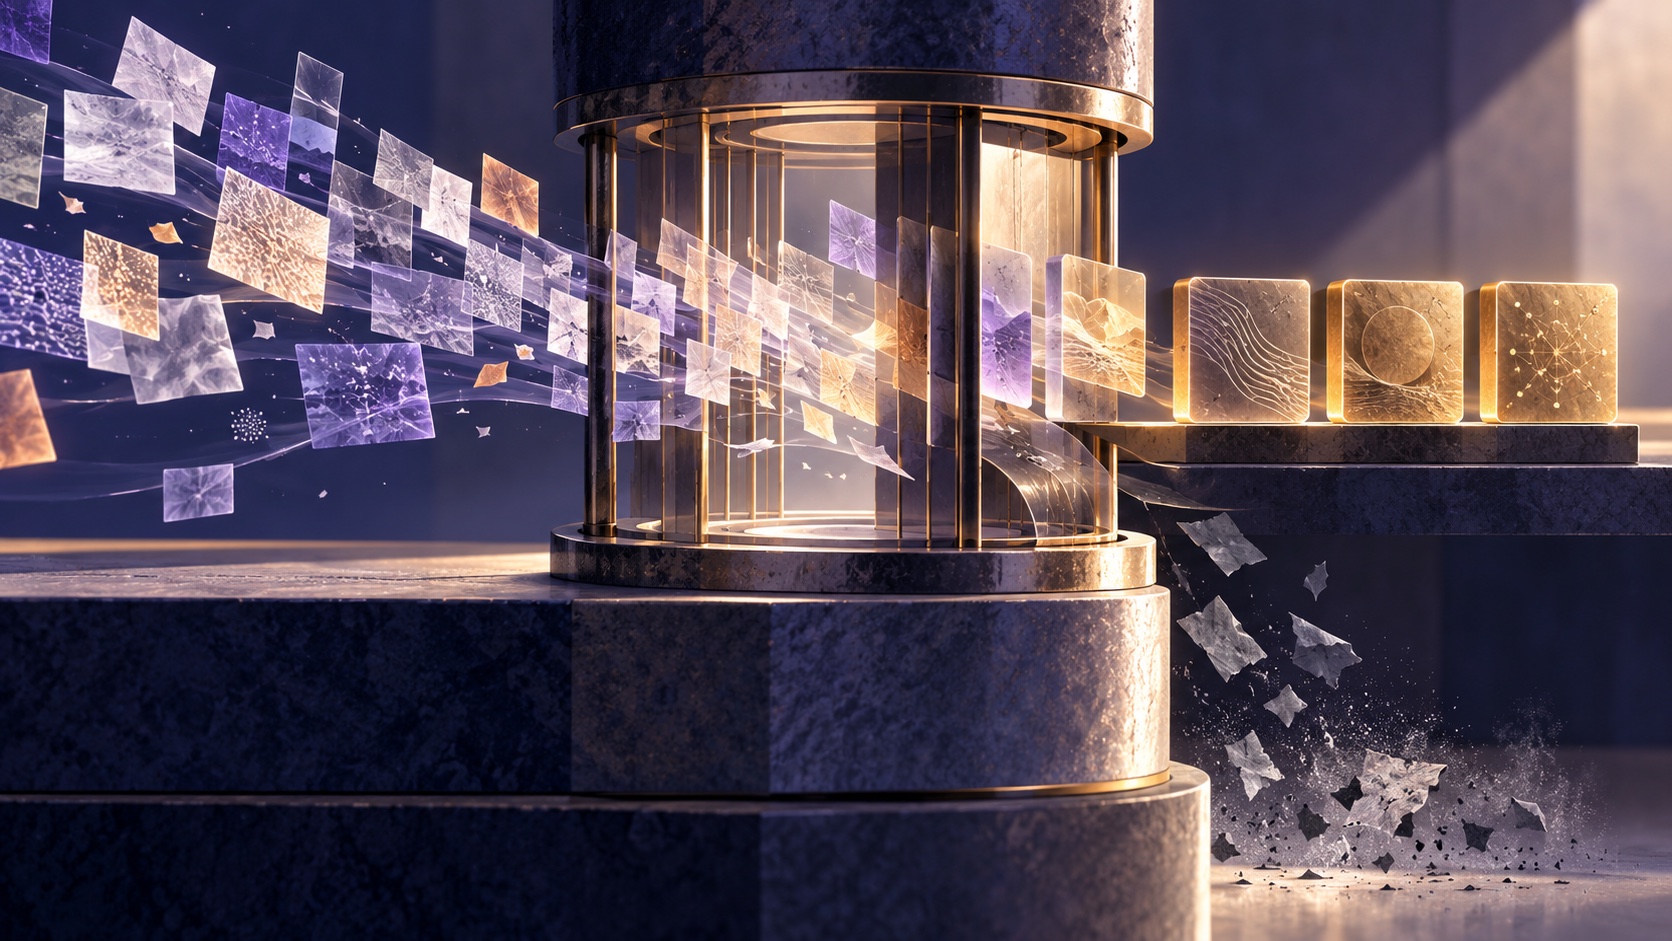
Google describes two phases. During “wake,” the system uses fast temporary memory to handle new information. During “sleep,” it expands a set of low-rank expert parameters, distills selected context into them, generates synthetic practice examples and evaluates whether this rehearsal improves chosen tasks. Temporary state can then be cleared for the next cycle. “Sleep” and “dreaming” are metaphors for offline computation; this is a machine-learning procedure, not a claim about machine consciousness. [1]
The authors report learning new facts, retaining long-context knowledge up to 10 million tokens and improving complex reasoning in their experiments. Those are research results reported by the authors, not independently reproduced guarantees for arbitrary models, data or applications. The underlying paper, Language Models Need Sleep, describes the proposed architecture and experiments in more detail; the October blog communicates the same research direction to a broader audience. [1] [2]
The approach sits between two familiar choices. Retrieval-augmented systems keep knowledge outside the model and fetch it when needed. Full fine-tuning changes model weights but is expensive and can disrupt earlier capabilities. A periodic consolidation cycle tries to keep the accessible memory benefits of retrieval while allowing selected patterns to become durable model behavior.
Why the update boundary matters
Changing parameters has a different risk profile from adding a document to a search index. A bad index entry can often be removed and the next query uses the corrected corpus. A bad model update can alter unrelated answers, and the affected behavior may be difficult to locate. Continual learning research calls one central failure catastrophic forgetting: new training can degrade previously learned capabilities. Google frames its architecture around reducing that risk through allocated experts and rehearsal, but a system still needs explicit evaluations across old and new tasks. [1] [2]
There is also a data-governance problem. “The model learned from recent work” sounds useful until the recent work includes confidential customer information, a temporary instruction, a mistaken claim or a malicious prompt. The architecture does not itself establish whether source material is consented, retained, filtered, attributable or deletable. Those are policy and system-design decisions that have to be made before the update job begins.
This is why the framework should not be described as a deployed chatbot learning from each user’s private conversation. Google’s post says the process uses human-defined training rules and offline consolidation, but does not announce a general product that automatically incorporates ordinary chat messages into model weights. [1]
What the experiments do and do not answer
The core evidence is a research paper and Google’s explanation of it. That is stronger than a feature teaser, but it remains a bounded experimental evaluation. Benchmarks such as TRACE, designed for continual learning in language models, and the Mammoth framework, which supports comparisons across many continual-learning methods and datasets, help make forgetting and transfer measurable. One headline result on a selected task cannot show how an update behaves across every user, language, domain or safety boundary. [4] [5]
The authors’ “Hope” architecture is part of the technical foundation they cite. A result built on a particular architecture, training schedule and evaluation suite does not automatically transfer to a different base model or production environment. The practical questions are whether the method retains capabilities outside the reported tasks, how often consolidation must run, what compute and latency it costs, and how reliably updates can be rolled back. [3]
A deployment checklist for model teams
Teams evaluating persistent learning should begin with a narrow, non-sensitive corpus and a written admission rule. Keep source lineage for each candidate fact, and distinguish verified knowledge from user preference or temporary task context. Run a fixed regression suite before and after each update, including old capabilities, safety behavior, privacy probes and targeted tests for the new information. Compare against a retrieval baseline so the team can see whether changing parameters is necessary.
Make the update reversible. Version the model and training data, preserve a known-good checkpoint, assign an owner to approve each update and monitor for behavior shifts after release. Provide a deletion and correction procedure that reaches the learned representation rather than merely removing the original document from storage. If the team cannot identify which data entered an update or restore a prior checkpoint, the feature is not ready for sensitive production knowledge.
The “sleep” idea is compelling because it treats memory as a lifecycle rather than a larger context window. Its value will depend less on the metaphor than on whether a system can learn selected, useful information without quietly absorbing the wrong things. For now, Google has published a research direction and reported experimental evidence. The next step is broader independent evaluation and a transparent account of how persistent model updates behave in real deployments.
Frequently asked questions
Does Google’s sleep framework let a deployed chatbot learn from every conversation?
No. Google Research describes a research framework with periodic offline consolidation, synthetic rehearsal and parameter updates under human-designed training rules. The announcement does not establish automatic learning from ordinary user conversations in a deployed Google product.
How is continual learning different from retrieval augmented generation?
Retrieval supplies selected external information at inference time, while continual learning changes model parameters so information can persist in the model itself. Retrieval is easier to inspect and update; parameter updates can improve integrated behavior but require careful evaluation for forgetting, privacy and rollback.
Sources & further reading
- Google Research: The sleep framework
- arXiv: Language Models Need Sleep: Learning to Self-Modify and Consolidate Memories
- Google Research: Hope is all you need
- TRACE: A Comprehensive Benchmark for Continual Learning in Large Language Models
- Mammoth: Continual learning research framework and benchmark suite
Keep reading
GitHub Agentic Workflows Turn Markdown Tasks Into Reviewable Actions Jobs
GitHub’s agentic workflows bring Markdown instructions into Actions with guardrails for agent-proposed changes.
GitHub Copilot’s New App Identity Moves Agent Billing to the Organization
GitHub’s Copilot SDK preview separates service identity from a person’s login, shifting agent access, policy and usage accountability to the organization.
Google’s Flu Forecast Win Shows Why Public-Health AI Needs Calibration
CDC ranked a Google model first on one flu forecast score. Here is what that result says about accuracy, uncertainty and public-health planning.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.