
GPT-6.1 Terra Makes Computer Use Cheaper. Your Workflow Still Needs a Verifier
OpenAI positions GPT-6.1 Terra for visual and desktop tasks at lower API prices. Here is what its benchmarks establish and what they leave open.
On this page
A desktop agent can click the right button and still produce the wrong outcome. It may select the wrong row, miss a validation message, or stop after a dialog closes without checking whether the change saved. OpenAI’s new GPT-6.1 Terra makes computer-use more affordable on paper. For teams deciding whether to automate, the harder question is whether they can cheaply verify what happened after the clicks.
What OpenAI has announced
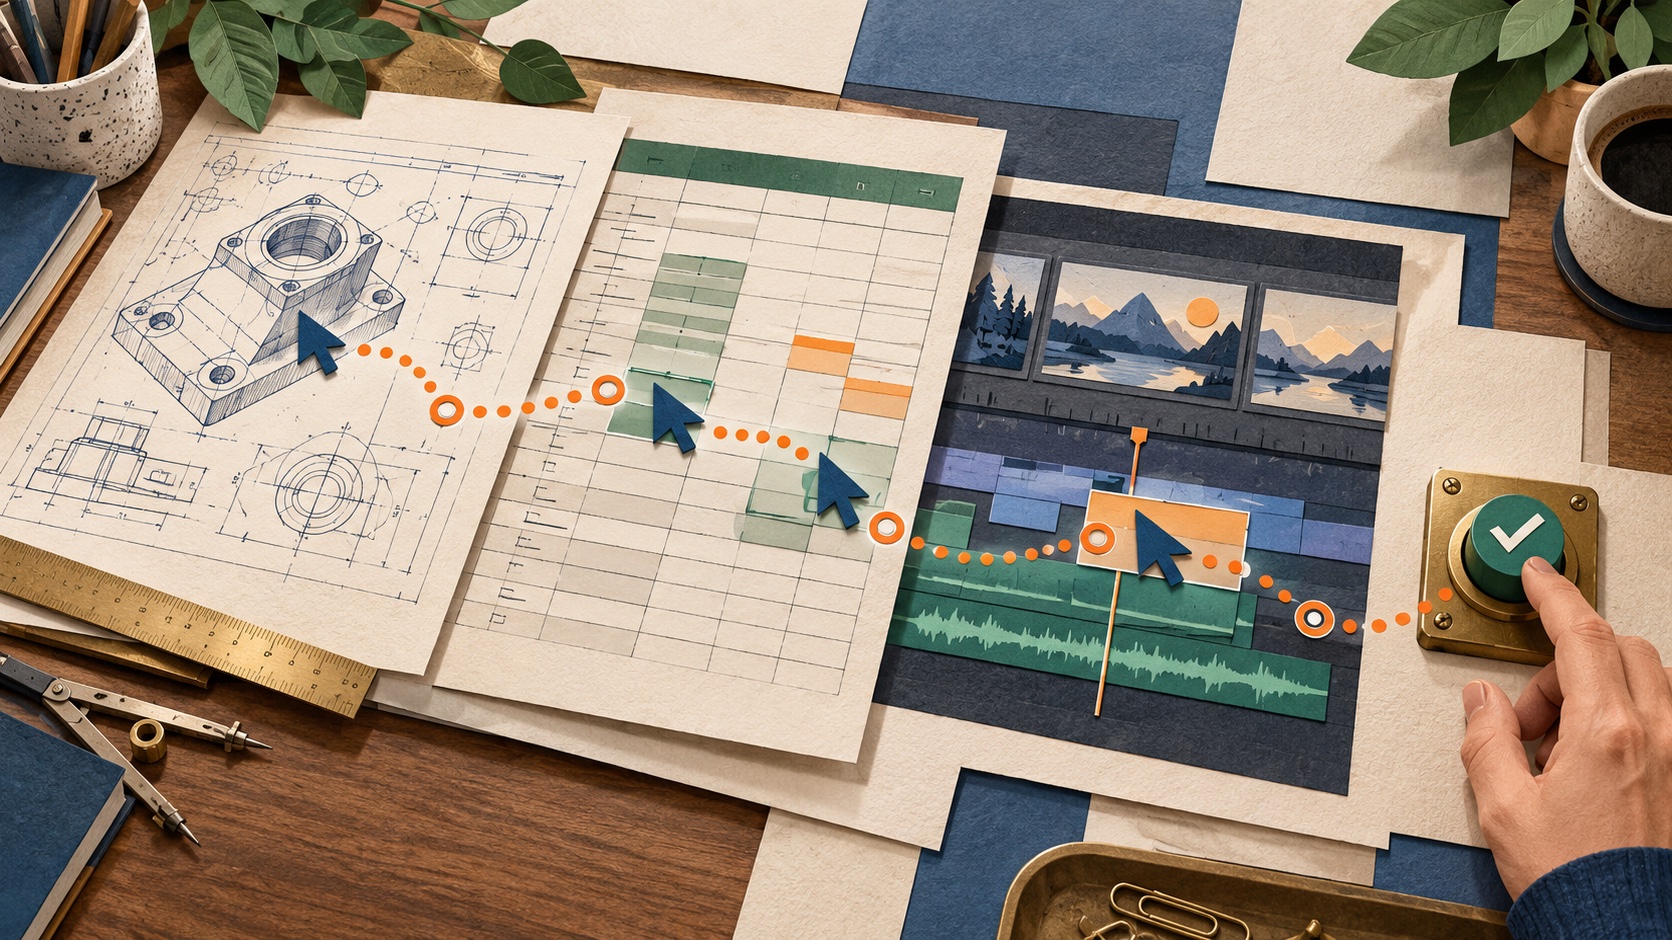
OpenAI describes GPT-6.1 Terra as an efficient model for visual reasoning and computer use, including tasks such as reading technical drawings, filling forms and editing video. The company says its standard API pricing is 50% lower than GPT-5.6 Terra and GPT-6.1 Sol, and lists availability in the API, ChatGPT Work and Codex. These are current product claims from OpenAI’s announcement; customers should check the live pricing and product documentation before budgeting. [1]
The benchmark section combines several different kinds of evidence. OpenAI reports a 15-point improvement over GPT-5.6 Terra on Agents’ Last Exam at medium reasoning effort, plus results on visual reasoning, terminal coding and OSWorld 2.1. It also reports a lower error rate on an internal error-inducing prompt set. Each number has a boundary: the internally created tests are not independent replications, and benchmark score differences do not map directly to a production workflow’s success rate. [1]
OpenAI’s system-card addendum describes the model’s safety evaluations and safeguards. It is the right place to inspect the company’s own deployment claims, but it remains an assessment supplied by the model provider. A buyer still needs to evaluate the complete system they plan to run: model, tool permissions, application state, orchestration code and review policy. [2]
A lower token price is not a lower task cost by itself
OpenAI’s API price is a useful input, but computer use consumes more than model tokens. A task may require screenshot capture, multiple model calls, retries, waiting for a page, reading an error state and a human review. The total cost is closer to:
model calls + tool execution + retries + verification + exception handling
A workflow that costs less per call can still cost more per completed task if the agent needs many more steps or if a human has to repair frequent near-misses. Conversely, a cheaper model that completes a narrow, well-structured task reliably may make automation economical where a premium model would not. Measure cost per verified outcome, not cost per million tokens alone.
The same distinction applies to speed. A fast model does not make a slow external application respond faster, and it cannot skip a second-factor prompt, a rate limit or a stale record. A robust workflow waits for explicit state changes rather than treating a successful click as proof.
What computer-use benchmarks can tell you
Computer-use research has moved beyond static questions. OSWorld’s original benchmark uses real applications in desktop environments and defines tasks whose completion can be checked against the resulting state. OSWorld 2.0 expands the focus to longer workflows and challenges such as dynamic environments, cross-source reasoning and visual precision. That work illustrates why desktop automation is hard: task success depends on a sequence of actions and on what the environment did between them. [3] [4]
Benchmarks are still snapshots. They use a set of applications, tasks, machines and scoring rules. Your team’s finance system may have custom fields; your browser may show a different banner; a role may lack permission to edit; a production record may already have changed. A model’s score does not certify behavior on those conditions.
This is why the most useful test is an application-specific pilot. Choose a task with a clear desired end state, make the first run read-only or reversible, and check the result independently. Record whether the agent selected the right entity, whether it noticed errors, and whether its final report matches the application state. Include interruptions: expired sessions, network delays, duplicate submissions and ambiguous confirmations.
Build the verifier before widening access
For a form-filling workflow, the agent can draft values and submit them in a sandbox. A verifier can then re-read the saved record through a trusted API and compare fields against the request. For a video-editing workflow, compare the exported timeline or project metadata rather than trusting a narration that says “done.” For a financial action, keep the final approval and transfer outside the model’s authority.
A practical rollout has three gates:
- Read: can the model find the correct record without changing it?
- Propose: can it prepare a change that a person can inspect before submission?
- Commit: only after the prior stages are stable, can it make a bounded change with independent confirmation and a recovery path?
Keep permissions scoped to the task, log tool actions, and make cancellation visible. If a model reports that it completed a task, the system should be able to show the evidence: which record changed, which fields changed and what confirms the final state.
That discipline is especially important for desktop use because the interface is a layer between an agent and the underlying application. A visual agent may see a success toast while the server later rejects the write. An accessible browser workflow or API might provide stronger verification; the right interface depends on the product and the action’s risk.
The useful question for buyers
GPT-6.1 Terra could make visual automation cheaper, and OpenAI’s published results suggest improved performance on its selected evaluations. The launch does not establish how reliably the model will handle every customer’s applications, nor does a lower API price prove lower total operating cost.
Teams should ask a more concrete question: can we define and verify success for one small task? If yes, the model’s price and performance are worth testing against that baseline. If the outcome cannot be inspected independently, making the model cheaper or faster does not make the workflow safer.
For a broader view, see our guides to computer-use agents and OS-level sandboxing and AI productivity measurement.
Frequently asked questions
Is GPT-6.1 Terra available through the API?
OpenAI says GPT-6.1 Terra is available in its API as gpt-6.1-terra, as well as in ChatGPT Work and Codex for Plus, Pro, Enterprise and Edu users. Availability and pricing should be checked against current account and API documentation.
Do OpenAI's computer-use benchmarks guarantee reliable automation?
No. Benchmarks measure performance on defined task sets under particular conditions. They do not establish success on your applications, accounts, permissions, data or recovery paths; teams should validate outcomes before accepting writes or external actions.
Sources & further reading
Keep reading
AI Blind-Sweep Ultrasound Matches Experts in Two Clinics. What the Study Proves
A prospective study tested AI gestational-age estimates from scans by novice operators in Chicago and Nairobi, with important limits on generalization.
Meta’s PrivacyLib Puts Agent Data Rules at the Point of Access
Meta’s latest infrastructure account shows how shared privacy checks can follow internal AI-agent requests across connected data systems.
Meta’s Recommender Tokens Turn Product Meaning Into Reusable Vocabulary
Meta’s GenRecs approach replaces one-item IDs with semantic token sequences. The promise is better generalization; the hard part is measuring it fairly.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.