
Meta’s Recommender Tokens Turn Product Meaning Into Reusable Vocabulary
Meta’s GenRecs approach replaces one-item IDs with semantic token sequences. The promise is better generalization; the hard part is measuring it fairly.
On this page
Most recommendation systems begin with an unromantic fact: the model needs an identifier for every item. That works until the item is new, rare or unlike anything the model has seen. Meta’s GenRecs Tokenization tries to give each ad more than an opaque ID. It maps content and engagement patterns into reusable tokens, so the representation can carry some of the meaning of the item into the model.
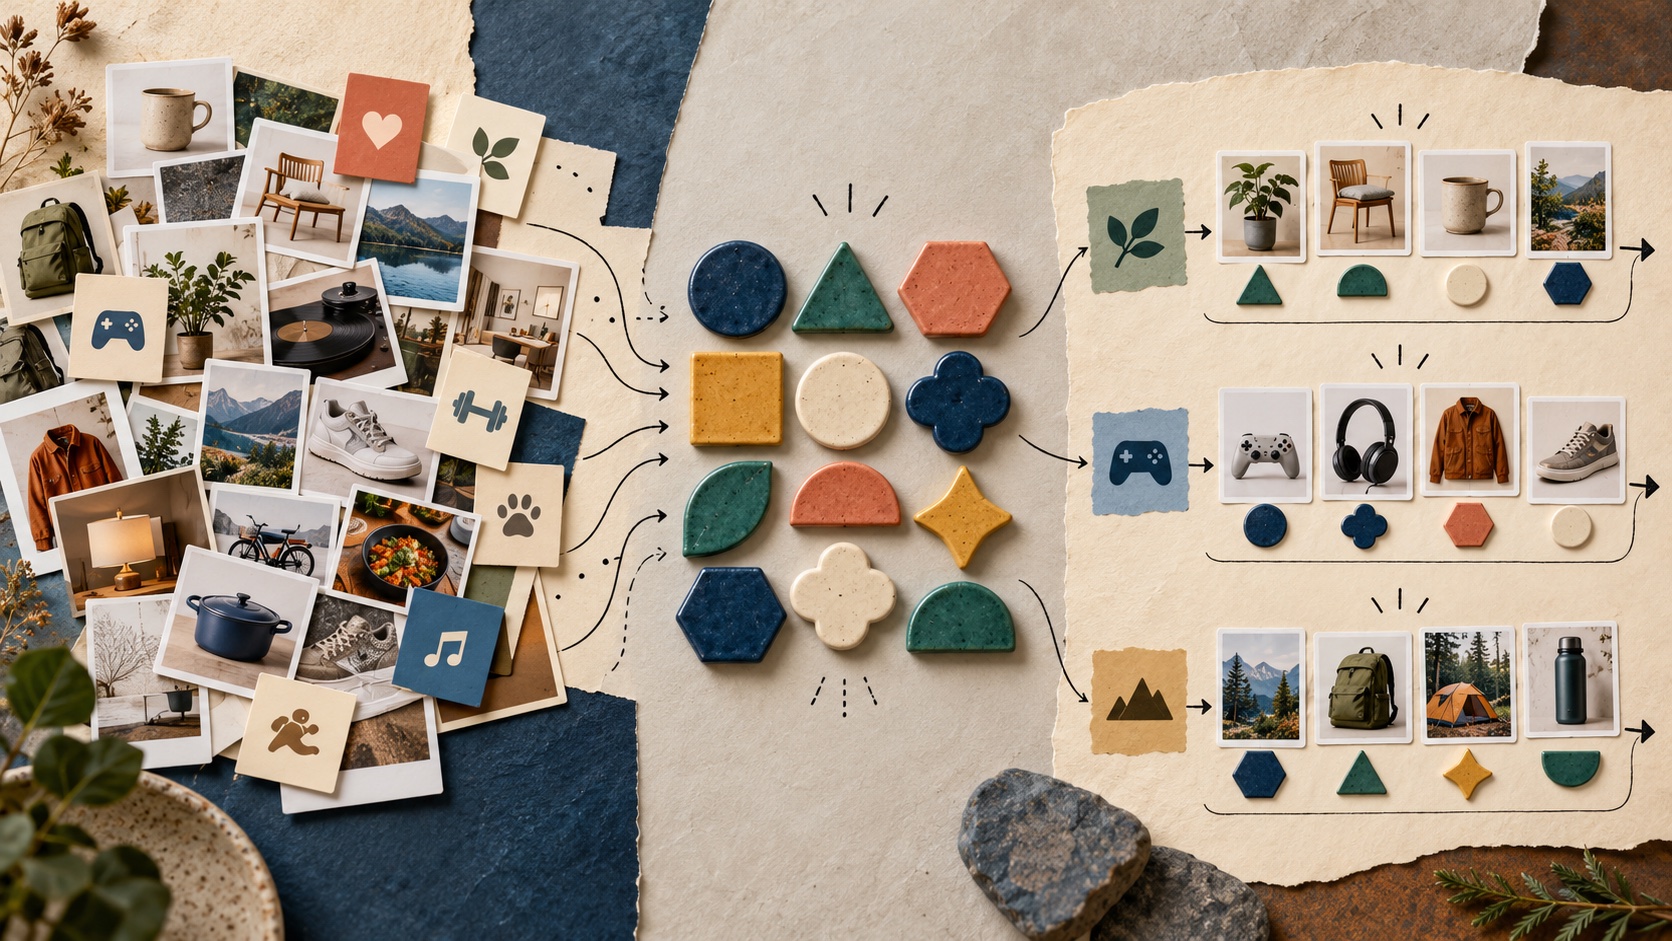
From unique IDs to shared representations
In a traditional recommender, an item ID is a lookup key. The model can learn that people who interacted with item 123 often interact with item 456, but the IDs themselves do not tell it that both items are trail-running shoes, new-season versions or related products. A new item may begin with little interaction history.
Meta says GenRecs starts by encoding an item’s text and images into an embedding, combining that content signal with representations learned from engagement, then quantizing the result into a short sequence of discrete tokens. Similar items can share pieces of the vocabulary. A new running shoe campaign, for example, can reuse learned structure from earlier campaigns rather than beginning with a completely isolated identifier. [1]
This is not simply “put an LLM on ads.” The interesting change is the representation. If item content and interaction histories become sequences that a transformer can process, the model can reuse patterns across items and potentially improve predictions for the long tail. Meta describes a pipeline involving semantic embeddings, decomposition into subspaces and codebook quantization. [1]
Why a stable vocabulary matters
Generative recommendation research has explored representing items as sequences of semantic IDs. The TIGER paper, for example, studies generative retrieval in which a model predicts a sequence representing a relevant item. Google Research has also described semantic IDs for recommendation. These works are not the same implementation as Meta’s production system, but they show that the broader idea has been examined beyond one vendor announcement. [3] [4]
A shared vocabulary can help with sparsity: if a model learns that a particular pattern of features often corresponds to a certain kind of user interest, a new item may benefit from tokens it shares with established items. It can also create a more compositional way to represent the catalogue. Rather than memorize every item independently, a model learns reusable combinations.
There are tradeoffs. A codebook can collapse distinctions that matter. Two products can be visually similar while having different safety, price or suitability constraints. An embedding may encode correlations that do not generalize when user behavior changes. Token sequences also add a serving and training system that has to be maintained as inventory, languages and objectives evolve.
Semantic representation should therefore be treated as one source of evidence for ranking, not as a complete definition of relevance. A product’s content may suggest similarity; user choice, policy, freshness, diversity and business constraints still shape whether it belongs in a particular feed.
Reading Meta’s result carefully
Meta reports that GenRecs Tokenization, paired with its Generative Ads Model (GEM) and Adaptive Ranking Model, delivered a 0.35% lift in conversions across surfaces. The footnote says the measurement uses Meta internal data from February 2026. Separately, Meta’s October 13 GEM post reports larger conversion and click-through improvements for the overall system. Those figures have different scopes and should not be added together or treated as independent replications. [1] [2]
A reported 0.35% lift can matter at a huge scale, but the practical meaning depends on the baseline and experiment design. Was the result relative or absolute? How were users randomized? Did the effect hold across campaigns, regions and advertiser objectives? Did the change affect ad diversity or user experience? The public post does not provide the complete data needed to answer those questions, so this article presents the figure as Meta’s reported result rather than an independently validated outcome.
For a team evaluating a similar approach, the first comparison should be simple: unique IDs, content embeddings and semantic token sequences on the same held-out or online test, with identical candidate generation and ranking conditions. Check new-item and long-tail performance separately from aggregate metrics. Inspect whether gains survive changes in catalogue distribution, and track latency and memory as well as conversion.
Where it is useful
Semantic IDs are most interesting when the catalogue is large, items arrive faster than interaction history accumulates, and content provides useful relationships. They may be less compelling when the inventory is small, item descriptions are poor or the task depends primarily on exact user-item history.
The implementation also needs a path for refresh. If an item changes, should its tokens change? How does a model compare new and old vocabularies during retraining? Can the serving stack roll back a tokenizer without invalidating cached features? These operational questions can determine whether a research idea becomes a reliable production system.
Meta’s contribution is a concrete account of a large-scale design: encode items, turn representations into discrete sequences, and combine those sequences with generative ranking models. The company’s result is a useful signal that the idea has practical potential at its scale. It is not a universal benchmark. The durable lesson is to ask whether representations give a model transferable structure—and then test that claim where the cold-start problem actually lives.
For context, see our explainers on hybrid search and pgvector and GraphRAG’s knowledge graph tradeoffs.
Frequently asked questions
What is semantic tokenization in a recommender system?
It represents items through short sequences of learned tokens that encode content and engagement patterns, rather than assigning each item only a unique opaque identifier. Related items can share parts of the representation.
Does Meta's reported conversion lift prove semantic tokens will improve every recommender?
No. Meta reports a 0.35% conversion lift for its production system paired with other models, measured on internal data in February 2026. Results depend on the inventory, users, objective, experiment design and serving system.
Sources & further reading
Keep reading
AI Blind-Sweep Ultrasound Matches Experts in Two Clinics. What the Study Proves
A prospective study tested AI gestational-age estimates from scans by novice operators in Chicago and Nairobi, with important limits on generalization.
Meta’s PrivacyLib Puts Agent Data Rules at the Point of Access
Meta’s latest infrastructure account shows how shared privacy checks can follow internal AI-agent requests across connected data systems.
GPT-6.1 Terra Makes Computer Use Cheaper. Your Workflow Still Needs a Verifier
OpenAI positions GPT-6.1 Terra for visual and desktop tasks at lower API prices. Here is what its benchmarks establish and what they leave open.
/* Comments */
Comments are offline right now — we reconnect automatically, nothing is lost.