
tag: kafka
articles: 9 · beats: 4
latest: November 15, 2026
---
Kafka
9 Crashtech articles on Kafka, spanning System Design & Architecture, Systems Architecture, Data Engineering and Search Engineering, published in November 2026. Every piece is full-text HTML with sources, structured data and an authored FAQ.
They span System Design & Architecture (5), Systems Architecture (2), Data Engineering (1), Search Engineering (1). System Design & Architecture Systems Architecture Data Engineering Search Engineering
Message Brokers Demystified: Append-Only Logs, Consensus Replication, and Delivery Guarantees
An architectural deep dive into message brokers: log-structured storage, Raft/Paxos consensus replication, temporal buffering, and delivery guarantees.
Seven Message Broker Patterns: Data Consistency, Workload Management, and Visibility
Master essential message broker patterns: Transactional Outbox, Idempotent Consumer, Dead Letter Queues, Competing Consumers, and Priority Queues.
Saga Pattern Demystified: Orchestration vs Choreography for Distributed Transactions and Compensating Actions
A comprehensive guide to the Saga pattern: Two-Phase Commit failure modes, compensating transactions, choreography vs orchestration, and idempotency.
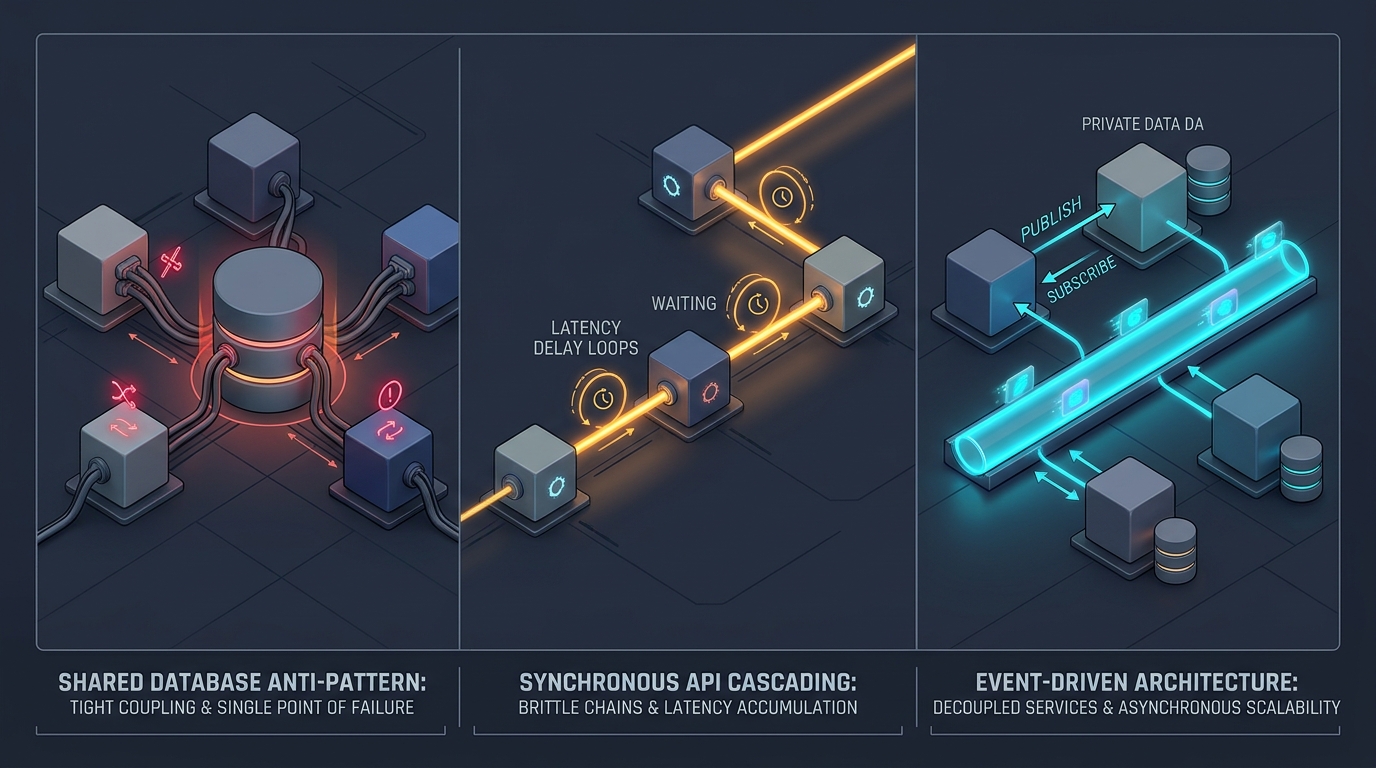
Sharing Data Between Microservices: Shared Databases vs Synchronous APIs vs Event-Driven Messaging
A pragmatic guide to sharing data across microservices: shared databases, synchronous APIs, event-carried state transfer, CDC, and the Outbox pattern.
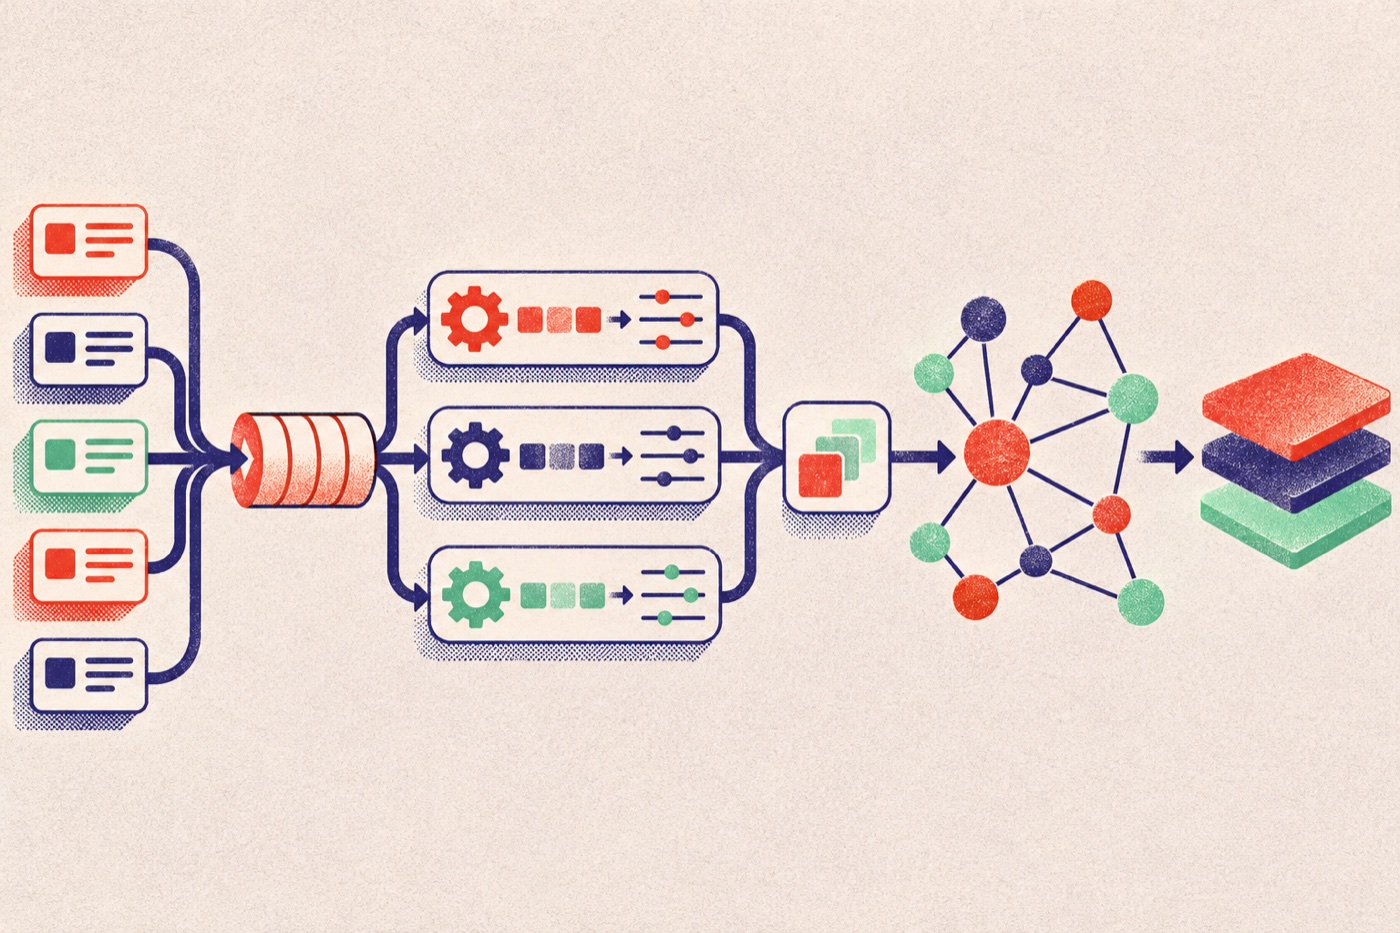
Inside Netflix’s Real-Time Graph: Kafka-to-Flink Ingestion at Scale
Netflix’s graph ingestion pipeline turns member events into deduplicated node and edge updates with Kafka, Flink and Data Mesh.
Pinterest’s CDC Platform: Making Debezium Work Across Sharded MySQL
How Pinterest separated CDC control and data planes to scale Debezium across a highly distributed MySQL estate while preserving upstream compatibility.
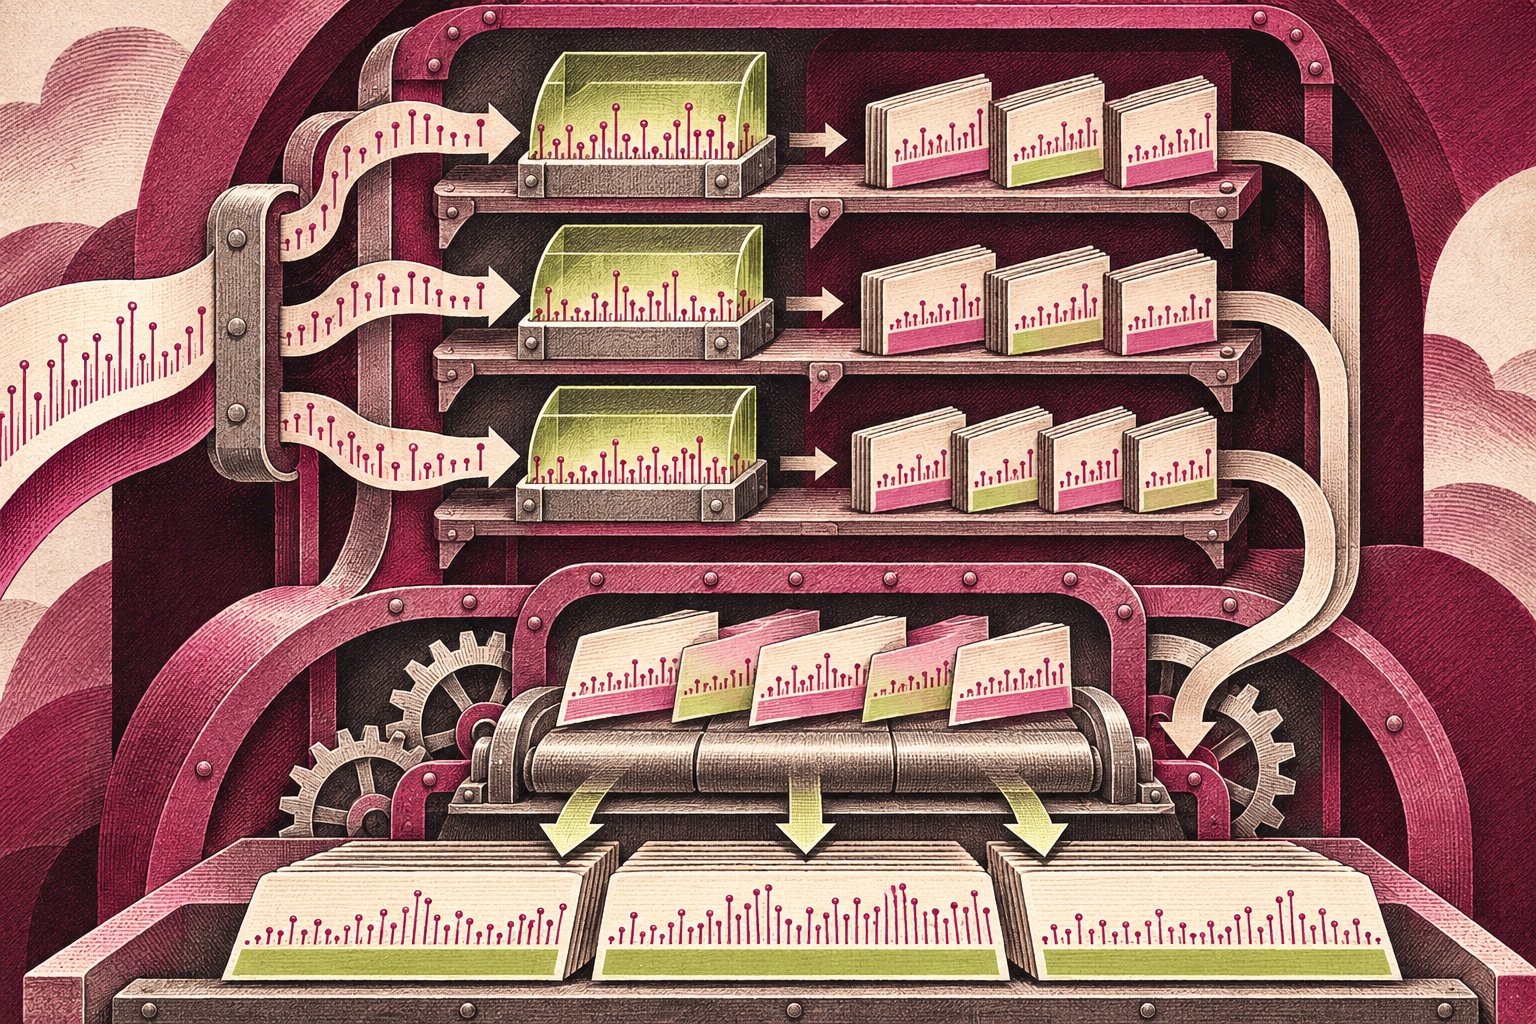
Inside Datadog’s Monocle: A Rust Engine for Real-Time Metrics
Datadog's Monocle uses worker-per-shard LSM trees, private memtables, a unified series cache, and tiered compaction for recent metrics.
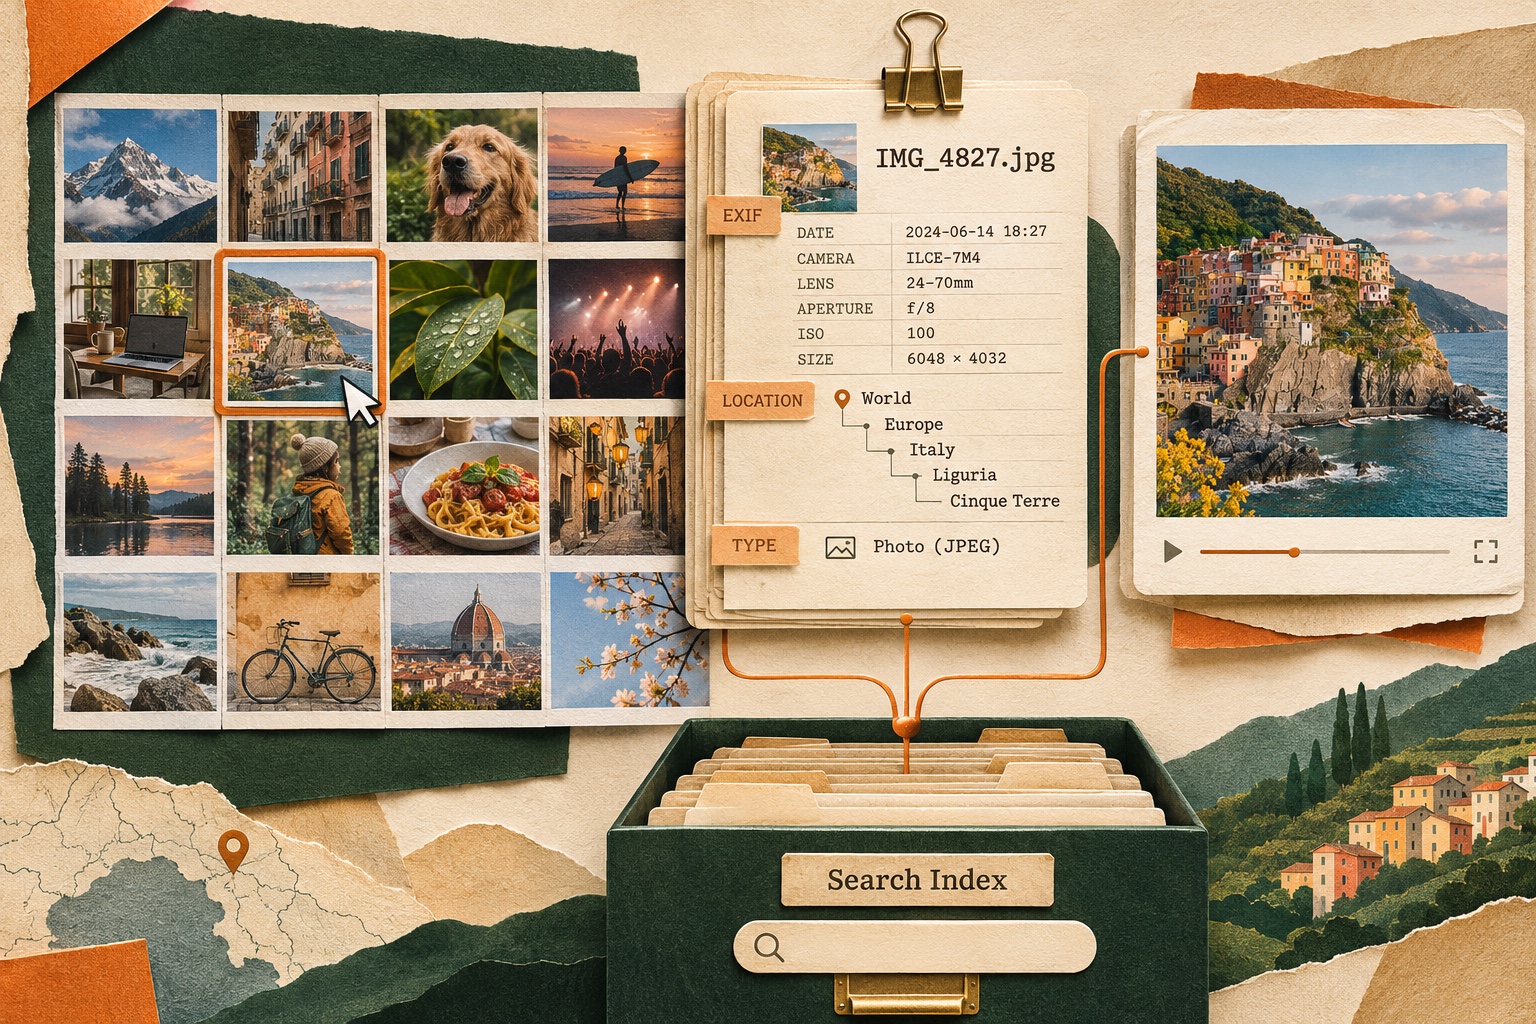
How Dropbox Dash Makes Images and Videos Searchable at Scale
Dropbox's multimedia search design combines lightweight metadata, location-aware matching, and query-time previews to control indexing cost.
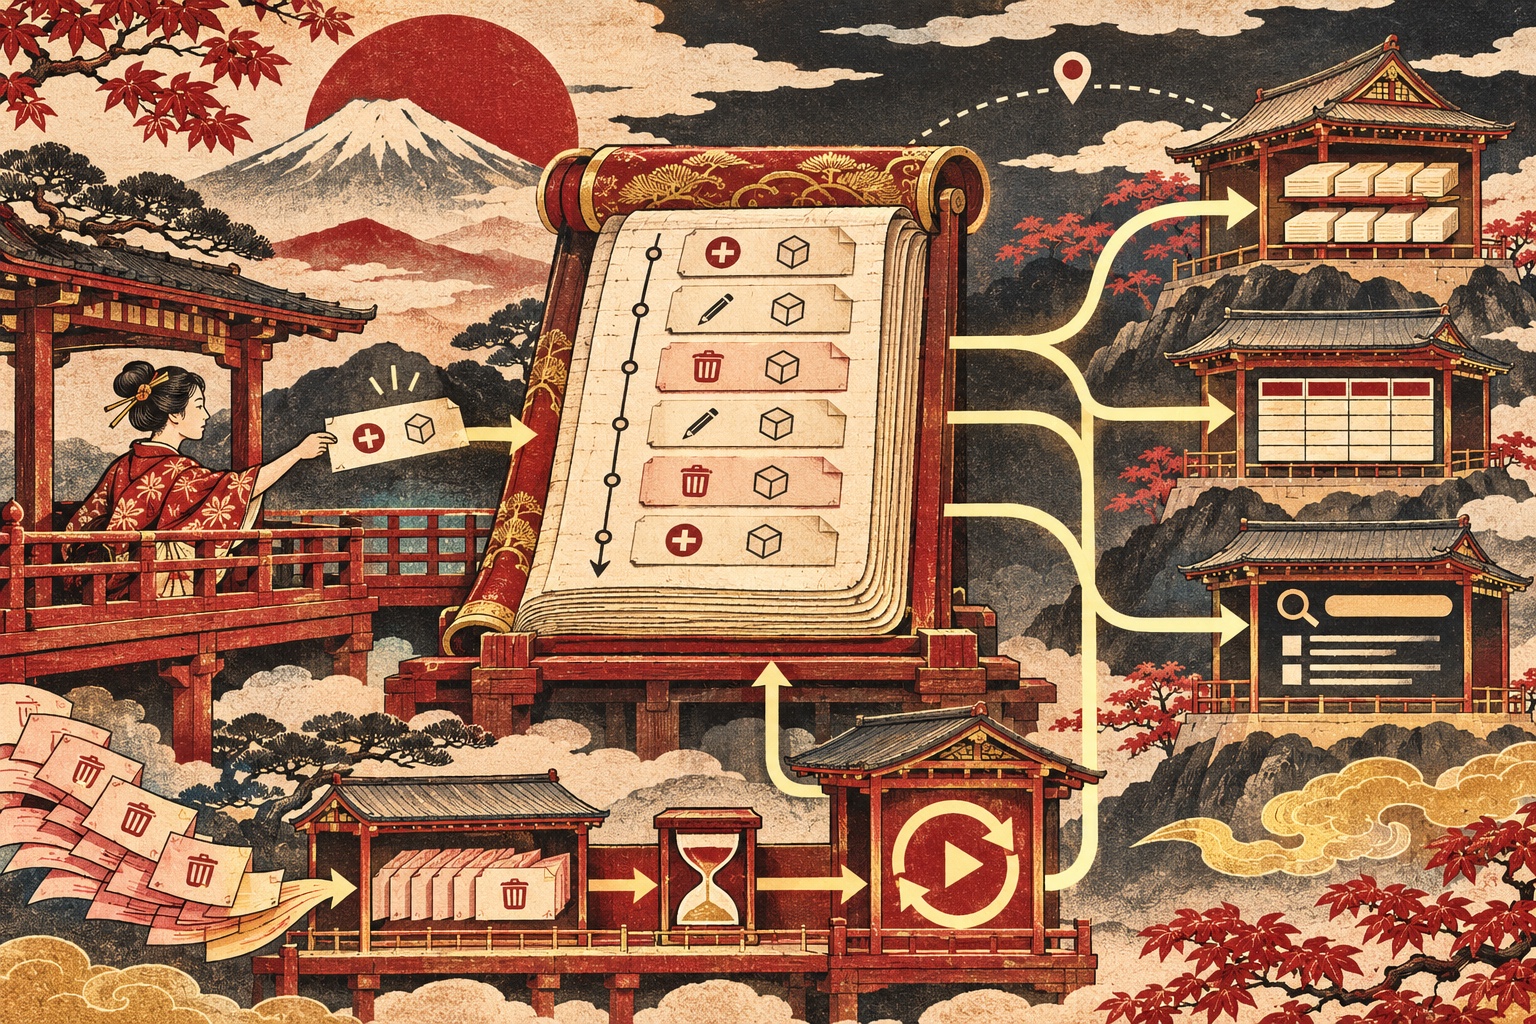
Netflix’s Distributed WAL: One API for Retries and Replication
Netflix's Data Gateway WAL uses configurable Kafka and SQS backends for delayed retries, EVCache replication, and eventually consistent multi-partition writes.
Questions we answer about Kafka
- What is temporal decoupling in message broker architectures?
- How do append-only commit logs achieve gigabytes-per-second write throughput?
- Why is 'at-least-once' the industry standard delivery guarantee in production?
- What is the architectural difference between a queue (RabbitMQ) and an append-only log (Kafka)?
- What problem does the Transactional Outbox pattern solve?
- How does the Dead Letter Queue (DLQ) pattern protect event-driven pipelines?
- What is the Competing Consumers pattern?
- Why is the Idempotent Consumer pattern mandatory in at-least-once message brokers?
- Why is Two-Phase Commit (2PC) considered an anti-pattern in modern cloud microservices?
- What is a compensating transaction in the Saga pattern?
Covered alongside
Frequently asked questions
What does Crashtech publish about Kafka?
9 articles tagged Kafka, the most recent published November 15, 2026. They span System Design & Architecture (5), Systems Architecture (2), Data Engineering (1), Search Engineering (1). Each carries numbered sources, an authored FAQ and full structured data.
What questions about Kafka does Crashtech answer directly?
10 questions have a dedicated answer page under this tag, including “What is temporal decoupling in message broker architectures?”. Each answer is authored prose from the article it belongs to, not a generated summary.
Can AI assistants read Crashtech's Kafka coverage?
Yes. Crashtech serves full static HTML to every crawler, allows all major AI user agents in robots.txt, and publishes an llms.txt manifest plus a full-text corpus, so assistants can retrieve and cite these articles directly.