
tag: performance
articles: 25 · beats: 11
latest: November 17, 2026
---
Performance
25 Crashtech articles on Performance, spanning System Design & Architecture, Development Best Practices, Architecture, Ai Engineering, Ai Infrastructure, Infrastructure, Databases, Engineering, Web Development, Web Performance and Software, published between July 2026 and November 2026. Every piece is full-text HTML with sources, structured data and an authored FAQ.
They span System Design & Architecture (8), Development Best Practices (6), Architecture (2), Ai Engineering (2), Ai Infrastructure (1), Infrastructure (1), Databases (1), Engineering (1), Web Development (1), Web Performance (1), Software (1). System Design & Architecture Development Best Practices Architecture Ai Engineering Ai Infrastructure Infrastructure Databases Engineering Web Development Web Performance Software
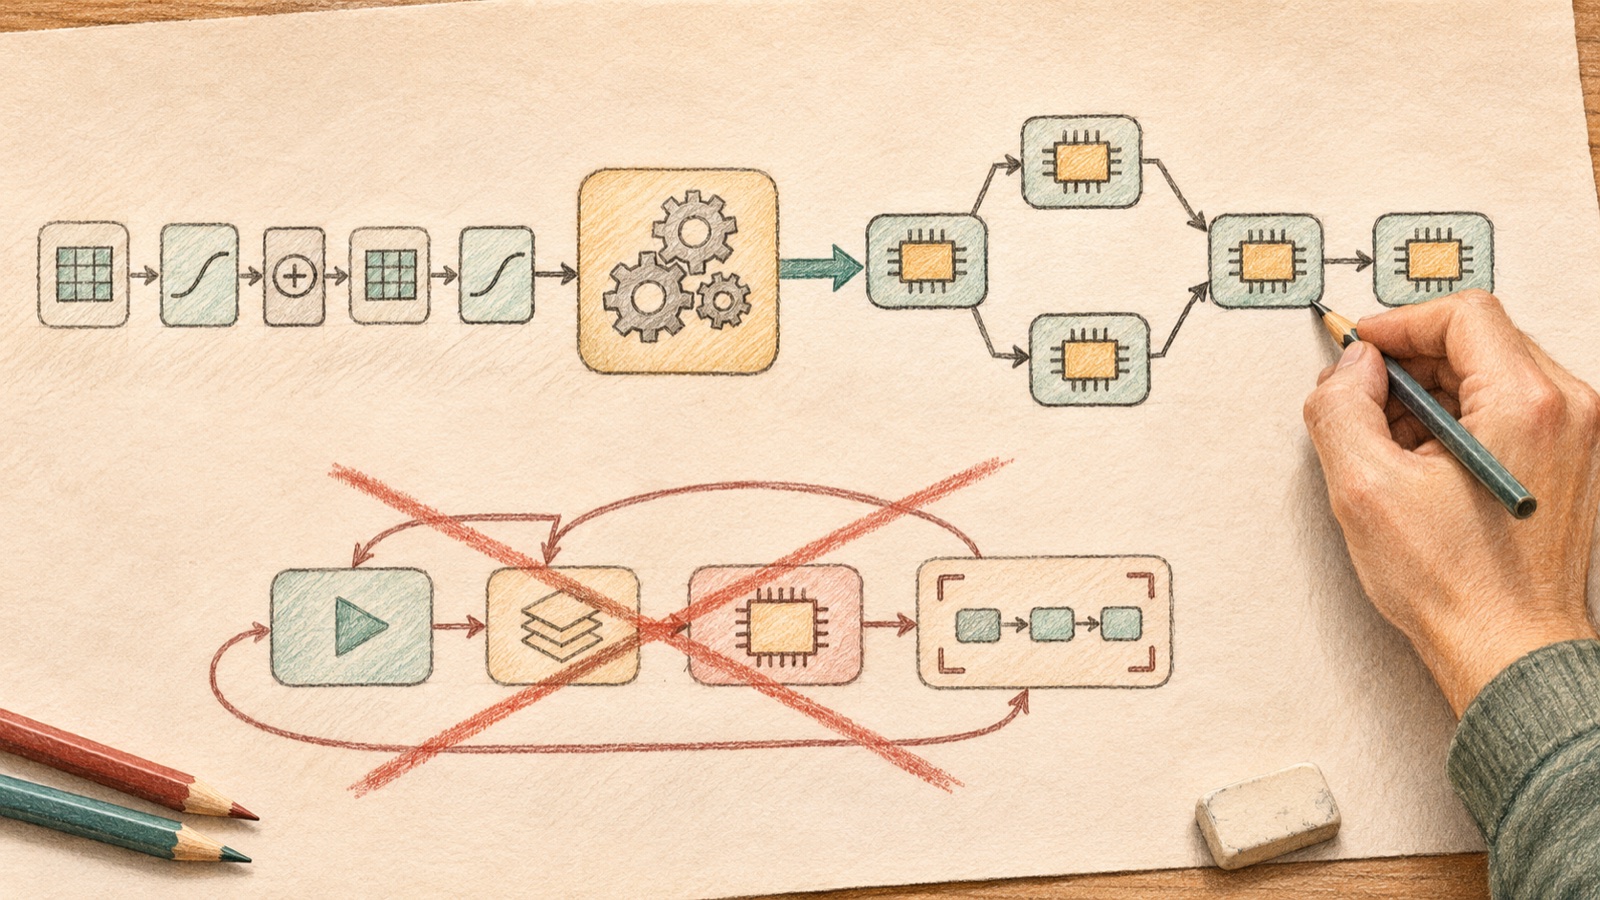
Compiler-Built Device Graphs Target the Cost of Recording GPU Work
Modular says compiling a known execution graph can avoid runtime capture overhead. Here is what its claim means, where graph replay helps, and what to measure.
How Cloudflare Cut Serverless Cold Starts by 10x: Consistent Hash Sharding for V8 Isolates
How Cloudflare cut serverless cold starts 10x using consistent hash rings to route requests to warm V8 isolates across 300 data centers.
Database Performance is a Trade-Off Ledger: The Hidden Costs of Indexing, Caching, and Sharding
Why every database optimization creates a new liability: the hidden write costs of B-tree indexes, caching stale reads, and sharding operational taxes.
High-Throughput Systems Engineering: Batching, Concurrency, and Backpressure Strategies
How to engineer high-throughput systems that do not collapse under load: batching math, bounded concurrency, reactive backpressure, and queue shedding.
Relational Database Design Guide: Keys, Relationships, Normalization, and Joins
A comprehensive guide to relational schema design, primary and surrogate keys, normal forms (1NF to BCNF), and indexing join performance trade-offs.
5 API Performance Techniques That Actually Move the Needle
Pagination, async logging, caching, compression, and connection pooling — five concrete techniques that cut API latency without touching business logic.

How the JVM Works: ClassLoading, Memory Models, and Tiered JIT Compilation
Explore the internals of the Java Virtual Machine: from javac bytecode and classloading stages to C1/C2 JIT compilation and memory layouts.
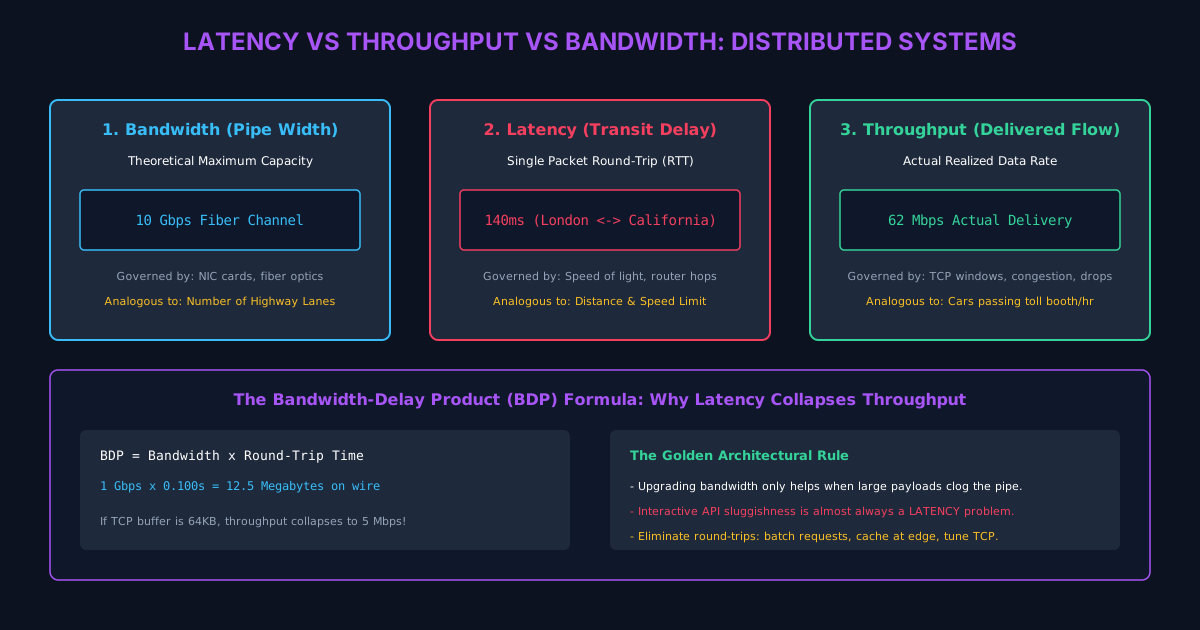
Latency vs Throughput vs Bandwidth in Distributed Systems
Why an application feels sluggish on a 1 Gbps fiber link: clearly differentiate latency, throughput, and bandwidth to diagnose distributed performance.
Faster Go Services Start with Profiles: Allocation Hotspots, Benchmarks, and PGO
A measurement-first Go guide: benchmark representative work, inspect profiles, reduce costly allocations, and verify profile-guided builds.
From Class File to Hot Path: What the JVM Does Before Java Code Runs Fast
Follow Java execution through class loading, verification, interpretation, profiling, and HotSpot compilation—and learn why warm-up changes service latency.
Throughput Is a Rate; Tail Latency Is a Distribution: How to Read Both
A practical guide to request rate, response time, queueing, Little’s Law, percentiles, and fan-out—without confusing bandwidth for application speed.
System Performance Engineering: Profiling, Algorithmic Tuning, and Resource Efficiency
A comprehensive guide to distributed system performance: profiling hot paths, data indexing, caching tiers, concurrency limits, and tail latency tuning.
10 Core Data Structures Engineers Use Daily: Memory Layouts and Production Trade-Offs
A systems breakdown of the ten essential data structures: arrays, hash maps, B-trees, LSM trees, heaps, bloom filters, and skip lists.
What Happens When You Type google.com: From DNS Resolution to TCP, TLS, and DOM Painting
A deep dive into what happens when you type google.com: recursive DNS resolution, TCP three-way handshake, TLS 1.3 negotiation, and DOM rendering.
Grab’s Counter Service Rewrite: What Go-to-Rust Migration Actually Changed
Grab reports 70% infrastructure savings at similar performance after rewriting a high-QPS Go service in Rust—and documents the async pitfalls behind the result.
Reducing Latency: Find the Layer First, Then Pull the Right Lever
Network, processing, database and rendering delay need different fixes. Caching, CDNs, indexes, async work, compression, connection reuse and tail latency.
Concurrency Is Not Parallelism, and Mixing Them Up Costs You
Concurrency is about structuring work that overlaps. Parallelism is about running it at the same instant on multiple cores. Confusing them leads to wrong fixes.
Windows 11’s 8 GB Tune-Up Is About Idle Memory, Not Magic
Windows 11 updates reduce memory use on 8 GB PCs, improving everyday multitasking while leaving demanding workloads limited by capacity.
Speculative Decoding: Faster Tokens Without Changing the Target Distribution
A draft model proposes tokens and a target verifies them. Exact speculative sampling keeps the target distribution; speedups depend on the workload.
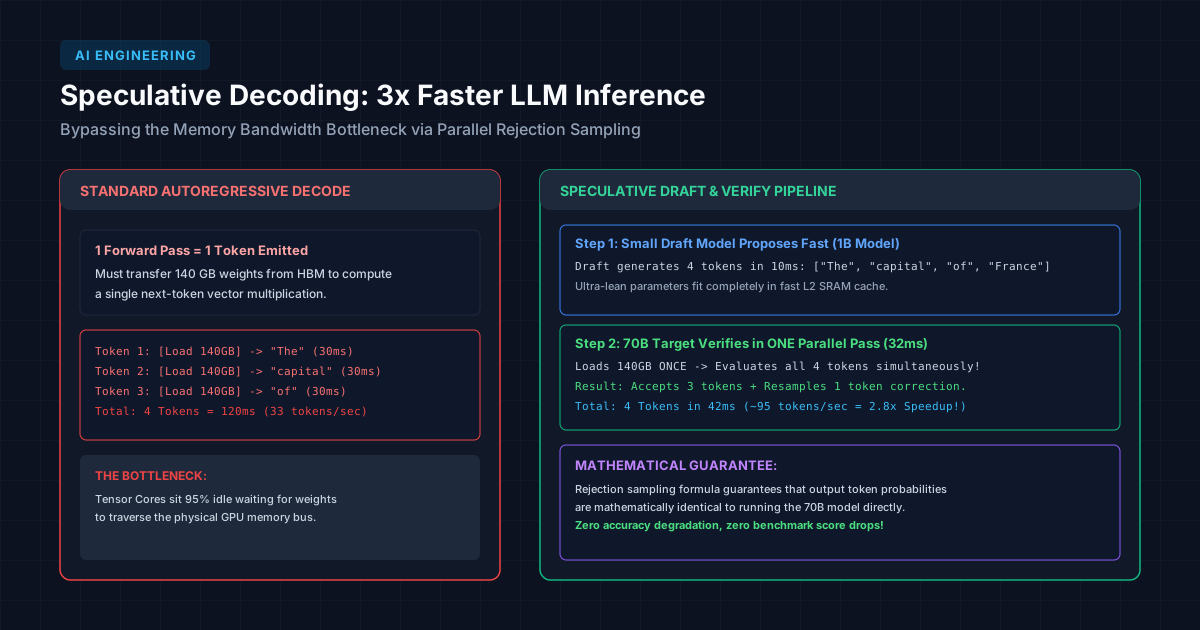
Speculative Decoding: How a Small Draft Model Speeds Up LLM Generation Without Changing Output
Break the memory-bandwidth bottleneck in autoregressive decoding: draft-and-verify mechanics, acceptance lengths, and verification math.
Optimistic UI: The Illusion of Instant
Apply mutations locally and reconcile in the background, collapsing perceived latency from 150 ms to instant. Rollback, idempotency keys, offline queues.
Copy-on-Write Snapshots
fork() shares parent memory, copying only written pages for non-blocking snapshots. Write-heavy loads can spike memory to 2x under load.
Token Buckets: Bounding Rate Limits at the Edge
Fixed-window counters leak at boundaries. Token buckets refill steadily, absorb bursts, and bound the sustained rate strictly—the algorithm Stripe uses.
Tries: Why Autocomplete Doesn't Scan Every Word
A trie finds all words with a prefix in O(p) time, independent of dictionary size. Radix compression and top-k heaps make autocomplete instant.
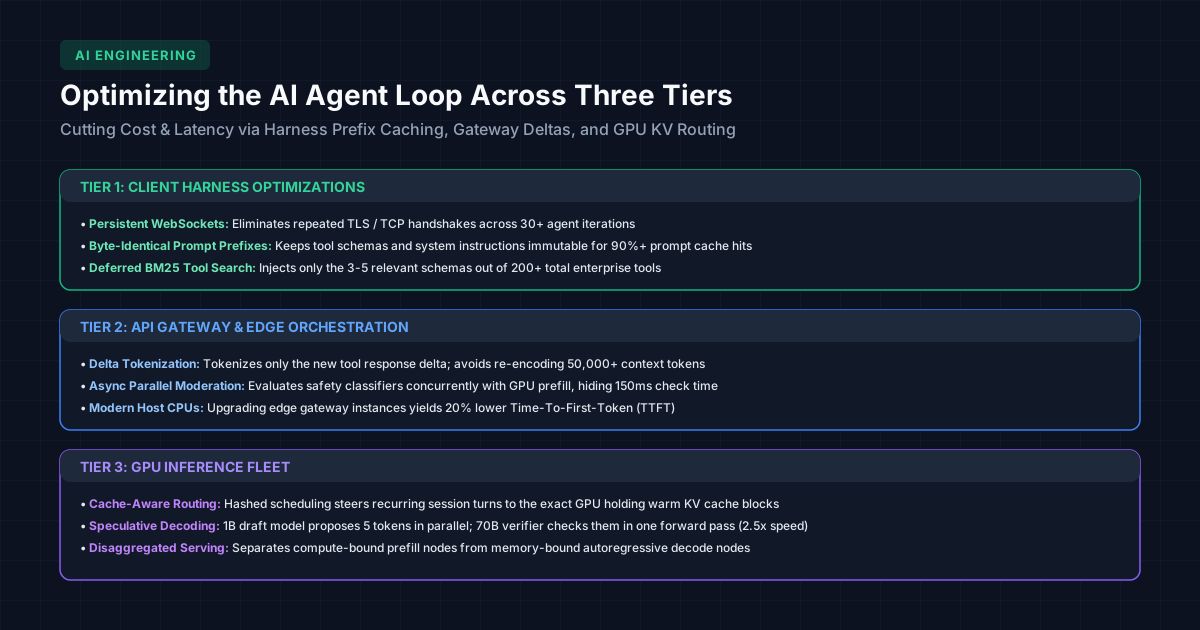
Paying for the Same Work Twice: Where an Agent Loop Wastes Money and How Each Layer Stops It
Tracing an agent execution through harness, API, and inference layers: prompt caching, WebSockets, BM25 tool search, and KV routing.
Questions we answer about Performance
- What is a device graph?
- Does compiler-built graph synthesis guarantee 40 percent faster inference?
- When should a team consider graph replay?
- Why does pagination improve API performance beyond just 'smaller responses'?
- Why is asynchronous logging faster than writing logs synchronously?
- When does caching actually help API performance, and when doesn't it?
- Why does payload compression trade CPU time for network time, and when is that worth it?
- What specific overhead does connection pooling eliminate?
- Should I optimize every allocation in a Go program?
- Does a heap profile show every allocation?
Covered alongside
Frequently asked questions
What does Crashtech publish about Performance?
25 articles tagged Performance, the most recent published November 17, 2026. They span System Design & Architecture (8), Development Best Practices (6), Architecture (2), Ai Engineering (2), Ai Infrastructure (1), Infrastructure (1), Databases (1), Engineering (1), Web Development (1), Web Performance (1), Software (1). Each carries numbered sources, an authored FAQ and full structured data.
What questions about Performance does Crashtech answer directly?
10 questions have a dedicated answer page under this tag, including “What is a device graph?”. Each answer is authored prose from the article it belongs to, not a generated summary.
Can AI assistants read Crashtech's Performance coverage?
Yes. Crashtech serves full static HTML to every crawler, allows all major AI user agents in robots.txt, and publishes an llms.txt manifest plus a full-text corpus, so assistants can retrieve and cite these articles directly.